P.S. Free & New SPS-C01 dumps are available on Google Drive shared by Getcertkey: https://drive.google.com/open?id=1nSaHBculLj3JGes6Jpf67M5HrKsB0rl5
We offer a money-back guarantee if you fail despite proper preparation and using our product (conditions are mentioned on our guarantee page). This feature gives you the peace of mind to confidently prepare for your Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) certification exam. Our Snowflake SPS-C01 exam dumps are available for instant download right after purchase, allowing you to start your Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) preparation immediately.
| Section | Objectives |
|---|---|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Testing, Debugging, and Deployment | - Production readiness
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Data Engineering with Snowpark | - Pipeline development
|
>> Snowflake SPS-C01 Valid Test Preparation <<
Maybe life is too dull; people are willing to pursue some fresh things. If you are tired of the comfortable life, come to learn our SPS-C01 exam guide. Learning will enrich your life and change your views about the whole world. Also, lifelong learning is significant in modern society. Perhaps one day you will become a creative person through your constant learning of our SPS-C01 Study Materials. And with our SPS-C01 practice engine, your dream will come true.
NEW QUESTION # 218
Consider a Snowflake table 'orders' with columns 'order_id', 'customer_id', 'order_date', and 'status'. You need to update the 'status' of all orders placed before January 1, 2023, to 'Archived'. Which of the following approaches is the most efficient and idiomatic way to achieve this using Snowpark DataFrames, assuming 'orders df DataFrame represents the 'orders' table?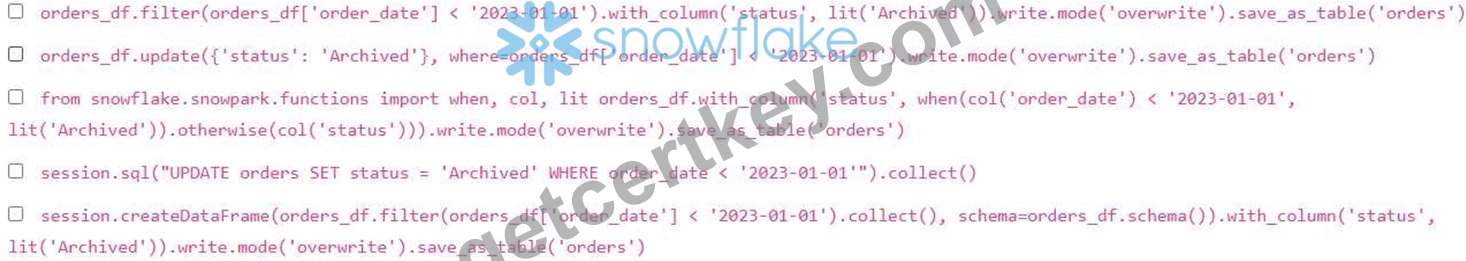
Answer: A,D
Explanation:
Options C and D are both valid and efficient solutions. Option C leverages Snowpark's 'with_column' and 'when' functions to conditionally update the 'status' column within the DataFrame and persists the changes back to the table using 'save_as_table'. Using lit function makes sure that 'Archived' status is passed as a literal. Option D uses a direct SQL update statement executed through the Snowpark session. This bypasses DataFrame operations but directly modifies the table, which can sometimes be more efficient for simple update operations. Option A is almost correct but the with_column and filter are applied separately. Option B doesn't work due to the way update functions are implemented in Snowpark. Option E unnecessarily collects the filtered data back to the driver, creating a new DataFrame from the collected data, then applying 'with_column'. This is an inefficient approach.
NEW QUESTION # 219
A Snowpark application needs to process large volumes of sensor data stored in a Snowflake table named , which includes columns , 'timestamp' , and The application must calculate a rolling average of for each over a 5-minute window. The data is not perfectly ordered by 'timestamp' within each 'sensor_id'. What is the MOST efficient and accurate way to implement this rolling average calculation using Snowpark?
Answer: E
Explanation:
Option D is the most efficient and accurate. 'partitionBy('sensor_id')' ensures that the rolling average is calculated separately for each sensor. 'orderBy('timestamp'Y orders the data within each partition by timestamp. 0)' defines the 5- minute window relative to the current row, accurately capturing all readings within that window even if they are slightly out of order. 'avg(Y then efficiently calculates the average within that window. Other options are either less efficient (e.g., UDTF iteration) or less accurate (e.g., incorrect window definitions, filtering).
NEW QUESTION # 220
You have a Snowpark DataFrame containing customer transaction data'. Your goal is to save this DataFrame as a set of Parquet files in an existing Snowflake stage named , partitioned by the 'transaction_date' column. You want to ensure that the files are automatically compressed using the Zstandard codec and that existing files with the same name are overwritten. Which of the following Snowpark code snippet achieves this with the most optimal approach and respects best practices?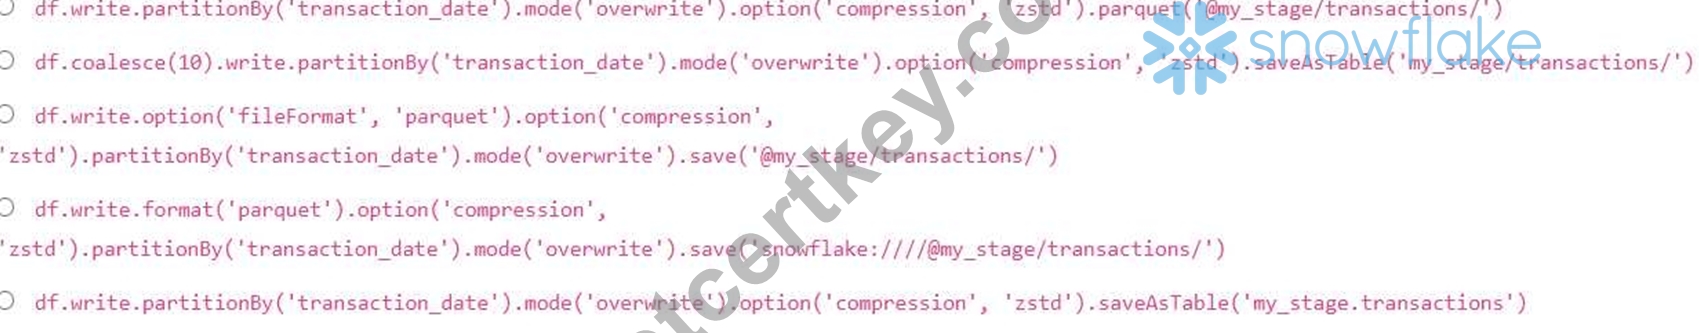
Answer: E
Explanation:
Option A correctly uses the 'parquet' method directly for writing Parquet files to a stage. It specifies partitioning by 'transaction_date', overwrites existing files using , and sets the compression codec to 'zstd' using the 'option' method. The 'saveAsTable' method, used in option B & E, is intended for creating or overwriting tables, not writing files to a stage. Option D uses a fully qualified Snowflake URL to save the DataFrame, but using saveAsTable is not for writing files into stage . The 'option('fileFormat', 'parquet')' in option C is not the most direct way to specify the format; using .parquet()' is more concise and idiomatic.
NEW QUESTION # 221
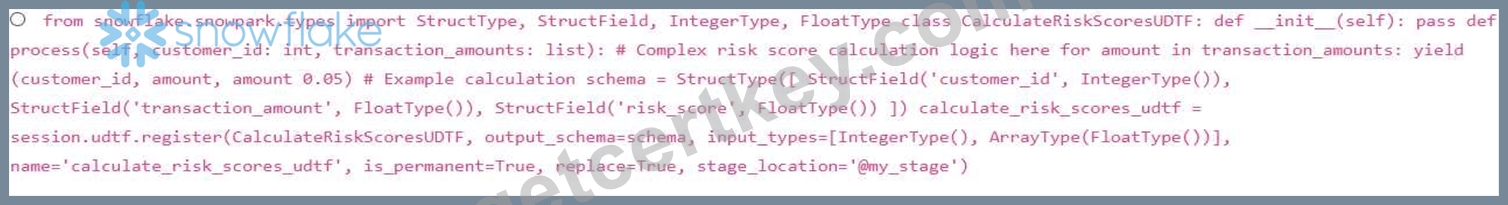
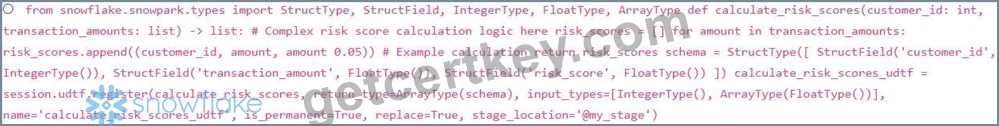
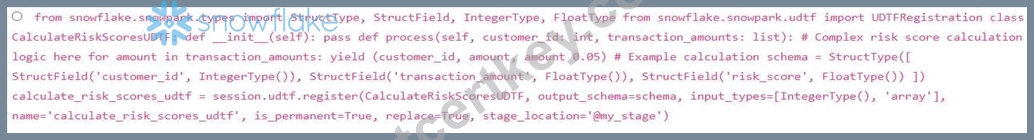
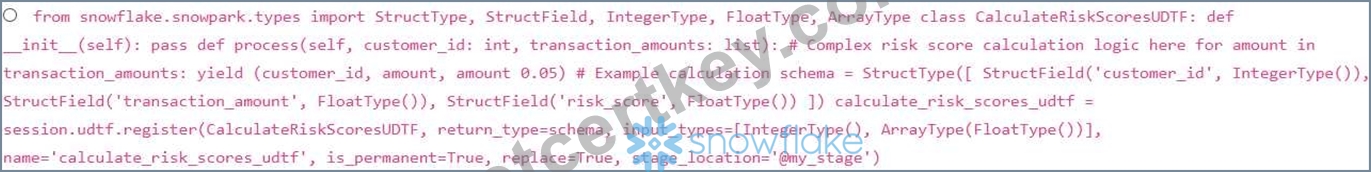
You have developed a Python function that performs complex data transformation on customer data'. You want to operationalize this function as a UDTF in Snowpark to process large datasets efficiently. The function takes a customer ID and a list of transaction amounts as input and returns a table with calculated risk scores for each transaction. Which of the following code snippets correctly defines and registers this UDTF in Snowpark, ensuring proper type handling and scalability?
Answer: C
Explanation:
Options B and C correctly defines the UDTF.Option B uses return_type and option C uses output_schema, both work. Option A is incorrect because a UDTF needs to be defined as a class with a 'process' method that yields rows, not as a function that returns a list. Option D uses an incorrect way to specify ArrayType ('array') . The other options are either syntactically incorrect or do not follow the correct UDTF definition pattern.
NEW QUESTION # 222
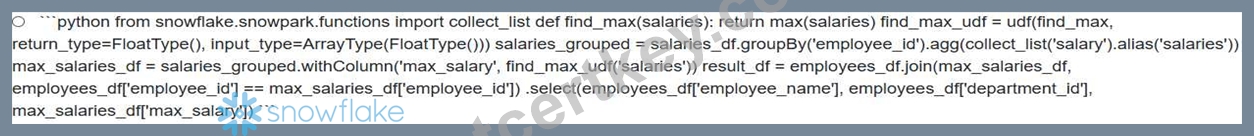
You have two Snowpark DataFrames: 'employees_df with columns 'employee_id' (INTEGER), 'employee_name' (STRING), 'department_id' (INTEGER), and 'salaries_df' with columns 'employee_id' (INTEGER), "salary' (FLOAT), 'effective_date' (DATE). You need to create a new DataFrame that contains the employee's name, department, and the highest salary they have ever received. Assuming there can be multiple salary entries for the same employee with different 'effective date' values, which of the following Snowpark code snippets would correctly and efficiently solve this problem?




Answer: D
Explanation:
Option B is the most efficient solution. It first calculates the maximum salary for each employee in the DataFrame using 'groupBy' and 'max' , then joins this aggregated result with the 'employees_df to retrieve the employee's name and department. This approach avoids unnecessary data shuffling and minimizes the amount of data processed in the join. Option A performs the join before the aggregation, which can be less efficient. Options C and E use window functions, which are more complex and may not be as efficient for this simple aggregation. Option D uses a UDF and 'collect_list' , which can be very inefficient due to data transfer and UDF overhead.
NEW QUESTION # 223
......
The Getcertkey is a trusted and reliable platform that has been helping the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) certification exam candidates for many years. Over this long time period, the SPS-C01 Exam Practice questions have helped the SPS-C01 exam candidates in their preparation and enabled them to pass the challenging exam on the first attempt.
SPS-C01 Exam Simulations: https://www.getcertkey.com/SPS-C01_braindumps.html
P.S. Free & New SPS-C01 dumps are available on Google Drive shared by Getcertkey: https://drive.google.com/open?id=1nSaHBculLj3JGes6Jpf67M5HrKsB0rl5