It is our biggest goal to try to get every candidate through the exam. Although the passing rate of our DP-750 simulating exam is nearly 100%, we can refund money in full if you are still worried that you may not pass the DP-750 exam. You don't need to worry about the complexity of the refund process at all, we've made it quite simple. And if you really want to pass the exam instead of refund, you can wait for our updates for we will update our DP-750 Study Guide for sure to make you pass the exam.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Prepare and process data | 30-35% | - Ingest and transform data
|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
Boring life will wear down your passion for life. It is time for you to make changes. Our DP-750study materials are specially prepared for you. In addition, learning is becoming popular among all age groups. After you purchase our DP-750 study materials, you can make the best use of your spare time to update your knowledge. When your life is filled with enriching yourself, you will feel satisfied with your good change. Our DP-750 Study Materials are designed to stimulate your interest in learning so that you learn in happiness.
NEW QUESTION # 17
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1. Job1 contains multiple tasks.
Failures of non-critical tasks must be logged but must NOT trigger notifications. Notifications must be triggered only when critical tasks have failed, and Job1 has completed You need to configure the job alerting behavior.
What should trigger a notification?
Answer: C
Explanation:
The correct answer is B - a job failure.
The requirement draws a clear line: non-critical task failures should be logged silently; notifications should only fire when a critical failure causes the whole job to stop. Configuring the alert on ' Job Failure ' achieves this precisely - the notification triggers when the job itself reaches a Failed terminal state, which only happens when at least one critical task has failed and the job cannot complete.
Option A (task failure) would send a notification for every task-level failure, including non-critical ones. That
' s exactly the noise the question wants to avoid. Option C (job success) would never alert on failures at all.
Option D (task success) confirms completion but doesn ' t catch failures.
Setting alerting at the job level rather than the task level is also simpler to configure - you don ' t need to mark individual tasks as critical or non-critical in the notification settings.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/alerts
NEW QUESTION # 18
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.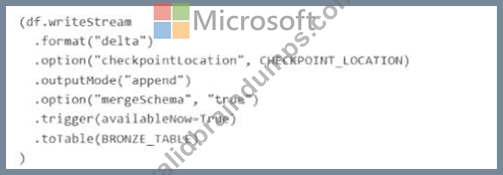
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.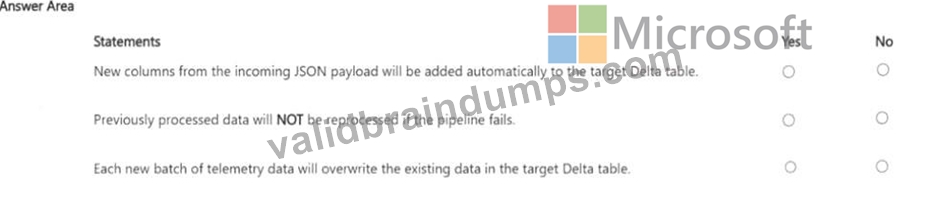
Answer:
Explanation: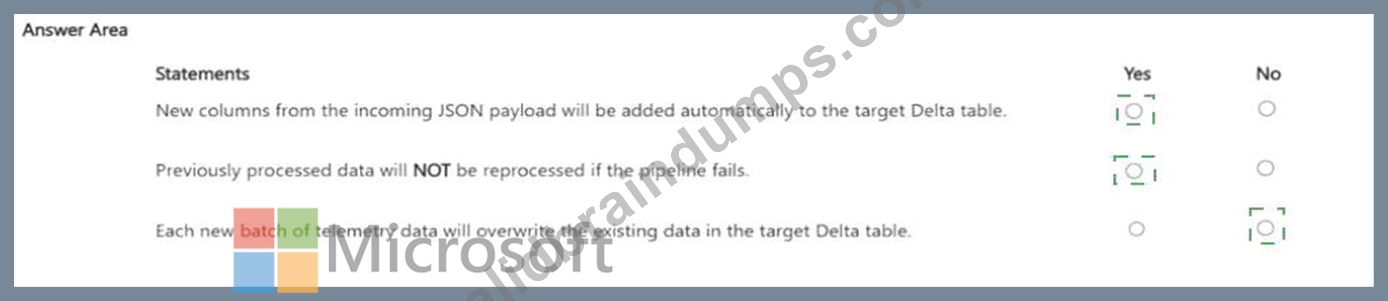
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: ' overwrite ' replaces existing data; ' append ' adds to it.
Always check whether the code uses the correct Delta format (.format( ' delta ' )), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 19
You have an Azure Databticks workspace that is enabled for Unity Catalog and contains a catalog named catalog1.
You have a group named group!
You plan to create a schema named schema1 in catalog1.
You need to ensure that group1 meets the following requirements:
* Can create tables in schema1
* Can modify and query tables
* Cannot grant permissions for the schema and its objects
How should you complete the SQL statements? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.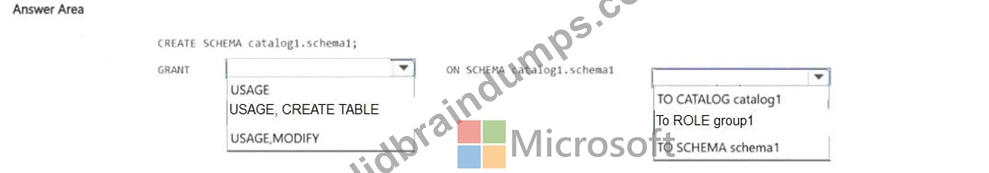
Answer:
Explanation: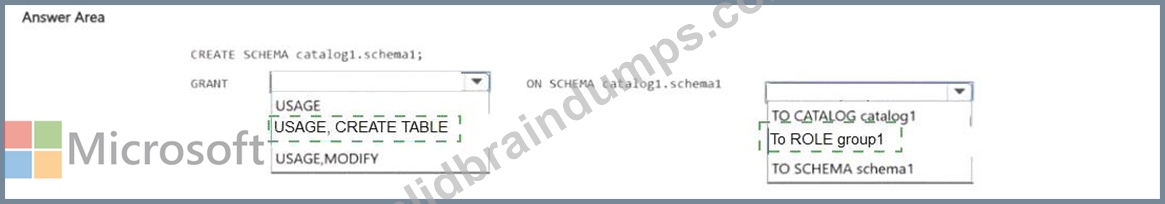
Explanation:
The correct SQL grants group1 the ability to work within the schema without delegating that ability to anyone else:
GRANT USE SCHEMA ON schema1 TO group1 - required as a prerequisite to access any object inside the schema.
GRANT CREATE TABLE ON SCHEMA schema1 TO group1 - allows creating new tables.
GRANT SELECT, MODIFY ON SCHEMA schema1 TO group1 - SELECT for queries, MODIFY for INSERT/UPDATE/DELETE operations.
Crucially, MANAGE is NOT granted. In Unity Catalog, MANAGE is what allows a principal to grant and revoke privileges on the schema and its objects. Leaving it out means group1 can do all the data work but cannot redistribute those permissions - precisely what the requirement 'Cannot grant permissions for the schema and its objects' demands.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/manage- privileges/privileges
NEW QUESTION # 20
You have an Azure Databricks workspace that is enabled for Unity Catalog You have a complex job named Job1 that contains eight tasks. Job! takes multiple hours to complete During the last job run, the final task fails due to a transient issue.
You need to retry the last task without rerunning tasks that have already completed.
What should you do?
Answer: C
Explanation:
The correct answer is B - Repair the current job run.
Repair Run is designed for exactly this situation: a long-running job where most tasks succeeded but the final task failed due to a transient issue. Instead of restarting the entire eight-task job from the beginning - wasting hours of compute - Repair Run re-executes only the failed task and any dependents that were skipped as a result. All tasks that completed successfully are marked done and their outputs are reused.
Option A (update job parameters) changes configuration for future runs but doesn't re-execute the failed task in the current run. Option C (Restart Job1) re-runs every task from the start - precisely what the question says to avoid. Option D (disable and re-enable the schedule) creates a brand-new run on the next schedule trigger, again starting from the beginning rather than repairing the existing run.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/repair-job-failures
NEW QUESTION # 21
You have an Azure Databricks workspace that contains multiple all-purpose clusters.
You discover that some clusters remain idle for long periods after users finish their work.
You need to reduce compute costs without affecting active workloads.
What should you do?
Answer: C
Explanation:
To reduce compute costs from idle clusters without impacting active workloads, you must configure Auto-Termination and use Cluster Policies.
Core Remedies
*-> Auto-Termination: Set a strict inactivity timeout (e.g., 20-30 minutes) on all-purpose clusters to automatically shut them down when idle.
Cluster Policies: Enforce maximum auto-termination limits across the workspace so users cannot disable or set excessively long idle timeouts.
Single User Access Mode: Use this mode where possible, as it tracks idleness more accurately than Shared mode by monitoring the specific user's activity.
Reference:
https://medium.com/@sujathamudadla1213/databricks-lakehouse-platform-describe-how- clusters-are-terminated-and-the-impact-of-terminating-a-b6236689fd2e
NEW QUESTION # 22
......
For candidates who are going to buy DP-750 study materials online, they may care much about the private information. We respect the privacy of you, and we can ensure you that if you DP-750 study materials from us, your personal information such as your name and email address will be protected well. Once the order finishes, your information will be concealed. In addition, DP-750 Exam Materials are high quality, since we have a professional team to check the questions and answers. Online and offline chat service stuff is available, if you have any questions about DP-750 study materials, don’t hesitate to contact us.
Latest DP-750 Cram Materials: https://www.validbraindumps.com/DP-750-exam-prep.html