P.S. It-PassportsがGoogle Driveで共有している無料かつ新しいDP-600ダンプ:https://drive.google.com/open?id=1S30lqzkHb0YBsHr56sV7538FKVGRL9l0
DP-600学習教材を世界中に確実に紹介し、幸運とより良い機会を求めるすべての人々が自分の人生の価値を実現できるようにするという大胆な考えを持っています。したがって、DP-600練習問題は、DP-600試験に合格し、より良い未来を勝ち取るのに役立ちます。また、常に先駆的な精神を持ち続け、あなたの道を歩むプロジェクトに積極的に取り組みます。 DP-600トレーニング資料は、その素晴らしい品質のためにあなたを決して失望させません。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
尊敬され、高い社会的地位を獲得することは、おそらくあなたが常に望んでいることです。しかし、それを達成したい場合は、特定の分野で優れた能力と深い知識を所有する必要があります。 DP-600認定に合格すると、それが証明され、目標を実現するのに役立ちます。DP-600クイズ準備を購入すると、DP-600試験に合格できます。当社の製品は専門家によって編集され、長年の経験を持つ専門家によって承認されています。It-Passports購入前に、最新のDP-600クイズトレントを無料でダウンロードして試用できます。
質問 # 18
What should you recommend using to ingest the customer data into the data store in the AnatyticsPOC workspace?
正解:D
解説:
For ingesting customer data into the data store in the AnalyticsPOC workspace, a dataflow (D) should be recommended. Dataflows are designed within the Power BI service to ingest, cleanse, transform, and load data into the Power BI environment. They allow for the low-code ingestion and transformation of data as needed by Litware's technical requirements. Reference = You can learn more about dataflows and their use in Power BI environments in Microsoft's Power BI documentation.
Topic 1, Litware. Inc.
Overview
Litware. Inc. is a manufacturing company that has offices throughout North America. The analytics team at Litware contains data engineers, analytics engineers, data analysts, and data scientists.
Existing Environment
litware has been using a Microsoft Power Bl tenant for three years. Litware has NOT enabled any Fabric capacities and features.
Fabric Environment
Litware has data that must be analyzed as shown in the following table.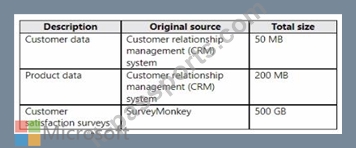
The Product data contains a single table and the following columns.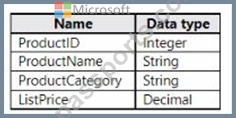
The customer satisfaction data contains the following tables:
* Survey
* Question
* Response
For each survey submitted, the following occurs:
* One row is added to the Survey table.
* One row is added to the Response table for each question in the survey.
The Question table contains the text of each survey question. The third question in each survey response is an overall satisfaction score. Customers can submit a survey after each purchase.
User Problems
The analytics team has large volumes of data, some of which is semi-structured. The team wants to use Fabric to create a new data store.
Product data is often classified into three pricing groups: high, medium, and low. This logic is implemented in several databases and semantic models, but the logic does NOT always match across implementations.
Planned Changes
Litware plans to enable Fabric features in the existing tenant. The analytics team will create a new data store as a proof of concept (PoC). The remaining Litware users will only get access to the Fabric features once the PoC is complete. The PoC will be completed by using a Fabric trial capacity.
The following three workspaces will be created:
* AnalyticsPOC: Will contain the data store, semantic models, reports, pipelines, dataflows, and notebooks used to populate the data store
* DataEngPOC: Will contain all the pipelines, dataflows, and notebooks used to populate Onelake
* DataSciPOC: Will contain all the notebooks and reports created by the data scientists The following will be created in the AnalyticsPOC workspace:
* A data store (type to be decided)
* A custom semantic model
* A default semantic model
* Interactive reports
The data engineers will create data pipelines to load data to OneLake either hourly or daily depending on the data source. The analytics engineers will create processes to ingest transform, and load the data to the data store in the AnalyticsPOC workspace daily. Whenever possible, the data engineers will use low-code tools for data ingestion. The choice of which data cleansing and transformation tools to use will be at the data engineers' discretion.
All the semantic models and reports in the Analytics POC workspace will use the data store as the sole data source.
Technical Requirements
The data store must support the following:
* Read access by using T-SQL or Python
* Semi-structured and unstructured data
* Row-level security (RLS) for users executing T-SQL queries
Files loaded by the data engineers to OneLake will be stored in the Parquet format and will meet Delta Lake specifications.
Data will be loaded without transformation in one area of the AnalyticsPOC data store. The data will then be cleansed, merged, and transformed into a dimensional model.
The data load process must ensure that the raw and cleansed data is updated completely before populating the dimensional model.
The dimensional model must contain a date dimension. There is no existing data source for the date dimension. The Litware fiscal year matches the calendar year. The date dimension must always contain dates from 2010 through the end of the current year.
The product pricing group logic must be maintained by the analytics engineers in a single location. The pricing group data must be made available in the data store for T-SQL queries and in the default semantic model. The following logic must be used:
* List prices that are less than or equal to 50 are in the low pricing group.
* List prices that are greater than 50 and less than or equal to 1,000 are in the medium pricing group.
* List pnces that are greater than 1,000 are in the high pricing group.
Security Requirements
Only Fabric administrators and the analytics team must be able to see the Fabric items created as part of the PoC. Litware identifies the following security requirements for the Fabric items in the AnalyticsPOC workspace:
* Fabric administrators will be the workspace administrators.
* The data engineers must be able to read from and write to the data store. No access must be granted to datasets or reports.
* The analytics engineers must be able to read from, write to, and create schemas in the data store. They also must be able to create and share semantic models with the data analysts and view and modify all reports in the workspace.
* The data scientists must be able to read from the data store, but not write to it. They will access the data by using a Spark notebook.
* The data analysts must have read access to only the dimensional model objects in the data store. They also must have access to create Power Bl reports by using the semantic models created by the analytics engineers.
* The date dimension must be available to all users of the data store.
* The principle of least privilege must be followed.
Both the default and custom semantic models must include only tables or views from the dimensional model in the data store. Litware already has the following Microsoft Entra security groups:
* FabricAdmins: Fabric administrators
* AnalyticsTeam: All the members of the analytics team
* DataAnalysts: The data analysts on the analytics team
* DataScientists: The data scientists on the analytics team
* Data Engineers: The data engineers on the analytics team
* Analytics Engineers: The analytics engineers on the analytics team
Report Requirements
The data analysis must create a customer satisfaction report that meets the following requirements:
* Enables a user to select a product to filter customer survey responses to only those who have purchased that product
* Displays the average overall satisfaction score of all the surveys submitted during the last 12 months up to a selected date
* Shows data as soon as the data is updated in the data store
* Ensures that the report and the semantic model only contain data from the current and previous year
* Ensures that the report respects any table-level security specified in the source data store
* Minimizes the execution time of report queries
質問 # 19
You have a Fabric workspace named Workspace1 and an Azure Data Lake Storage Gen2 account named storage"!. Workspace1 contains a lakehouse named Lakehouse1.
You need to create a shortcut to storage! in Lakehouse1.
Which connection and endpoint should you specify? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.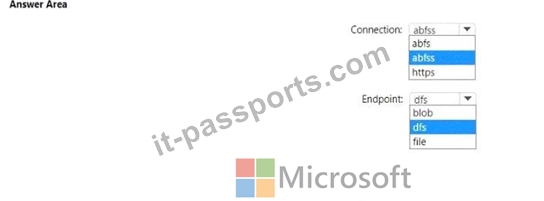
正解:
解説: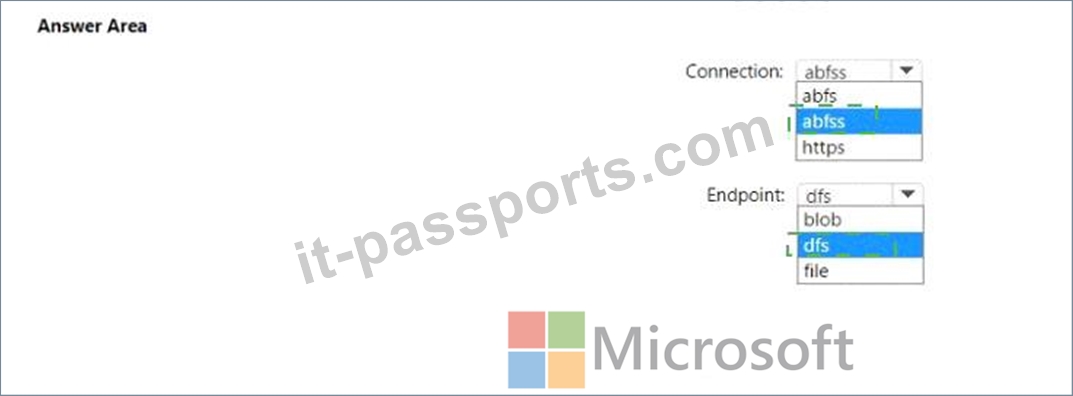
Explanation: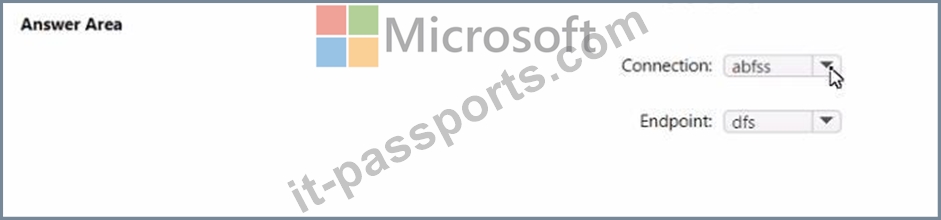
When creating a shortcut to an Azure Data Lake Storage Gen2 account in a lakehouse, you should use the abfss (Azure Blob File System Secure) connection string and the dfs (Data Lake File System) endpoint. The abfss is used for secure access to Azure Data Lake Storage, and the dfs endpoint indicates that the Data Lake Storage Gen2 capabilities are to be used.
質問 # 20
You have a Fabric tenant.
You plan to create a Fabric notebook that will use Spark DataFrames to generate Microsoft Power Bl visuals.
You run the following code.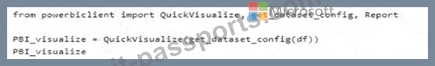
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.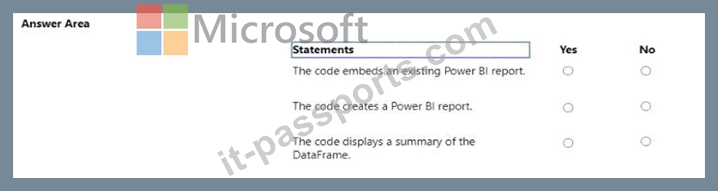
正解:
解説: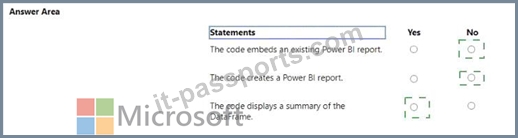
Explanation:
* The code embeds an existing Power BI report. - No
* The code creates a Power BI report. - Yes
* The code displays a summary of the DataFrame. - Yes
The code provided seems to be a snippet from a SQL query or script which is neither creating nor embedding a Power BI report directly. It appears to be setting up a DataFrame for use within a larger context, potentially for visualization in Power BI, but the code itself does not perform the creation or embedding of a report.
Instead, it's likely part of a data processing step that summarizes data.
References =
* Introduction to DataFrames - Spark SQL
* Power BI and Azure Databricks
質問 # 21
You have the following KQL query.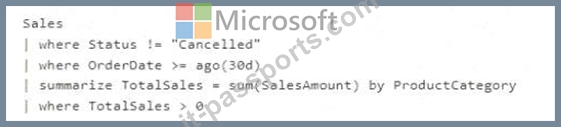
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.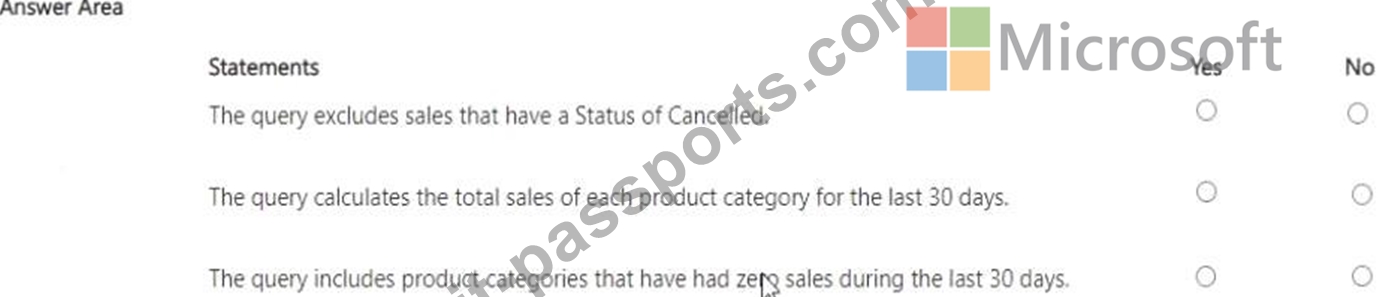
正解:
解説: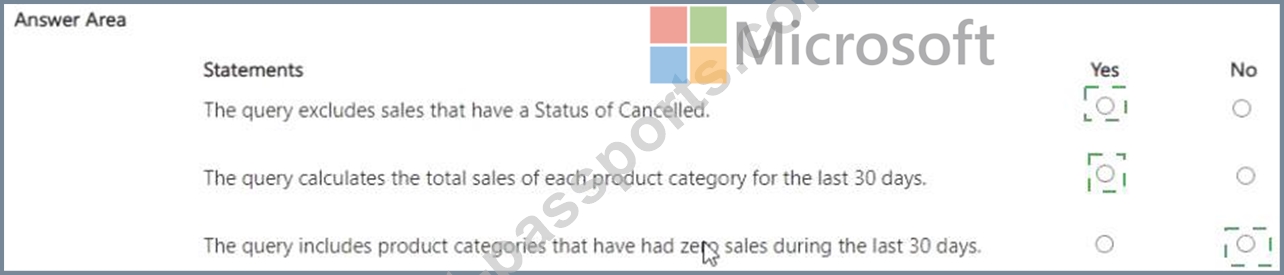
Explanation: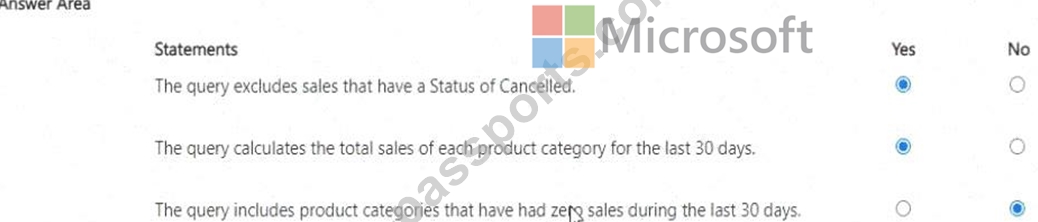
質問 # 22
You need to resolve the issue with the pricing group classification.
How should you complete the T-SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.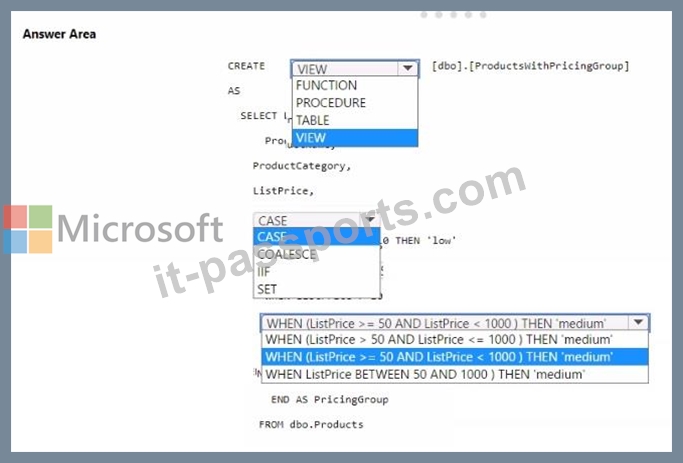
正解:
解説: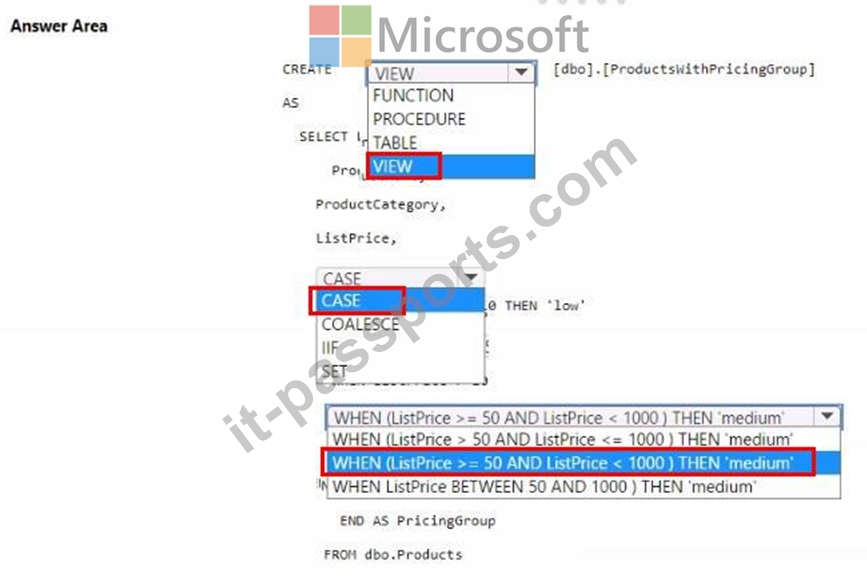
質問 # 23
......
MicrosoftのDP-600認定試験は実は技術専門家を認証する試験です。 MicrosoftのDP-600認定試験はIT人員が優れたキャリアを持つことを助けられます。優れたキャリアを持ったら、社会と国のために色々な利益を作ることができて、国の経済が継続的に発展していることを進められるようになります。全てのIT人員がそんなにられるとしたら、国はぜひ強くなります。It-PassportsのMicrosoftのDP-600試験トレーニング資料はIT人員の皆さんがそんな目標を達成できるようにヘルプを提供して差し上げます。It-PassportsのMicrosoftのDP-600試験トレーニング資料は100パーセントの合格率を保証しますから、ためらわずに決断してIt-Passportsを選びましょう。
DP-600関連復習問題集: https://www.it-passports.com/DP-600.html
BONUS!!! It-Passports DP-600ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1S30lqzkHb0YBsHr56sV7538FKVGRL9l0