P.S. Free 2026 Microsoft DP-700 dumps are available on Google Drive shared by ExamcollectionPass: https://drive.google.com/open?id=10kYuyLaOyx7JyrkQVKh8ET4f1n65uKqF
Our DP-700 test prep is of high quality. The passing rate and the hit rate are both high. The passing rate is about 98%-100%. We can guarantee that you have a very high possibility to pass the exam. The DP-700 guide torrent is compiled by the experts and approved by the professionals with rich experiences. The DP-700 prep torrent is the products of high quality complied elaborately and gone through strict analysis and summary according to previous exam papers and the popular trend in the industry. The language of the DP-700 exam material is simple and easy to be understood.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Implementing Data Engineering Solutions Using Microsoft Fabric |
| Exam Number: | DP-700 |
| Related Certifications: | Microsoft Certified: Power BI Data Analyst Associate Microsoft Certified: Azure Data Engineer Associate |
| Real Exam Qty: | 50–60 |
| Certificate Validity Period: | 1 year |
| Exam Duration: | 100 minutes |
| Exam Price: | $165 USD |
| Exam Format: | Interactive items, Scenario-based, Multiple select, Case studies, Multiple choice |
| Available Languages: | French, Chinese (Simplified), English, German, Korean, Japanese, Portuguese (Brazil), Spanish |
| Passing Score: | 700 (scaled score 100–1000) |
| Recommended Training: | Microsoft Learn: Implementing Data Engineering Solutions Using Microsoft Fabric Microsoft Fabric Documentation |
| Exam Registration: | Microsoft Official Exam Registration Pearson VUE Registration |
| Sample Questions: | Microsoft DP-700 Sample Questions |
| Exam Way: | Online proctored or onsite testing center |
| Pre Condition: | No mandatory prerequisites; recommended experience with data integration, transformation, SQL, PySpark, KQL, and Microsoft Fabric |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/resources/study-guides/dp-700 |
>> Latest DP-700 Study Notes <<
We have developed three versions of our DP-700 exam questions. So you can choose the version of DP-700 training guide according to your interests and habits. And if you buy the value pack, you have all of the three versions, the price is quite preferential and you can enjoy all of the study experiences. This means you can study DP-700 Practice Engine anytime and anyplace for the convenience these three versions bring.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 104
You have a Fabric notebook named Notebook1 that has been executing successfully for the last week.
During the last run, Notebook1executed nine jobs.
You need to view the jobs in a timeline chart.
What should you use?
Answer: E
Explanation:
The run series from the details of the application run is the most detailed and relevant feature for visualizing job execution in a timeline format, making it the correct choice for this scenario. It provides an intuitive way to analyze job execution patterns and improve the efficiency of the notebook.
NEW QUESTION # 105
HOTSPOT
You are processing streaming data from an external data provider.
You have the following code segment.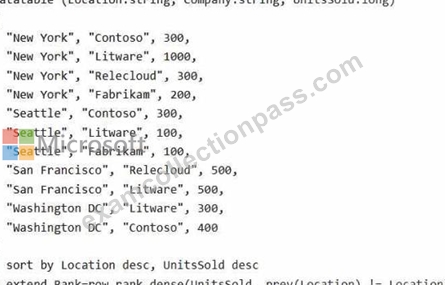
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.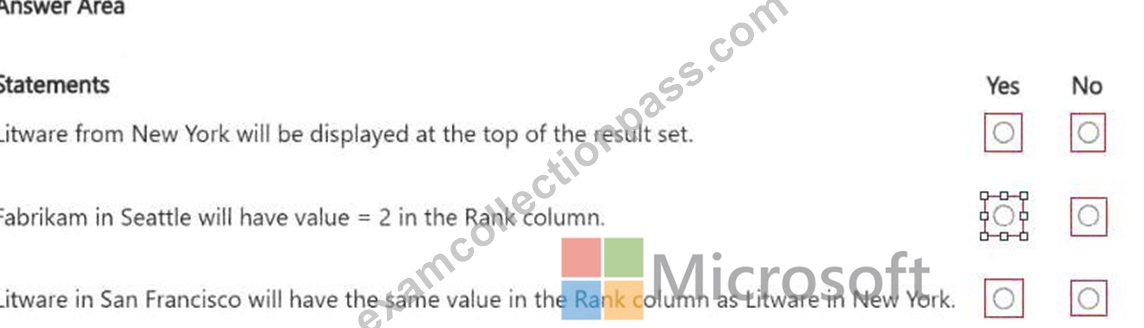
Answer:
Explanation: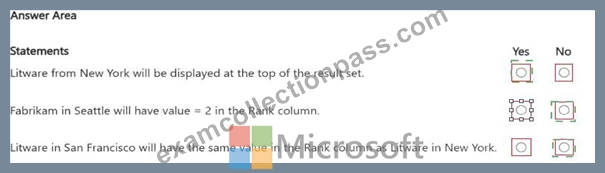
Explanation: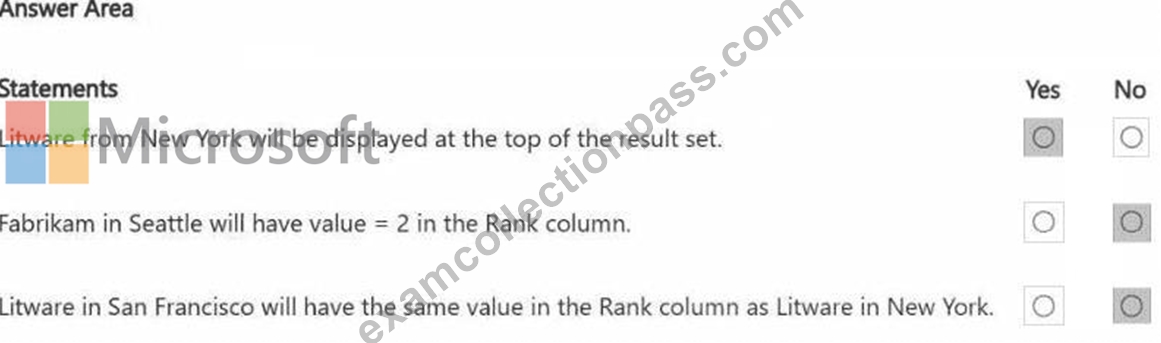
Litware from New York will be displayed at the top of the result set - Yes The data is sorted first by Location in descending order and then by UnitsSold in descending order. Since
"New York" is alphabetically the last Location, it will appear first in the result set. Within "New York", Litware has the highest UnitsSold (1000), so it will be displayed at the top.
Fabrikam in Seattle will have value = 2 in the Rank column - No
The row_rank_dense function assigns dense ranks based on UnitsSold within each location. In "Seattle":
Contoso has UnitsSold = 300 # Rank 1
Litware has UnitsSold = 100 # Rank 2
Fabrikam also has UnitsSold = 100, so it shares the same rank (2) as Litware.
Litware in San Francisco will have the same value in the Rank column as Litware in New York - No The rank is calculated separately for each location. In "San Francisco":
Both Relecloud and Litware have UnitsSold = 500, so they share the same rank (1).
In "New York", Litware has the highest UnitsSold = 1000 # Rank 1.
Since ranks are calculated independently for each location, Litware in San Francisco does not share the same rank as Litware in New York.
NEW QUESTION # 106
Your company has three newly created data engineering teams named Team1, Team2, and Team3 that plan to use Fabric. The teams have the following personas:
* Team1 consists of members who currently use Microsoft Power BI. The team wants to transform data by using by a low-code approach.
* Team2 consists of members that have a background in Python programming. The team wants to use PySpark code to transform data.
* Team3 consists of members who currently use Azure Data Factory. The team wants to move data between source and sink environments by using the least amount of effort.
You need to recommend tools for the teams based on their current personas.
What should you recommend for each team? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.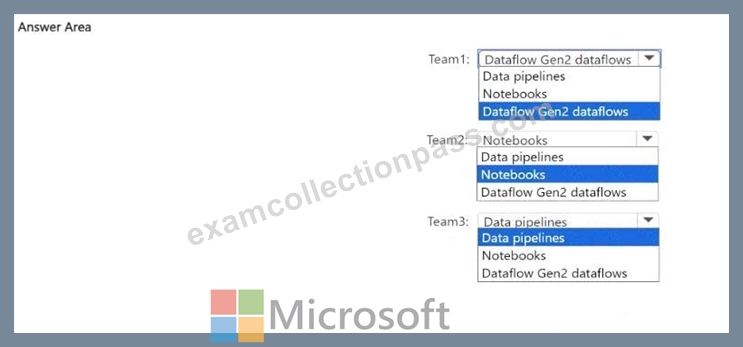
Answer:
Explanation: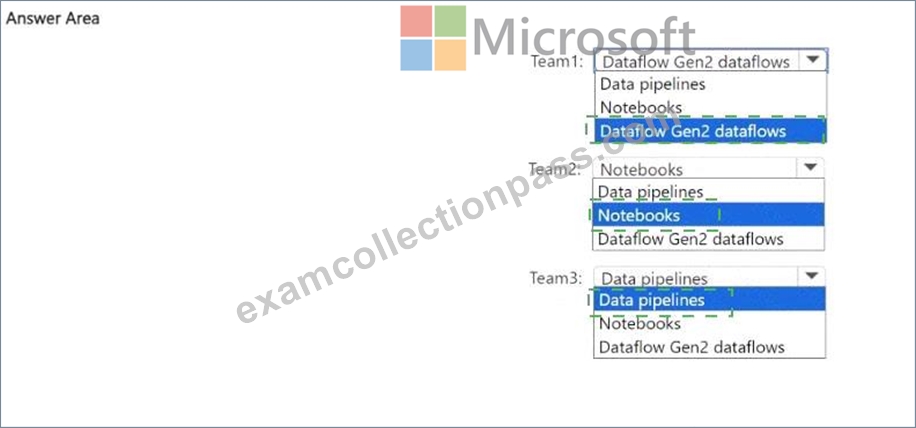
Explanation: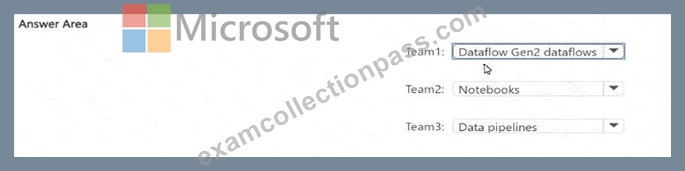
NEW QUESTION # 107
You have an Azure Data Lake Storage Gen2 account named storage1 and an Amazon S3 bucket named storage2.
You have the Delta Parquet files shown in the following table.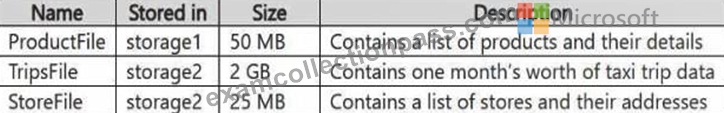
You have a Fabric workspace named Workspace1 that has the cache for shortcuts enabled. Workspace1 contains a lakehouse named Lakehouse1. Lakehouse1 has the following shortcuts:
The data from which shortcuts will be retrieved from the cache?
Answer: B
Explanation:
When the cache for shortcuts is enabled in Fabric, the data retrieval is governed by the caching behavior, which generally retains data for a specific period after it was last accessed. The data from the shortcuts will be retrieved from the cache if the data is stored in locations that support caching. Here's a breakdown based on the data's location:
Products: The ProductFile is stored in Azure Data Lake Storage Gen2 (storage1). Since Azure Data Lake is a supported storage system in Fabric and the file is relatively small (50 MB), this data is most likely cached and can be retrieved from the cache.
Stores: The StoreFile is stored in Amazon S3 (storage2), and even though it is stored in a different cloud provider, Fabric can cache data from Amazon S3 if caching is enabled. This data (25 MB) is likely cached and retrievable.
Trips: The TripsFile is stored in Amazon S3 (storage2) and is significantly larger (2 GB) compared to the other files. While Fabric can cache data from Amazon S3, the larger size of the file (2 GB) may exceed typical cache sizes or retention windows, causing this file to likely be retrieved directly from the source instead of the cache.
NEW QUESTION # 108
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric eventstream that loads data into a table named Bike_Location in a KQL database. The table contains the following columns:
BikepointID
Street
Neighbourhood
No_Bikes
No_Empty_Docks
Timestamp
You need to apply transformation and filter logic to prepare the data for consumption. The solution must return data for a neighbourhood named Sands End when No_Bikes is at least 15. The results must be ordered by No_Bikes in ascending order.
Solution: You use the following code segment: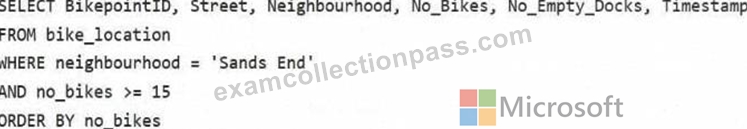
Does this meet the goal?
Answer: B
Explanation:
This code does not meet the goal because this is an SQL-like query and cannot be executed in KQL, which is required for the database.
Correct code should look like:
NEW QUESTION # 109
......
Test DP-700 Dumps.zip: https://www.examcollectionpass.com/Microsoft/DP-700-practice-exam-dumps.html
P.S. Free & New DP-700 dumps are available on Google Drive shared by ExamcollectionPass: https://drive.google.com/open?id=10kYuyLaOyx7JyrkQVKh8ET4f1n65uKqF