BONUS!!! Download part of ValidBraindumps DP-700 dumps for free: https://drive.google.com/open?id=1-Z4FJ2g0mdQgCpx8klEwbwoZmwDJxism
As the quick development of the world economy and intense competition in the international, the world labor market presents many new trends: company’s demand for the excellent people is growing. As is known to us, the DP-700 certification is one mainly mark of the excellent. If you want to improve your correct rates of exam, we believe the best method is inscribed according to the fault namely this in appearing weak sports, specific aim ground consolidates knowledge is nodded. Our DP-700 Guide Torrent will help you establish the error sets. We believe that it must be very useful for you to take your exam, and it is necessary for you to use our DP-700 test questions.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
When you have adequately prepared for the Implementing Data Engineering Solutions Using Microsoft Fabric (DP-700) questions, only then you become capable of passing the Microsoft exam. There is no purpose in attempting the Microsoft DP-700 certification exam if you have not prepared with ValidBraindumps's Free Microsoft DP-700 PDF Questions. It's time to get serious if you want to validate your abilities and earn the Microsoft DP-700 Certification. If you hope to pass the Implementing Data Engineering Solutions Using Microsoft Fabric exam on your first attempt, you must be studied with real DP-700 exam questions verified by Microsoft DP-700.
NEW QUESTION # 38
You have a Fabric workspace named Workspace1 that contains the items shown in the following table.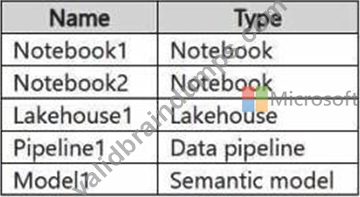
For Model1, the Keep your Direct Lake data up to date option is disabled.
You need to configure the execution of the items to meet the following requirements:
How should you orchestrate each item? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.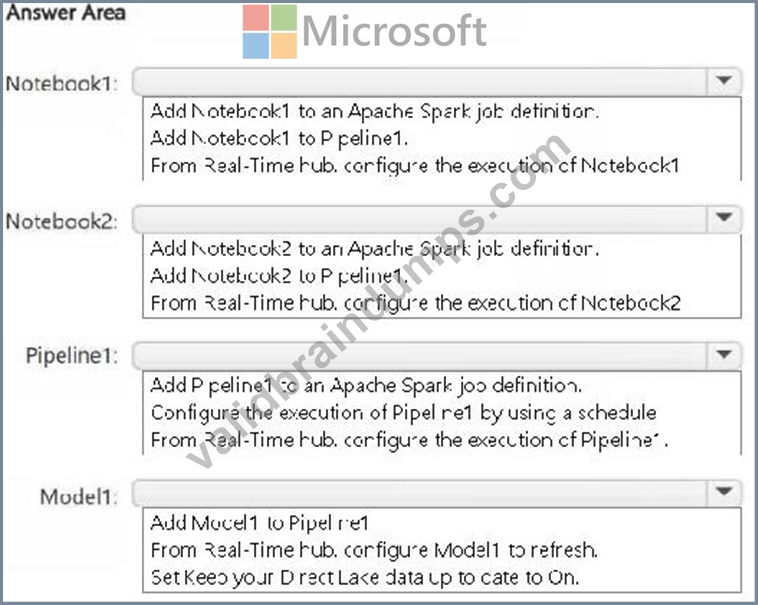
Answer:
Explanation: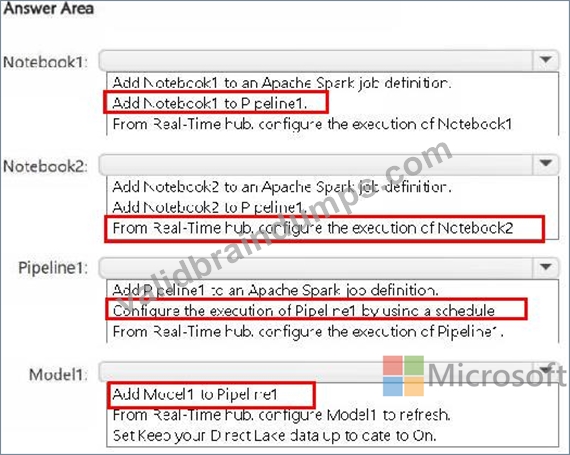
NEW QUESTION # 39
You have a Fabric .
In Warehouse1, you create a table named DimCustomer by running the following statement.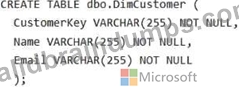
You need to set the Customerkey column as a primary key of the DimCustomer table.
Which three code segments should you run in sequence? To answer, move the appropriate code segments from the list of code segments to the answer area and arrange them in the correct order.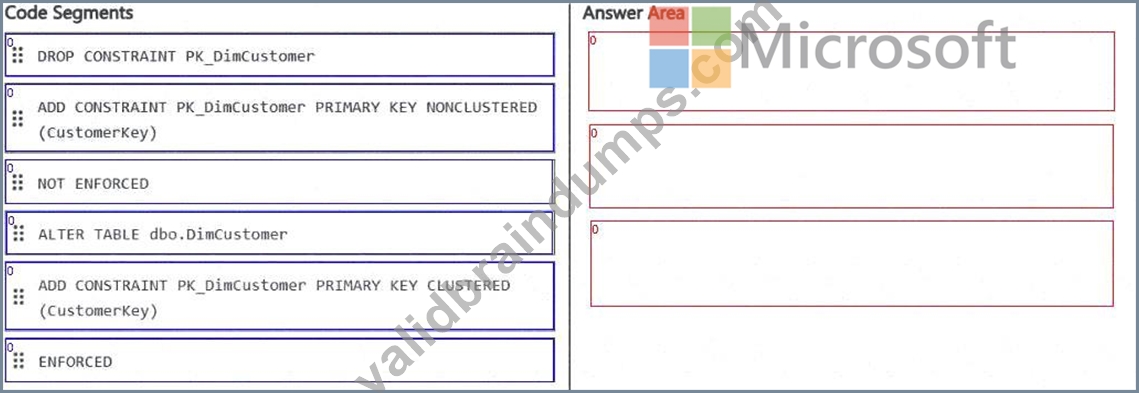
Answer:
Explanation: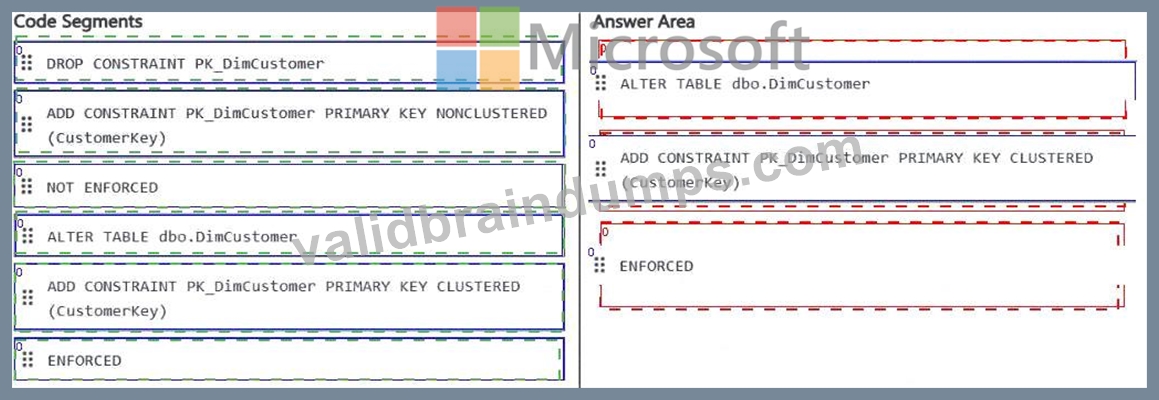
Explanation: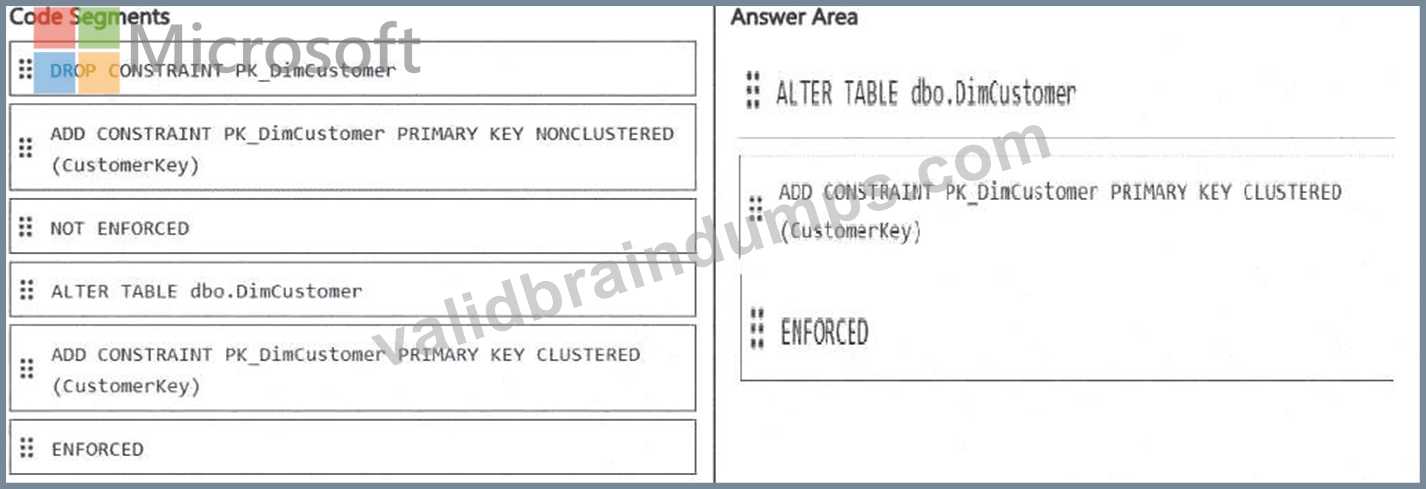
NEW QUESTION # 40
You have a Fabric warehouse named DW1 that loads data by using a data pipeline named Pipeline1. Pipeline1 uses a Copy data activity with a dynamic SQL source. Pipeline1 is scheduled to run every 15 minutes.
You discover that Pipeline1 keeps failing.
You need to identify which SQL query was executed when the pipeline failed.
What should you do?
Answer: A
Explanation:
The input JSON contains the configuration details and parameters passed to the Copy data activity during execution, including the dynamically generated SQL query.
Viewing the input JSON for the failed pipeline run provides direct insight into what query was executed at the time of failure.
NEW QUESTION # 41
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a KQL database that contains two tables named Stream and Reference. Stream contains streaming data in the following format.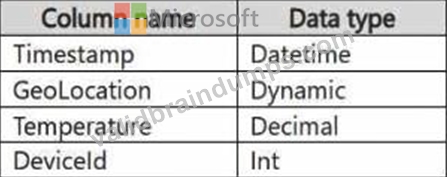
Reference contains reference data in the following format.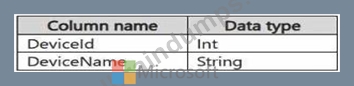
Both tables contain millions of rows.
You have the following KQL queryset.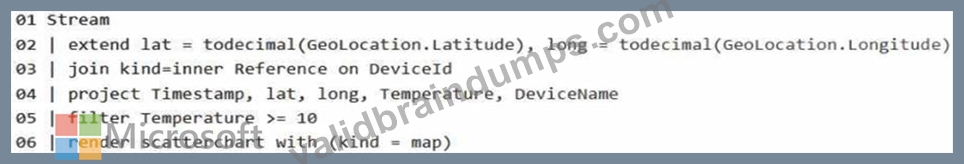
You need to reduce how long it takes to run the KQL queryset.
Solution: You add the make_list() function to the output columns.
Does this meet the goal?
Answer: A
Explanation:
Adding an aggregation like make_list() would require additional processing and memory, which could make the query slower.
NEW QUESTION # 42
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric eventstream that loads data into a table named Bike_Location in a KQL database. The table contains the following columns:
BikepointID
Street
Neighbourhood
No_Bikes
No_Empty_Docks
Timestamp
You need to apply transformation and filter logic to prepare the data for consumption. The solution must return data for a neighbourhood named Sands End when No_Bikes is at least 15. The results must be ordered by No_Bikes in ascending order.
Solution: You use the following code segment: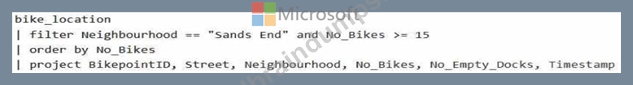
Does this meet the goal?
Answer: B
Explanation:
This code does not meet the goal because it uses order by, which is not valid in KQL. The correct term in KQL is sort by.
Correct code should look like: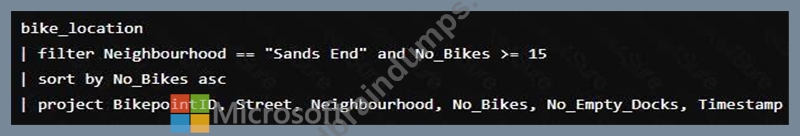
NEW QUESTION # 43
......
We have harmonious cooperation with exam candidates. The relation comes from the excellence of our DP-700 training materials. We never avoid our responsibility of offering help for exam candidates like you, so choosing our DP-700 practice dumps means you choose success. Moreover, without the needs of waiting, you can download the DP-700 Study Guide after paying for it immediately. And we have patient and enthusiastic staff offering help on our DP-700 learning prep.
DP-700 Reliable Test Labs: https://www.validbraindumps.com/DP-700-exam-prep.html
What's more, part of that ValidBraindumps DP-700 dumps now are free: https://drive.google.com/open?id=1-Z4FJ2g0mdQgCpx8klEwbwoZmwDJxism