BTW, DOWNLOAD part of Free4Torrent Databricks-Generative-AI-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1V-iuP2l0LJxVCak2KtQZCVIb_ivfTSzU
The system of our Databricks-Generative-AI-Engineer-Associate latest exam file is great. It is developed and maintained by our company's professional personnel and is dedicated to provide the first-tier service to the clients. Our system updates the Databricks-Generative-AI-Engineer-Associate exam questions periodically and frequently to provide more learning resources and responds to the clients' concerns promptly. Our system will supplement new Databricks-Generative-AI-Engineer-Associate Latest Exam file and functions according to the clients' requirements and surveys the clients' satisfaction degrees about our Databricks-Generative-AI-Engineer-Associate cram materials. The Databricks-Generative-AI-Engineer-Associate exam will be a piece of cake with our Databricks-Generative-AI-Engineer-Associate exam prep.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Databricks-Generative-AI-Engineer-Associate Exam Format <<
You can run the Databricks Certified Generative AI Engineer Associate Databricks-Generative-AI-Engineer-Associate PDF Questions file on any device laptop, smartphone or tablet, etc. You just need to memorize all Databricks-Generative-AI-Engineer-Associate exam questions in the pdf dumps file. Databricks Databricks-Generative-AI-Engineer-Associate practice test software (Web-based and desktop) is specifically useful to attempt the Databricks-Generative-AI-Engineer-Associate Practice Exam. It has been a proven strategy to pass professional exams like the Databricks Databricks-Generative-AI-Engineer-Associate exam in the last few years. Databricks Certified Generative AI Engineer Associate Databricks-Generative-AI-Engineer-Associate practice test software is an excellent way to engage candidates in practice.
NEW QUESTION # 54
A Generative AI Engineer is deploying an agent using Mosaic AI Model Serving. The agent needs to access various Databricks resources, including Vector Search, Databricks SQL, and Functions. They need to find the easiest and best-practice way to authenticate the deployed agent to access these resources.
What approach should they choose?
Answer: D
NEW QUESTION # 55
Databricks offers a number of built-in AI judges that provide metrics and rationale for different types of quality issues a Generative AI application may have.
Which of the following pairs of judges both require a ground-truth label in the evaluation dataset field expected_response to execute?
Answer: D
Explanation:
In the Agent Evaluation terminology used by this question, correctness compares the generated response with the expected answer, while context_sufficiency determines whether the retrieved context contains enough information to produce that expected answer. Both therefore depend on ground-truth information supplied through expected_response. Groundedness instead examines whether the response is supported by the retrieved context; it does not inherently need a reference answer. Chunk relevance and relevance to the query assess alignment with the user's request, while guideline adherence evaluates compliance with specified instructions. Databricks explicitly distinguishes the ground-truth-dependent judges in its migration documentation. In MLflow 3, names and schemas have evolved, including expectations.expected_response and explicitly selected scorers, so the question should be interpreted using its stated legacy judge terminology.
Databricks documentation
NEW QUESTION # 56
A Generative AI Engineer I using the code below to test setting up a vector store: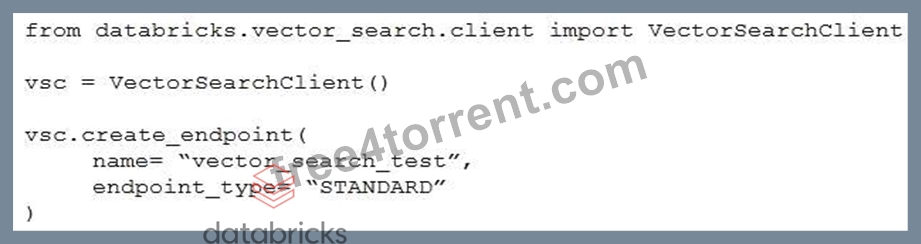
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: D
Explanation:
Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options:
* Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, henceOption B.
NEW QUESTION # 57
A Generative AI Engineer at an automotive company would like to build a question-answering chatbot to help customers answer specific questions about their vehicles. They have:
A catalog with hundreds of thousands of cars manufactured since the 1960s Historical searches with user queries and successful matches Descriptions of their own cars in multiple languages They have already selected an open-source LLM and created a test set of user queries. They need to discard techniques that will not help them build the chatbot. Which do they discard?
Answer: A
Explanation:
According to Generative AI engineering standards for Retrieval-Augmented Generation (RAG), chunking strategy is a critical optimization variable. Setting the chunk size to match the model's maximum context window (e.g., 4k or 8k tokens) is a poor practice and should be discarded. Large chunks introduce significant "noise" into the LLM's context, as only a small portion of a massive chunk usually contains the answer to a specific query. This leads to the "lost in the middle" phenomenon where LLMs struggle to extract relevant information from bloated contexts. Furthermore, large chunks reduce the precision of the vector search. Standard best practices involve using smaller, semantically meaningful chunks (typically 256-512 tokens) with overlap to maintain context. In contrast, metadata filtering (B) is essential for narrowing searches to specific car years, fine-tuning embeddings (C) improves retrieval accuracy for domain-specific technical terms, and few-shot examples (D) guide the LLM's output format and tone.
NEW QUESTION # 58
A Generative AI Engineer is building a Databricks-hosted assistant that must (1) query Unity Catalog tables with row and column permissions enforced, and (2) avoid managing any external infrastructure. The team wants the LLM to use governed data access through tools exposed via MCP.
Which MCP server choice meets these constraints?
Answer: C
Explanation:
A managed Databricks MCP server provides tools for accessing Databricks services without requiring the team to host an external server. For structured table queries, a suitable managed SQL or Genie tool uses Databricks-governed data access. Unity Catalog remains responsible for authorization instead of delegating security decisions to the language model. When permissions must reflect the individual requester, the application must use the appropriate user authorization configuration so row filters and column masks are evaluated for that identity. Passing credentials in prompts exposes secrets unnecessarily. A self-managed virtual machine violates the infrastructure requirement. Direct JDBC access also fails the requested MCP architecture and introduces custom integration work. Managed hosting simplifies deployment while preserving the platform's access-control model. Databricks tools documentation , authentication documentation
NEW QUESTION # 59
......
Once you browser our official websites, you are bound to love our Databricks-Generative-AI-Engineer-Associate practice questions. All our Databricks-Generative-AI-Engineer-Associate study materials are displayed orderly on the web page. Also, you just need to click one kind; then you can know much about it. There have detailed introductions about the Databricks-Generative-AI-Engineer-Associate learnign braindumps such as price, version, free demo and so on. As long as you click on it, all the information will show up right away. It is quite convenient.
Real Databricks-Generative-AI-Engineer-Associate Dumps Free: https://www.free4torrent.com/Databricks-Generative-AI-Engineer-Associate-braindumps-torrent.html
DOWNLOAD the newest Free4Torrent Databricks-Generative-AI-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1V-iuP2l0LJxVCak2KtQZCVIb_ivfTSzU