What's more, part of that Dumpleader DP-700 dumps now are free: https://drive.google.com/open?id=1l3iuoDoGHyephW6Eq1XXtY5CaPEOF8PJ
As a prestigious platform offering practice material for all the IT candidates, Dumpleader experts try their best to research the best valid and useful DP-700 exam dumps to ensure you 100% pass. The contents of DP-700 exam training material cover all the important points in the DP-700 Actual Test, which can ensure the high hit rate. You can instantly download the DP-700 practice dumps and concentrate on your study immediately.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Implementing Data Engineering Solutions Using Microsoft Fabric |
| Exam Number: | DP-700 |
| Passing Score: | 700 (scaled score 100–1000) |
| Exam Price: | $165 USD |
| Real Exam Qty: | 50–60 |
| Related Certifications: | Microsoft Certified: Azure Data Engineer Associate Microsoft Certified: Power BI Data Analyst Associate |
| Certificate Validity Period: | 1 year |
| Exam Duration: | 100 minutes |
| Exam Format: | Multiple select, Interactive items, Case studies, Scenario-based, Multiple choice |
| Available Languages: | Portuguese (Brazil), Japanese, Spanish, French, Chinese (Simplified), Korean, English, German |
| Recommended Training: | Microsoft Learn: Implementing Data Engineering Solutions Using Microsoft Fabric Microsoft Fabric Documentation |
| Exam Registration: | Pearson VUE Registration Microsoft Official Exam Registration |
| Sample Questions: | Microsoft DP-700 Sample Questions |
| Exam Way: | Online proctored or onsite testing center |
| Pre Condition: | No mandatory prerequisites; recommended experience with data integration, transformation, SQL, PySpark, KQL, and Microsoft Fabric |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/resources/study-guides/dp-700 |
We prepare everything you need to prepare, and help you pass the exam easily. The DP-700 exam braindumps of us have the significant information for the exam, if you use it, you will learn the basic knowledge as well as some ways. We offer free update for you, and you will get the latest version timely, and you just need to practice the DP-700 Exam Dumps. We believe that with the joint efforts of both us, you will gain a satisfactory result.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 56
You have a Fabric workspace that contains a lakehouse named Lakehousel. Lakehousel contains a table named Status_Target that has the following columns:
* Key
* Status
* LastModified
The data source contains a table named Status.Source that has the same columns as Status_Target. Status.
Source is used to populate Status_Target. In a notebook name Notebook!, you load Status_Source to a DataFrame named sourceDF and Status_Target to a DataFrame named targetDF. You need to implement an incremental loading pattern by using Notebook-!. The solution must meet the following requirements:
* For all the matching records that have the same value of key, update the value of LastModified in Status_Target to the value of LastModified in Status_Source.
* Insert all the records that exist in Status_Source that do NOT exist in Status_Target.
* Set the value of Status in Status_Target to inactive for all the records that were last modified more than seven days ago and that do NOT exist in Status.Source.
How should you complete the statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.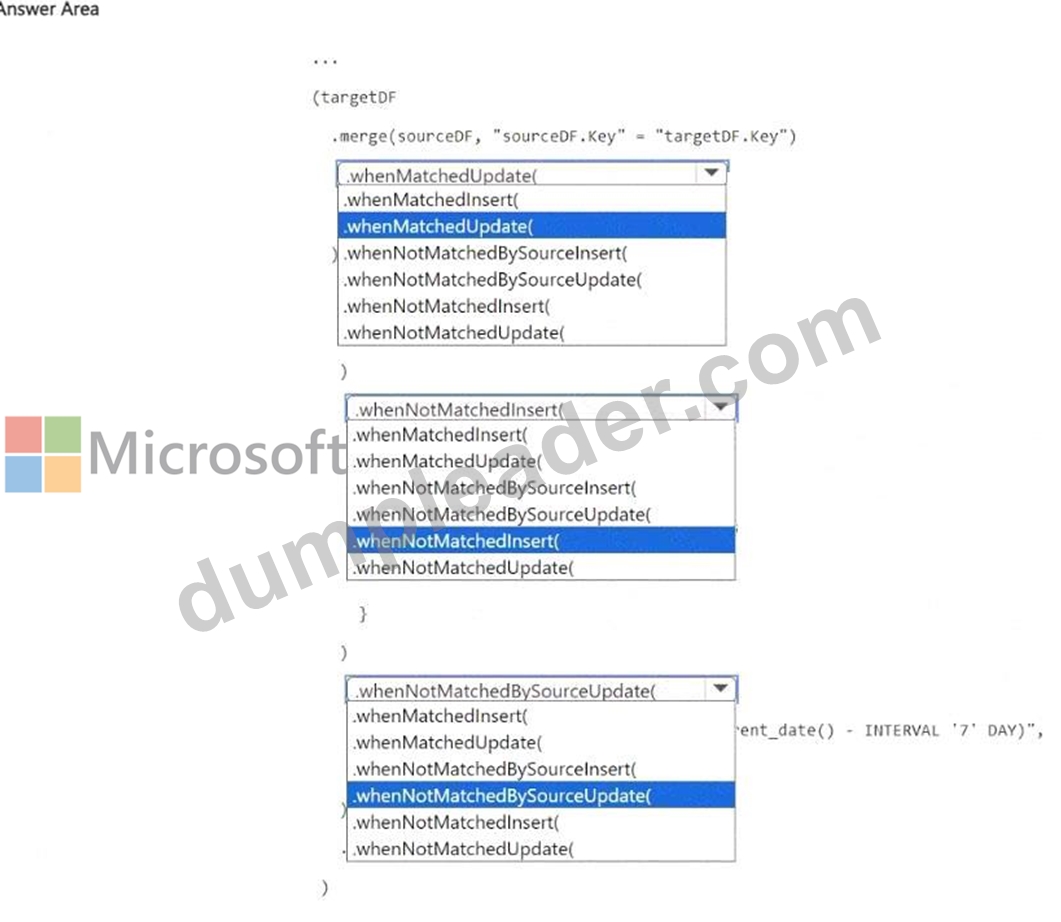
Answer:
Explanation: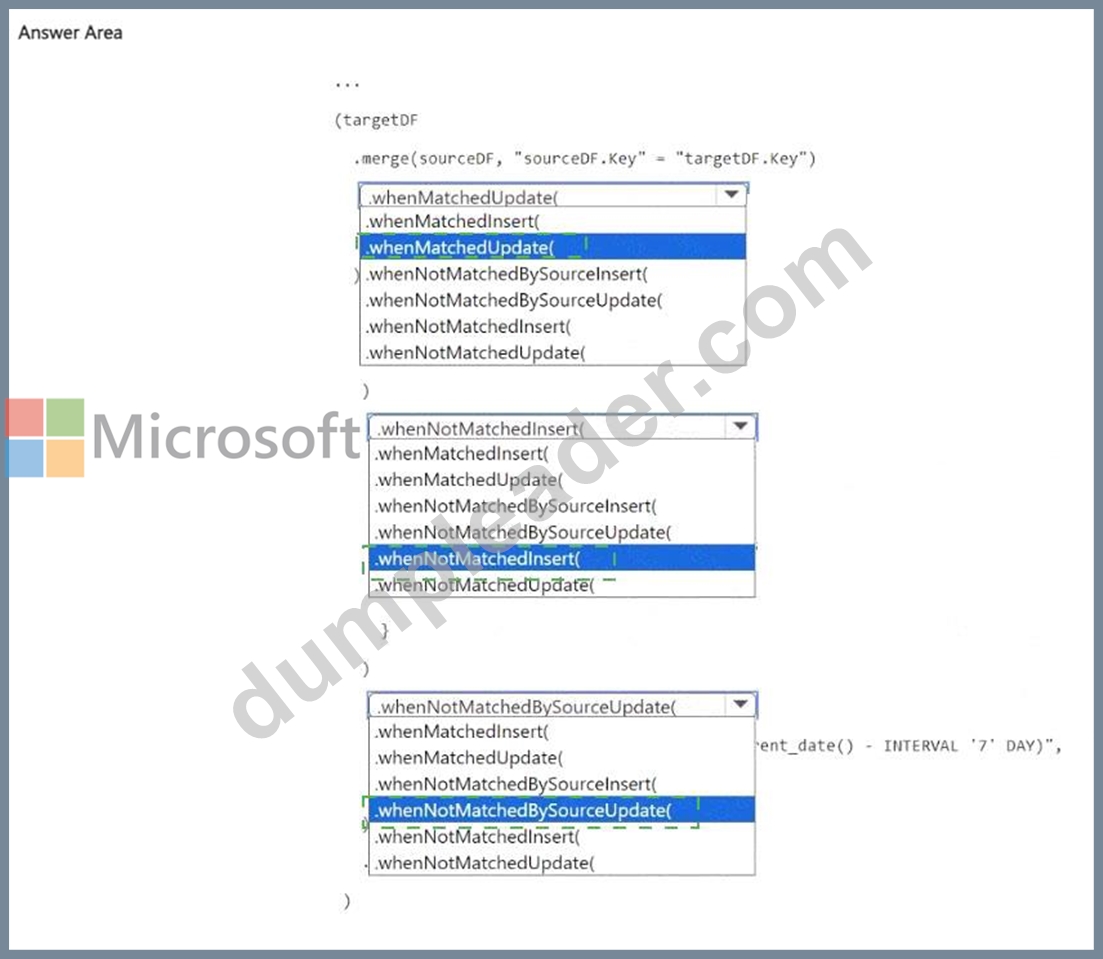
Explanation: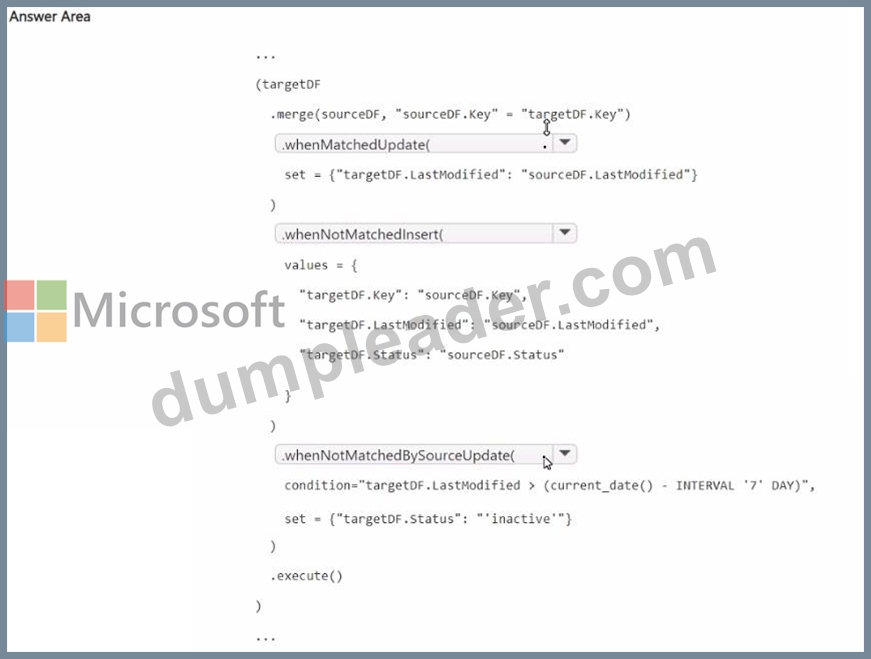
NEW QUESTION # 57
You have a KQL database that contains two table named Stream and Reference. Stream contains streaming data in the following format.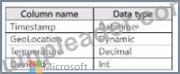
Reference contains reference data in the following format.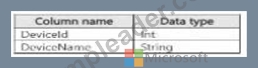
Both tables contains millions of rows.
You have the following KQL queryset.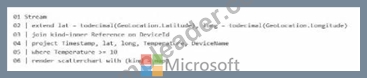
You need to reduce how long it takes to run KQL queryset.
Solution: You move the line 05 to line 02.
Does this meet the goal?
Answer: A
NEW QUESTION # 58
HOTSPOT
You have a Fabric workspace that contains two lakehouses named Lakehouse1 and Lakehouse2. Lakehouse1 contains staging data in a Delta table named Orderlines. Lakehouse2 contains a Type 2 slowly changing dimension (SCD) dimension table named Dim_Customer.
You need to build a query that will combine data from Orderlines and Dim_Customer to create a new fact table named Fact_Orders. The new table must meet the following requirements:
Enable the analysis of customer orders based on historical attributes.
Enable the analysis of customer orders based on the current attributes.
How should you complete the statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.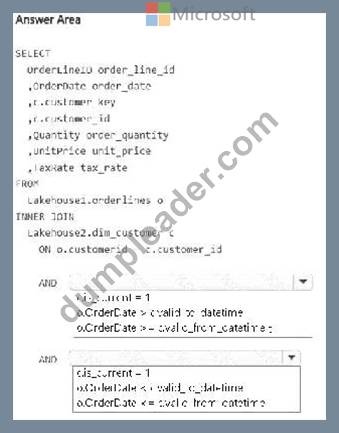
Answer:
Explanation: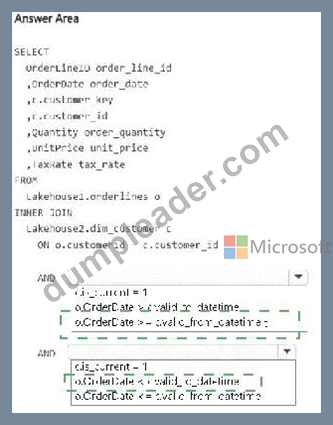
Explanation: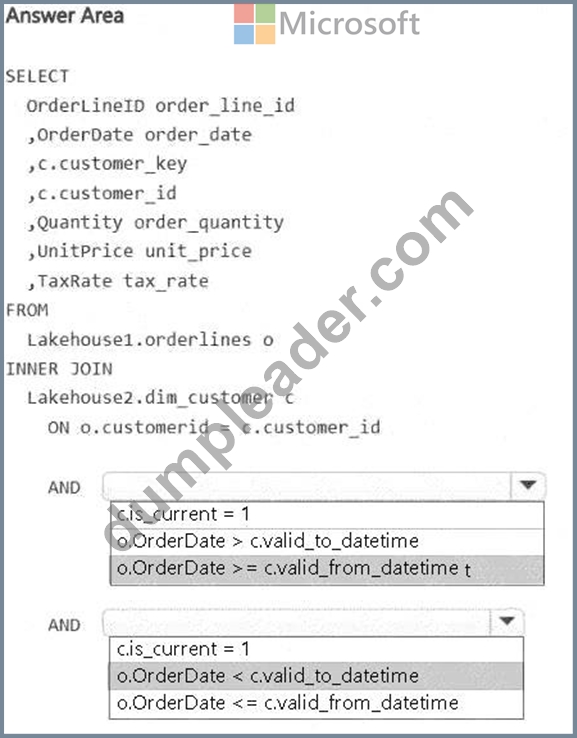
NEW QUESTION # 59
You need to schedule the population of the medallion layers to meet the technical requirements.
What should you do?
Answer: B
Explanation:
The technical requirements specify that:
Why Use a Data Pipeline That Calls Other Data Pipelines?
- Sequential execution of child pipelines.
- Error handling to send email notifications upon failures.
- Parallel execution of tasks where possible (e.g., simultaneous imports into the bronze layer).
NEW QUESTION # 60
DRAG DROP
You have a Fabric eventhouse that contains a KQL database. The database contains a table named TaxiData.
The following is a sample of the data in TaxiData.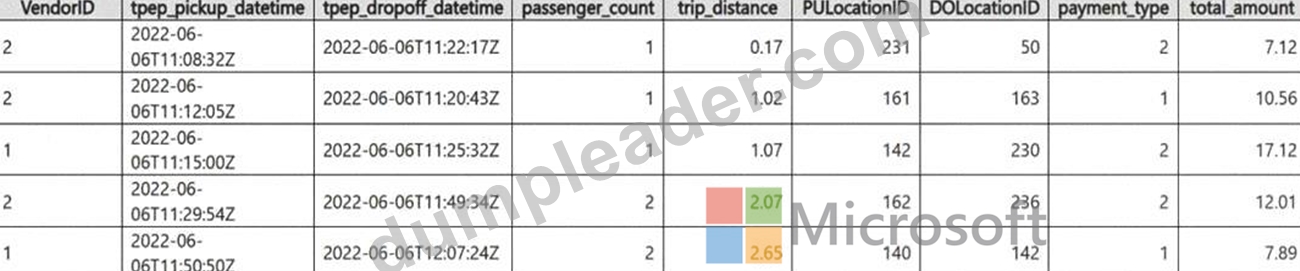
You need to build two KQL queries. The solution must meet the following requirements:
One of the queries must partition RunningTotalAmount by VendorID.
The other query must create a column named FirstPickupDateTime that shows the first value of each hour from tpep_pickup_datetime partitioned by payment_type.
How should you complete each query? To answer, drag the appropriate values the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.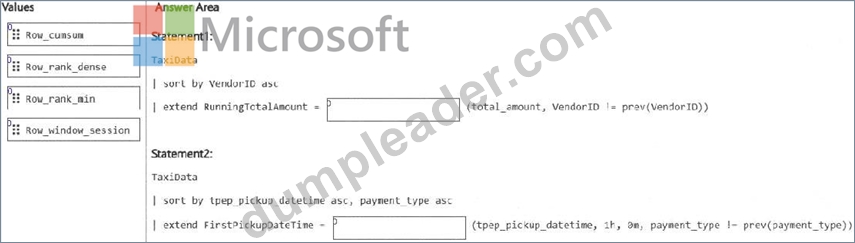
Answer:
Explanation: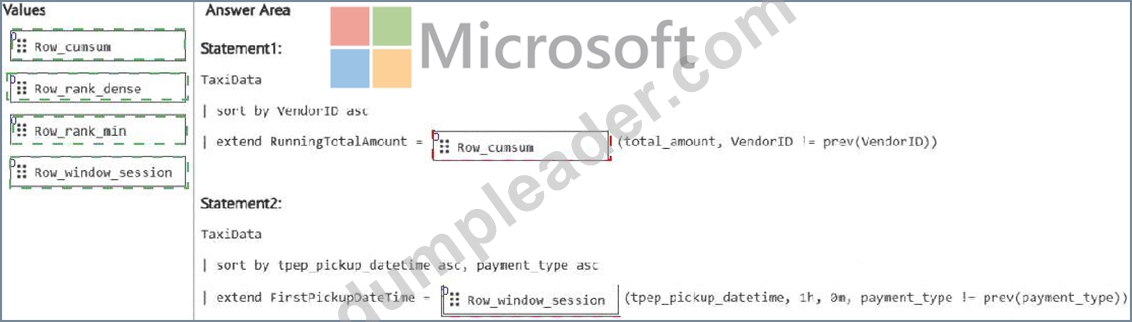
Explanation: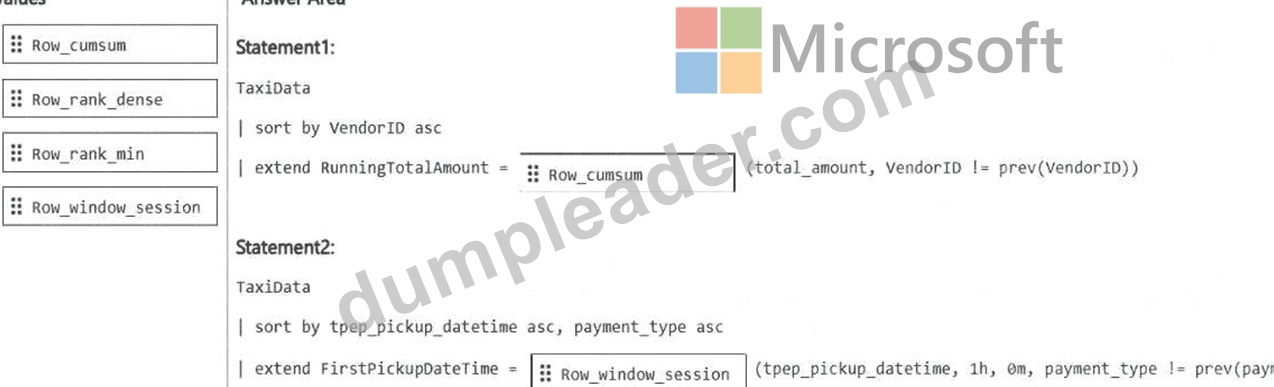
Partition the RunningTotalAmount by VendorID. - Row_cumsum
The Row_cumsum function computes the cumulative sum of a column while optionally restarting the accumulation based on a condition. In this case, it calculates the cumulative sum of total_amount for each VendorID, restarting when the VendorID changes (VendorID != prev(VendorID)).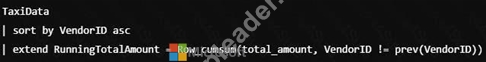
Create a column FirstPickupDateTime that shows the first value of each hour from tpep_pickup_datetime, partitioned by payment_type - Row_window_session
NEW QUESTION # 61
......
DP-700 Cert Exam: https://www.dumpleader.com/DP-700_exam.html
DOWNLOAD the newest Dumpleader DP-700 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1l3iuoDoGHyephW6Eq1XXtY5CaPEOF8PJ