PDFExamDumps是一個優秀的IT認證考試資料網站,在PDFExamDumps您可以找到關於Microsoft AI-300認證考試的考試心得和考試材料。您也可以在PDFExamDumps免費下載部分關於Microsoft AI-300考試的考題和答案。PDFExamDumps還將及時免費為您提供有關Microsoft AI-300考試材料的更新。並且我們的銷售的考試考古題資料都提供答案。我們的IT專家團隊將不斷的利用行業經驗來研究出準確詳細的考試練習題來協助您通過考試。總之,我們將為您提供你所需要的一切關於Microsoft AI-300認證考試的一切材料。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Optimize generative AI systems and model performance | 15–20% | - Improve efficiency and cost-effectiveness
|
| Topic 2: Implement generative AI quality assurance and observability | 10–15% | - Monitor generative AI systems
|
| Topic 3: Design and implement a GenAIOps infrastructure | 20–25% | - Set up Microsoft Foundry environment
|
| Topic 4: Design and implement an MLOps infrastructure | 15–20% | - Create and manage Machine Learning workspace resources and assets
|
| Topic 5: Implement machine learning model lifecycle and operations | 25–30% | - Deploy models to production
|
揮灑如椽之巨筆譜寫生命之絢爛華章,讓心的小舟在波瀾壯闊的汪洋中乘風破浪,直濟滄海。如何才能到達天堂,捷徑只有一個,那就是使用PDFExamDumps Microsoft的AI-300考試培訓資料。這是我們對每位IT考生的忠告,希望他們能抵達夢想的天堂。
問題 #141
Drag and Drop Question
A team iterates prompts used by a generative AI agent. The team must support internal review before releasing changes.
The team must:
- Track prompt changes with a clear history for audit and rollback.
- Compare prompt variants in parallel without affecting the prompt used in the production environment.
You need to select the appropriate source control approach for each requirement.
What should you use for each requirement? To answer, move the appropriate source controls to the correct requirements. You may use each source control once, more than once, or not at all.
You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.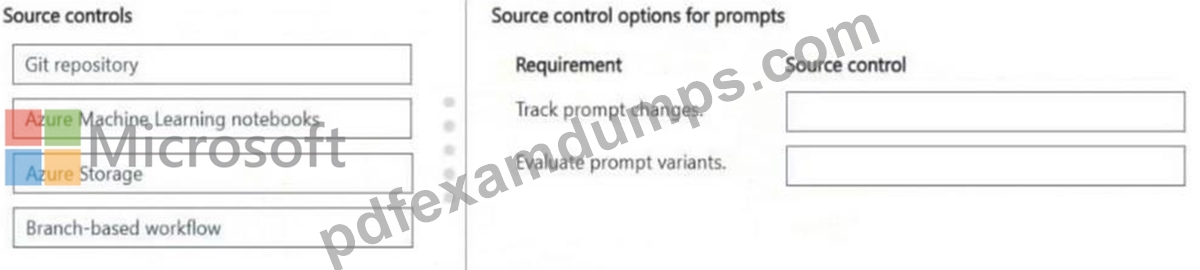
答案:
解題說明: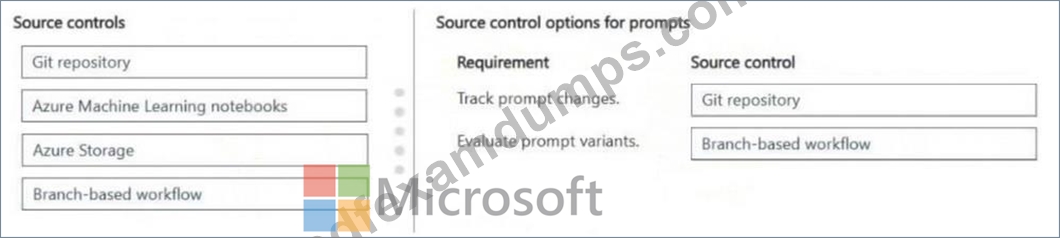
問題 #142
You create a workspace by using Azure Machine Learning Studio.
You must run a Python SDK v2 notebook in the workspace by using Azure Machine Learning Studio. You must preserve the current values of variables set in the notebook for the current instance.
You need to maintain the state of the notebook.
What should you do?
答案:A
問題 #143
A Retrieval-Augmented Generation (RAG) solution returns incomplete answers because relevant content is inconsistently retrieved from the knowledge source.
You need to improve RAG accuracy without changing the embedding model currently in use. You need to achieve this goal while minimizing operational costs.
Which two actions should you perform? Each correct answer presents part of the solution.
Choose two.
NOTE: Each correct selection is worth one point.
答案:A,B
解題說明:
To improve Retrieval-Augmented Generation (RAG) accuracy, address inconsistent retrieval, and eliminate incomplete answers without changing the embedding model or increasing costs significantly, you must move beyond naive fixed-length chunking and implement a two-stage retrieval process.
Here is the targeted, low-cost strategy:
1. Tune Chunk Size and Overlap to Match Content Structure
Inconsistent retrieval often occurs because important information is split across chunk boundaries (breaking context) or chunks are too large, diluting the semantic meaning.
2. Implement an Optimized Re-ranker
The initial vector search often returns "noise"-chunks that are semantically close but not actually relevant. A re-ranker acts as a second, smarter, but more "expensive" step that works on a smaller subset of data, making it low-cost overall.
Reference:
https://medium.com/@sthanikamsanthosh1994/how-to-improve-rag-retrieval-augmented- generation-performance-2a42303117f8
問題 #144
A data science team plans to evaluate multiple hyperparameter values automatically while training a model in Azure Machine Learning.
The tuning process must run multiple training trials without manually modifying the training script for each run.
You need to automate hyperparameter tuning for the training job.
What should you do?
答案:D
解題說明:
Correct:
* Create a tuning job that runs multiple trials with different parameter values To best automate hyperparameter tuning in Azure Machine Learning, you should create a Sweep Job (in SDK v2) or a HyperDrive experiment (in SDK v1).
This creates a tuning job that automatically launches multiple training trials (child runs) using your single base training script without requiring manual code modifications for each run.
Key Components to Automate the Job
To set up this job successfully using the Azure Machine Learning Python SDK v2, you will define:
Parameterized Training Script: Write your code to accept hyperparameters as command-line arguments (e.g., using Python's argparse), allowing the tuning job to pass different values to each trial.
Search Space: Define the range or specific discrete/continuous choices for the values you want to test (e.g., learning rates, batch sizes).Sampling Algorithm: Choose how Azure ML should navigate your search space. Options include Random sampling, Grid sampling (testing every possible combination), or Bayesian sampling (using previous trial results to pick the next best values).Primary Metric: Specify the performance metric your script logs (like accuracy or loss) so Azure ML knows which target to optimize.
Early Termination Policy: Optional policy (like a Bandit Policy) to automatically cancel poorly performing trials early, saving you compute time and cost.
Incorrect:
* Adjust hyperparameters after model deployment.
* Duplicate the training script for each parameter combination.
* Manually change hyperparameter values between training runs.
* Run a single training job with fixed hyperparameters.
* Select hyperparameters based only on default model settings.
Reference:
https://learn.microsoft.com/en-us/python/api/azureml-train-core/azureml.train.hyperdrive
問題 #145
An organization maintains separate Azure Machine Learning workspaces for development and production.
Both environments must use the same validated assets without duplicating them.
Assets must be shared across workspaces while maintaining centralized governance and version control.
You need to enable reuse of assets across workspaces without copying them.
What should you do?
答案:B
解題說明:
Microsoft ' s Azure Machine Learning documentation on registries describes them as organization-level repositories that sit above individual workspaces. When you publish an asset such as a model, environment, or component to an Azure ML registry, it becomes accessible to any workspace in any subscription within the same Azure tenant, all without physical duplication. The registry maintains a single source of truth with full version history. Option A (Git integration) synchronizes code, not compiled ML artifacts. Option B (pipeline component) packages a reusable pipeline step but does not solve cross-workspace sharing. Option C (shared environment) addresses runtime dependencies, not the full range of ML assets. The registry is the purpose- built solution for centralized governance, version control, and cross-workspace asset sharing - the Microsoft- recommended pattern for mature MLOps organizations.
Microsoft Learn Reference Topic: Share assets across workspaces with Azure Machine Learning registries
問題 #146
......
每個IT人士都在努力,不是為了升職就是為了加薪,這也是現代社會所形成的壓力的一種體現。這樣討得上司的喜歡,還不如用實力說話。大家來通過Microsoft的AI-300考試認證吧,其實這個考試也沒有想像的那麼苦難,只需要你選擇合適的培訓資料就足夠,PDFExamDumps Microsoft的AI-300考試培訓資料將是最好的培訓資料,選擇了它你就是選擇你最想要的,為了現實,趕緊行動吧。
AI-300考試證照: https://www.pdfexamdumps.com/AI-300_valid-braindumps.html