無料でクラウドストレージから最新のMogiExam DY0-001 PDFダンプをダウンロードする:https://drive.google.com/open?id=1Xrmsquw19vFpuCZvrXr9cxwCESFldERj
MogiExamの経験豊富な専門家チームはCompTIAのDY0-001認定試験に向かって専門性の問題集を作って、とても受験生に合っています。MogiExamの商品はIT業界中で高品質で低価格で君の試験のために専門に研究したものでございます。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
| トピック 5 |
|
これらの問題を解決するための基本的な方法は、社会の発展よりも速いスピードで成長することです。現場では、CompTIA認定を取得して、自分自身を改善し、より良いあなたとより良い未来を目指してください。それにより、あなたはあなたの職業で認められます。 DY0-001試験トレントは、より大企業に注意を向けさせる能力を証明できます。その後、より良い仕事を取得し、適切な職場に行くための選択肢があります。そして、DY0-001試験問題は、98%以上の高い品質と高い合格率で有名です。 DY0-001学習ガイドをお試しください。
質問 # 83
Which of the following types of machine learning is a GPU most commonly used for?
正解:C
解説:
GPUs excel at the massive parallelism required for the matrix and tensor operations at the heart of deep neural network training and inference, making them the go-to hardware for deep learning workloads.
質問 # 84
A data analyst wants to use compression on an analyzed data set and send it to a new destination for further processing. Which of the following issues will most likely occur?
正解:C
解説:
Compression and decompression are CPU‐intensive operations; on large data sets, the extra processing load can significantly spike CPU utilization. Memory, OS support, or library dependencies are far less likely to be the primary bottleneck in a standard compression workflow.
質問 # 85
A data scientist has built an image recognition model that distinguishes cars from trucks. The data scientist now wants to measure the rate at which the model correctly identifies a car as a car versus when it misidentifies a truck as a car. Which of the following would best convey this information?
正解:A
解説:
A confusion matrix directly shows true positives (cars correctly identified) and false positives (trucks misidentified as cars), giving you exactly the rates you're interested in.
質問 # 86
Which of the following does k represent in the k-means model?
正解:B
解説:
# In k-means clustering, k represents the number of clusters that the algorithm will attempt to form. The algorithm partitions the dataset into k distinct, non-overlapping clusters based on feature similarity. Each cluster has a centroid, and the algorithm aims to minimize the intra-cluster variance.
Why the other options are incorrect:
* A: Number of tests is unrelated to the k-means algorithm.
* B: Data splits refer to cross-validation or train/test splits, not k in k-means.
* D: Distance between features is computed during clustering but is not what "k" represents.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 4.2:"In k-means clustering, k denotes the number of clusters into which the dataset will be partitioned."
* Introduction to Machine Learning, Chapter 6:"The 'k' in k-means specifies how many groupings the algorithm will seek to discover based on proximity in feature space."
-
質問 # 87
SIMULATION
A data scientist needs to determine whether product sales are impacted by other contributing factors. The client has provided the data scientist with sales and other variables in the data set.
The data scientist decides to test potential models that include other information.
INSTRUCTIONS
Part 1
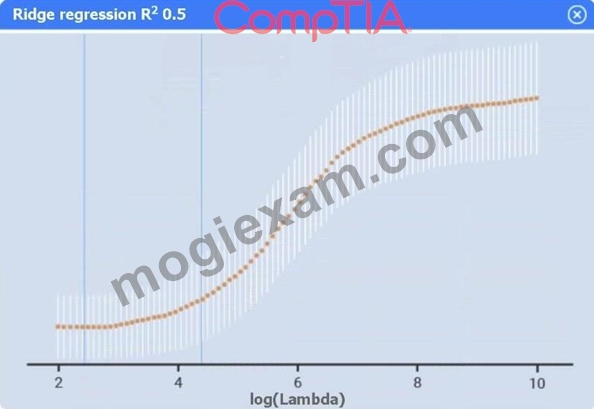
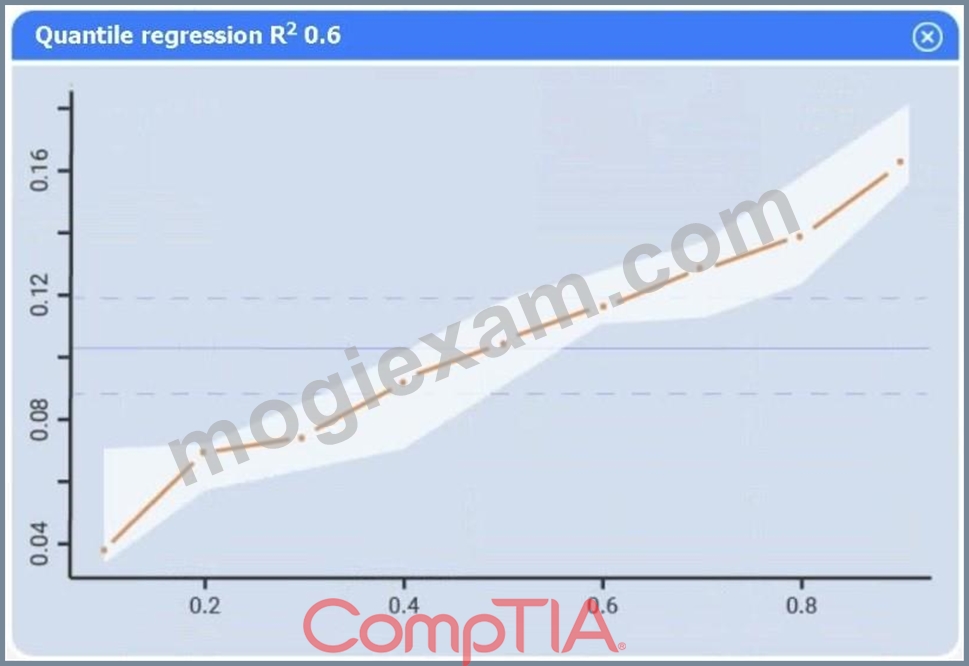
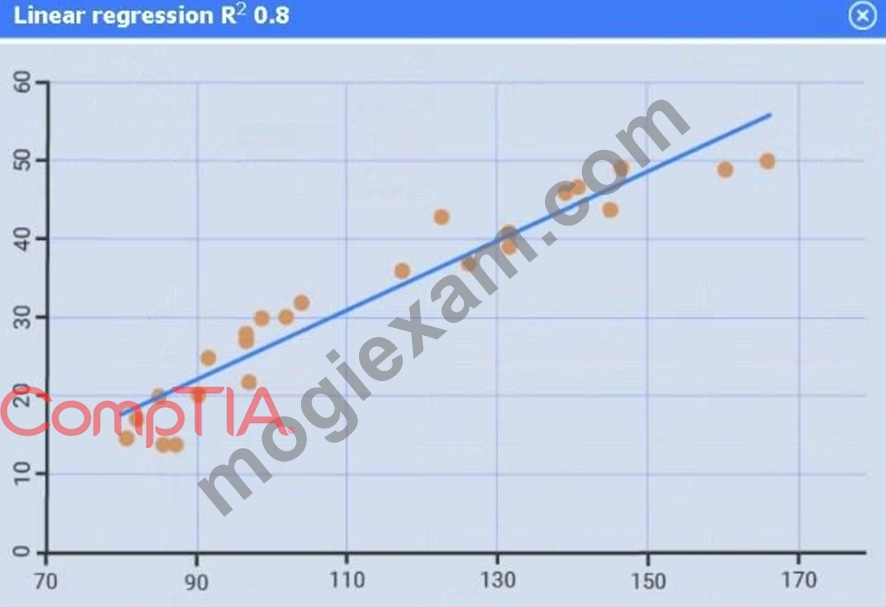
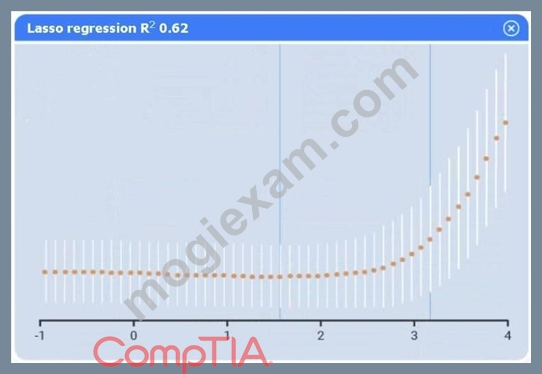
Use the information provided in the table to select the appropriate regression model.
Part 2
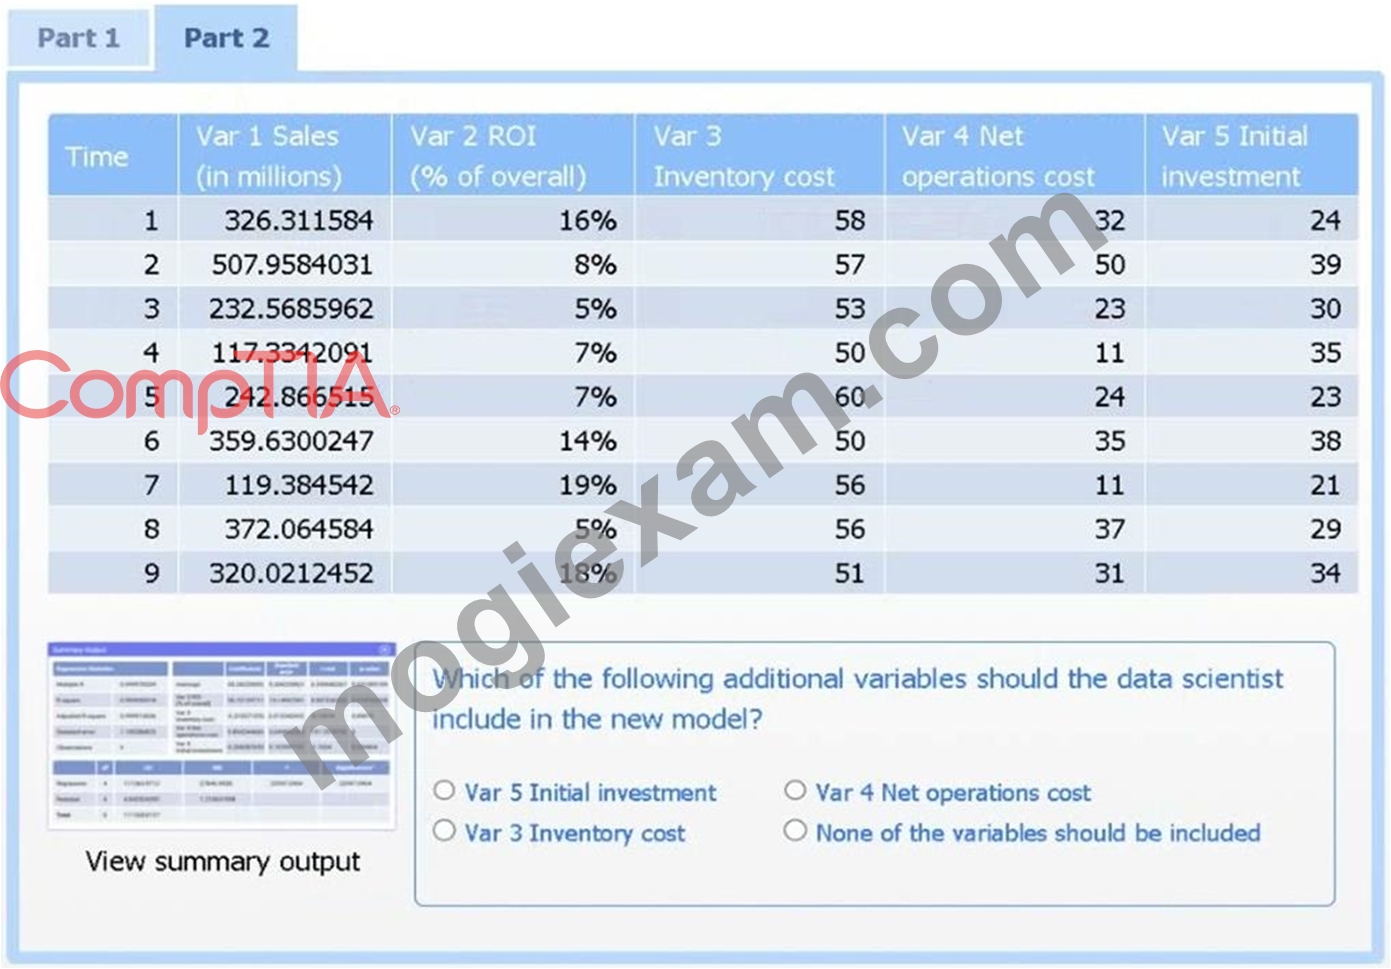
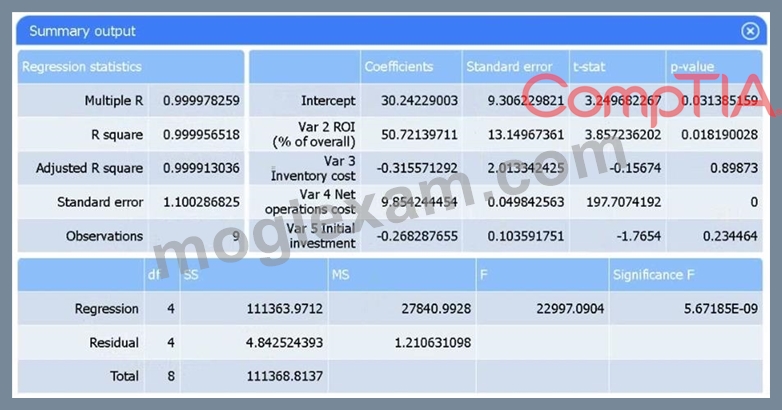
Review the summary output and variable table to determine which variable is statistically significant.
If at any time you would like to bring back the initial state of the simulation, please click the Reset All button.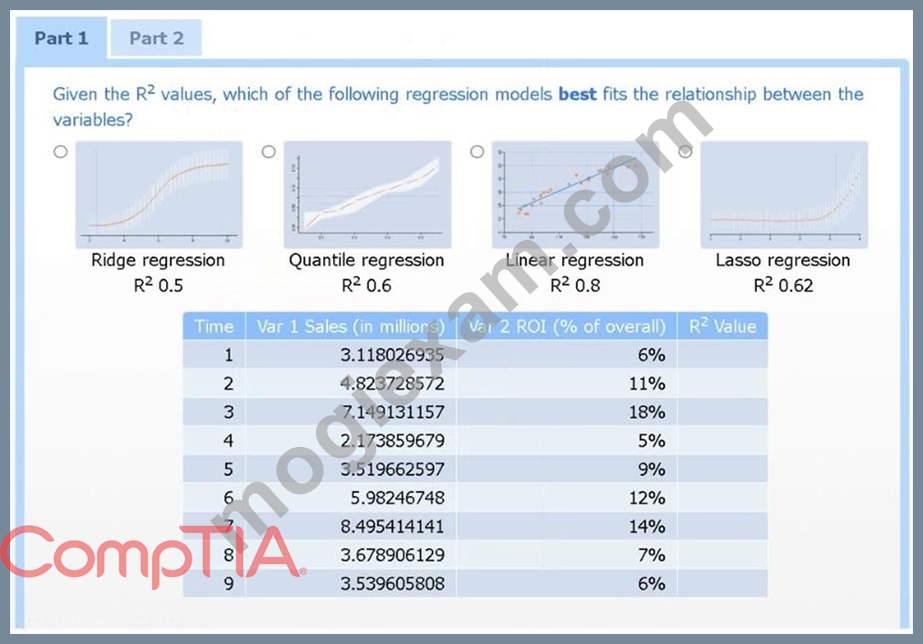
正解:
解説:
Part 1
Linear regression.
Of the four models, linear regression has the highest R² (0.8), indicating it explains the greatest proportion of variance in sales.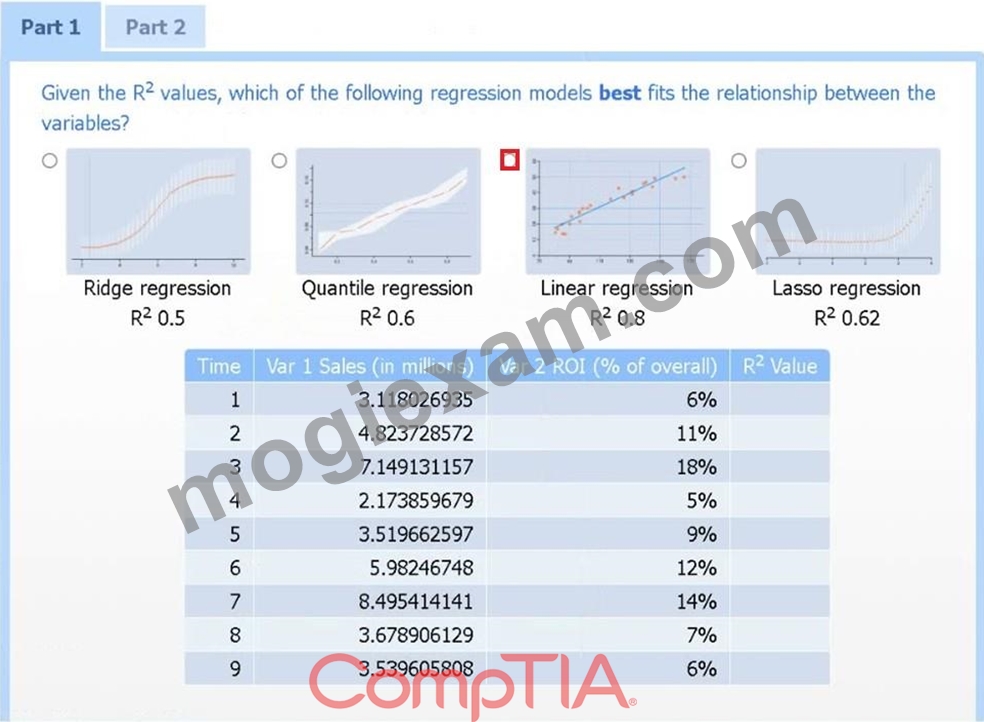
Part 2
Var 4 - Net operations cost.
Net operations cost has a p-value of essentially 0 (far below 0.05), indicating it is the only additional predictor statistically significant in explaining sales. Neither inventory cost (p≈0.90) nor initial investment (p≈0.23) reach significance.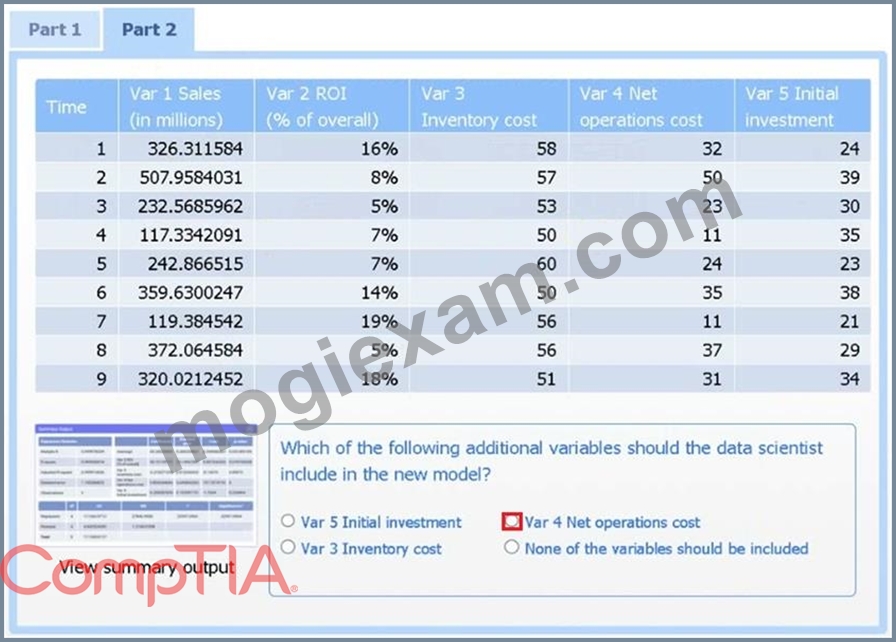
質問 # 88
......
DY0-001参考資料を使用したお客様からいい評価をもらいました。DY0-001参考資料は多くの人の絶対いい選択です。DY0-001参考資料の難点については、弊社の専門家ガ例を挙げて説明します。そうすれば、わかりやすく、覚えやすいです。弊社の DY0-001参考資料は実践に基づいて、専門的な知識の蓄積です。だから、DY0-001試験のために、弊社の商品を選ばれば、後悔することがないです。
DY0-001日本語版問題解説: https://www.mogiexam.com/DY0-001-exam.html
さらに、MogiExam DY0-001ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1Xrmsquw19vFpuCZvrXr9cxwCESFldERj