You don't need to worry about wasting your precious time but failing to get the Databricks-Certified-Data-Engineer-Professionalcertification. With our Databricks-Certified-Data-Engineer-Professional practice guide, your success is 100% guaranteed. Tens of thousands of people have used our Databricks-Certified-Data-Engineer-Professional Study Materials and the pass rate of the exam is high as 98% to 100%. This means as long as you learn with our Databricks-Certified-Data-Engineer-Professional learning quiz, you will pass the exam without doubt.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Modelling | 6% | - Design Medallion Architecture - Implement dimensional and relational models - Optimize table design and partitioning |
| Topic 2: Data Ingestion & Acquisition | 7% | - Ingest data from diverse sources - Handle incremental and batch data loads - Use Auto Loader and structured streaming |
| Topic 3: Monitoring and Alerting | 10% | - Set up alerts and notifications - Track data lineage and metrics - Monitor pipeline performance and health |
| Topic 4: Data Governance | 7% | - Enforce data policies and standards - Manage data assets and metadata - Use Unity Catalog for governance |
| Topic 5: Debugging and Deploying | 10% | - Implement CI/CD and DevOps practices - Deploy using Asset Bundles, CLI, and APIs - Troubleshoot and debug pipelines |
| Topic 6: Data Sharing and Federation | 5% | - Manage cross-platform data access - Implement Lakehouse Federation - Use Delta Sharing for secure data sharing |
| Topic 7: Developing Code for Data Processing using Python and SQL | 22% | - Use Databricks-specific libraries and APIs - Write efficient and maintainable code - Implement complex data processing logic |
| Topic 8: Data Transformation, Cleansing, and Quality | 10% | - Implement schema evolution and management - Apply data cleansing and validation rules - Enforce data quality standards |
| Topic 9: Ensuring Data Security and Compliance | 10% | - Implement access control and permissions - Ensure data privacy and compliance - Secure data at rest and in transit |
| Topic 10: Cost & Performance Optimisation | 13% | - Optimize compute and storage resources - Apply cost management best practices - Improve query and pipeline performance |
>> Databricks-Certified-Data-Engineer-Professional Latest Exam Experience <<
We are proud that our Databricks Databricks-Certified-Data-Engineer-Professional exam preparation material is one of the best in the market. You should buy our Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) valid dumps and start preparation now because of some amazing offers. These offers are up to 1 year of Free Databricks-Certified-Data-Engineer-Professional Dumps updates, free demos of our Databricks-Certified-Data-Engineer-Professional exam product, and a full refund guarantee. What are you waiting for? Buy actual Databricks Databricks-Certified-Data-Engineer-Professional now at discount and start your preparation.
NEW QUESTION # 197
Which statement describes the correct use of pyspark.sql.functions.broadcast?
Answer: D
Explanation:
https://spark.apache.org/docs/3.1.3/api/python/reference/api/pyspark.sql.functions.broadcast.html The broadcast function in PySpark is used in the context of joins. When you mark a DataFrame with broadcast, Spark tries to send this DataFrame to all worker nodes so that it can be joined with another DataFrame without shuffling the larger DataFrame across the nodes. This is particularly beneficial when the DataFrame is small enough to fit into the memory of each node. It helps to optimize the join process by reducing the amount of data that needs to be shuffled across the cluster, which can be a very expensive operation in terms of computation and time.
The pyspark.sql.functions.broadcast function in PySpark is used to hint to Spark that a DataFrame is small enough to be broadcast to all worker nodes in the cluster. When this hint is applied, Spark can perform a broadcast join, where the smaller DataFrame is sent to each executor only once and joined with the larger DataFrame on each executor. This can significantly reduce the amount of data shuffled across the network and can improve the performance of the join operation. In a broadcast join, the entire smaller DataFrame is sent to each executor, not just a specific column or a cached version on attached storage. This function is particularly useful when one of the DataFrames in a join operation is much smaller than the other, and can fit comfortably in the memory of each executor node.
NEW QUESTION # 198
A data engineer is masking a column containing email addresses. The goal is to produce output strings of identical length for all rows, while generating different outputs for different email values.
Which SQL function should be used to achieve this?
Answer: B
Explanation:
The hash() function in Databricks SQL returns a deterministic fixed-length integer (or hexadecimal string) derived from the input. When applied to sensitive identifiers like email addresses, it produces a unique value for each distinct input while ensuring uniform output size, making it suitable for anonymization where referential consistency is required.
Functions like mask() perform pattern-based substitutions that change string lengths, and sha1() or sha2() produce long hexadecimal strings of varying lengths (depending on hash size), which may not match requirements for fixed-length masking.
Therefore, the correct choice for fixed-length, deterministic pseudonymization of email addresses is hash(email), as it maintains analytical usability while anonymizing sensitive data.
NEW QUESTION # 199
A junior member of the data engineering team is exploring the language interoperability of Databricks notebooks. The intended outcome of the below code is to register a view of all sales that occurred in countries on the continent of Africa that appear in the geo_lookup table.
Before executing the code, running SHOW TABLES on the current database indicates the database contains only two tables: geo_lookup and sales.
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from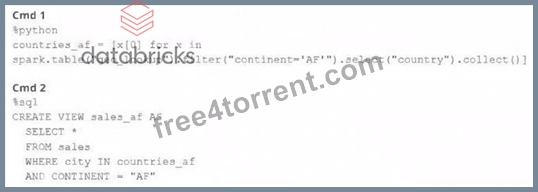
Which statement correctly describes the outcome of executing these command cells in order in an interactive notebook?
Answer: B
Explanation:
This is the correct answer because Cmd 1 is written in Python and uses a list comprehension to extract the country names from the geo_lookup table and store them in a Python variable named countries af. This variable will contain a list of strings, not a PySpark DataFrame or a SQL view.
Cmd 2 is written in SQL and tries to create a view named sales af by selecting from the sales table where city is in countries af. However, this command will fail because countries af is not a valid SQL entity and cannot be used in a SQL query. To fix this, a better approach would be to use spark.sql() to execute a SQL query in Python and pass the countries af variable as a parameter.
NEW QUESTION # 200
Which method can be used to determine the total wall-clock time it took to execute a query?
Answer: D
Explanation:
The Query Profiler in Databricks SQL and notebooks provides a detailed breakdown of query performance metrics. The "Total wall-clock duration" metric directly represents the total elapsed time from query start to completion, including all execution, planning, and waiting stages. In contrast, "Aggregated task time" reflects the cumulative duration across all parallel tasks, which does not equal the total elapsed wall time since tasks often run concurrently. Using job duration from Spark UI can underestimate or overestimate runtime when queries span multiple jobs.
Therefore, the Query Profiler's total wall-clock duration is the officially documented method to determine actual query execution time.
NEW QUESTION # 201
A company has a task management system that tracks the most recent status of tasks. The system takes task events as input and processes events in near real-time using Lakeflow Declarative Pipelines. A new task event is ingested into the system when a task is created or the task status is changed. Lakeflow Declarative Pipelines provides a streaming table (tasks_status) for BI users to query.
The table represents the latest status of all tasks and includes 5 columns:
task_id (unique for each task)
task_name
task_owner
task_status
task_event_time
The table enables three properties: deletion vectors, row tracking, and change data feed (CDF).
A data engineer is asked to create a new Lakeflow Declarative Pipeline to enrich the tasks_status table in near real-time by adding one additional column representing task_owner's department, which can be looked up from a static dimension table (employee).
How should this enrichment be implemented?
Answer: B
Explanation:
Change Data Feed (CDF) allows downstream consumers to read incremental changes (inserts, updates, deletes) from a Delta table. The documentation explains that when streaming from a Delta table with CDF enabled, developers can use readStream().option("readChangeFeed","true") to capture incremental events. For maintaining a derived table with enrichment logic, the recommended practice is to use apply_changes(), which applies CDC semantics (insert/update/delete) correctly to the target streaming table. By joining with the static employee dimension, enriched rows are generated before being merged into the new streaming target. This ensures correctness, scalability, and minimal latency. Batch reads or skipping commits do not maintain correctness for CDC pipelines.
NEW QUESTION # 202
......
Everyone is not willing to fall behind, but very few people take the initiative to change their situation. Take time to make a change and you will surely do it. Our Databricks-Certified-Data-Engineer-Professional actual test guide can give you some help. Our company aims to help ease the pressure on you to prepare for the exam and eventually get a certificate. Obtaining a certificate is equivalent to having a promising future and good professional development. Our Databricks-Certified-Data-Engineer-Professional Study Materials have a good reputation in the international community and their quality is guaranteed. Why don't you there have a brave attempt? You will certainly benefit from your wise choice.
Databricks-Certified-Data-Engineer-Professional Reliable Test Objectives: https://www.free4torrent.com/Databricks-Certified-Data-Engineer-Professional-braindumps-torrent.html