P.S. Free & New Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by ITdumpsfree: https://drive.google.com/open?id=1zyrJhHpPaXRNU9mhD3w_mokqHX8rbXQ5
While the Google Professional-Machine-Learning-Engineer practice questions in PDF format are helpful for learning all the relevant answers to clear the Professional-Machine-Learning-Engineer exam, we offer an additional tool to enhance your confidence and skills. Our online Google Practice Test engine allows you to learn and practice for the Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) exam simultaneously. This feature is designed to strengthen your knowledge and ensure you are fully prepared for success.
Google Professional Machine Learning Engineer certification exam is a challenging but rewarding qualification for individuals looking to demonstrate their expertise in machine learning. Successful candidates will gain a deep understanding of machine learning concepts and techniques, and will be well-positioned to pursue careers in machine learning engineering, data science, and related fields.
Google Professional Machine Learning Engineer Certification Exam is a highly prestigious certification offered by Google. It is designed for individuals who wish to showcase their expertise in the field of machine learning and demonstrate their ability to design, build, and deploy highly scalable and reliable machine learning models. Google Professional Machine Learning Engineer certification exam tests candidates on a variety of topics related to machine learning, including data preprocessing, feature engineering, model selection and evaluation, and deployment and monitoring of machine learning models.
>> Reliable Exam Professional-Machine-Learning-Engineer Pass4sure <<
Google trained experts have made sure to help the potential applicants of Google Professional-Machine-Learning-Engineer certification to pass their Google Professional-Machine-Learning-Engineer exam on the first try. Our PDF format carries real Google Professional Machine Learning Engineer exam dumps. You can use this format of Google Professional-Machine-Learning-Engineer Actual Questions on your smart devices.
NEW QUESTION # 61
During batch training of a neural network, you notice that there is an oscillation in the loss. How should you adjust your model to ensure that it converges?
Answer: B
Explanation:
https://developers.google.com/machine-learning/crash-course/introduction-to-neural-networks/playground-exercises
NEW QUESTION # 62
You work for a gaming company that has millions of customers around the world. All games offer a chat feature that allows players to communicate with each other in real time. Messages can be typed in more than
20 languages and are translated in real time using the Cloud Translation API. You have been asked to build an ML system to moderate the chat in real time while assuring that the performance is uniform across the various languages and without changing the serving infrastructure.
You trained your first model using an in-house word2vec model for embedding the chat messages translated by the Cloud Translation API. However, the model has significant differences in performance across the different languages. How should you improve it?
Answer: C
Explanation:
The problem with the current approach is that it relies on the Cloud Translation API to translate the chat messages into a common language before embedding them with the in-house word2vec model. This introduces two sources of error: the translation quality and the word2vec quality. The translation quality may vary across different languages, depending on the availability of data and the complexity of the grammar and vocabulary.
The word2vec quality may also vary depending on the size and diversity of the corpus used to train it. These errors may affect the performance of the classifier that moderates the chat messages, resulting in significant differences across the languages.
A better approach would be to train a classifier using the chat messages in their original language, without relying on the Cloud Translation API or the in-house word2vec model. This way, the classifier can learn the nuances and subtleties of each language, and avoid the errors introduced by the translation and embedding processes. This would also reduce the latency and cost of the moderation system, as it would not need to invoke the Cloud Translation API for every message. To train a classifier using the chat messages in their original language, one could use a multilingual pre-trained model such as mBERT or XLM-R, which can handle multiple languages and domains. Alternatively, one could train a separate classifier for each language, using a monolingual pre-trained model such as BERT or a custom model tailored to the specific language and task.
References:
* Professional ML Engineer Exam Guide
* Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate
* Google Cloud launches machine learning engineer certification
* [mBERT: Bidirectional Encoder Representations from Transformers]
* [XLM-R: Unsupervised Cross-lingual Representation Learning at Scale]
* [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding]
NEW QUESTION # 63
Your team is working on an NLP research project to predict political affiliation of authors based on articles they have written. You have a large training dataset that is structured like this: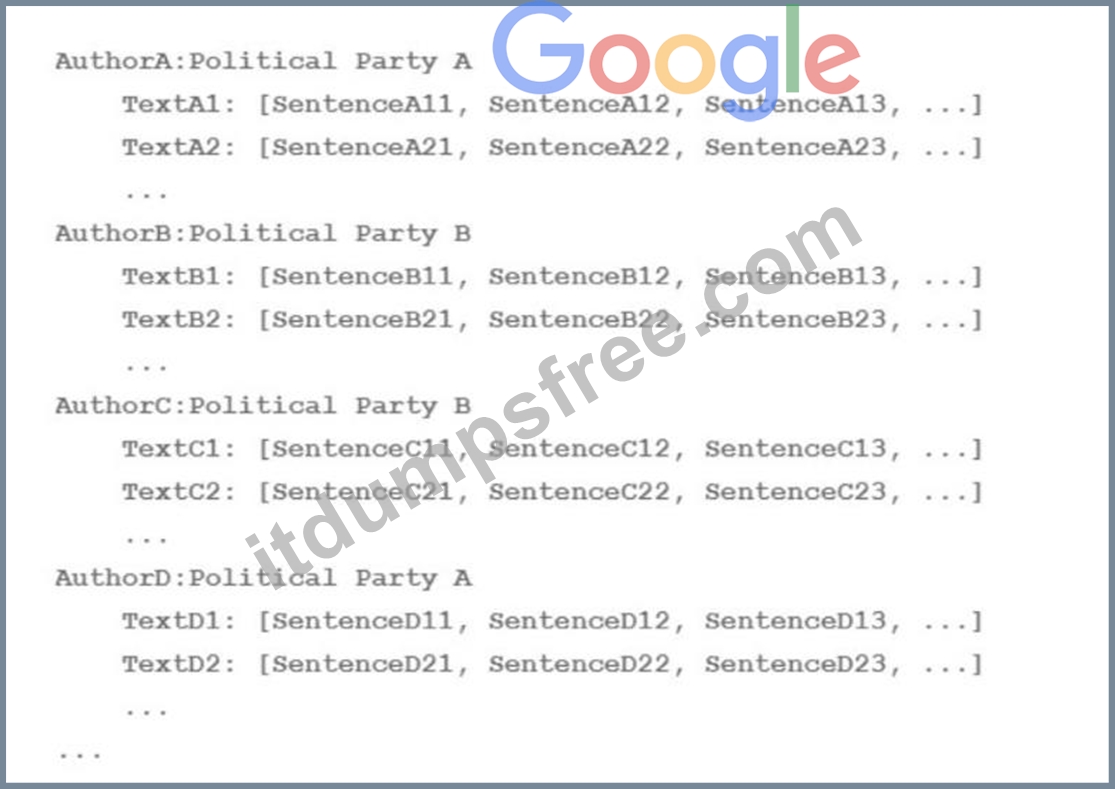
A)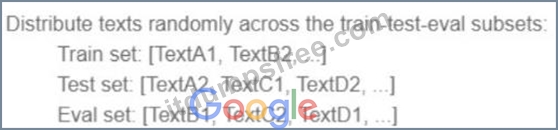
B)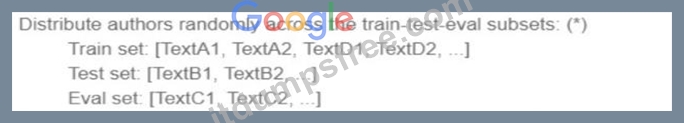
C)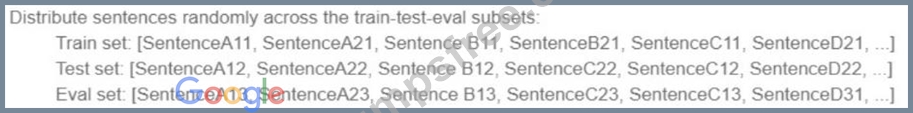
D)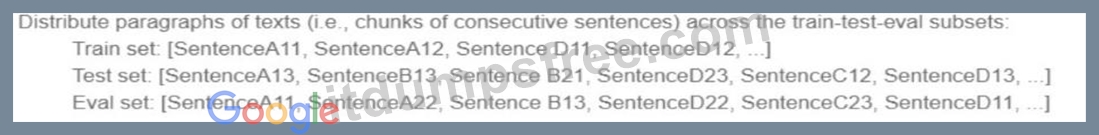
Answer: C
NEW QUESTION # 64
You have been asked to productionize a proof-of-concept ML model built using Keras. The model was trained in a Jupyter notebook on a data scientist's local machine. The notebook contains a cell that performs data validation and a cell that performs model analysis. You need to orchestrate the steps contained in the notebook and automate the execution of these steps for weekly retraining. You expect much more training data in the future. You want your solution to take advantage of managed services while minimizing cost. What should you do?
Answer: C
Explanation:
The best option for productionizing a Keras model is to use TensorFlow Extended (TFX), a framework for building end-to-end machine learning pipelines that can handle large-scale data and complex workflows. TFX provides standard components for data ingestion, transformation, validation, analysis, training, tuning, serving, and monitoring. TFX pipelines can be orchestrated with Vertex AI Pipelines, a managed service that runs on Google Cloud Platform and leverages Kubernetes and Argo. Vertex AI Pipelines allows you to automate the execution of your TFX pipeline steps, schedule retraining jobs, and scale up or down the resources as needed.
By using TFX and Vertex AI Pipelines, you can take advantage of the following benefits:
* You can reuse the existing code in your Jupyter notebook, as TFX supports Keras as a first-class citizen.
You can also use the Keras Tuner to optimize your model hyperparameters.
* You can ensure data quality and consistency by using the TFX Data Validation component, which can detect anomalies, drift, and skew in your data. You can also use the TFX SchemaGen component to generate a schema for your data and enforce it throughout the pipeline.
* You can analyze your model performance and fairness by using the TFX Model Analysis component, which can produce various metrics and visualizations. You can also use the TFX Model Validation component to compare your new model with a baseline model and set thresholds for deploying the model to production.
* You can deploy your model to various serving platforms by using the TFX Pusher component, which can push your model to Vertex AI, Cloud AI Platform, TensorFlow Serving, or TensorFlow Lite. You can also use the TFX Model Registry to manage the versions and metadata of your models.
* You can monitor your model performance and health by using the TFX Model Monitor component, which can detect data drift, concept drift, and prediction skew in your model. You can also use the TFX Evaluator component to compute metrics and validate your model against a baseline or a slice of data.
* You can reduce the cost and complexity of managing your own infrastructure by using Vertex AI Pipelines, which provides a serverless environment for running your TFX pipeline. You can also use the Vertex AI Experiments and Vertex AI TensorBoard to track and visualize your pipeline runs.
References:
* [TensorFlow Extended (TFX)]
* [Vertex AI Pipelines]
* [TFX User Guide]
NEW QUESTION # 65
You want to rebuild your ML pipeline for structured data on Google Cloud. You are using PySpark to conduct data transformations at scale, but your pipelines are taking over 12 hours to run. To speed up development and pipeline run time, you want to use a serverless tool and SQL syntax. You have already moved your raw data into Cloud Storage. How should you build the pipeline on Google Cloud while meeting the speed and processing requirements?
Answer: B
Explanation:
BigQuery is a serverless, scalable, and cost-effective data warehouse that allows users to run SQL queries on large volumes of data. BigQuery Load is a tool that can ingest data from Cloud Storage into BigQuery tables.
BigQuery SQL is a dialect of SQL that supports many of the same functions and operations as PySpark, such as window functions, aggregate functions, joins, and subqueries. By using BigQuery Load and BigQuery SQL, you can rebuild your ML pipeline for structured data on Google Cloud without having to manage any servers or clusters, and with faster performance and lower cost than using PySpark on Dataproc. You can also use BigQuery ML to create and evaluate ML models using SQL commands. References:
* BigQuery documentation
* BigQuery Load documentation
* BigQuery SQL reference
* BigQuery ML documentation
NEW QUESTION # 66
......
Latest Professional-Machine-Learning-Engineer Test Preparation: https://www.itdumpsfree.com/Professional-Machine-Learning-Engineer-exam-passed.html
What's more, part of that ITdumpsfree Professional-Machine-Learning-Engineer dumps now are free: https://drive.google.com/open?id=1zyrJhHpPaXRNU9mhD3w_mokqHX8rbXQ5