P.S. Free 2026 CompTIA DY0-001 dumps are available on Google Drive shared by TestSimulate: https://drive.google.com/open?id=1jM8b8mVunkmH90othf194P1q-Osdtv1W
Our DY0-001 training quiz will be your best teacher who helps you to find the key and difficulty of the exam, so that you no longer feel confused when review. Our DY0-001 study materials will be your best learning partner and will accompany you through every day of the review. Our DY0-001 Exam Quiz will help you to deal with all the difficulties you have encountered in the learning process and make you walk more easily and happily on the road of studying.
| Certification Vendor: | CompTIA |
|---|---|
| Exam Name: | CompTIA DataAI Certification Exam (V1) |
| Exam Number: | DY0-001 |
| Passing Score: | Pass/Fail (no scaled score) |
| Exam Format: | Performance-based questions, Multiple-choice |
| Certificate Validity Period: | Approximately 3 years from launch (retirement expected around 2027) |
| Real Exam Qty: | Up to 90 |
| Related Certifications: | CompTIA DataX |
| Exam Duration: | 165 minutes |
| Available Languages: | Japanese, English |
| Recommended Training: | CompTIA Official Training Partners CompTIA CertMaster Learn (DataAI) |
| Exam Registration: | Pearson VUE CompTIA Registration CompTIA DataAI Official Page |
| Sample Questions: | CompTIA DY0-001 Sample Questions |
| Exam Way: | Test center or online proctored exam (Pearson VUE) |
| Pre Condition: | Recommended: 5+ years experience in data science, analytics, or related technical roles |
| Official Syllabus URL: | https://www.comptia.org/en-us/certifications/dataai/ |
TestSimulate is a website to achieve dreams of many IT people. TestSimulate provide candidates participating in the IT certification exams the information they want to help them pass the exam. Do you still worry about passing CompTIA certification DY0-001 exam? Have you thought about purchasing an CompTIA certification DY0-001 exam counseling sessions to assist you? TestSimulate can provide you with this convenience. TestSimulate's training materials can help you pass the certification exam. TestSimulate's exercises are almost similar to real exams. With TestSimulate's accurate CompTIA Certification DY0-001 Exam practice questions and answers, you can pass CompTIA certification DY0-001 exam with a high score.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 10
A data scientist is developing a model to predict the outcome of a vote for a national mascot. The choice is between tigers and lions. The full data set represents feedback from individuals representing 17 professions and 12 different locations. The following rank aggregation represents 80% of the data set: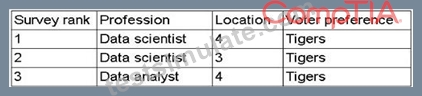
(Screenshot shows survey rankings for just two professions and a few locations, all voting for "Tigers") Which of the following is the most likely concern about the model's ability to predict the outcome of the vote?
Answer: C
Explanation:
# Extrapolated data refers to making predictions about data points that fall outside the observed range or distribution. Since the sample data (80%) is heavily skewed toward a small subset of professions and locations, predicting results for the remaining, unrepresented professions and regions involves extrapolation.
Why the other options are incorrect:
* A: Interpolation occurs within the bounds of observed data - not the issue here.
* C: In-sample data refers to training data, which is overrepresented in this case.
* D: Out-of-sample data is a concern in generalization but extrapolation is more specific here.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.2:"Extrapolation introduces risk when models are used outside the range of data they were trained on, especially if certain subgroups are underrepresented."
-
NEW QUESTION # 11
The term "greedy algorithms" refers to machine-learning algorithms that:
Answer: D
Explanation:
Greedy algorithms build the solution iteratively by choosing at each step the option that appears best at that moment, without reconsidering earlier choices.
NEW QUESTION # 12
Which of the following does k represent in the k-means model?
Answer: D
Explanation:
# In k-means clustering, k represents the number of clusters that the algorithm will attempt to form. The algorithm partitions the dataset into k distinct, non-overlapping clusters based on feature similarity. Each cluster has a centroid, and the algorithm aims to minimize the intra-cluster variance.
Why the other options are incorrect:
* A: Number of tests is unrelated to the k-means algorithm.
* B: Data splits refer to cross-validation or train/test splits, not k in k-means.
* D: Distance between features is computed during clustering but is not what "k" represents.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 4.2:"In k-means clustering, k denotes the number of clusters into which the dataset will be partitioned."
* Introduction to Machine Learning, Chapter 6:"The 'k' in k-means specifies how many groupings the algorithm will seek to discover based on proximity in feature space."
-
NEW QUESTION # 13
A data analyst wants to use compression on an analyzed data set and send it to a new destination for further processing. Which of the following issues will most likely occur?
Answer: A
Explanation:
Compression and decompression are CPU‐intensive operations; on large data sets, the extra processing load can significantly spike CPU utilization. Memory, OS support, or library dependencies are far less likely to be the primary bottleneck in a standard compression workflow.
NEW QUESTION # 14
A data scientist is analyzing a data set with categorical features and would like to make those features more useful when building a model. Which of the following data transformation techniques should the data scientist use? (Choose two.)
Answer: F
Explanation:
One-hot encoding creates binary indicator columns for each category, allowing models to treat nominal categories without implying any order.
Label encoding maps categories to integer labels, which can be useful for tree-based models or when you need a single numeric column (though you must ensure the algorithm can handle treated ordinality appropriately).
NEW QUESTION # 15
......
Latest DY0-001 Exam Dumps: https://www.testsimulate.com/DY0-001-study-materials.html
What's more, part of that TestSimulate DY0-001 dumps now are free: https://drive.google.com/open?id=1jM8b8mVunkmH90othf194P1q-Osdtv1W