P.S. Free & New SPS-C01 dumps are available on Google Drive shared by PassReview: https://drive.google.com/open?id=1sb4FKW1_wOgyKeFmIRP-EGgswlCWPaPj
It will improve your skills to face the difficulty of the SPS-C01 exam questions and accelerate the way to success in IT filed with our latest study materials. Free demo of our SPS-C01 dumps pdf can be downloaded before purchase and 24/7 customer assisting support can be access. Well preparation of SPS-C01 Practice Test will be closer to your success and get authoritative certification easily.
| Section | Objectives |
|---|---|
| Topic 1: Data Engineering with Snowpark | - Pipeline development
|
| Topic 2: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Topic 3: Testing, Debugging, and Deployment | - Production readiness
|
| Topic 4: Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Topic 5: Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Topic 6: DataFrame Operations and Data Processing | - Data transformation workflows
|
Our SPS-C01 learning guide is for the world and users are very extensive. In order to give users a better experience, we have been constantly improving. The high quality and efficiency of SPS-C01 exam prep has been recognized by users. The high passing rate of our SPS-C01 test materials are its biggest feature. As long as you use SPS-C01 Exam Prep, you can certainly harvest what you want thing. Not only you can pass the SPS-C01 exam in the shortest time, but also you can otain the dreaming SPS-C01 certification to have a brighter future.
NEW QUESTION # 230
You have a DataFrame 'df containing user profile data'. A column named "profile" stores JSON objects with potentially missing fields. These objects might include 'name', 'age', 'location', and 'preferences'. You need to extract the user's name and age. If 'age' is missing, you want to default to 0. Furthermore, you want to filter out any rows where the 'location' field is an empty string. Which combination of Snowpark code snippets will achieve this? (Select all that apply)





Answer: B,C,E
Explanation:
Options A, B and C correctly address the requirements. They extract the name and handle the missing 'age' by defaulting to 0, and filter out rows with an empty string for 'location'. - Option A uses 'nvr to replace NULL 'age' values and ' to filter out empty locations. - Option B uses 'iff to achieve the same age default and sf.lit(")' for filtering. - Option C uses 'coalesce' to default 'age' and 'sf.lengtm to check if the location string has any characters. Option D will filter out all the rows where location is Null and option E uses zeroifnull function which is deprecated, and replaces age which is 0 if column is NULL. and option D wont filer empty string in location
NEW QUESTION # 231
You are developing a Snowpark application that processes large volumes of JSON data from an external stage. Initial testing on a MEDIUM warehouse results in significant query queuing. You suspect the issue is CPU bound due to complex JSON parsing and UDF execution within Snowpark. Considering only warehouse sizing options and assuming cost is a secondary concern to performance during peak processing hours, which strategy is MOST effective for optimizing performance? Consider the impact on concurrency.
Answer: C
Explanation:
Upgrading to a larger warehouse (X-LARGE or higher) provides significantly more CPU resources, which directly addresses the CPU-bound nature of complex JSON parsing and IJDF execution. Scaling out with smaller warehouses (option B) increases concurrency but doesn't necessarily alleviate the CPU bottleneck within individual queries. Materialized Views (option D) can help, but this question is focused on only warehouse sizing options. Option E will almost certainly make things worse. Upgrading to a LARGE could help, but the question asks for the most effective approach. Larger warehouse sizes generally deliver the best performance for intensive workloads.
NEW QUESTION # 232
Consider a Snowpark DataFrame with a containing date values, some of which are corrupted (e.g., invalid date formats or out-of-range values). You need to identify and either remove or correct these corrupted date values. Which of the following approaches can be effectively used in Snowpark Python to handle such scenarios? (Select all that apply)
Answer: B,D,E
Explanation:
Options A, B, and D are valid approaches. Option A allows converting the column to date, setting incorrect values as NULL, which can then be filtered. Option B (UDF) provides flexibility for custom date parsing and error handling. Option D is valid as well, as it filters out data which doesn't match the expression. Option C is incorrect. The 'to_date' function in Snowpark does not have an 'IGNORE' keyword to replace invalid dates with NULL automatically. If it fails to convert to date, it will throw an error. Option E assumes that the corrupted dates can be pre-identified, which is generally not the case as the process aims to identify the dates that are corrupt, thus making it an incorrect answer.
NEW QUESTION # 233
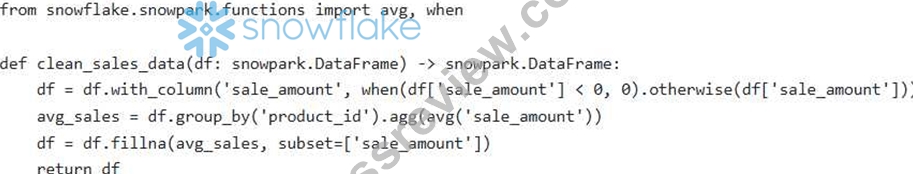
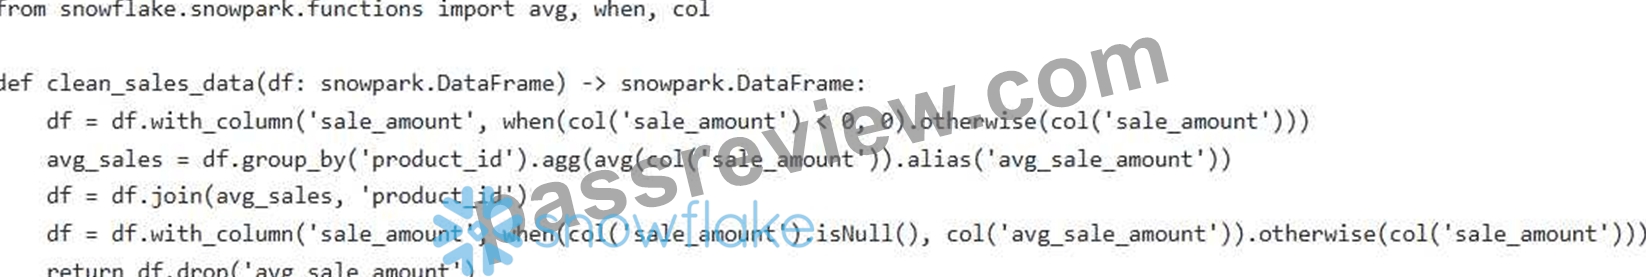
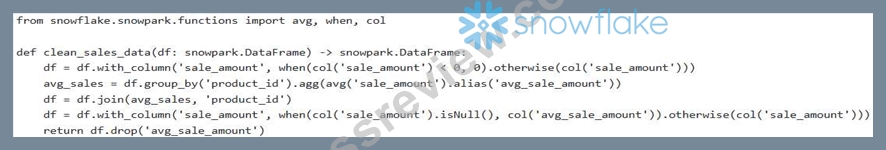
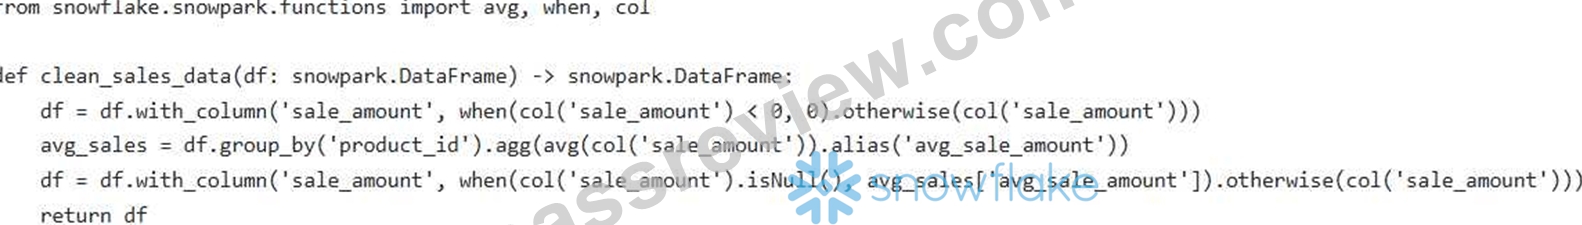
You have a Snowpark DataFrame with columns 'product_id', 'customer_id', and 'sale_amount'. Some values are negative, indicating returns, and others are null. You need to replace negative values with 0 and fill null values with the average 'sale_amount' for each 'product_id'. Which of the following approaches is the MOST efficient and correct way to achieve this using Snowpark?
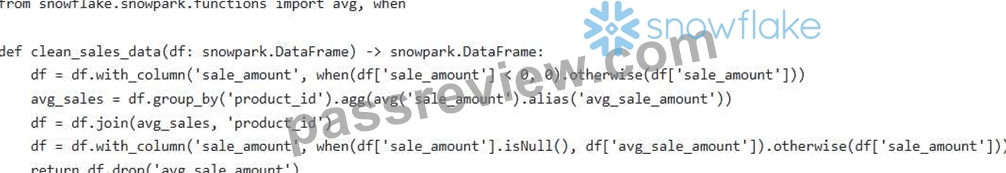
Answer: B
Explanation:
Option E first replaces negative values with 0. Then, it calculates the average sales amount per product and joins it back to the original DataFrame. Finally, it fills null values with the calculated average sales amount and drops the temporary column. This is efficient because it utilizes Snowpark's DataFrame operations. other options does not handle nulls or gives errors.
NEW QUESTION # 234
A data science team wants to operationalize a Snowpark Python UDF that performs sentiment analysis on customer reviews. The UDF, 'analyze sentiment(review_text)', is currently defined within a Snowpark session. Which of the following approaches is the MOST efficient and scalable way to deploy this UDF for real-time scoring of incoming review data in a Snowflake table named 'CUSTOMER REVIEWS'?
Answer: A
Explanation:
Registering the UDF as a persistent UDF in Snowflake allows it to be called directly from SQL, leveraging Snowflake's query engine for optimal performance and scalability. Option A keeps the transformation entirely within Snowpark, which is a valid approach, but less scalable. Option C involves converting to a Pandas DataFrame, which moves data outside of Snowflake and negates its benefits. Option D creates a stored procedure that is correct but the question ask to perform in real time so it's not ideal. Option E is not the way to persist Snowpark with UDF.
NEW QUESTION # 235
......
At the same time, SPS-C01 study material also has a timekeeping function that allows you to be cautious and keep your own speed while you are practicing, so as to avoid the situation that you can't finish all the questions during the exam. With SPS-C01 Learning Materials, you only need to spend half your money to get several times better service than others. And you can get the SPS-C01 certification with little effort and money.
Download SPS-C01 Fee: https://www.passreview.com/SPS-C01_exam-braindumps.html
P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by PassReview: https://drive.google.com/open?id=1sb4FKW1_wOgyKeFmIRP-EGgswlCWPaPj