Experts hired by CCAR-P exam questions not only conducted in-depth research on the prediction of test questions, but also made great breakthroughs in learning methods. With CCAR-P training materials, you can easily memorize all important points of knowledge without rigid endorsements. With CCAR-P exam torrent, you no longer need to spend money to hire a dedicated tutor to explain it to you, even if you are a rookie of the industry, you can understand everything in the materials without any obstacles. With CCAR-P Exam Questions, your teacher is no longer one person, but a large team of experts who can help you solve all the problems you have encountered in the learning process.
| Section | Weight | Objectives |
|---|---|---|
| Evaluation, Testing & Optimization | 16% | - Optimize performance, prompting, and model selection - Define evaluation metrics and success criteria - Test accuracy, reliability, latency, and cost - Implement iterative improvement pipelines |
| Developer Productivity & Operational Enablement | 7% | - Support debugging, monitoring, and operational resolution - Configure Claude tools and environments for teams - Improve developer workflows with AI-assisted tooling |
| Stakeholder Communication & Lifecycle Management | 14% | - Document architectures and support full lifecycle phases - Conduct structured discovery and requirement gathering - Communicate architectural decisions and trade-offs - Manage stakeholder feedback and expectation alignment |
| Integration | 19% | - Integrate Claude with enterprise systems, APIs, and tools - Implement Model Context Protocol (MCP) integrations - Design authentication, authorization, and observability - Integrate with data pipelines and RAG systems |
| Governance, Safety & Risk Management | 14% | - Address ethical AI considerations and bias mitigation - Manage data privacy and security compliance - Implement guardrails and safety controls - Ensure regulatory compliance (GDPR, HIPAA, etc.) |
| Solution Design & Architecture | 17% | - Select architectural patterns: workflow, agentic, augmented LLM - Design end-to-end architectures and feedback loops - Align solutions to business value pillars - Translate business problems into Claude-based AI solutions - Design multi-agent systems and orchestration strategies |
| Claude Models, Prompting & Context Engineering | 13% | - Apply context engineering and context management techniques - Select appropriate Claude models based on trade-offs - Design system prompts, templates, and guardrails - Mitigate prompt injection, leaks, and jailbreak risks |
Provided that you lose your exam with our CCAR-P exam questions unfortunately, you can have full refund or switch other version for free. All the preoccupation based on your needs and all these explain our belief to help you have satisfactory and comfortable purchasing services on the CCAR-P Study Guide. We assume all the responsibilities our CCAR-P simulating practice may bring you foreseeable outcomes and you will not regret for believing in us assuredly.
NEW QUESTION # 72
You are diagnosing a Claude Code session whose subagent uses 50,000 tokens of context before the engineer types a single message.
Which root cause is most likely?
Answer: A
Explanation:
Claude Code constructs the model context before the first user message. That initial context can include the system prompt, project instructions, subagent configuration, MCP server instructions, and tool definitions expressed as JSON schemas. When numerous MCP servers expose many tools and Tool Search is disabled, those schemas must be loaded upfront. A large collection of verbose tool descriptions and parameter schemas can therefore consume tens of thousands of tokens before the engineer enters any text.
Tool Search is specifically designed to prevent this form of context inflation. With Tool Search enabled, Claude initially receives only server instructions and compact tool-identification information; full tool schemas are deferred until a relevant tool is discovered and required. Anthropic consequently describes Tool Search as the mechanism for keeping MCP context consumption low as integrations scale.
Keyboard layouts, font rendering, and display scaling operate outside the language-model context and cannot generate API input tokens. Likewise, model behavior does not silently reserve 50,000 tokens for personal preferences. The diagnostic action is to inspect configured MCP servers and tool counts, determine whether Tool Search has been disabled, and remove or defer unnecessary definitions.
Study Guide references/topics: [MCP Tool Search and context scaling](https://docs.anthropic.com/en/docs
/claude-code/mcp); MCP server configuration; subagent context budgeting; tool-schema optimization.
NEW QUESTION # 73
An architect is reviewing a Claude-based candidate-screening tool prior to deployment. A stakeholder asserts that because the model was not trained on company data, no bias evaluation is necessary.
Which two responses most accurately challenge this assertion? (Select two.)
Answer: A,B
Explanation:
The absence of company-specific training does not establish unbiased behavior. A foundation model may reflect demographic associations or unequal treatment patterns originating from pretraining data, model behavior, prompt framing, retrieval content, or the surrounding decision workflow. Because candidate screening can materially affect employment opportunities, the complete system must be evaluated across relevant protected groups before deployment. Appropriate measures include selection-rate differences, false- positive and false-negative rates, calibration, intersectional slices, and human override patterns. Disclosure that AI is used does not replace empirical fairness testing. Protected-class labels need not have been explicit in training data for proxy variables or inferred attributes to produce disparities. Provider policies similarly do not validate a customer's specific implementation. Anthropic system cards document discriminatory-bias evaluations, reinforcing the need for application-level testing. Claude model system card
NEW QUESTION # 74
You are evaluating model-selection claims used by a peer team.
For each statement, select yes if the statement is generally true. Otherwise, select no.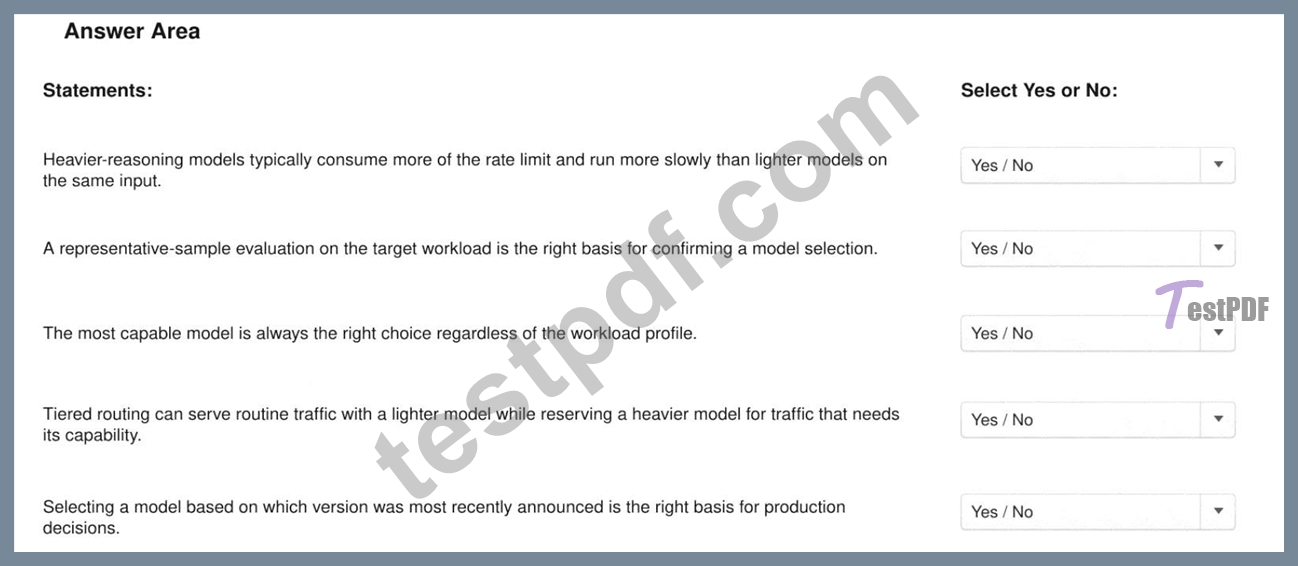
Answer:
Explanation: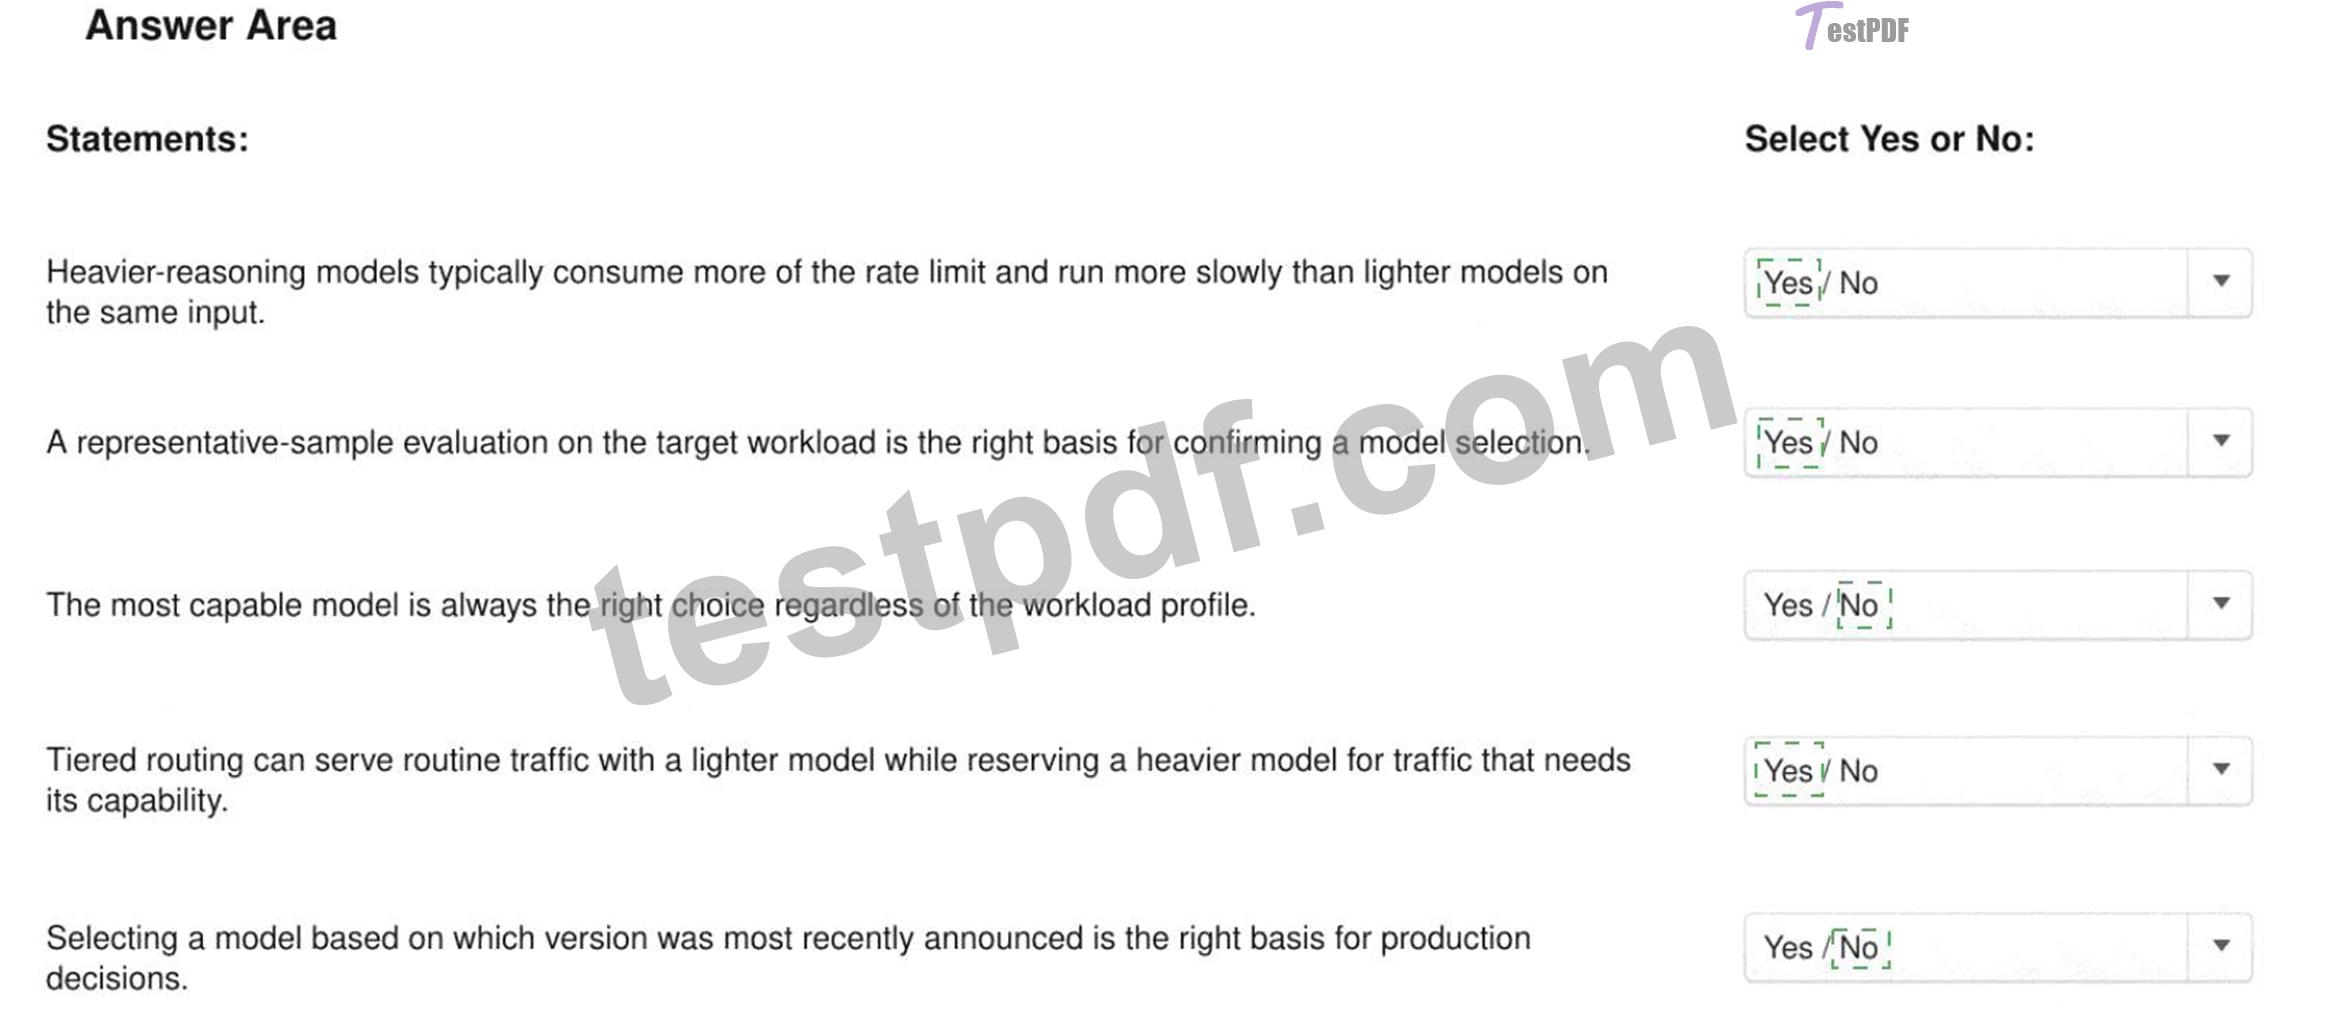
Explanation:
Yes, Yes, No, Yes, No
More capable reasoning configurations generally require greater computation, produce higher latency, and may consume larger token or rate-limit allocations than lighter alternatives. This makes the first statement generally accurate, although actual performance must be measured under the organization's specific provider and service tier.
Representative workload testing is essential because generic benchmark rankings do not establish performance on the organization's prompts, data, edge cases, tools, or required output format. Anthropic recommends benchmark tests specific to the use case, using actual prompts and data, followed by comparison of accuracy, quality, edge-case behavior, and cost. Choosing the Right Model The strongest model is not automatically the correct production choice. Model selection must balance capability, speed, cost, throughput, and operational constraints. Tiered routing implements this principle by serving predictable requests with an efficient model and escalating difficult cases to a more capable model.
Anthropic documents multi-model strategies in which lower-cost workers handle most traffic while harder decisions are escalated.
Recency is also not a valid selection criterion. A newly announced model must pass the workload's existing evaluation, security, latency, and cost gates before replacing a validated production model.
Study Guide references/topics: Model trade-offs; representative evaluations; tiered routing; escalation architectures; cost-capability optimization; model migration validation.
NEW QUESTION # 75
You are documenting an architectural decision to support future audit and onboarding.
Which artifact is the strongest fit?
Answer: D
Explanation:
An Architecture Decision Record is designed to preserve a significant architectural choice in a concise, durable, and reviewable form. The context explains the problem, constraints, and forces that shaped the decision. The decision section records the selected approach. Alternatives demonstrate that other viable options were evaluated, while consequences identify benefits, costs, limitations, operational obligations, and residual risks. The date and authors establish accountability and historical sequence.
This structure supports audit because a reviewer can trace why a model, integration pattern, retrieval architecture, security boundary, or deployment approach was chosen. It also supports onboarding by preventing new team members from interpreting intentional design choices as arbitrary implementation details.
A slide deck may communicate a decision at a meeting but is weak as the sole authoritative record when it lacks written rationale. A code comment is too localized and may not capture system-level implications or rejected alternatives. A verbal conversation creates no durable evidence and depends entirely on individual memory.
The ADR should be version-controlled, linked to affected requirements and implementation artifacts, assigned an owner, and reviewed when its assumptions or operating conditions materially change.
Study Guide references/topics: Architecture Decision Records; decision context; alternatives; consequences; auditability; onboarding; lifecycle review.
NEW QUESTION # 76
You are classifying chunking strategies by the corpus type each is best suited to.
For each chunking strategy, select the appropriate corpus type: "Long Structured Documents,"
"Heterogeneous Short Records," or "Code or Hierarchical Specifications."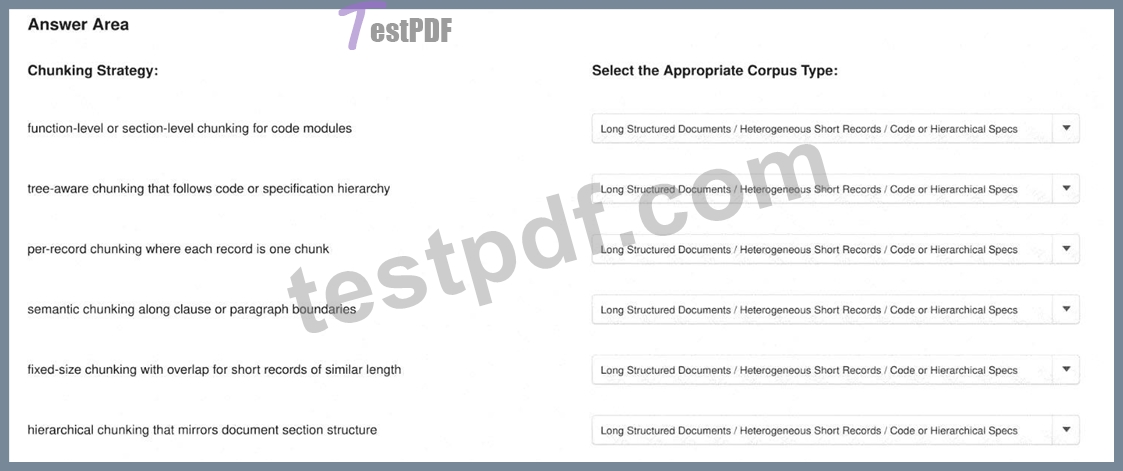
Answer:
Explanation: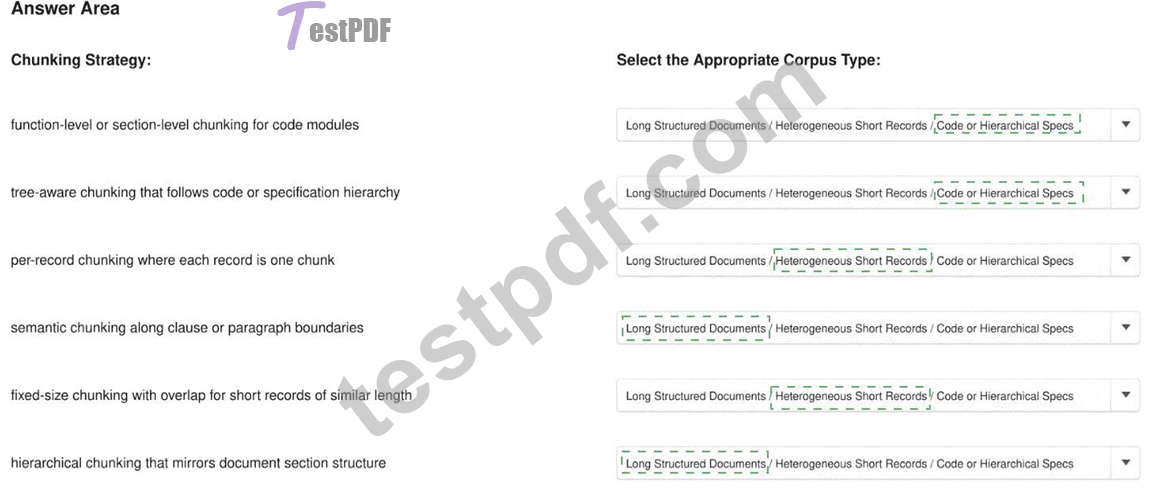
Explanation:
* Function-level or section-level chunking for code modules - Code or Hierarchical Specifications
* Tree-aware chunking that follows code or specification hierarchy - Code or Hierarchical Specifications
* Per-record chunking where each record is one chunk - Heterogeneous Short Records
* Semantic chunking along clause or paragraph boundaries - Long Structured Documents
* Fixed-size chunking with overlap for short records of similar length - Heterogeneous Short Records
* Hierarchical chunking that mirrors document section structure - Long Structured Documents Chunking must preserve the structural unit that carries meaning in the source corpus. Code and hierarchical specifications are best divided at function, module, class, or tree boundaries because arbitrary token cuts can separate definitions from their implementation or parent context. Heterogeneous short-record collections should generally preserve each record as an independent chunk. Fixed-size overlapping chunks are also effective when records have broadly similar lengths and lack meaningful internal hierarchy. Long structured documents benefit from semantic boundaries such as clauses and paragraphs, while hierarchical chunking preserves relationships among sections, subsections, and parent headings. Anthropic notes that chunk size, boundaries, and overlap materially affect retrieval performance; therefore, one universal chunking method is inappropriate. Anthropic Contextual Retrieval
NEW QUESTION # 77
......
In the Desktop CCAR-P practice exam software version of Anthropic CCAR-P practice test is updated and real. The software is useable on Windows-based computers and laptops. There is a demo of the Claude Certified Architect - Professional (CCAR-P) practice exam which is totally free. Claude Certified Architect - Professional (CCAR-P) practice test is very customizable and you can adjust its time and number of questions.
Popular CCAR-P Exams: https://www.testpdf.com/CCAR-P-exam-braindumps.html