We boost professional expert team to organize and compile the AI-200 training materials diligently and provide the great service which include the service before and after the sale, the 24-hours online customer service. So you can not only get the first-class AI-200 Exam Questions but also get the first-class services. If you have any question, you can just contact us online or via email at any time you like. And you can free download the demos of our AI-200 study guide before your payment.
| Section | Objectives |
|---|---|
| Topic 1: Connect to and consume Azure services | - Integrate Azure services
|
| Topic 2: Develop containerized solutions on Azure | - Implement containerized applications
|
| Topic 3: Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Topic 4: Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
>> Reliable AI-200 Exam Answers <<
Our AI-200 study questions will update frequently to guarantee that you can get enough test banks and follow the trend in the theory and the practice. That is to say, our AI-200 training materials boost many advantages and to gain a better understanding of our AI-200 Guide Torrent. It is very worthy for you to buy our AI-200 practice guide and please trust us. If you still can't fully believe us, please read the introduction of the features and the functions of our AI-200 learning questions.
NEW QUESTION # 41
You are designing an Azure Database for PostgreSQL table for semantic search. Queries frequently filter on the created_at column.
The schema must support vector similarity search and reliable date filtering.
You need to ensure that the table meets the requirements.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: B,D
Explanation:
To meet the requirements, store embeddings in a pgvector column and use a typed timestamp column for created_at. These two steps enable high-dimensional vector similarity operations and allow efficient, reliable date-based filtering.
Store embeddings in a pgvector column: Enables the database to store and query high- dimensional vector embeddings using native similarity operators.
Use a typed timestamp column for created_at: Ensures accurate date-and-time comparisons, indexing, and dependable performance when filtering queries by creation date.
Reference:
https://learn.microsoft.com/en-us/training/modules/implement-vector-search-azure-database-postgresql/
NEW QUESTION # 42
You are developing a serverless Java application on Azure. You create a new Azure Key Vault to work with secrets from a new Azure Functions application.
The application must meet the following requirements:
Reference the Azure Key Vault without requiring any changes to the Java code.
Dynamically add and remove instances of the Azure Functions host based on the number of incoming application events.
Ensure that instances are perpetually warm to avoid any cold starts.
Connect to a VNet.
Authentication to the Azure Key Vault instance must be removed if the Azure Function application is deleted.
You need to grant the Azure Functions application access to the Azure Key Vault.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.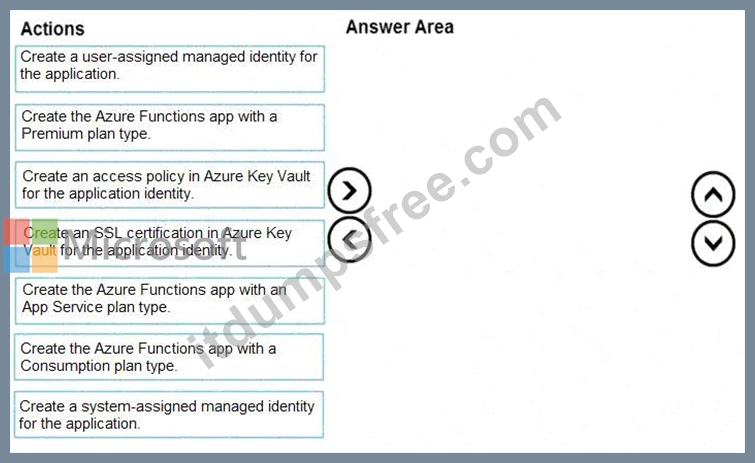
Answer:
Explanation: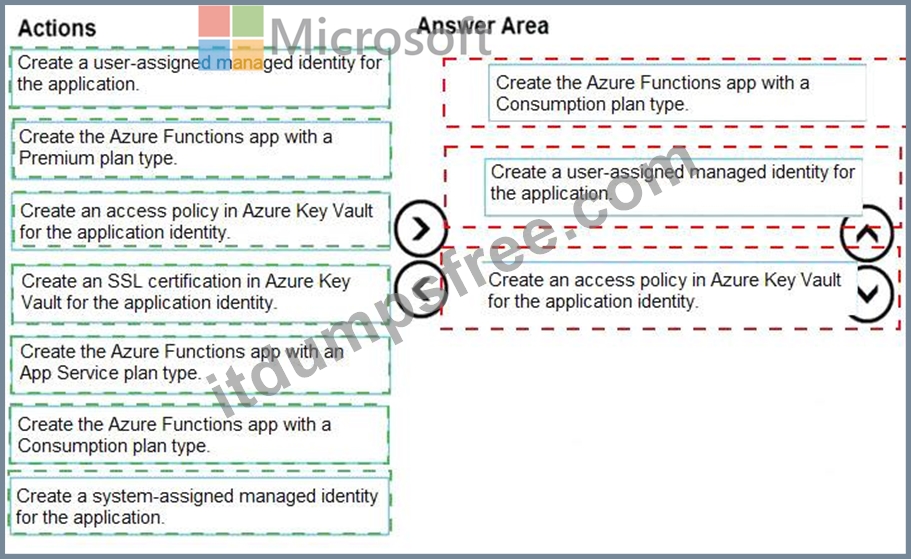
Explanation: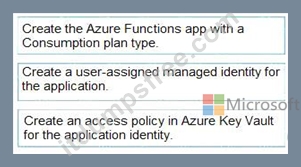
Step 1: Create the Azure Functions app with a Consumption plan type.
Use the Consumption plan for serverless.
Step 2: Create a system-assigned managed identity for the application.
Create a system-assigned managed identity for your application.
Key Vault references currently only support system-assigned managed identities. User-assigned identities cannot be used.
Step 3: Create an access policy in Key Vault for the application identity.
Create an access policy in Key Vault for the application identity you created earlier. Enable the " Get " secret permission on this policy. Do not configure the " authorized application " or applicationId settings, as this is not compatible with a managed identity.
Reference:
https://docs.microsoft.com/en-us/azure/app-service/app-service-key-vault-references
NEW QUESTION # 43
You are designing an Azure Function app that exposes a public API.
The solution must:
Validate incoming request data and return results immediately to the caller.
Support Microsoft Entra ID authentication.
Scale automatically under variable load.
You need to implement a trigger.
Which trigger should you implement?
Answer: D
Explanation:
Detailed Explanation: An HTTP trigger is the only option that directly accepts a synchronous external request and can return a response immediately to the caller. Azure Functions uses HTTP triggers to implement serverless APIs and webhooks, while Microsoft Entra authentication can be applied to the Function App or API surface. Queue, Event Grid, and Service Bus triggers are asynchronous event-processing mechanisms and do not provide the request/response semantics required by this public API scenario.
Study Guide Alignment: Azure service integration: Service Bus, Event Grid, Azure Functions triggers
/bindings, and event-driven processing.
Official Microsoft Learn References: AI-200 Study Guide | Azure Functions HTTP trigger
NEW QUESTION # 44
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
You need to address the known issue resulting from vector similarity queries.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: B,C
Explanation:
Known Issues: RU consumption spikes during vector similarity queries.
To address the RU (Request Unit) consumption spikes during vector similarity queries in Azure Cosmos DB, you should perform the following two steps:
Modify the indexing precision of the vector fields
Change the vector index type from flat to quantizedFlat or diskANN
Indexing Precision Tuning: Modifying parameters like vector quantization (e.g., configuring quantizedByteSize) alters the size and precision of the stored vector elements. Lowering the precision decreases memory usage and index size, allowing faster searches that consume far fewer RUs at the expense of marginal recall accuracy.
Index Type Modification: A standard flat index conducts a brute-force k-nearest neighbors (kNN) exact search across every document. This requires vast computational overhead and causes RU spikes as your dataset grows. Transitioning to quantizedFlat or diskANN leverages compression techniques and advanced graph-traversal algorithms to perform approximate nearest neighbor (ANN) searches, dropping query latency and compute costs significantly.
Reference:
https://learn.microsoft.com/en-us/azure/cosmos-db/gen-ai/vector-search-performance-tips
NEW QUESTION # 45
You are developing an AI application that retrieves database credentials from Key Vault by using the Azure SDK for Python.
The application must use managed identity for authentication.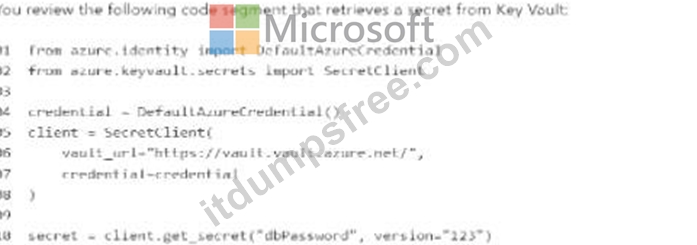
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.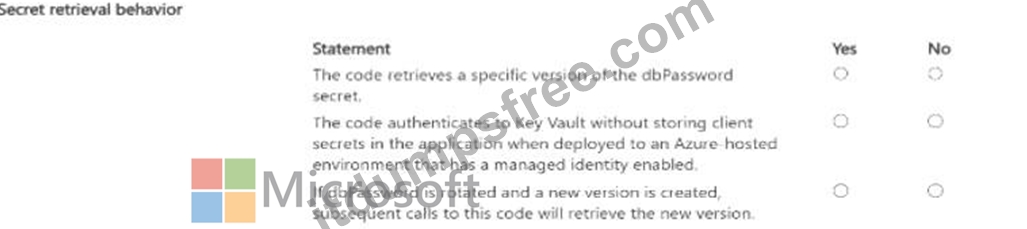
Answer:
Explanation: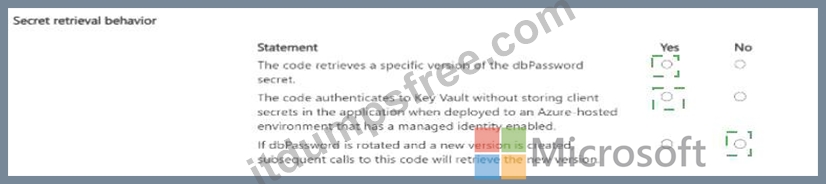
Explanation: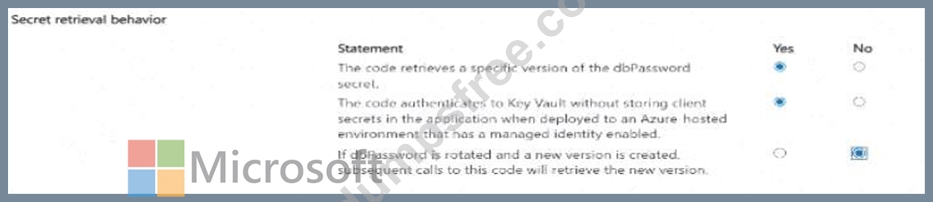
Verified answer: Yes; Yes; No.
Detailed Explanation: The get_secret call supplies an explicit version value, so it retrieves that particular version of dbPassword. DefaultAzureCredential can authenticate to Key Vault by using the Azure-hosted application's managed identity without embedding a client secret in the application. Because the code requests a fixed version, later secret rotation creates a newer version but subsequent executions of this exact code continue to request the specified old version. To follow the latest version automatically, the version parameter must be omitted.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Managed identities for Azure resources | Use Key Vault references for App Service and Functions
NEW QUESTION # 46
......
Our website offer considerate 24/7 services with non-stopping care for you after purchasing our AI-200 learning materials. Although we cannot contact with each other face to face, but there are no disparate treatments and we treat every customer with consideration like we are around you at every stage during your review process on our AI-200 Exam Questions. We will offer help insofar as I can. While our AI-200 training guide is beneficiary even you lose your chance of winning this time.
New AI-200 Exam Notes: https://www.itdumpsfree.com/AI-200-exam-passed.html