Our website provides the most up to date and accurate Databricks Databricks-Certified-Data-Engineer-Professional learning materials which are the best for clearing Databricks-Certified-Data-Engineer-Professional real exam. It is best choice to accelerate your career as a professional in the information technology industry. We are proud of our reputation of helping people clear Databricks-Certified-Data-Engineer-Professional Actual Test in your first attempt. Our pass rate reached almost 86% in recent years.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Ingestion & Acquisition | 7% | - Handle incremental and batch data loads - Ingest data from diverse sources - Use Auto Loader and structured streaming |
| Topic 2: Data Modelling | 6% | - Design Medallion Architecture - Implement dimensional and relational models - Optimize table design and partitioning |
| Topic 3: Debugging and Deploying | 10% | - Implement CI/CD and DevOps practices - Troubleshoot and debug pipelines - Deploy using Asset Bundles, CLI, and APIs |
| Topic 4: Cost & Performance Optimisation | 13% | - Optimize compute and storage resources - Improve query and pipeline performance - Apply cost management best practices |
| Topic 5: Ensuring Data Security and Compliance | 10% | - Ensure data privacy and compliance - Implement access control and permissions - Secure data at rest and in transit |
| Topic 6: Developing Code for Data Processing using Python and SQL | 22% | - Write efficient and maintainable code - Implement complex data processing logic - Use Databricks-specific libraries and APIs |
| Topic 7: Data Governance | 7% | - Enforce data policies and standards - Use Unity Catalog for governance - Manage data assets and metadata |
| Topic 8: Data Transformation, Cleansing, and Quality | 10% | - Enforce data quality standards - Apply data cleansing and validation rules - Implement schema evolution and management |
| Topic 9: Data Sharing and Federation | 5% | - Implement Lakehouse Federation - Manage cross-platform data access - Use Delta Sharing for secure data sharing |
| Topic 10: Monitoring and Alerting | 10% | - Track data lineage and metrics - Set up alerts and notifications - Monitor pipeline performance and health |
>> Latest Databricks-Certified-Data-Engineer-Professional Exam Experience <<
In today's era, knowledge is becoming more and more important, and talents are becoming increasingly saturated. In such a tough situation, how can we highlight our advantages? It may be a good way to get the test Databricks-Certified-Data-Engineer-Professional certification. In fact, we always will unconsciously score of high and low to measure a person's level of strength, believe that we have experienced as a child by elders inquire achievement feeling, now, we still need to face the fact. Our society needs all kinds of comprehensive talents, the Databricks-Certified-Data-Engineer-Professional Latest Dumps can give you what you want, but not just some boring book knowledge, but flexible use of combination with the social practice. Therefore, it is necessary for us to pass all kinds of qualification examinations, the Databricks-Certified-Data-Engineer-Professional study practice question can bring you high quality learning platform.
NEW QUESTION # 63
A data engineer, User A, has promoted a new pipeline to production by using the REST API to programmatically create several jobs. A DevOps engineer, User B, has configured an external orchestration tool to trigger job runs through the REST API. Both users authorized the REST API calls using their personal access tokens.
Which statement describes the contents of the workspace audit logs concerning these events?
Answer: D
Explanation:
The events are that a data engineer, User A, has promoted a new pipeline to production by using the REST API to programmatically create several jobs, and a DevOps engineer, User B, has configured an external orchestration tool to trigger job runs through the REST API. Both users authorized the REST API calls using their personal access tokens. The workspace audit logs are logs that record user activities in a Databricks workspace, such as creating, updating, or deleting objects like clusters, jobs, notebooks, or tables. The workspace audit logs also capture the identity of the user who performed each activity, as well as the time and details of the activity.
Because these events are managed separately, User A will have their identity associated with the job creation events and User B will have their identity associated with the job run events in the workspace audit logs.
NEW QUESTION # 64
The data science team has created and logged a production model using MLflow. The model accepts a list of column names and returns a new column of type DOUBLE.
The following code correctly imports the production model, loads the customers table containing the customer_id key column into a DataFrame, and defines the feature columns needed for the model.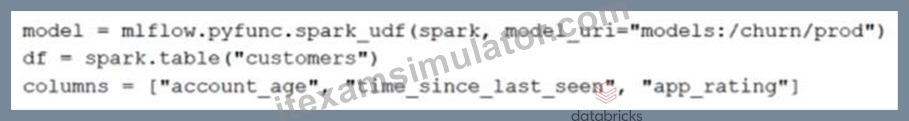
Which code block will output a DataFrame with the schema "customer_id LONG, predictions DOUBLE"?
Answer: E
Explanation:
This code block applies the Spark UDF created from the MLflow model to the DataFrame df by selecting the existing customer_id column and the new column produced by the model, which is aliased to predictions. The model(*columns) part is where the UDF is applied to the columns specified in the columns list, and alias("predictions") is used to name the output column of the model's predictions. This will result in a DataFrame with the desired schema: "customer_id LONG, predictions DOUBLE".
NEW QUESTION # 65
A data engineer is using Lakeflow Declarative Pipeline to propagate row deletions from a source bronze table (user_bronze) to a target silver table (user_silver). The engineer wants deletions in user_bronze to automatically delete corresponding rows in user_silver during pipeline execution.
Which configuration ensures deletions in the bronze table are propagated to the silver table?
Answer: B
Explanation:
According to Databricks documentation, Change Data Feed (CDF) allows pipelines to read incremental data changes, including inserts, updates, and deletes, from a Delta table. When deletions occur in the source table, reading the CDF stream ensures downstream consumers receive the deletion records. The Lakeflow Declarative Pipelines API provides the apply_changes() function (or auto-CDC pipelines) with the apply_as_deletes parameter to correctly apply those deletions to the target table. This enables automatic synchronization between bronze and silver layers. Options A and D either require manual handling or complete rebuilds, and C incorrectly applies CDF to the target rather than the source. Therefore, enabling CDF on the bronze table and using apply_as_deletes=True is the correct, Databricks-supported configuration.
NEW QUESTION # 66
A data engineer needs to productionize a new Spark application written by teammate. This application has numerous external dependencies, including libraries, and requires custom environment variables and Spark configuration parameters to be set. Which two methods will help the data engineer accomplish the task? (Choose two.)
Answer: B,D
Explanation:
Compute policies allow centrally defining and enforcing Spark configuration parameters, system properties, and environment variables required by the application, ensuring consistent production settings. Init scripts enable installing external dependencies and performing custom environment setup at cluster startup, making them essential for productionizing Spark applications with complex dependency and configuration requirements.
NEW QUESTION # 67
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.
Which solution would improve the performance?


Answer: B
Explanation:
When joining a stream of advertisement impressions with a stream of user clicks, you want to minimize the state that you need to maintain for the join. Option A suggests using a left outer join with the condition that clickTime == impressionTime, which is suitable for correlating events that occur at the exact same time. However, in a real-world scenario, you would likely need some leeway to account for the delay between an impression and a possible click. It's important to design the join condition and the window of time considered to optimize performance while still capturing the relevant user interactions. In this case, having the watermark can help with state management and avoid state growing unbounded by discarding old state data that's unlikely to match with new data.
NEW QUESTION # 68
......
After the client pay successfully they could receive the mails about Databricks-Certified-Data-Engineer-Professional guide questions our system sends by which you can download our test bank and use our study materials in 5-10 minutes. The mail provides the links and after the client click on them the client can log in and gain the Databricks-Certified-Data-Engineer-Professional Study Materials to learn. The procedures are simple and save clients' time. For the client the time is limited and very important and our product satisfies the client’s needs to download and use our Databricks-Certified-Data-Engineer-Professional practice engine immediately.
Databricks-Certified-Data-Engineer-Professional Exams Dumps: https://www.itexamsimulator.com/Databricks-Certified-Data-Engineer-Professional-brain-dumps.html