2026 Latest Itbraindumps DP-750 PDF Dumps and DP-750 Exam Engine Free Share: https://drive.google.com/open?id=1EpxF-fXJ2TmbBYzixcuBjyYP5-SiXc2v
In this cut-throat competitive world of Microsoft, the Microsoft DP-750 certification is the most desired one. But what creates an obstacle in the way of the aspirants of the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certificate is their failure to find up-to-date, unique, and reliable Implementing Data Engineering Solutions Using Azure Databricks (DP-750) practice material to succeed in passing the Microsoft DP-750 certification exam.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30–35% | - Ingest and transform data
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
The benefits after you pass the test DP-750 certification are enormous and you can improve your social position and increase your wage. Our DP-750 study materials will help you gain the success in your career. You can be respected and enjoy the great fame among the industry. When applying for the jobs your resumes will be browsed for many times and paid high attention to. The odds to succeed in the job interview will increase. So you could see the detailed information of our DP-750 Study Materials before you decide to buy them.
NEW QUESTION # 30
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.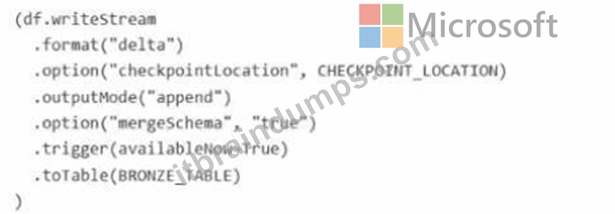
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.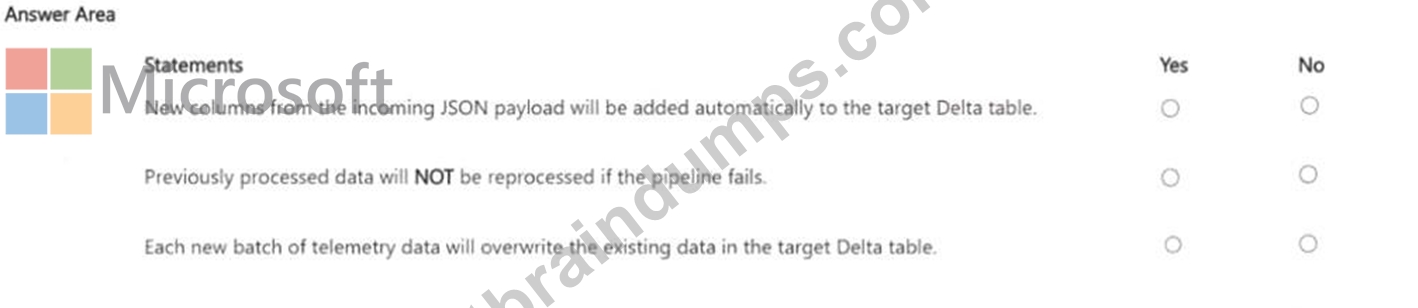
Answer:
Explanation: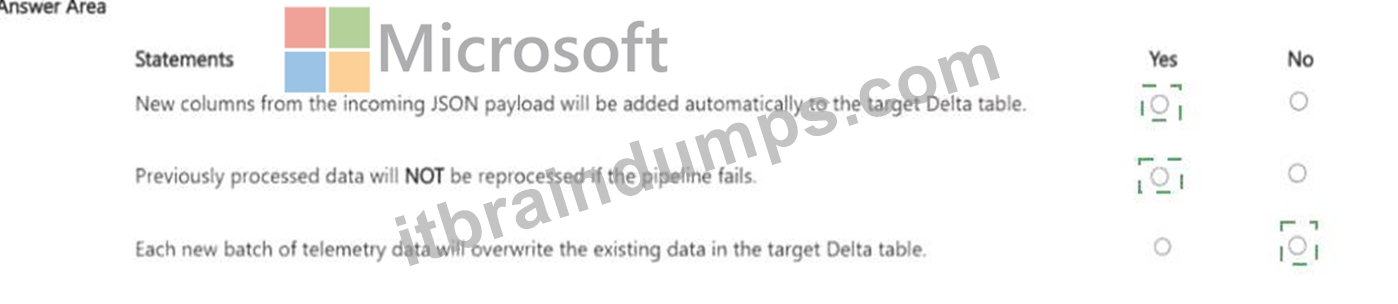
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: 'overwrite' replaces existing data; 'append' adds to it.
Always check whether the code uses the correct Delta format (.format('delta')), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 31
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales.
Sales stores transaction data and contains the following columns:
- transaction_id (string)
- transaction_date (date)
- amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
- amount must be greater than 0.
- transaction_id must never be null.
- Invalid records must be rejected when data is written to the Sales
table.
What should you do?
Answer: B
Explanation:
To enforce these table-level data quality rules and automatically reject any invalid write operations in Azure Databricks, you must configure NOT NULL and CHECK constraints on the Delta table using standard SQL commands.
In Delta Lake, these constraints are enforced instantly on write. If an incoming record violates any of them, the entire transaction fails, and the invalid records are rejected.
1. Enforce transaction_id Cannot Be Null
Add a NOT NULL constraint to the transaction_id column. This blocks any write attempt containing a null identifier.
ALTER TABLE sales_data ALTER COLUMN transaction_id SET NOT NULL;
2. Enforce amount Must Be Greater Than 0
Add a CHECK constraint to the table to validate that the amount values strictly exceed zero.
ALTER TABLE sales_data ADD CONSTRAINT check_amount_positive CHECK (amount > 0); Reference:
https://docs.databricks.com/aws/en/tables/constraints
NEW QUESTION # 32
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales. Sales stores transaction data and contains the following columns:
* transactionjd (string)
* transaction date (date)
* amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
* amount must be greater than 0.
* transaction id must never be null.
* Invalid records must be rejected when data is written to the Sales table.
What should you do?
Answer: D
Explanation:
The correct answer is D - a NOT NULL constraint on transaction_id and a CHECK constraint on amount.
Delta Lake table constraints are enforced at write time by the Delta engine itself. A NOT NULL constraint rejects any INSERT or UPDATE that would place a null in transaction_id. A CHECK constraint with amount
> 0 rejects any row where amount is zero or negative. Combined, they implement exactly the stated quality rules: bad rows are rejected when data is written, not filtered away at read time.
Options A and C (SELECT with WHERE / views) are read-time constructs - they don't prevent invalid data from entering the table. A clever pipeline bypass could write directly to the table and skip the view entirely.
Option B (row-level security with WHERE conditions) is an access-control feature for restricting which rows users see, not for enforcing data quality on writes. Table constraints are the only mechanism that genuinely blocks bad data at the storage layer.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-constraints
NEW QUESTION # 33
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named db1.sales_orders.
db1.sales_orders is updated nightly and has change data feed (CDF) enabled.
You need to ingest all the changes from the db1.sales_orders table, including inserts, updates, and deletes, into a downstream pipeline.
How should you complete the PsySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.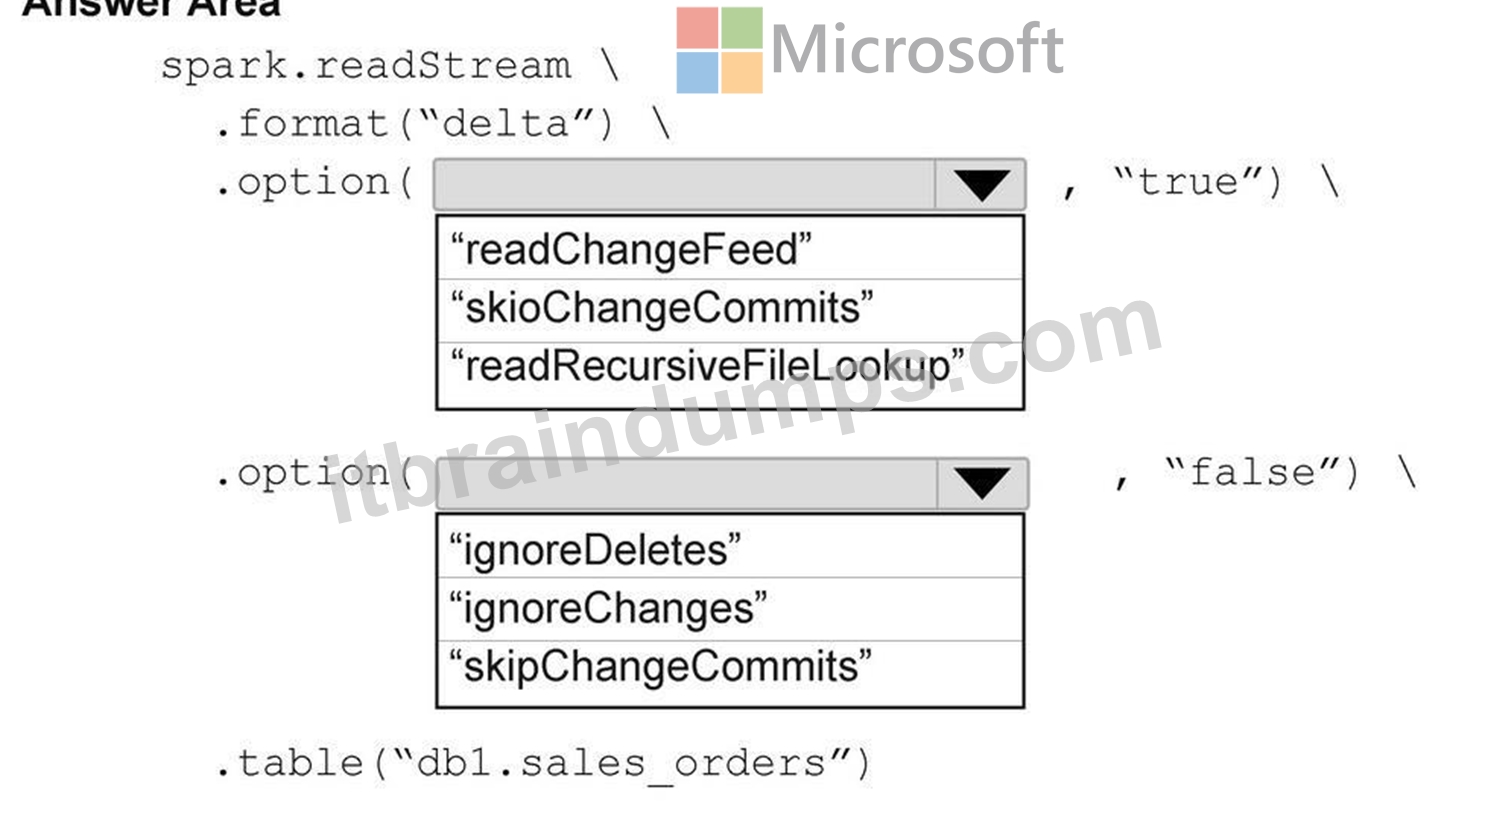
Answer:
Explanation: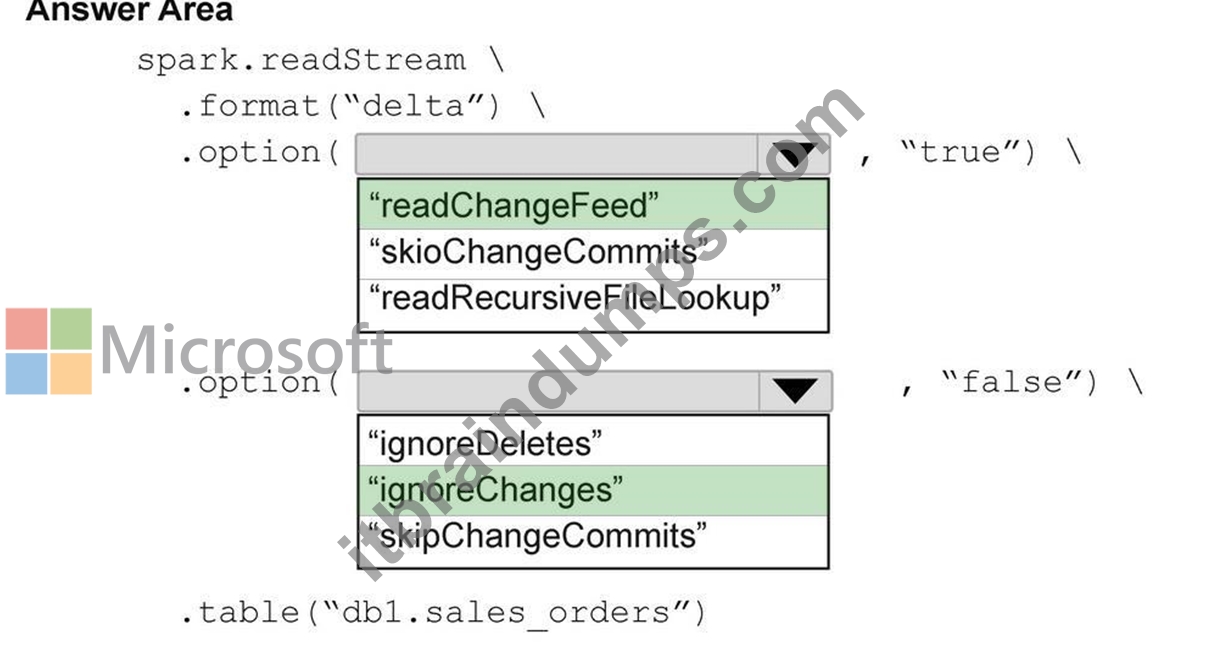
NEW QUESTION # 34
You have an Azure Databricks workspace that is enabled for Unity Catalog You have a complex job named Job1 that contains eight tasks. Job! takes multiple hours to complete During the last job run, the final task fails due to a transient issue.
You need to retry the last task without rerunning tasks that have already completed.
What should you do?
Answer: A
Explanation:
The correct answer is B - Repair the current job run.
Repair Run is designed for exactly this situation: a long-running job where most tasks succeeded but the final task failed due to a transient issue. Instead of restarting the entire eight-task job from the beginning - wasting hours of compute - Repair Run re-executes only the failed task and any dependents that were skipped as a result. All tasks that completed successfully are marked done and their outputs are reused.
Option A (update job parameters) changes configuration for future runs but doesn't re-execute the failed task in the current run. Option C (Restart Job1) re-runs every task from the start - precisely what the question says to avoid. Option D (disable and re-enable the schedule) creates a brand-new run on the next schedule trigger, again starting from the beginning rather than repairing the existing run.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/repair-job-failures
NEW QUESTION # 35
......
If you pay more attention to the privacy protection on buying DP-750 training materials, you can choose us. We respect your right to privacy. If you choose us, we ensure that your personal identification will be protected well. Once the order finishes, your personal information such as your name and email address will be concealed. Furthermore, we offer you free demo for you to have a try before buying DP-750 Exam Dumps, so that you can have a deeper understanding of what you are going to buy. You just need to spend about 48 to 72 hours on learning, and you can pass the exam. So don’t hesitate, just choose us!
DP-750 Exam Vce Format: https://www.itbraindumps.com/DP-750_exam.html
BONUS!!! Download part of Itbraindumps DP-750 dumps for free: https://drive.google.com/open?id=1EpxF-fXJ2TmbBYzixcuBjyYP5-SiXc2v