PrepAwayETE's website pages list the important information about our AI-500 real quiz, the exam name and code, the updated time, the total quantity of the questions and answers, the characteristics and merits of the product, the price, the discounts to the client, the details of our AI-500 training materials, the contact methods, the evaluations of the client on our AI-500 learning guide. You can analyze the information the website pages provide carefully before you decide to buy our AI-500 real quiz. Also our pass rate is high as 99% to 100%, you will pass the AI-500 exam for sure.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Develop multi-agent solutions in Azure | 30–35% | - Implement agents using Azure AI services
|
| Topic 2: Secure, govern, and deploy multi-agent solutions | 20–25% | - Deploy and maintain solutions
|
| Topic 3: Evaluate, optimize, and monitor multi-agent solutions | 20–25% | - Implement observability
|
| Topic 4: Architect multi-agent solutions | 15–20% | - Design logical architecture for multi-agent systems
|
>> AI-500 Vce Test Simulator <<
Our AI-500 exam torrent offers you free demo to try before buying. You will get your downing link and password after the payment, and you can download AI-500 exam dumps right now. If you have any questions, you can directly contact us through online live chat or you can notify us through email, we will give you reply as soon as we can. In addition, we provide you free update for one year after purchasing the AI-500 Exam Dumps.
NEW QUESTION # 11
You have a LangGraph workflow in Microsoft Foundry that is compiled as app by using a checkpointer. Each request includes a value named ticket_id.
You need to instrument the workflow so that each streamed run sends OpenTelemetry traces to Observability in Foundry. The solution must meet the following requirements:
* Correlate graph steps and tool calls for each request by the supplied ticket__id.
* Use the Azure Al OpenTelemetry tracer with the LangGraph invocation.
How should you complete the code? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.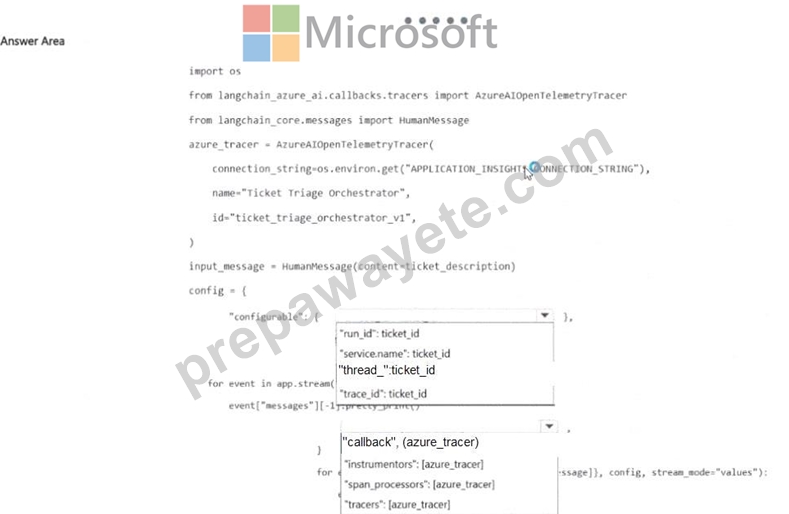
Answer:
Explanation: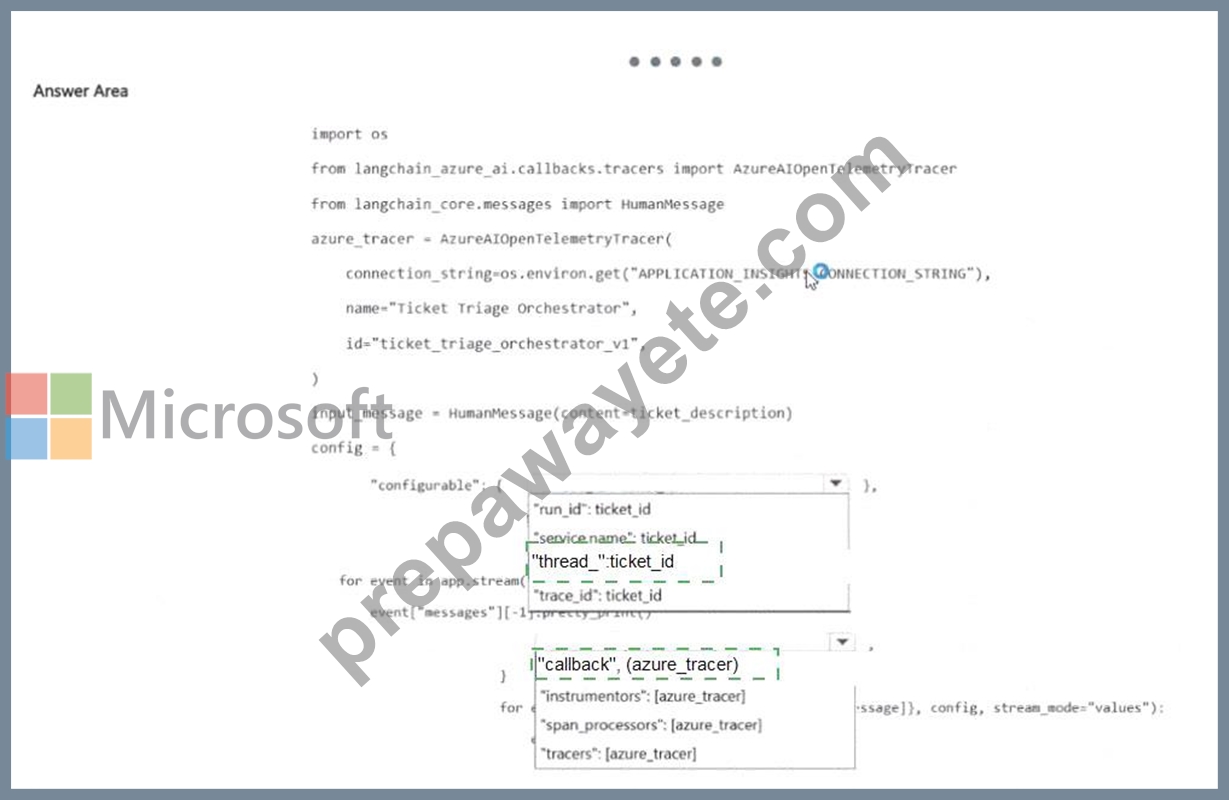
Explanation:
` " thread_id " : ticket_id` and ` " callbacks " : [azure_tracer]`.
LangGraph checkpointers use a stable `thread_id` under the configurable invocation context to associate execution and persisted state with the same logical request or conversation. Setting that value to the supplied
`ticket_id` allows graph steps and tool calls to be correlated to the ticket across a streamed run. Microsoft Foundry ' s LangGraph integration also uses `AzureAIOpenTelemetryTracer` through LangChain/LangGraph callbacks. Adding the tracer in the `callbacks` list causes agent, model, and tool spans to be emitted through OpenTelemetry and become visible in Foundry/Application Insights. A random run ID would not provide the stable checkpointer identity needed for state continuity, and fields such as `span_processors` are configured at a different instrumentation layer. Therefore the two code completions shown in the answer are correct. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: Microsoft Foundry - develop LangChain/LangGraph agents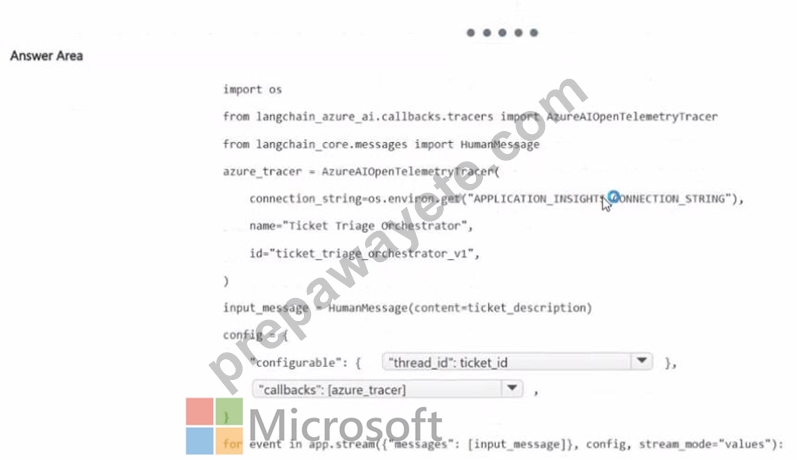
NEW QUESTION # 12
You have a LangGraph multi-agent workflow that uses Azure Cosmos DB as a checkpointer.
You plan to change the pruning rules for the running message list before the next release You need to implement evaluations tor memory. The solution must meet the following requirements:
* Verify that claim-related state values remain correct at transition points.
* Verify that conversation context is preserved after an interruption.
* Identify the source of any loss of continuity during a run
Which three actions should you perform Each correct answer presents part of the solution NOTE: Each correct selection is worth one point.
Answer: C,D,F
Explanation:
Memory evaluation must verify persistence across interruption, correctness of checkpointed state, and enough telemetry to locate where continuity was lost. Running a scripted multi-turn case with one stable `thread_id` before and after a restart directly tests whether the Cosmos-backed LangGraph checkpointer restores the same conversation/workflow. Comparing persisted checkpoint documents with expected state values at each handoff verifies that claim-related state has not been corrupted by the new pruning rules. Correlating the evaluation run with trace spans then provides the diagnostic path to identify which agent transition or state- management operation caused a failure. Changing the thread ID each turn would intentionally create separate state scopes, and removing durable artifacts would defeat the persistence test. Tool-call arguments alone do not prove workflow-memory continuity. Therefore D, E, and F are the complementary actions required. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Azure Cosmos DB integrations for LangGraph and agent state
NEW QUESTION # 13
You have a Microsoft Foundry multi-agent solution for loan applications. Each agent scores a full application independently and does NOT require output from other agents.
You need to recommend an orchestration pattern that meets the following requirements:
Produces one aggregated recommendation
Preserves independent scoring -
Minimizes end-to-end latency -
Minimize development effort -
What should you recommend?
Answer: B
Explanation:
The scoring agents do not depend on each other ' s output, so their work should be fanned out in parallel and aggregated afterward. Microsoft Agent Framework concurrent orchestration is intended for independent participants that can process the same input simultaneously. That minimizes end-to-end latency because completion time approaches the slowest individual scorer instead of the sum of all scorers. The concurrent workflow also provides a fan-in stage that can aggregate the separate scores into one recommendation without requiring a complex custom conversation protocol. Sequential orchestration wastes time by serializing independent work. Group chat and Magentic-style collaboration introduce unnecessary coordination and planning overhead when the agents simply need independent scoring. Therefore D, concurrent, is the simplest and fastest orchestration pattern. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Microsoft Agent Framework - Concurrent orchestration
NEW QUESTION # 14
You need to define a strategy to meet the business requirements for emergency room visits.
Which workflow node should you add to the Lead Orchestrator workflow?
Answer: A
Explanation:
The business requirement says that a physician must approve any triage assessment that recommends an emergency room visit. The workflow must therefore pause and collect a human response before continuing.
Ask a question is the option that introduces that interactive human-in-the-loop step. Deliver a message only informs someone; it does not capture a decision. Agent invokes another AI component, which would not satisfy the explicit requirement for a physician ' s approval. Go to changes the workflow path but likewise does not obtain human authorization. Microsoft Agent Framework documents human-in-the-loop request
/response patterns for cases where execution must wait for approval or additional human input. For a medical escalation decision, the control must be deterministic and auditable rather than encoded as a prompt suggestion. Consequently, Ask a question is the workflow node that best enforces the business requirement.
At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Microsoft Agent Framework - Human-in-the-loop workflows
NEW QUESTION # 15
You have a Microsoft Foundry agent that answers questions about products. You evaluate the agent responses and discover the following issues:
* Questions about a product named product1 make up 40 percent of user traffic, and responses are returned in inconsistent formats.
* Questions about a product named product2 appear infrequently in the existing logs but have high escalation rates.
The available chat logs include customer names and contact details, and the labeling budget enables subject matter experts (SMEs) to review only a limited subset of training examples.
You need to design a dataset preparation plan to fine-tune the agent. The solution must meet the following requirements:
* Match usage patterns for the product1 questions.
* Cover the product2 questions.
* Meet General Data Protection Regulation < GDPR) and Health Insurance Portability and Accountability Act (HIPAA) privacy requirements for names and contact details.
* Minimize SME review efforts during labeling.
What should you include in the design? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.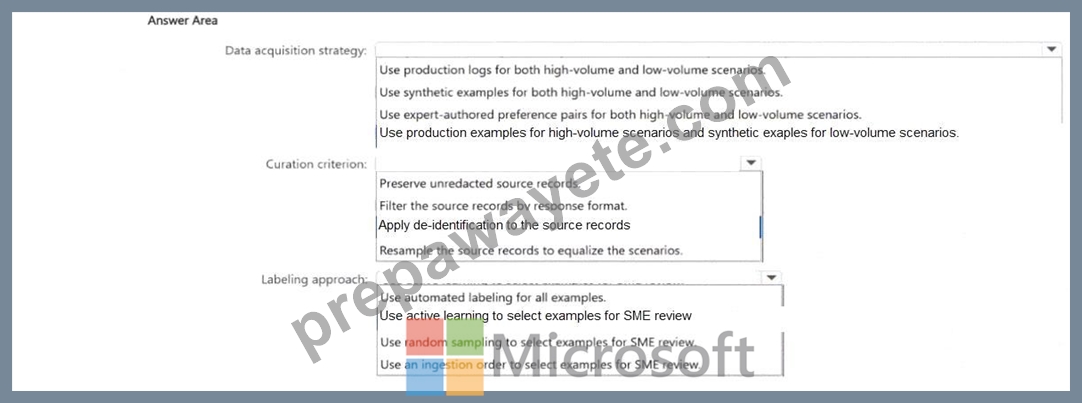
Answer:
Explanation: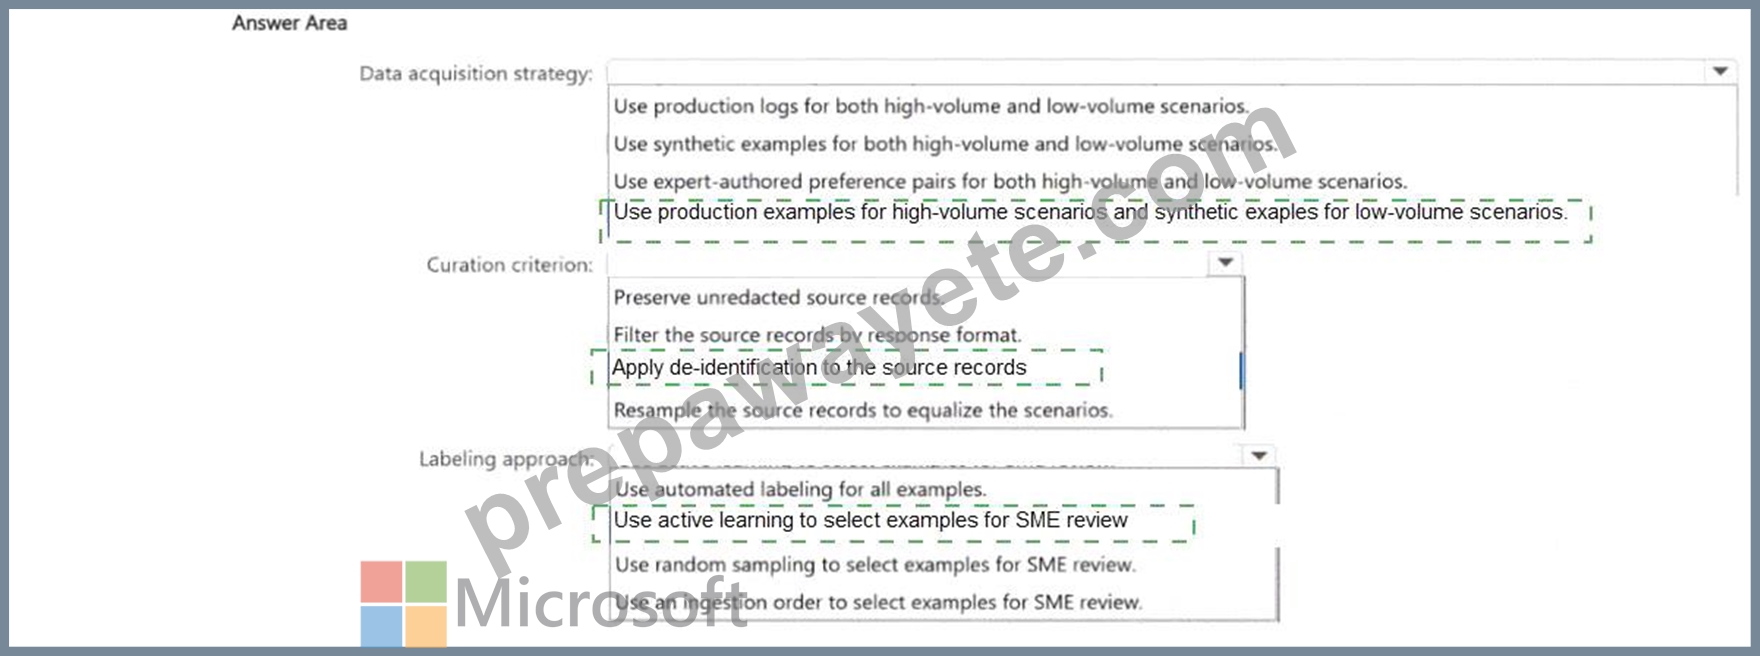
Explanation:
Data acquisition: Production examples for high-volume product1 and synthetic examples for sparse product2; Curation: De-identify source records; Labeling: Use active learning to prioritize SME review.
Product1 represents a large share of real traffic, so production examples best preserve its true usage distribution. Product2 appears infrequently but has high escalation impact, making synthetic generation appropriate for filling the coverage gap without waiting for more production traffic. Because the available logs contain names and contact information, those records should be de-identified before they are reused for training or labeling. Finally, the SME budget is limited, so active learning should prioritize the examples where expert labels are most informative instead of reviewing a uniform random sample. Microsoft Foundry guidance supports synthetic fine-tuning data when real examples are sparse, and Microsoft healthcare/privacy tooling supports de-identification of sensitive identifiers. This design balances representativeness, rare-case coverage, privacy, and labeling efficiency. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Microsoft Foundry - synthetic fine-tuning data generation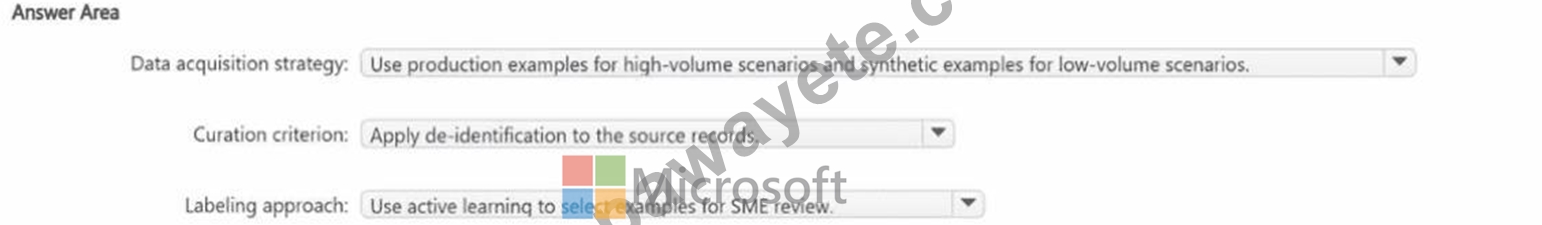
NEW QUESTION # 16
......
Are you an IT staff? Are you enroll in the most popular IT certification exams? If you tell me “yes", then I will tell you a good news that you're in luck. PrepAwayETE's Microsoft AI-500 Exam Training materials can help you 100% pass the exam. This is a real news. If you want to scale new heights in the IT industry, select PrepAwayETE please. Our training materials can help you pass the IT exams. And the materials we have are very cheap. Do not believe it, see it and then you will know.
AI-500 Practice Engine: https://www.prepawayete.com/Microsoft/AI-500-practice-exam-dumps.html