IT업계 종사자라면 누구나 Anthropic 인증CCAR-P시험을 패스하고 싶어하리라고 믿습니다. 많은 분들이 이렇게 좋은 인증시험은 아주 어렵다고 생각합니다. 네 맞습니다. 패스할 확율은 아주 낮습니다. 노력하지 않고야 당연히 불가능한 일이 아니겠습니까? Anthropic 인증CCAR-P 시험은 기초 지식 그리고 능숙한 전업지식이 필요 합니다. KoreaDumps는 여러분들한테Anthropic 인증CCAR-P시험을 쉽게 빨리 패스할 수 있도록 도와주는 사이트입니다. KoreaDumps의Anthropic 인증CCAR-P시험관련 자료로 여러분은 짧은 시간내에 간단하게 시험을 패스할수 있습니다. 시간도 절약하고 돈도 적게 들이는 이런 제안은 여러분들한테 딱 좋은 해결책이라고 봅니다.
| Section | Weight | Objectives |
|---|---|---|
| Stakeholder Communication & Lifecycle Management | 14% | - Document architectures and support full lifecycle phases - Conduct structured discovery and requirement gathering - Communicate architectural decisions and trade-offs - Manage stakeholder feedback and expectation alignment |
| Claude Models, Prompting & Context Engineering | 13% | - Apply context engineering and context management techniques - Design system prompts, templates, and guardrails - Mitigate prompt injection, leaks, and jailbreak risks - Select appropriate Claude models based on trade-offs |
| Integration | 19% | - Integrate Claude with enterprise systems, APIs, and tools - Design authentication, authorization, and observability - Integrate with data pipelines and RAG systems - Implement Model Context Protocol (MCP) integrations |
| Governance, Safety & Risk Management | 14% | - Ensure regulatory compliance (GDPR, HIPAA, etc.) - Implement guardrails and safety controls - Address ethical AI considerations and bias mitigation - Manage data privacy and security compliance |
| Evaluation, Testing & Optimization | 16% | - Define evaluation metrics and success criteria - Test accuracy, reliability, latency, and cost - Optimize performance, prompting, and model selection - Implement iterative improvement pipelines |
| Solution Design & Architecture | 17% | - Design multi-agent systems and orchestration strategies - Select architectural patterns: workflow, agentic, augmented LLM - Design end-to-end architectures and feedback loops - Align solutions to business value pillars - Translate business problems into Claude-based AI solutions |
| Developer Productivity & Operational Enablement | 7% | - Support debugging, monitoring, and operational resolution - Improve developer workflows with AI-assisted tooling - Configure Claude tools and environments for teams |
KoreaDumps는 많은 분들이Anthropic인증CCAR-P시험을 응시하여 성공하도록 도와주는 사이트입니다KoreaDumps의 Anthropic인증CCAR-P 학습가이드는 시험의 예상문제로 만들어진 아주 퍼펙트한 시험자료입니다. Anthropic인증CCAR-P시험은 최근 가장 인기있는 시험으로 IT인사들의 사랑을 독차지하고 있으며 국제적으로 인정해주는 시험이라 어느 나라에서 근무하나 제한이 없습니다. KoreaDumps로 여러분은 소유하고 싶은 인증서를 빠른 시일내에 얻게 될것입니다.
질문 # 21
You are defining transparency practices for a customer-facing assistant whose responses are materially shaped by AI.
Which transparency practice most directly supports responsible deployment?
정답:A
설명:
Responsible deployment requires users to receive an accurate representation of the system with which they are interacting. Option C provides that transparency while also establishing a practical escalation path.
Disclosure should be proportionate to the material role AI plays, expressed in language appropriate to the audience, and aligned with organizational policy and applicable regulatory obligations.
A documented human-contact route is important when the assistant cannot resolve an issue, produces a disputed result, encounters a high-impact exception, or handles a matter requiring human authority. Anthropic' s Responsible Scaling Policy recognizes escalation to human reviewers as an appropriate safeguard for edge cases and situations requiring human judgment. Responsible Scaling Policy Options A and D intentionally conceal material AI involvement from affected users, weakening informed decision-making, auditability, and trust. Option B is also unsuitable because transparency does not require revealing proprietary prompts, confidential controls, or internal security mechanisms; however, it does require an honest explanation of AI involvement and the system's operational role.
The correct design combines disclosure, understandable limitations, human escalation, and records demonstrating that the organization's transparency requirements are consistently applied.
Study Guide references/topics: AI transparency; informed user interaction; human escalation; responsible deployment; disclosure policy; operational accountability.
질문 # 22
A managed agent deployment for claims triage has grown from 6 tools to 34 tools over 18 months as product teams added capabilities. Triage accuracy has declined from 91 percent to 78 percent, and average tool- selection latency has increased by 2.3 seconds. A junior engineer has proposed adding a tool-router agent in front of the current agent to filter the tool list per request.
Which two findings should you present to justify capability decomposition before adding the router? (Select two.) Each correct answer presents part of the solution.
정답:B,C
설명:
Four distinct workflow domains indicate that the agent's responsibilities have expanded beyond a cohesive capability boundary. Decomposing the deployment into domain-focused agents reduces each agent's tool- selection space and produces clearer prompts, permissions, evaluations, and ownership. Option E strengthens this conclusion because placing a model-based router before the existing overloaded agent adds latency, cost, and another failure point without correcting the underlying capability sprawl. Overlapping descriptions should be clarified, while unused tools may simply be removed; neither finding alone proves that separate domain agents are required. Public documentation of a pattern is not evidence that it fits this workload. Anthropic emphasizes simple composable patterns, clearly differentiated tools, and empirical evaluation before adding orchestration complexity. Building Effective Agents
질문 # 23
You are designing a content moderation classifier that processes high volumes of user-generated comments under a tight per-message latency budget using well-defined classification labels.
Which model selection best aligns with the workload?
정답:C
설명:
Haiku is the appropriate starting point because the workload is high-volume, latency-sensitive, and based on a stable closed set of moderation labels. These characteristics favor a fast, cost-efficient model capable of consistent classification without incurring the additional inference time and expense associated with deeper reasoning.
Anthropic's model-selection guidance requires architects to balance capability, speed, and cost rather than automatically selecting the most capable model. Its content-moderation guidance specifically identifies Haiku as a cost-effective option for processing moderation workloads at substantial scale. Choosing the Right Model
, Content Moderation
Opus is disproportionate to a routine closed-set classification problem. Sonnet may become justified if evaluation demonstrates that Haiku fails materially on complex policy distinctions, multilingual ambiguity, or adversarial edge cases, but it should not be selected merely because it is larger. Enabling extended thinking on every request would further increase latency and token consumption without evidence that the additional reasoning improves the defined success metrics. The correct architectural practice is to establish a representative moderation evaluation set, validate Haiku against accuracy and safety thresholds, and escalate only the cases that genuinely need deeper reasoning.
Study Guide references/topics: Model selection; capability-latency-cost trade-offs; classification workloads; evaluation-driven routing; moderation architecture.
질문 # 24
You are identifying signals that a deployment should re-enter design rather than continue iterating in place.
Which signal most directly indicates the need for a new design cycle?
정답:D
설명:
A new design cycle is warranted when the required change crosses an architectural boundary. Option D explicitly states that the existing architecture cannot satisfy the new requirements without redistributing component responsibilities or altering core contracts. Such changes may affect service ownership, orchestration, data flows, integration interfaces, security boundaries, failure handling, evaluation strategy, and operational accountability. They therefore require renewed discovery, impact analysis, design review, stakeholder approval, and regression planning.
Options A, B, and C are localized maintenance activities. Clarifying a runbook improves operational documentation but does not change the deployed system's structure. Adjusting an alert threshold is a controlled operational tuning activity, provided the change remains within established monitoring policy.
Editing customer-facing copy is similarly confined to the presentation or content layer. None of these changes inherently invalidates component contracts or architectural assumptions.
An architect should distinguish between iteration within an approved design and evidence that the design itself no longer supports the required outcome. Re-entering design for every minor adjustment creates unnecessary governance overhead; continuing local iteration after architectural assumptions have failed creates unmanaged technical and operational risk. Option D is the only signal that establishes a structural incompatibility.
Study Guide references/topics: Lifecycle feedback loops; design re-entry criteria; architectural significance; component responsibilities; interface contracts; controlled operational iteration.
질문 # 25
You are reviewing a peer's end-to-end design for a Claude-based platform expected to scale to thousands of concurrent users.
For each statement, indicate Yes if it reflects sound architectural practice. Otherwise, select No.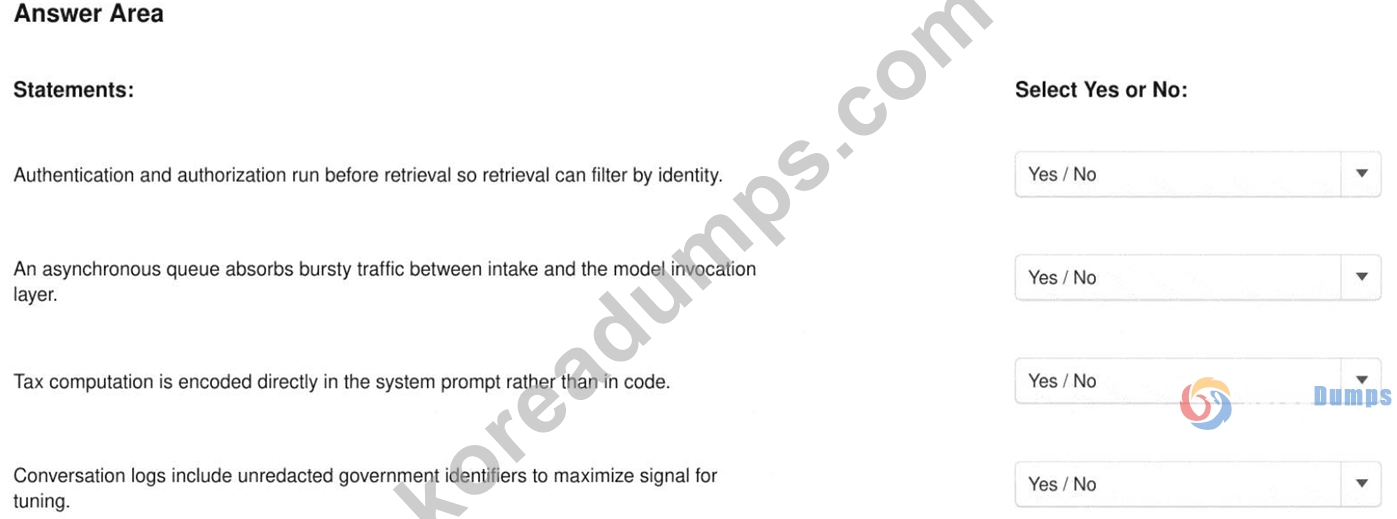
정답:
설명: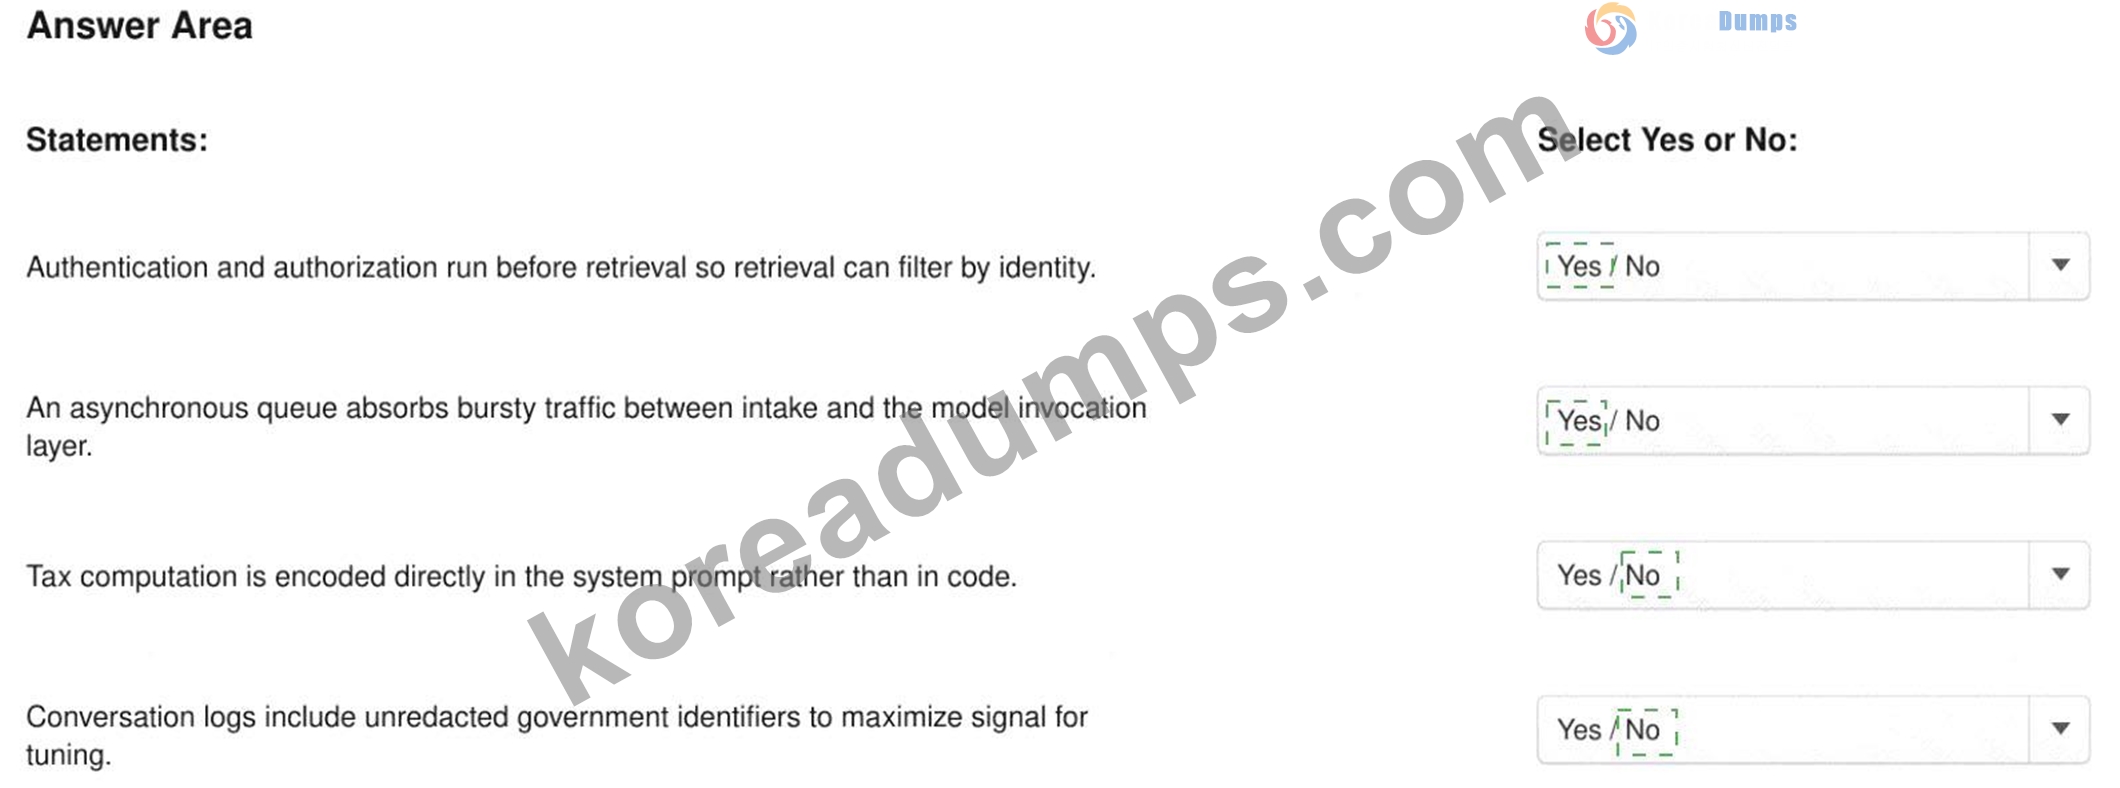
Explanation:
* Authentication and authorization run before retrieval so retrieval can filter by identity - Yes
* An asynchronous queue absorbs bursty traffic between intake and the model-invocation layer - Yes
* Tax computation is encoded directly in the system prompt rather than in code - No
* Conversation logs include unredacted government identifiers to maximize tuning signal - No Authentication and authorization must precede retrieval so unauthorized information never enters model context. An asynchronous queue is appropriate for burst absorption, backpressure, controlled concurrency, and retry management at scale. Deterministic tax computation should be implemented in validated code or a controlled calculation tool, not delegated to probabilistic prompt interpretation. Including unredacted government identifiers in conversation logs violates data-minimization principles and creates unnecessary privacy, security, and regulatory exposure. Sensitive fields should be removed, tokenized, or redacted before logging or model use unless specifically required and authorized. The resulting design separates deterministic computation, access control, scalable orchestration, and language reasoning into appropriate architectural layers.
질문 # 26
......
발달한 네트웨크 시대에 인터넷에 검색하면 많은Anthropic인증 CCAR-P시험공부자료가 검색되어 어느 자료로 시험준비를 해야 할지 망서이게 됩니다. 이 글을 보는 순간 다른 공부자료는 잊고KoreaDumps의Anthropic인증 CCAR-P시험준비 덤프를 주목하세요. 최강 IT전문가팀이 가장 최근의Anthropic인증 CCAR-P 실제시험 문제를 연구하여 만든Anthropic인증 CCAR-P덤프는 기출문제와 예상문제의 모음 공부자료입니다. KoreaDumps의Anthropic인증 CCAR-P덤프만 공부하면 시험패스의 높은 산을 넘을수 있습니다.
CCAR-P유효한 시험자료: https://www.koreadumps.com/CCAR-P_exam-braindumps.html