DOWNLOAD the newest PassCollection DP-800 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1qbPj2v9xyQ-iIkUlrZ4DHEnQ_j2WeUnj
PassCollection Developing AI-Enabled Database Solutions (DP-800) exam questions are consistently updated to make sure they are according to the Microsoft latest exam syllabus. If you choose PassCollection, you can be sure that you'll always get the updated and real DP-800 exam questions, which are essential to go through the DP-800 test in one go. In addition, we also offer up to 1 year of free Microsoft DP-800 certification exam question updates. These free updates ensure that candidates get access to the latest Microsoft exam questions even after they have made their initial purchase.
| Section | Objectives |
|---|---|
| Develop and manage database solutions | - Optimize performance and scalability - Ensure security and compliance of data solutions |
| Design and implement data solutions | - Design database solutions using Azure data services - Implement data storage and data processing solutions |
| Monitor, troubleshoot, and maintain solutions | - Monitoring database health and performance - Troubleshooting data pipeline issues |
| Integrate AI capabilities with database systems | - Use Azure AI services with database workloads - Implement AI-assisted data processing |
>> Valid Braindumps DP-800 Ebook <<
It is our company that can provide you with special and individual service which includes our DP-800 preparation quiz and good after-sale services. Our experts will check whether there is an update every day, so you needn’t worry about the accuracy of DP-800 Study Materials. If there is an update system, we will send them to the customer automatically. As is known to all, our DP-800 simulating materials are high pass-rate in this field, that's why we are so famous.
NEW QUESTION # 30
You have an Azure SQL database that contains a table named Table1. Table1 contains 25,000,000 rows of data and a datetime2 column named DateKey. The data in Table1 spans the years 2020 through 2021.
You need to partition the data in Table1 by year. The solution must minimize how long it takes to rebuild or reindex the table.
How should you complete the Transact-SQL code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.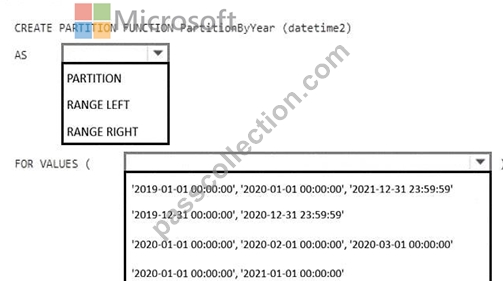
Answer:
Explanation: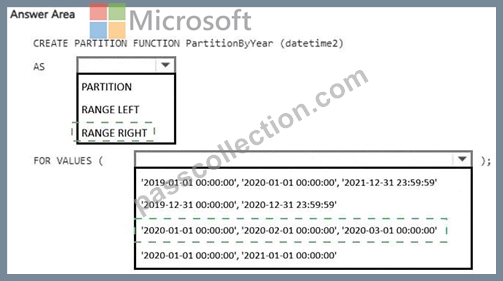
Explanation:
* Partition range # RANGE RIGHT
* Boundary values # ' 2020-01-01 00:00:00 ' , ' 2021-01-01 00:00:00 '
Comprehensive and Detailed Explanation with all Developing AI-Enabled Database Solutions documents : = The correct configuration is to use RANGE RIGHT with boundary values at the start of each year :
CREATE PARTITION FUNCTION PartitionByYear (datetime2)
AS RANGE RIGHT
FOR VALUES (
' 2020-01-01 00:00:00 ' ,
' 2021-01-01 00:00:00 '
);
Microsoft documents that with RANGE RIGHT , each boundary value belongs to the partition on its right .
For date-based partitioning, this is the natural pattern because a boundary such as 2021-01-01 becomes the lower boundary of the 2021 partition.
With these boundaries, the resulting ranges are effectively:
* Partition 1: dates before 2020-01-01
* Partition 2: 2020-01-01 through before 2021-01-01
* Partition 3: 2021-01-01 and later
This cleanly separates the 2020 and 2021 data into year-aligned partitions. Microsoft specifically recommends RANGE RIGHT for date-based boundaries because the first day of a period remains in the same partition as the rest of that period.
The other boundary choices are incorrect or less appropriate:
* Using year-end timestamps with RANGE LEFT is more cumbersome and can be sensitive to datetime2 precision.
* Monthly boundaries would partition by month, not year.
* Including 2019 and a 2021-12-31 23:59:59 boundary creates unnecessary partitions and is not the cleanest year-based design.
Therefore:
* First dropdown: RANGE RIGHT
* Second dropdown: ' 2020-01-01 00:00:00 ' , ' 2021-01-01 00:00:00 '
NEW QUESTION # 31
Drag and Drop Question
You have an Azure AI Search service and an index named hotels that includes a vector field named DescriptionVector.
You query hotels by using the Search Documents REST API.
You need to implement a hybrid search query that uses DescriptionVector and includes captions.
How should you complete the REST request body? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.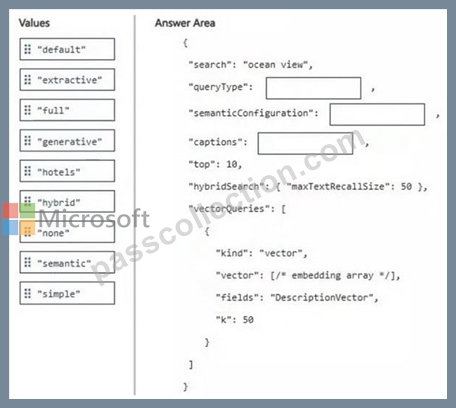
Answer:
Explanation: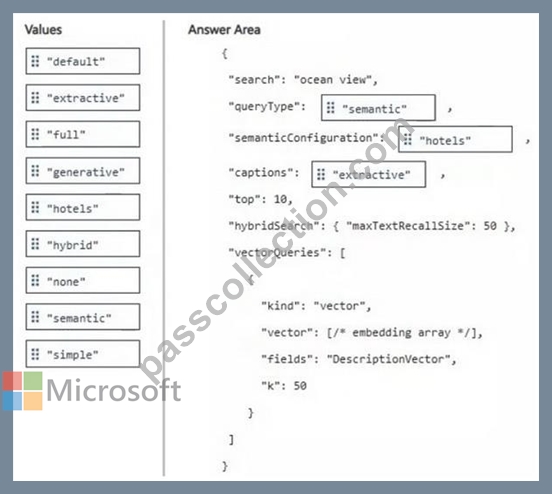
NEW QUESTION # 32
You are developing an Azure SQL database solution from a locally cloned GitHub repository by using Microsoft Visual Studio Code and GitHub Copilot Chat.
You need to ensure that GitHub Copilot Chat can call the hosted GitHub MCP Server tools by using OAuth. The MCP server configuration must be scoped to the repository.
What should you do in Visual Studio Code?
Answer: A
Explanation:
To connect GitHub Copilot Chat to an Azure SQL Database using a hosted GitHub MCP (Model Context Protocol) Server, follow these steps. This setup ensures that Copilot can interact directly with your repository and database schema using OAuth.
Step 1: Configure the MCP Server in VS Code
You must set the scope to the Workspace level to ensure the server is restricted to your specific repository.
Open your locally cloned GitHub repository in VS Code.
Open the Command Palette (Ctrl+Shift+P or Cmd+Shift+P).
Type and select: MCP: Add Server.
Select HTTP (HTTP or Server-Sent Events).
Enter the URL: https://api.githubcopilot.com/mcp/
Crucial: When prompted for the configuration scope, select Workspace Settings.
This saves the config to .vscode/settings.json, binding the server to this repo.
Step 2: Authenticate via OAuth
Once the server is added, Copilot needs permission to act on your behalf.
Open the GitHub Copilot Chat panel.
You will see a notification or a prompt within the chat asking to Authorize the MCP server.
Follow the browser prompts to sign in and grant OAuth permissions.
This allows the hosted MCP server to "see" your repository's code and metadata.
Reference:
https://skywork.ai/skypage/en/The-Ultimate-Guide-to-GitHub's-MCP-Server:-Bridging-AI-and- Your-Codebase/1970685991323758592
NEW QUESTION # 33
You have a GitHub Actions workflow that builds and deploys an Azure SQL database. The schema is stored in a GitHub repository as an SDK-style SQL database project.
Following a code review, you discover that you need to generate a report that shows whether the production schema has diverged from the model in source control.
Which action should you add to the pipeline?
Answer: A
Explanation:
To generate a report showing the differences between your source control and the production database, you should use the sql-action (officially Azure/sql-action@v2).
Specifically, you need to set the action parameter to DriftReport.
When configured this way, the action compares your .dacpac file (built from your SQL project) against the target production database. It generates an HTML or XML report detailing any "drift"-- changes made directly to production that aren't in your code.
Reference:
https://learn.microsoft.com/en-us/sql/tools/sqlpackage/sqlpackage-deploy-drift-report
NEW QUESTION # 34
You have a SQL database in Microsoft Fabric that contains the following functions:
* A multi-statement table-valued function (TVF) named sales.mstvf_orderStatus() that returns order status information
* A scalar user-defined function (UOF) named dbo.ufn_GetlaxMultiplier(
2026 Latest PassCollection DP-800 PDF Dumps and DP-800 Exam Engine Free Share: https://drive.google.com/open?id=1qbPj2v9xyQ-iIkUlrZ4DHEnQ_j2WeUnj