The candidates taking the Databricks Certified Professional Data Engineer Exam exam can try a free demo and test features of Databricks Databricks-Certified-Professional-Data-Engineer exam questions before purchasing it. DumpsQuestion also provides three months of free updates on Databricks exam questions if the exam content changes after you have bought the product. The DumpsQuestion gets feedback from learned professionals and makes improvements in the Databricks-Certified-Professional-Data-Engineer valid questions so that it can serve the purpose well.So, are you ready to earn a Databricks Certified Professional Data Engineer Exam, and join a group of certified and skilled professionals? If yes, getting the Databricks Databricks-Certified-Professional-Data-Engineer exam questions by DumpsQuestion is a perfect start to your Databricks Certified Professional Data Engineer Exam exam preparation.
| Section | Weight | Objectives |
|---|---|---|
| Data Ingestion | 15-20% | - Streaming ingestion
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
|
| Data Processing with Spark | 25-30% | - Spark DataFrames and Spark SQL
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
|
| Delta Lake | 20-25% | - Delta Lake operations
|
>> Databricks-Certified-Professional-Data-Engineer Exam Introduction <<
Our test engine is designed to make you feel Databricks-Certified-Professional-Data-Engineer exam simulation and ensure you get the accurate answers for real questions. You can instantly download the Databricks-Certified-Professional-Data-Engineer free demo in our website so you can well know the pattern of our test and the accuracy of our Databricks-Certified-Professional-Data-Engineer Pass Guide. It allows you to study anywhere and anytime as long as you download our Databricks-Certified-Professional-Data-Engineer practice questions.
NEW QUESTION # 169
The data architect has decided that once data has been ingested from external sources into the Databricks Lakehouse, table access controls will be leveraged to manage permissions for all production tables and views.
The following logic was executed to grant privileges for interactive queries on a production database to the core engineering group.
GRANT USAGE ON DATABASE prod TO eng;
GRANT SELECT ON DATABASE prod TO eng;
Assuming these are the only privileges that have been granted to the eng group and that these users are not workspace administrators, which statement describes their privileges?
Answer: B
Explanation:
The GRANT USAGE ON DATABASE prod TO eng command grants the eng group the permission to use the prod database, which means they can list and access the tables and views in the database. The GRANT SELECT ON DATABASE prod TO eng command grants the eng group the permission to select data from the tables and views in the prod database, which means they can query the data using SQL or DataFrame API. However, these commands do not grant the eng group any other permissions, such as creating, modifying, or deleting tables and views, or defining custom functions. Therefore, the eng group members are able to query all tables and views in the prod database, but cannot create or edit anything in the database. Reference:
Grant privileges on a database: https://docs.databricks.com/en/security/auth-authz/table-acls/grant-privileges-database.html Privileges you can grant on Hive metastore objects: https://docs.databricks.com/en/security/auth-authz/table-acls/privileges.html
NEW QUESTION # 170
The following table consists of items found in user carts within an e-commerce website.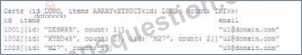
The following MERGE statement is used to update this table using an updates view, with schema evaluation enabled on this table.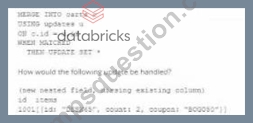
How would the following update be handled?
Answer: A
Explanation:
With schema evolution enabled in Databricks Delta tables, when a new field is added to a record through a MERGE operation, Databricks automatically modifies the table schema to include the new field. In existing records where this new field is not present, Databricks will insert NULL values for that field. This ensures that the schema remains consistent across all records in the table, with the new field being present in every record, even if it is NULL for records that did not originally include it.
:
Databricks documentation on schema evolution in Delta Lake: https://docs.databricks.com/delta/delta-batch.
html#schema-evolution
NEW QUESTION # 171
A dataset has been defined using Delta Live Tables and includes an expectations clause:
1. CONSTRAINT valid_timestamp EXPECT (timestamp > '2020-01-01')
What is the expected behaviour when a batch of data containing data that violates these constraints is
processed?
Answer: B
NEW QUESTION # 172
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.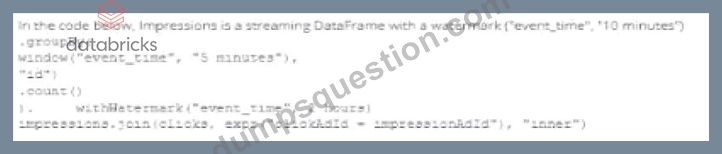
Which solution would improve the performance?




Answer: D
Explanation:
When joining a stream of advertisement impressions with a stream of user clicks, you want to minimize the state that you need to maintain for the join. Option A suggests using a left outer join with the condition that clickTime == impressionTime, which is suitable for correlating events that occur at the exact same time.
However, in a real-world scenario, you would likely need some leeway to account for the delay between an impression and a possible click. It's important to design the join condition and the window of time considered to optimize performance while still capturing the relevant user interactions. In this case, having the watermark can help with state management and avoid state growing unbounded by discarding old state data that's unlikely to match with new data.
NEW QUESTION # 173
A Delta Lake table representing metadata about content from user has the following schema:
Based on the above schema, which column is a good candidate for partitioning the Delta Table?
Answer: D
Explanation:
Partitioning a Delta Lake table improves query performance by organizing data into partitions based on the values of a column. In the given schema, the date column is a good candidate for partitioning for several reasons:
* Time-Based Queries: If queries frequently filter or group by date, partitioning by the date column can significantly improve performance by limiting the amount of data scanned.
* Granularity: The date column likely has a granularity that leads to a reasonable number of partitions (not too many and not too few). This balance is important for optimizing both read and write performance.
* Data Skew: Other columns like post_id or user_id might lead to uneven partition sizes (data skew), which can negatively impact performance.
Partitioning by post_time could also be considered, but typically date is preferred due to its more manageable granularity.
References:
* Delta Lake Documentation on Table Partitioning: Optimizing Layout with Partitioning
NEW QUESTION # 174
......
Using the Databricks Databricks-Certified-Professional-Data-Engineer updated product of DumpsQuestion will result in cracking the Databricks-Certified-Professional-Data-Engineer real test on the first try. The reliability and accuracy of our Databricks Databricks-Certified-Professional-Data-Engineer practice questions make us one of the trusted brands in the market. DumpsQuestion proudly presents you with an Databricks-Certified-Professional-Data-Engineer Exam Dumps that carry actual Databricks Databricks-Certified-Professional-Data-Engineer questions.
Databricks-Certified-Professional-Data-Engineer Torrent: https://www.dumpsquestion.com/Databricks-Certified-Professional-Data-Engineer-exam-dumps-collection.html