2026 Latest ValidTorrent MLA-C01 PDF Dumps and MLA-C01 Exam Engine Free Share: https://drive.google.com/open?id=1PJTJpfw6rUCrheRzaGHqkZmmoX5p8rrM
I know that you are already determined to make a change, and our MLA-C01 exam materials will spare no effort to help you. After you purchase our MLA-C01 practice engine, I hope you can stick with it. We can promise that you really don't need to spend a long time and you can definitely pass the MLA-C01 Exam. As we have so many customers passed the MLA-C01 study questions, the pass rate is high as 98% to 100%. And this data is tested. With our MLA-C01 learning guide, you won't regret!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Model Deployment and Inference | 20% | - Model deployment strategies (real-time, batch) - SageMaker endpoints configuration - Inference optimization (latency, throughput) - A/B testing and shadow mode deployment - Model versioning and rollback |
| Topic 2: Model Development | 30% | - Transfer learning and fine-tuning - Algorithm selection and model architecture - ML frameworks (SageMaker, built-in algorithms) - Distributed training - Hyperparameter optimization - Training and validation strategies |
| Topic 3: MLOps and Monitoring | 28% | - Model monitoring and drift detection - Incident response and remediation - Security and access management for ML - Cost optimization for ML workloads - CI/CD pipelines for ML - Model lineage and reproducibility |
| Topic 4: Data Processing | 22% | - Data validation and quality assessment - Data ingestion and transformation - Data pipelining with AWS services ( Glue, Data Brew, etc.) - Data preprocessing and feature engineering - Handling imbalanced data |
Customers always attach great importance to the quality of MLA-C01 exam torrent. We can guarantee that our study materials deserve your trustee. We have built good reputation in the market now. After about ten years’ development, we have owned a perfect quality control system. All MLA-C01 exam prep has been inspected strictly before we sell to our customers. The inspection process is very strict and careful. Any small mistake can be tested clearly. So you can completely believe our MLA-C01 Exam Guide. What’s more, all contents are designed carefully according to the exam outline. As you can see, the quality of our MLA-C01 exam torrent can stand up to the test. Your learning will be a pleasant process.
NEW QUESTION # 62
An ML engineer is working on an ML model to predict the prices of similarly sized homes. The model will base predictions on several features The ML engineer will use the following feature engineering techniques to estimate the prices of the homes:
* Feature splitting
* Logarithmic transformation
* One-hot encoding
* Standardized distribution
Select the correct feature engineering techniques for the following list of features. Each feature engineering technique should be selected one time or not at all (Select three.)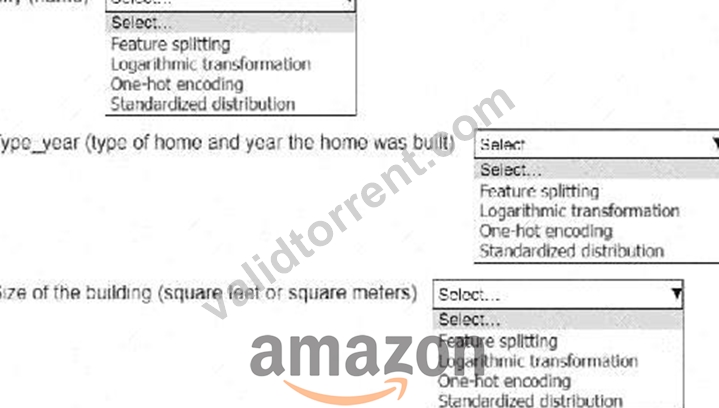
Answer:
Explanation: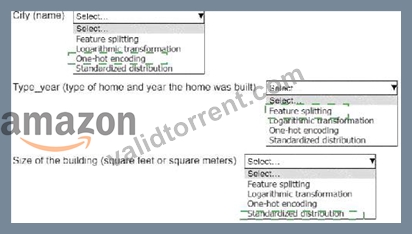
Explanation:
City (name): One-hot encoding
Type_year (type of home and year the home was built): Feature splitting Size of the building (square feet or square meters): Standardized distribution City (name): One-hot encoding Why? The " City " is a categorical feature (non-numeric), so one-hot encoding is used to transform it into a numeric format. This encoding creates binary columns for each unique category (e.g., cities like " New York " or " Los Angeles " ), which the model can interpret.
Type_year (type of home and year the home was built): Feature splitting Why? " Type_year " combines two pieces of information into one column, which could confuse the model.
Feature splitting separates this column into two distinct features: " Type of home " and " Year built, " enabling the model to process each feature independently.
Size of the building (square feet or square meters): Standardized distribution Why? Size is a continuous numerical variable, and standardization (scaling the feature to have a mean of 0 and a standard deviation of 1) ensures that the model treats it fairly compared to other features, avoiding bias from differences in feature scale.
By applying these feature engineering techniques, the ML engineer can ensure that the input data is correctly formatted and optimized for the model to make accurate predictions.
NEW QUESTION # 63
A company is gathering audio, video, and text data in various languages. The company needs to use a large language model (LLM) to summarize the gathered data that is in Spanish.
Which solution will meet these requirements in the LEAST amount of time?
Answer: B
Explanation:
Amazon Transcribeis well-suited for converting audio data into text, including Spanish.
Amazon Translatecan efficiently translate Spanish text into English if needed.
Amazon Bedrock, with theJurassic model, is designed for tasks like text summarization and can handle large language models (LLMs) seamlessly. This combination provides a low-code, managed solution to process audio, video, and text data with minimal time and effort.
NEW QUESTION # 64
A company is using an Amazon S3 bucket to collect data that will be used for ML workflows. The company needs to use AWS Glue DataBrew to clean and normalize the data.
Which solution will meet these requirements?
Answer: B
Explanation:
AWS Glue DataBrew supports datasets sourced directly from Amazon S3 paths. To clean and normalize data, AWS documentation specifies using DataBrew recipes, which define transformation steps such as standardization, deduplication, and formatting.
A profile job is used only for data analysis and statistics generation, not for transformation. A recipe job applies actual transformations to the data and writes the output to Amazon S3.
JDBC connections are used for relational databases, not S3 buckets. Therefore, options C and D are invalid.
AWS clearly documents that the correct workflow is:
* Create a DataBrew dataset from an S3 path
* Define transformations using a recipe
* Run a recipe job to produce cleaned data
Thus, Option B is the correct and AWS-aligned answer.
NEW QUESTION # 65
A company uses Amazon SageMaker Studio to develop an ML model. The company has a single SageMaker Studio domain. An ML engineer needs to implement a solution that provides an automated alert when SageMaker compute costs reach a specific threshold.
Which solution will meet these requirements?
Answer: A
Explanation:
Adding resource tagging to the SageMaker user profile enables tracking and monitoring of costs associated with specific SageMaker resources.
AWS Budgets allows setting thresholds and automated alerts for costs and usage, making it the ideal service to notify the ML engineer when compute costs reach a specified limit.
This solution is efficient and integrates seamlessly with SageMaker and AWS cost management tools.
NEW QUESTION # 66
A company stores historical data in .csv files in Amazon S3. Only some of the rows and columns in the .csv files are populated. The columns are not labeled. An ML engineer needs to prepare and store the data so that the company can use the data to train ML models.
Select and order the correct steps from the following list to perform this task. Each step should be selected one time or not at all. (Select and order three.)
* Create an Amazon SageMaker batch transform job for data cleaning and feature engineering.
* Store the resulting data back in Amazon S3.
* Use Amazon Athena to infer the schemas and available columns.
* Use AWS Glue crawlers to infer the schemas and available columns.
* Use AWS Glue DataBrew for data cleaning and feature engineering.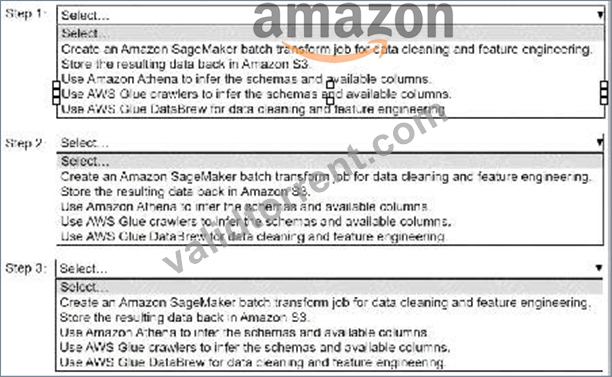
Answer:
Explanation:
Explanation:
Step 1: Use AWS Glue crawlers to infer the schemas and available columns.Step 2: Use AWS Glue DataBrew for data cleaning and feature engineering.Step 3: Store the resulting data back in Amazon S3.
* Step 1: Use AWS Glue Crawlers to Infer Schemas and Available Columns
* Why?The data is stored in .csv files with unlabeled columns, and Glue Crawlers can scan the raw data in Amazon S3 to automatically infer the schema, including available columns, data types, and any missing or incomplete entries.
* How?Configure AWS Glue Crawlers to point to the S3 bucket containing the .csv files, and run the crawler to extract metadata. The crawler creates a schema in the AWS Glue Data Catalog, which can then be used for subsequent transformations.
* Step 2: Use AWS Glue DataBrew for Data Cleaning and Feature Engineering
* Why?Glue DataBrew is a visual data preparation tool that allows for comprehensive cleaning and transformation of data. It supports imputation of missing values, renaming columns, feature engineering, and more without requiring extensive coding.
* How?Use Glue DataBrew to connect to the inferred schema from Step 1 and perform data cleaning and feature engineering tasks like filling in missing rows/columns, renaming unlabeled columns, and creating derived features.
* Step 3: Store the Resulting Data Back in Amazon S3
* Why?After cleaning and preparing the data, it needs to be saved back to Amazon S3 so that it can be used for training machine learning models.
* How?Configure Glue DataBrew to export the cleaned data to a specific S3 bucket location. This ensures the processed data is readily accessible for ML workflows.
Order Summary:
* Use AWS Glue crawlers to infer schemas and available columns.
* Use AWS Glue DataBrew for data cleaning and feature engineering.
* Store the resulting data back in Amazon S3.
This workflow ensures that the data is prepared efficiently for ML model training while leveraging AWS services for automation and scalability.
NEW QUESTION # 67
......
You can find features of this Amazon MLA-C01 prep material below. All smart devices are suitable to use Amazon MLA-C01 pdf dumps of ValidTorrent. Therefore, you can open this Amazon MLA-C01 real dumps document and study for the Amazon MLA-C01 test at any time from your comfort zone. These MLA-C01 Dumps are updated, and ValidTorrent regularly amends the content as per new changes in the MLA-C01 real certification test.
MLA-C01 Dumps Questions: https://www.validtorrent.com/MLA-C01-valid-exam-torrent.html
P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by ValidTorrent: https://drive.google.com/open?id=1PJTJpfw6rUCrheRzaGHqkZmmoX5p8rrM