Many exam candidates feel hampered by the shortage of effective 3V0-25.25 practice materials, and the thick books and similar materials causing burden for you. Serving as indispensable choices on your way of achieving success especially during this exam, more than 98 percent of candidates pass the exam with our 3V0-25.25 practice materials and all of former candidates made measurable advance and improvement. All 3V0-25.25 practice materials fall within the scope of this exam for your information. The content is written promptly and helpfully because we hired the most processional experts in this area to compile the 3V0-25.25 practice materials. Our 3V0-25.25 practice materials will be worthy of purchase, and you will get manifest improvement.
| Certification Vendor: | VMware |
|---|---|
| Exam Name: | Advanced VMware Cloud Foundation 9.0 Networking |
| Exam Number: | 3V0-25.25 |
| Related Certifications: | VMware Certified Professional - Data Center Virtualization (VCP-DCV) VMware Cloud Foundation Specialist certifications |
| Real Exam Qty: | 60-70 |
| Exam Price: | USD 250-450 (varies by region) |
| Available Languages: | English |
| Exam Format: | Multiple select, Multiple choice, Scenario-based questions, Drag and drop |
| Certificate Validity Period: | 2 years |
| Passing Score: | Scaled score 300 (on a 100-500 scale) |
| Exam Duration: | 135-150 |
| Recommended Training: | VMware Cloud Foundation Training VMware NSX Training Courses |
| Exam Registration: | VMware Certification Portal Pearson VUE VMware Exams |
| Sample Questions: | VMware 3V0-25.25 Sample Questions |
| Exam Way: | Computer-based exam delivered via online proctoring or Pearson VUE test centers |
| Pre Condition: | Recommended: VMware Certified Professional (VCP-DCV) or equivalent hands-on experience with VMware Cloud Foundation and NSX networking |
| Official Syllabus URL: | https://www.vmware.com/education-services/certification.html |
If you fail 3V0-25.25 exam unluckily, don’t worry about it, because we provide full refund for everyone who failed the exam. You can ask for a full refund once you show us your unqualified transcript to our staff. The whole process is time-saving and brief, which would help you pass the next 3V0-25.25 Exam successfully. Please contact us through email when you need us. The 3V0-25.25 question dumps produced by our company, is helpful for our customers to pass their exams and get the 3V0-25.25 certification within several days. Our 3V0-25.25 exam questions are your best choice.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 38
A sovereign cloud provider has a VMware Cloud Foundation (VCF) stretched Workload Domain across two data centers (AZ1 and AZ2), where site connectivity via Layer 3 is provided by the underlay. The following NSX details are included in the design:
* Each site must host its own local NSX Edge Cluster for availability zones.
* Tier-0 gateways must be configured in active/active mode with BGP ECMP to local top-of-rack switches.
* Inter-site Edge TEP traffic must not cross the inter-DC link.
* SDDC Manager is used to automate NSX deployment.
During deployment of the Edge Cluster for AZ2, the SDDC Manager workflow fails because the Edge transport nodes' TEP IPs are not reachable from the ESXi transport nodes. Which step ensures correct Edge Cluster deployment in multi-site stretched domains?
Answer: C
Explanation:
Comprehensive and Detailed 250 to 350 words of Explanation From VMware Cloud Foundation (VCF) documents:
In aVMware Cloud Foundation (VCF)stretched cluster or Multi-Availability Zone (Multi-AZ) architecture, the networking design must account for the fact that AZ1 and AZ2 typically reside in different Layer 3 subnets. While the NSX Overlay provides Layer 2 adjacency for virtual machines across sites, the underlying Tunnel Endpoints (TEPs)must be able to communicate over the physical Layer 3 network.
According to the VCF Design Guide for Multi-AZ deployments, when stretching a workload domain, each availability zone should have its own dedicatedTEP IP Pool. This is because TEP traffic is encapsulated (Geneve) and routed via the physical underlay. If the Edge nodes in AZ2 were to use the same IP pool as AZ1 (Option C), the physical routers would likely encounter routing conflicts or reachability issues, as the subnet for AZ1 would not be natively routable or "local" to the AZ2 Top-of-Rack (ToR) switches.
The failure during the SDDC Manager workflow occurs because the automated "Liveness Check" or "Pre- validation" step attempts to verify that the newly assigned TEP IPs in AZ2 can reach the existing TEPs in the environment. To resolve this and ensure a successful deployment, the administrator must define a uniqueAZ2- specific IP Poolin NSX. Furthermore, this pool must be associated with anUplink Profile(or a Sub-Transport Node Profile in VCF 5.x/9.0) that uses the specific VLAN tagged for TEP traffic in the second data center.
This ensures that the Edge Nodes in AZ2 are assigned IPs that are valid and routable within the AZ2 underlay, allowing Geneve tunnels to establish correctly to the ESXi hosts in both sites without requiring a stretched Layer 2 physical network for the TEP infrastructure.
NEW QUESTION # 39
An administrator implements route leaking between the Tier-0 gateways to enhance east/west communication because the physical L3 devices are oversubscribed.
Where should route-maps be configured based on the architecture observed in the diagram?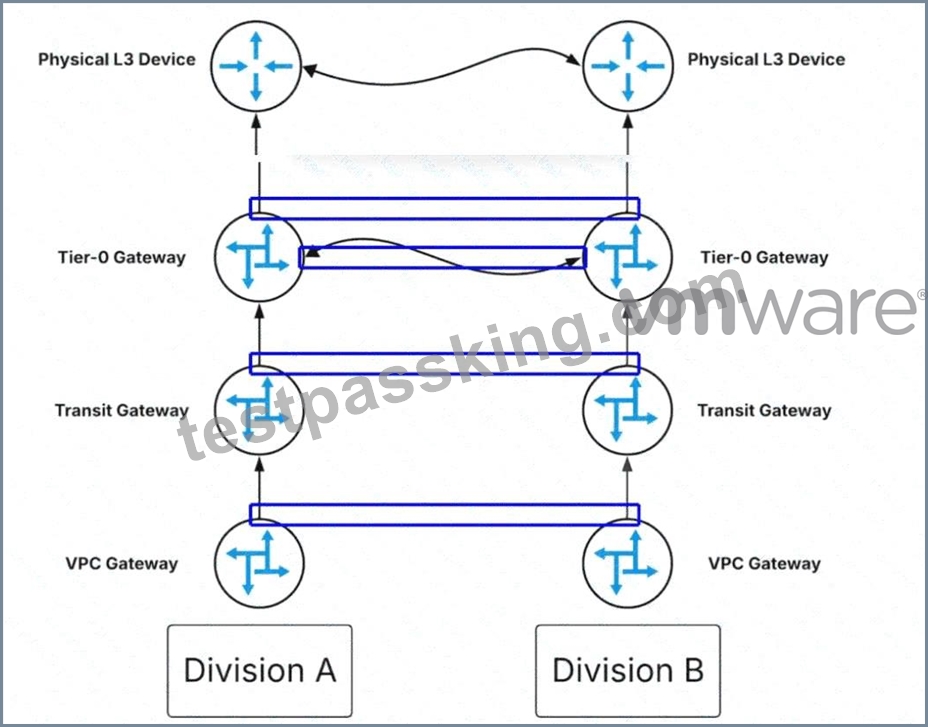
Answer:
Explanation: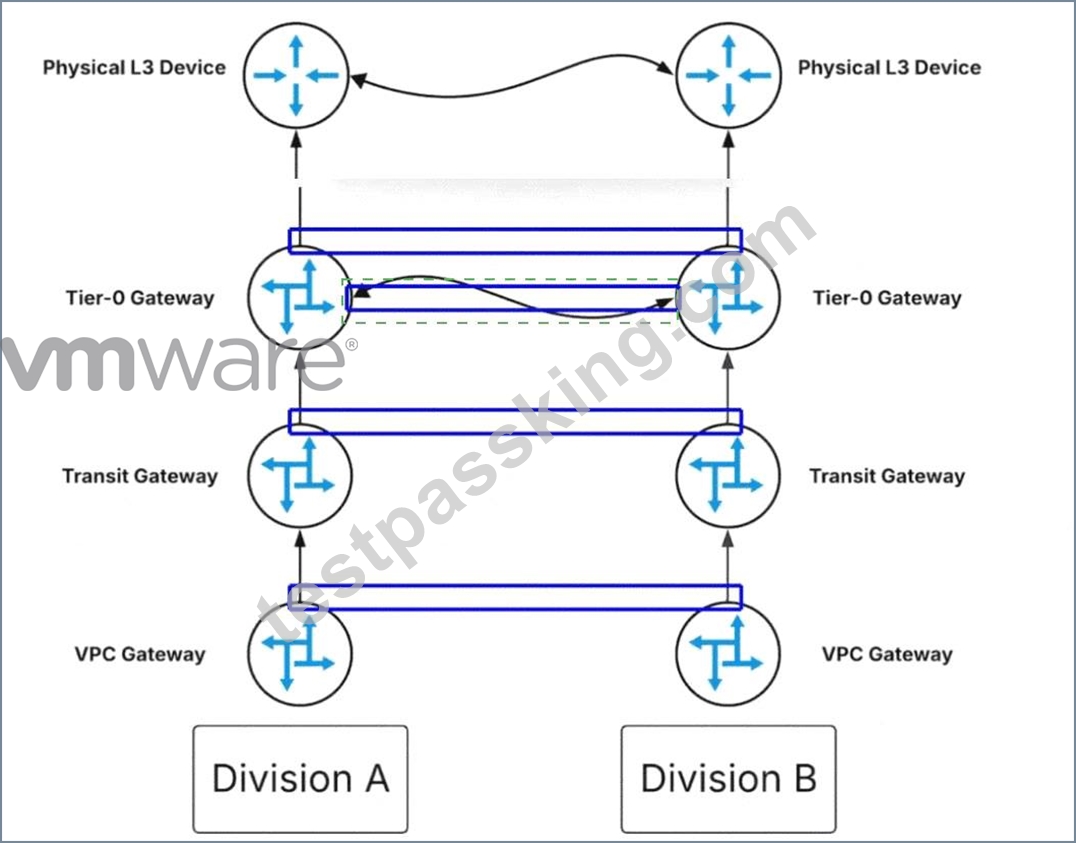
Explanation:
The administrator should click on theblue box representing the logical link between the two Tier-0 Gateways.
In the multi-tenant architecture ofVMware Cloud Foundation (VCF) 9.0, networking is structured hierarchically with VPC Gateways, Transit Gateways, and Tier-0 Gateways. Under normal conditions, traffic between isolated divisions (such as Division A and Division B) that need to communicate might be routed
"North" all the way to thePhysical L3 Devices(the physical core routers) before being routed back down.
However, if these physical devices are oversubscribed or reaching their throughput limits, this creates a performance bottleneck.
To optimize this flow, NSX allows forRoute Leakingat the Tier-0 layer. By establishing a logical peering or connection directly between twoTier-0 Gatewayswithin the virtual fabric, administrators can exchange routing information (prefixes) between the two environments without the traffic ever leaving the SDDC.
To control exactly which networks are shared and to prevent routing loops or unauthorized access,Route- Mapsmust be applied at this inter-gateway connection point. These route-maps define the "Permit" or "Deny" statements for specific IP prefixes being "leaked" from one routing table to another. By clicking the highlighted link between the Tier-0 Gateways, the administrator is targeting the specific control plane interface where these prefix exchanges occur. This configuration ensures that East-West traffic between Division A and Division B is handled locally by theNSX Edge Nodes, effectively bypassing the oversubscribed physical L3 devices and significantly reducing latency and physical network congestion.
NEW QUESTION # 40
The network team has decided to use a single Edge Cluster to provide Tier-0 A/A Gateway routing and Tier-1 Gateway A/S services.
The active Tier-1 with a Gateway Firewall service is on EN2.
Which highlighted options will show the ECMP paths used by that Tier-1 GFW?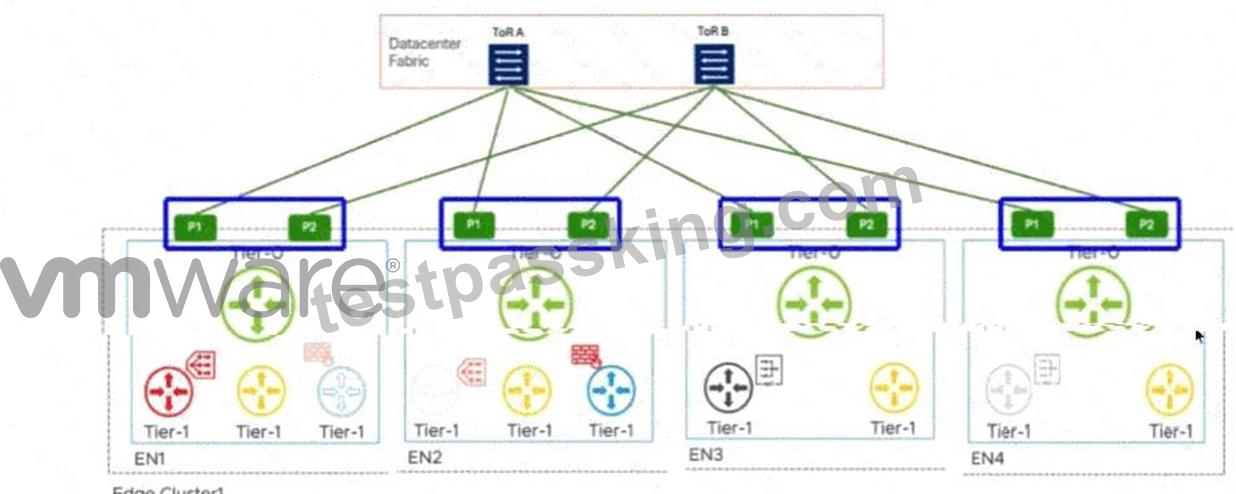
Answer:
Explanation: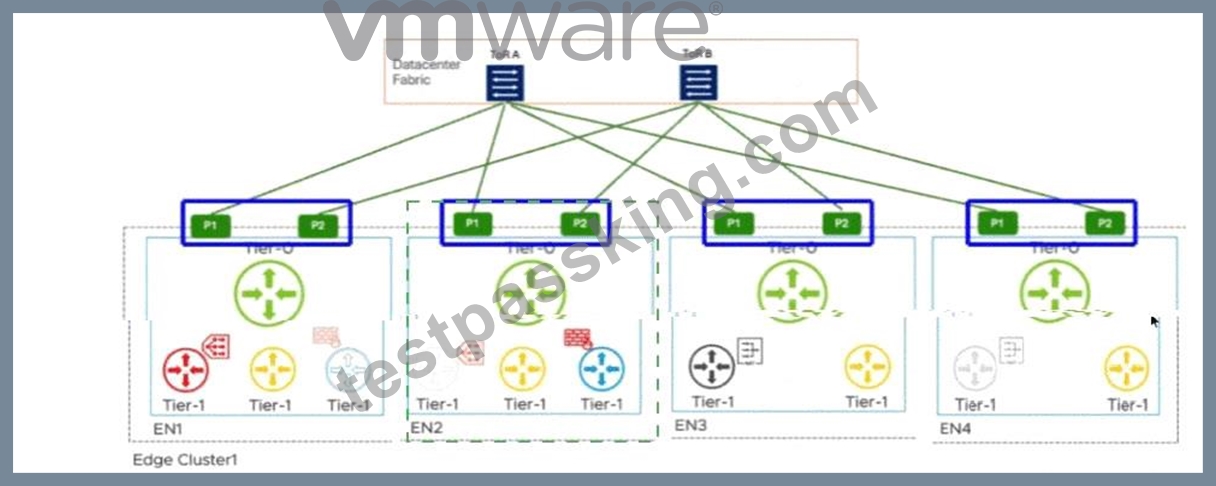
Explanation:
P1 and P2 interfaces on EN2
In aVMware Cloud Foundation (VCF)environment, the interaction between different tiers of logical gateways is governed by the placement ofService Routers (SR). When a Tier-1 Gateway is configured with stateful services, such as aGateway Firewall (GFW), it must operate inActive/Standby (A/S)mode. This ensures that session state is maintained on a single active node at any given time.
According to the provided diagram and VCF architectural guidelines, theActive Tier-1 SRis hosted onEdge Node 2 (EN2). In a multi-tier NSX design, the Tier-1 gateway is logically connected to the Tier-0 gateway via an internal transit segment (often referred to as the Router Link). While the Tier-0 gateway itself is running inActive/Active (A/A)mode across all nodes (EN1 through EN4) to provide high-bandwidth ECMP to the physical Top-of-Rack (ToR) switches, the Tier-1's path to the external world is constrained by its own current location.
Traffic originating from a workload segment attached to this Tier-1 will be processed by the GFW onEN2.
From there, the packet must exit to the physical network via the Tier-0 uplinks. Because the Tier-1 SR is localized to EN2, it will utilize the local Tier-0 instances and their corresponding physical uplinks located on that same node to avoid unnecessary inter-edge "East-West" hair-pinning over the Geneve overlay.
The highlighted optionsP1 and P2 on EN2represent the specific physical/logical uplink paths (VLAN- backed) that the Tier-1 GFW on EN2 will use to reachToR A and ToR B. Even though EN1, EN3, and EN4 also have active Tier-0 paths, the stateful nature of the Tier-1 on EN2 means its North-South traffic flow is anchored to the uplinks of its current host node. Therefore, to identify the ECMP paths actively utilized by that specific stateful Tier-1 service, the administrator must look at the uplink interfaces (P1/P2) associated with the node where that Tier-1 is active.
NEW QUESTION # 41
An administrator is tasked to configure NSX Federation between separate VMware Cloud Foundation (VCF) Fleets. Which requirement must all sites meet before being added to a Global Manager (GM) for NSX Federation?
Answer: B
NEW QUESTION # 42
An administrator encountered a failure with one of the NSX Managers in a VCF Fleet. The administrator has successfully re-deployed an NSX Manager from SFTP backups. However, after replacing the failed manager node, the new node joins successfully, but the cluster status remains "Degraded".
* The get cluster status command on the leader still shows the old UUID with state "REMOVED".
What is the command to resolve the issue?
Answer: D
Explanation:
Comprehensive and Detailed 250 to 350 words of Explanation From VMware Cloud Foundation (VCF) documents:
In aVMware Cloud Foundation (VCF)environment, the NSX Management Cluster consists of three nodes to ensure high availability and quorum. When a single node fails and is subsequently replaced-either through a manual deployment or an orchestrated recovery viaSDDC Manager-the internal database (Corfu) and the cluster manager must be updated to reflect the current members of the cluster.
When a node is lost or manually deleted from vCenter without being properly decommissioned through the NSX API or CLI, the remaining "Leader" node retains the metadata and theUUIDof that missing member.
Even after a new node joins the cluster and synchronizes data, the cluster state often remains in a"Degraded" status because the control plane still expects a response from the original, failed UUID.
According to NSX troubleshooting and recovery guides, the specific command to purge a stale or defunct member from the cluster configuration isdetach node <UUID>. This command must be executed from the CLI of the current Cluster Leader. By running detach node <old-uuid>, the administrator instructs the cluster manager to permanently remove the record of the failed node from the management plane's membership list.
Option B and C are incorrect because "delete node" is not the primary CLI command used for cluster membership cleanup; "detach" is the specific primitive required to break the logical association. Option A would remove the healthy new node, worsening the situation. Once the stale UUID is detached, the cluster status should transition from "Degraded" to "Stable" as it no longer tries to communicate with the non- existent entity. This process is essential in VCF operations to maintain a healthy "green" status in both the NSX Manager and the SDDC Manager dashboard.
NEW QUESTION # 43
......
Exam 3V0-25.25 Book: https://www.testpassking.com/3V0-25.25-exam-testking-pass.html