
2026 Latest TorrentValid Data-Engineer-Associate PDF Dumps and Data-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1eavEMMpBt_hNq5DXeFCwwbYXHV8OraZY
It is quite clear that let the facts speak for themselves is more convincing than any word, therefore, we have prepared free demo in this website for our customers to have a taste of the Data-Engineer-Associate test torrent compiled by our company. You will understand the reason why we are so confident to say that the Data-Engineer-Associate exam torrent compiled by our company is the top-notch Data-Engineer-Associate Exam Torrent for you to prepare for the exam. Just like the old saying goes:" Facts are stronger than arguments." You can choose to download our free demo at any time as you like, you are always welcome to have a try, and we trust that our Data-Engineer-Associate exam materials will never let you down.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Security and Governance | 18% | - Encrypt data at rest and in transit - Implement access control and authentication
|
| Topic 2: Data Operations and Support | 22% | - Ensure reliability and scalability - Monitor and troubleshoot data pipelines
- Backup, restore, and disaster recovery |
| Topic 3: Data Ingestion and Transformation | 34% | - Implement data quality and validation - Transform and enrich data
|
| Topic 4: Data Store Management | 26% | - Optimize storage performance and cost - Design and implement data storage solutions
|
>> Test Amazon Data-Engineer-Associate Questions Fee <<
The remarkably distinguished results Data-Engineer-Associate are enough to provide a reason for TorrentValid's huge clientele and obviously the best proof of its outstanding products. This is the reason that professionals find our Data-Engineer-Associate exam questions and answers products worthier than exam collection's or TorrentValid's dumps. Above all, it is the assurance of passing the exam with TorrentValid 100% money back guarantee that really distinguishes our Top Data-Engineer-Associate Dumps.
NEW QUESTION # 227
A company receives .csv files that contain physical address dat
a. The data is in columns that have the following names: Door_No, Street_Name, City, and Zip_Code. The company wants to create a single column to store these values in the following format: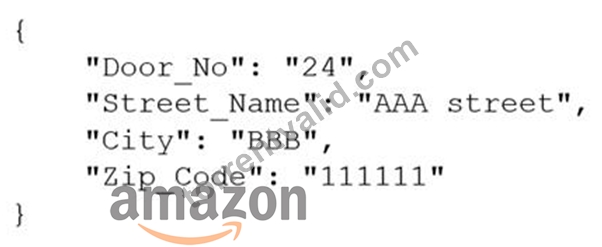
Which solution will meet this requirement with the LEAST coding effort?
Answer: A
Explanation:
The NEST TO MAP transformation allows you to combine multiple columns into a single column that contains a JSON object with key-value pairs. This is the easiest way to achieve the desired format for the physical address data, as you can simply select the columns to nest and specify the keys for each column. The NEST TO ARRAY transformation creates a single column that contains an array of values, which is not the same as the JSON object format. The PIVOT transformation reshapes the data by creating new columns from unique values in a selected column, which is not applicable for this use case. Writing a Lambda function in Python requires more coding effort than using AWS Glue DataBrew, which provides a visual and interactive interface for data transformations. Reference:
7 most common data preparation transformations in AWS Glue DataBrew (Section: Nesting and unnesting columns) NEST TO MAP - AWS Glue DataBrew (Section: Syntax)
NEW QUESTION # 228
A company is developing a product recommendation system that uses Amazon OpenSearch Service. The system needs to perform k-nearest neighbors (k-NN) vector searches on 10 million product embeddings with
768-dimensional vectors. The system must maintain high recall accuracy and support incremental updates without reindexing as new products are added each day. The system must also accommodate complex filtering based on product categories and inventory status.
Which vector index type will meet these requirements?
Answer: D
Explanation:
The correct answer is B because the scenario requires scalable approximate vector search, high recall, incremental updates, and complex filtering. Amazon OpenSearch Service supports k-NN vector search for recommendation use cases, and OpenSearch supports k-NN vector fields for high-dimensional vector search. The Lucene HNSW option is strongest here because OpenSearch documentation specifically states that Lucene supports k-NN searches using HNSW graphs and supports Lucene filters for k-NN searches. That directly matches the need for category and inventory filtering. Exact k-NN with Painless script scoring is accurate but too slow for 10 million vectors. IVF can be efficient but is less ideal for frequent incremental updates and complex filtering. Binary quantization reduces memory but sacrifices accuracy.
NEW QUESTION # 229
A manufacturing company collects sensor data from its factory floor to monitor and enhance operational efficiency. The company uses Amazon Kinesis Data Streams to publish the data that the sensors collect to a data stream. Then Amazon Kinesis Data Firehose writes the data to an Amazon S3 bucket.
The company needs to display a real-time view of operational efficiency on a large screen in the manufacturing facility.
Which solution will meet these requirements with the LOWEST latency?
Answer: C
Explanation:
This solution will meet the requirements with the lowest latency because it uses Amazon Managed Service for Apache Flink to process the sensor data in real time and write it to Amazon Timestream, a fast, scalable, and serverless time series database. Amazon Timestream is optimized for storing and analyzing time series data, such as sensor data, and can handle trillions of events per day with millisecond latency. By using AmazonTimestream as a source, you can create an Amazon QuickSight dashboard that displays a real-time view of operational efficiency on a large screen in the manufacturing facility. Amazon QuickSight is a fully managed business intelligence service that can connect to various data sources, including Amazon Timestream, and provide interactive visualizations and insights123.
The other options are not optimal for the following reasons:
A: Use Amazon Managed Service for Apache Flink (previously known as Amazon Kinesis Data Analytics) to process the sensor data. Use a connector for Apache Flink to write data to an Amazon Timestream database. Use the Timestream database as a source to create a Grafana dashboard. This option is similar to option C, but it uses Grafana instead of Amazon QuickSight to create the dashboard.
Grafana is an open source visualization tool that can also connect to Amazon Timestream, but it requires additional steps to set up and configure, such as deploying a Grafana server on Amazon EC2, installing the Amazon Timestream plugin, and creating an IAM role for Grafana to access Timestream. These steps can increase the latency and complexity of the solution.
B: Configure the S3 bucket to send a notification to an AWS Lambda function when any new object is created. Use the Lambda function to publish the data to Amazon Aurora. Use Aurora as a source to create an Amazon QuickSight dashboard. This option is not suitable for displaying a real-time view of operational efficiency, as it introduces unnecessary delays and costs in the data pipeline. First, the sensor data is written to an S3 bucket by Amazon Kinesis Data Firehose, which can have a buffering interval of up to 900 seconds. Then, the S3 bucket sends a notification to a Lambda function, which can incur additional invocation and execution time. Finally, the Lambda function publishes the data to Amazon Aurora, a relational database that is not optimized for time series data and can have higher storage and performance costs than Amazon Timestream .
D: Use AWS Glue bookmarks to read sensor data from the S3 bucket in real time. Publish the data to an Amazon Timestream database. Use the Timestream database as a source to create a Grafana dashboard.
This option is also not suitable for displaying a real-time view of operational efficiency, as it uses AWS Glue bookmarks to read sensor data from the S3 bucket. AWS Glue bookmarks are a feature that helps AWS Glue jobs and crawlers keep track of the data that has already been processed, so that they can resume from where they left off. However, AWS Glue jobs and crawlers are not designed for real-time data processing, as they can have a minimum frequency of 5 minutes and a variable start-up time.
Moreover, this option also uses Grafana instead of Amazon QuickSight to create the dashboard, which can increase the latency and complexity of the solution .
References:
1: Amazon Managed Streaming for Apache Flink
2: Amazon Timestream
3: Amazon QuickSight
4: Analyze data in Amazon Timestream using Grafana
5: Amazon Kinesis Data Firehose
6: Amazon Aurora
7: AWS Glue Bookmarks
8: AWS Glue Job and Crawler Scheduling
NEW QUESTION # 230
A data engineer needs to use AWS Step Functions to design an orchestration workflow. The workflow must parallel process a large collection of data files and apply a specific transformation to each file.
Which Step Functions state should the data engineer use to meet these requirements?
Answer: A
Explanation:
Option C is the correct answer because the Map state is designed to process a collection of data in parallel by applying the same transformation to each element. The Map state can invoke a nested workflow for each element, which can be another state machine or a Lambda function. The Map state will wait until all the parallel executions are completed before moving to the next state.
Option A is incorrect because the Parallel state is used to execute multiple branches of logic concurrently, not to process a collection of data. The Parallel state can have different branches with different logic and states, whereas the Map state has only one branch that is applied to each element of the collection.
Option B is incorrect because the Choice state is used to make decisions based on a comparison of a value to a set of rules. The Choice state does not process any data or invoke any nested workflows.
Option D is incorrect because the Wait state is used to delay the state machine from continuing for a specified time. The Wait state does not process any data or invoke any nested workflows.
Reference:
AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide, Chapter 5: Data Orchestration, Section 5.3: AWS Step Functions, Pages 131-132 Building Batch Data Analytics Solutions on AWS, Module 5: Data Orchestration, Lesson 5.2: AWS Step Functions, Pages 9-10 AWS Documentation Overview, AWS Step Functions Developer Guide, Step Functions Concepts, State Types, Map State, Pages 1-3
NEW QUESTION # 231
A company has five offices in different AWS Regions. Each office has its own human resources (HR) department that uses a unique IAM role. The company stores employee records in a data lake that is based on Amazon S3 storage.
A data engineering team needs to limit access to the records. Each HR department should be able to access records for only employees who are within the HR department's Region.
Which combination of steps should the data engineering team take to meet this requirement with the LEAST operational overhead? (Choose two.)
Answer: D,E
Explanation:
AWS Lake Formation is a service that helps you build, secure, and manage data lakes on Amazon S3. You can use AWS Lake Formation to register the S3 path as a data lake location, and enable fine-grained access control to limit access to the records based on the HR department's Region. You can use data filters to specify which S3 prefixes or partitions each HR department can access, and grant permissions to the IAM roles of the HR departments accordingly. This solution will meet the requirement with the least operational overhead, as it simplifies the data lake management and security, and leverages the existing IAM roles of the HR departments12.
The other options are not optimal for the following reasons:
* A. Use data filters for each Region to register the S3 paths as data locations. This option is not possible, as data filters are not used to register S3 paths as data locations, but to grant permissions to access specific S3 prefixes or partitions within a data location. Moreover, this option does not specify how to limit access to the records based on the HR department's Region.
* C. Modify the IAM roles of the HR departments to add a data filter for each department's Region. This option is not possible, as data filters are not added to IAM roles, but to permissions granted by AWS Lake Formation. Moreover, this option does not specify how to register the S3 path as a data lake location, or how to enable fine-grained access control in AWS Lake Formation.
* E. Create a separate S3 bucket for each Region. Configure an IAM policy to allow S3 access. Restrict access based on Region. This option is not recommended, as it would require more operational overhead to create and manage multiple S3 buckets, and to configure and maintain IAM policies for each HR department. Moreover, this option does not leverage the benefits of AWS Lake Formation, such as data cataloging, data transformation, and data governance.
References:
* 1: AWS Lake Formation
* 2: AWS Lake Formation Permissions
* : AWS Identity and Access Management
* : Amazon S3
NEW QUESTION # 232
......
Our AWS Certified Data Engineer - Associate (DEA-C01) exam tool can support almost any electronic device, from iPod, telephone, to computer and so on. You can use Our Data-Engineer-Associate test torrent by your telephone when you are travelling far from home; I think it will be very convenient for you. You can also choose to use our Data-Engineer-Associate study materials by your computer when you are at home. You just need to download the online version of our Data-Engineer-Associate study materials, which is not limited to any electronic device and support all electronic equipment in anywhere and anytime. At the same time, the online version of our AWS Certified Data Engineer - Associate (DEA-C01) exam tool will offer you the services for working in an offline states, I believe it will help you solve the problem of no internet. If you would like to try our Data-Engineer-Associate Test Torrent, I can promise that you will improve yourself and make progress beyond your imagination.
Data-Engineer-Associate Latest Exam Tips: https://www.torrentvalid.com/Data-Engineer-Associate-valid-braindumps-torrent.html
BONUS!!! Download part of TorrentValid Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=1eavEMMpBt_hNq5DXeFCwwbYXHV8OraZY