BTW, DOWNLOAD part of Exam-Killer Databricks-Generative-AI-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1UMWi-KaMje79FGaGxGhLqbPT9u479bZg
Take advantage of the Exam-Killer's Databricks training materials to prepare for the exam, let me feel that the exam have never so easy to pass. This is someone who passed the examination said to us. With Exam-Killer Databricks Databricks-Generative-AI-Engineer-Associate Exam Certification training, you can sort out your messy thoughts, and no longer twitchy for the exam. Exam-Killer have some questions and answers provided free of charge as a trial. If I just said, you may be not believe that. But as long as you use the trial version, you will believe what I say. You will know the effect of this exam materials.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
>> Databricks Databricks-Generative-AI-Engineer-Associate New Study Plan <<
The page of our Databricks-Generative-AI-Engineer-Associate simulating materials provides demo which are sample questions. The purpose of providing demo is to let customers understand our part of the topic and what is the form of our Databricks-Generative-AI-Engineer-Associate study materials when it is opened. In our minds, these two things are that customers who care about the Databricks-Generative-AI-Engineer-Associate Exam may be concerned about most. And you can click all three formats of our Databricks-Generative-AI-Engineer-Associate exam dumps to see.
NEW QUESTION # 53
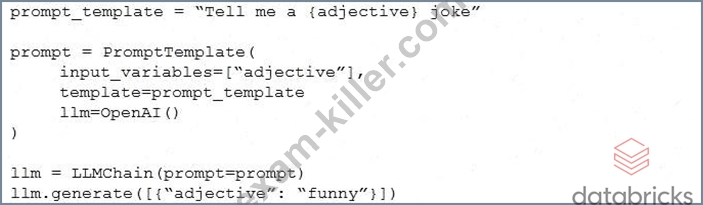
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.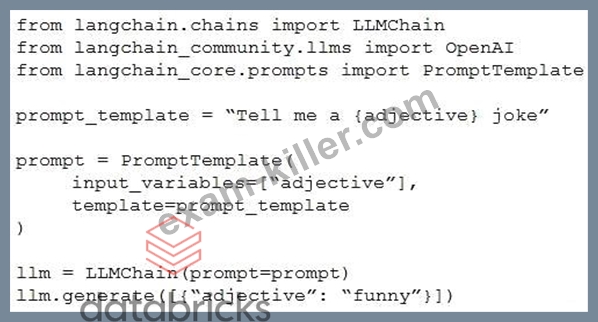
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
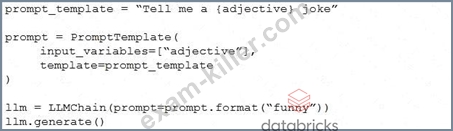
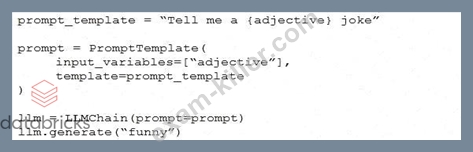
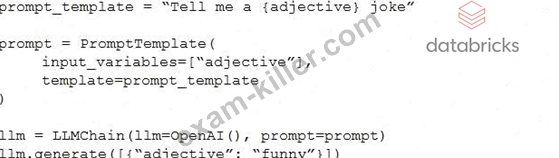
Answer: D
Explanation:
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here ' s a detailed breakdown of why Option C is the right choice and how it addresses the issue:
* Proper Initialization : In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
* Correct Use of Classes and Methods :
* The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
* The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
* The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
* Option A : Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
* Option B : Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
* Option D : Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain ' s architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
NEW QUESTION # 54
A Generative AI Engineer is building a Databricks-hosted assistant that must (1) query Unity Catalog tables with row and column permissions enforced, and (2) avoid managing any external infrastructure. The team wants the LLM to use governed data access through tools exposed via MCP.
Which MCP server choice meets these constraints?
Answer: D
Explanation:
A managed Databricks MCP server provides tools for accessing Databricks services without requiring the team to host an external server. For structured table queries, a suitable managed SQL or Genie tool uses Databricks-governed data access. Unity Catalog remains responsible for authorization instead of delegating security decisions to the language model. When permissions must reflect the individual requester, the application must use the appropriate user authorization configuration so row filters and column masks are evaluated for that identity. Passing credentials in prompts exposes secrets unnecessarily. A self-managed virtual machine violates the infrastructure requirement. Direct JDBC access also fails the requested MCP architecture and introduces custom integration work. Managed hosting simplifies deployment while preserving the platform's access-control model. Databricks tools documentation , authentication documentation
NEW QUESTION # 55
A Generative Al Engineer is building a system that will answer questions on currently unfolding news topics. As such, it pulls information from a variety of sources including articles and social media posts. They are concerned about toxic posts on social media causing toxic outputs from their system.
Which guardrail will limit toxic outputs?
Answer: A
Explanation:
The system answers questions on unfolding news topics using articles and social media, with a concern about toxic outputs from toxic inputs. A guardrail must limit toxicity in the LLM's responses. Let's evaluate the options.
Option A: Use only approved social media and news accounts to prevent unexpected toxic data from getting to the LLM Curating input sources (e.g., verified accounts) reduces exposure to toxic content at the data ingestion stage, directly limiting toxic outputs. This is a proactive guardrail aligned with data quality control.
Databricks Reference: "Control input data quality to mitigate unwanted LLM behavior, such as toxicity" ("Building LLM Applications with Databricks," 2023).
Option B: Implement rate limiting
Rate limiting controls request frequency, not content quality. It prevents overload but doesn't address toxicity in social media inputs or outputs.
Databricks Reference: Rate limiting is for performance, not safety: "Use rate limits to manage compute load" ("Generative AI Cookbook").
Option C: Reduce the amount of context items the system will include in consideration for its response Reducing context might limit exposure to some toxic items but risks losing relevant information, and it doesn't specifically target toxicity. It's an indirect, imprecise fix.
Databricks Reference: Context reduction is for efficiency, not safety: "Adjust context size based on performance needs" ("Databricks Generative AI Engineer Guide").
Option D: Log all LLM system responses and perform a batch toxicity analysis monthly Logging and analyzing responses is reactive, identifying toxicity after it occurs rather than preventing it. Monthly analysis doesn't limit real-time toxic outputs.
Databricks Reference: Monitoring is for auditing, not prevention: "Log outputs for post-hoc analysis, but use input filters for safety" ("Building LLM-Powered Applications").
Conclusion: Option A is the most effective guardrail, proactively filtering toxic inputs from unverified sources, which aligns with Databricks' emphasis on data quality as a primary safety mechanism for LLM systems.
NEW QUESTION # 56
A Generative AI Engineer has been asked to design an LLM-based application that accomplishes the following business objective: answer employee HR questions using HR PDF documentation.
Which set of high level tasks should the Generative AI Engineer's system perform?
Answer: A
Explanation:
To design an LLM-based application that can answer employee HR questions using HR PDF documentation, the most effective approach is option D. Here's why:
* Chunking and Vector Store Embedding:HR documentation tends to be lengthy, so splitting it into smaller, manageable chunks helps optimize retrieval. These chunks are then embedded into avector store(a database that stores vector representations of text). Each chunk of text is transformed into an embeddingusing a transformer-based model, which allows for efficient similarity-based retrieval.
* Using Vector Search for Retrieval:When an employee asks a question, the system converts their query into an embedding as well. This embedding is then compared with the embeddings of the document chunks in the vector store. The most semantically similar chunks are retrieved, which ensures that the answer is based on the most relevant parts of the documentation.
* LLM to Generate a Response:Once the relevant chunks are retrieved, these chunks are passed into the LLM, which uses them as context to generate a coherent and accurate response to the employee's question.
* Why Other Options Are Less Suitable:
* A (Calculate Averaged Embeddings): Averaging embeddings might dilute important information. It doesn't provide enough granularity to focus on specific sections of documents.
* B (Summarize HR Documentation): Summarization loses the detail necessary for HR-related queries, which are often specific. It would likely miss the mark for more detailed inquiries.
* C (Interaction Matrix and ALS): This approach is better suited for recommendation systems and not for HR queries, as it's focused on collaborative filtering rather than text-based retrieval.
Thus, option D is the most effective solution for providing precise and contextual answers based on HR documentation.
NEW QUESTION # 57
A company has a typical RAG-enabled, customer-facing chatbot on its website.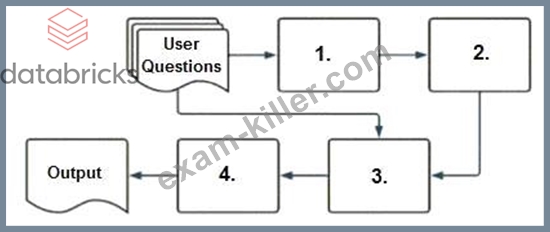
Select the correct sequence of components a user's questions will go through before the final output is returned. Use the diagram above for reference.
Answer: A
Explanation:
To understand how a typical RAG-enabled customer-facing chatbot processes a user's question, let's go through the correct sequence as depicted in the diagram and explained in option A:
* Embedding Model (1):The first step involves the user's question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
* Vector Search (2):The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
* Context-Augmented Prompt (3):The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
* Response-Generating LLM (4):Finally, the context-augmented prompt is fed into a response- generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable:
* B, C, D: These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence isembedding model, vector search, context-augmented prompt, response- generating LLM, which is option A.
NEW QUESTION # 58
......
The Desktop Databricks Databricks-Generative-AI-Engineer-Associate Practice Exam Software contains real Databricks Databricks-Generative-AI-Engineer-Associate exam questions. This provides you with a realistic experience of being in an Databricks Databricks-Generative-AI-Engineer-Associate examination setting. This feature assists you in becoming familiar with the layout of the Databricks Databricks-Generative-AI-Engineer-Associate test and enhances your ability to do well on Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) examination.
Training Databricks-Generative-AI-Engineer-Associate Materials: https://www.exam-killer.com/Databricks-Generative-AI-Engineer-Associate-valid-questions.html
P.S. Free 2026 Databricks Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by Exam-Killer: https://drive.google.com/open?id=1UMWi-KaMje79FGaGxGhLqbPT9u479bZg