BTW, DOWNLOAD part of DumpsFree DY0-001 dumps from Cloud Storage: https://drive.google.com/open?id=1sul5WaUU7NQMcQmU0yyDAuXGJgxU8vAN
A free demo of any CompTIA DY0-001 exam dumps format will be provided by DumpsFree to the one who wants to assess before purchasing. The desktop Customer Experience DY0-001 Practice Exam software is compatible with windows based computers. There is a 24/7 customer support team of DumpsFree always to fix any problems.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
>> Downloadable DY0-001 PDF <<
This is your right to have money-back guarantee, namely once but a full refund with the transcript. Some people worry about the complex refund of our DY0-001 exam practice, as a matter of fact, our refunding procedures are very simple. We will immediately refund if the buyer provide failure test proof just like failure score scan or screenshots. If you have any questions about our DY0-001 Preparation quiz, please contact us by online service or email, we will reply as soon as possible.
NEW QUESTION # 65
A data scientist is clustering a data set but does not want to specify the number of clusters present. Which of the following algorithms should the data scientist use?
Answer: A
Explanation:
# DBSCAN (Density-Based Spatial Clustering of Applications with Noise) is a density-based clustering algorithm that does not require specifying the number of clusters in advance. It identifies clusters of arbitrary shape and separates noise/outliers based on density thresholds.
Why other options are incorrect:
* B: k-NN is a supervised classification algorithm, not used for clustering.
* C: k-means requires predefining the number of clusters (k).
* D: Logistic regression is a classification model, not for clustering.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 4.2:"DBSCAN detects clusters based on data density without the need for a predefined k value and handles outliers effectively."
-
NEW QUESTION # 66
Which of the following compute delivery models allows packaging of only critical dependencies while developing a reusable asset?
Answer: D
Explanation:
# Containers (e.g., Docker) allow developers to package an application along with only the necessary runtime, libraries, and critical dependencies. This makes the asset lightweight, reusable, and portable across environments. Unlike virtual machines, containers share the host OS kernel and are far more efficient in packaging only what's essential.
Why the other options are incorrect:
* A: Thin clients refer to client-server models with minimal local processing - not relevant to dependency packaging.
* C: Virtual machines include an entire OS, leading to more overhead than necessary for reusable assets.
* D: Edge devices are hardware-based deployments typically used in IoT scenarios, not packaging tools.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 5.2:"Containers enable consistent development environments by packaging applications and only critical dependencies, making them ideal for portability and reuse."
* Docker Documentation:"Containers package code and dependencies into a single unit of software, ensuring consistency across environments while minimizing overhead."
-
NEW QUESTION # 67
The term "greedy algorithms" refers to machine-learning algorithms that:
Answer: C
Explanation:
# Greedy algorithms make decisions based on what appears to be the best (most optimal) choice at that current moment - i.e., a locally optimal decision - without regard to whether this choice will yield the globally optimal solution.
Examples in machine learning:
* Decision Tree algorithms (e.g., CART) use greedy approaches by selecting the best split at each node based on information gain or Gini index.
Why the other options are incorrect:
* A: This refers to Bayesian updating, not greedy behavior.
* B: That describes exhaustive search, not greediness.
* C: That aligns more with probabilistic or generative models, not greedy strategies.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 4.2 (Model Selection Methods):"Greedy algorithms make locally optimal decisions at each step. Decision trees, for instance, use greedy splitting based on current best criteria."
* Elements of Statistical Learning, Chapter 9:"Greedy methods make stepwise decisions that maximize immediate gains - they are fast, but may miss the global optimum."
-
NEW QUESTION # 68
A data scientist is developing a model to predict the outcome of a vote for a national mascot. The choice is between tigers and lions. The full data set represents feedback from individuals representing 17 professions and 12 different locations. The following rank aggregation represents 80% of the data set: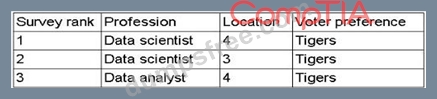
(Screenshot shows survey rankings for just two professions and a few locations, all voting for "Tigers") Which of the following is the most likely concern about the model's ability to predict the outcome of the vote?
Answer: C
Explanation:
# Extrapolated data refers to making predictions about data points that fall outside the observed range or distribution. Since the sample data (80%) is heavily skewed toward a small subset of professions and locations, predicting results for the remaining, unrepresented professions and regions involves extrapolation.
Why the other options are incorrect:
* A: Interpolation occurs within the bounds of observed data - not the issue here.
* C: In-sample data refers to training data, which is overrepresented in this case.
* D: Out-of-sample data is a concern in generalization but extrapolation is more specific here.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.2:"Extrapolation introduces risk when models are used outside the range of data they were trained on, especially if certain subgroups are underrepresented."
-
NEW QUESTION # 69
A company created a very popular collectible card set. Collectors attempt to collect the entire set, but the availability of each card varies, because some cards have higher production volumes than others. The set contains a total of 12 cards. The attributes of the cards are shown.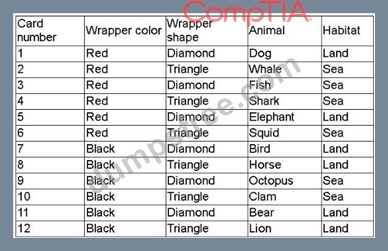
The data scientist is tasked with designing an initial model iteration to predict whether the animal on the card lives in the sea or on land, given the card's features: Wrapper color, Wrapper shape, and Animal.
Which of the following is the best way to accomplish this task?
Answer: D
Explanation:
# Decision trees are supervised classification models that can be used to predict a categorical target variable (e.
g., Habitat: Land or Sea) based on input features (e.g., Wrapper color, Wrapper shape, Animal type). They are interpretable, require minimal preprocessing, and are ideal for structured categorical data like this.
Why the other options are incorrect:
* A: ARIMA (AutoRegressive Integrated Moving Average) is used for time-series forecasting, not classification.
* B: Linear regression is used for predicting continuous numeric values, not categorical variables like
"Land" or "Sea".
* C: Association rules (like in market basket analysis) are used to discover relationships or co-occurrence among variables, not to build predictive models.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 4.1 & 4.2:"Decision trees are powerful classifiers for categorical output variables and allow for interpretable models based on feature splits."
* Machine Learning Textbook, Chapter 6:"Decision trees are ideal for early-stage model prototyping when the output is categorical and the data structure is tabular."
NEW QUESTION # 70
......
For a long time, our company is insisting on giving back to our customers on the DY0-001 study materials. Also, we have benefited from such good behavior. Our DY0-001 exam prep has gained wide popularity among candidates. Every worker in our company sticks to their jobs all the time. No one complain about the complexity of their jobs. Our researchers and experts are working hard to develop the newest version of the DY0-001 learning guide.
DY0-001 Valid Exam Topics: https://www.dumpsfree.com/DY0-001-valid-exam.html
P.S. Free & New DY0-001 dumps are available on Google Drive shared by DumpsFree: https://drive.google.com/open?id=1sul5WaUU7NQMcQmU0yyDAuXGJgxU8vAN