P.S. Testpdf在Google Drive上分享了免費的、最新的Workday-Pro-Integrations考試題庫:https://drive.google.com/open?id=1l-5KTUp-4Ki3JvWbIIOt42cFGGSNwgEd
Testpdf提供的Workday-Pro-Integrations考古題是最全面的學習資料,這是一個可以讓您高效高速的掌握知識的題庫寶典。我們提供的Workday Workday-Pro-Integrations模擬測試題及答案和真實考試的題目及答案有95%的相似性,能保證您100%通過Workday-Pro-Integrations認證考試,滿足廣大考生需求。當您真的了解我們產品的可靠性之后,您會毫不猶豫的購買它,因為Workday Workday-Pro-Integrations是您最好的選擇,甚至是您未來職業生涯成功不可缺少的。
| Section | Weight | Objectives |
|---|---|---|
| Cloud Connect & Connectors | 10–15% | - Using pre-built connectors - Configuring and managing third-party integrations |
| Workday Web Services & APIs | 15–20% | - SOAP and REST API usage - Integration with external systems - Authentication and authorization |
| Enterprise Interface Builder (EIB) | 20–25% | - Configuration, scheduling, and transformation rules - Troubleshooting and managing EIB workflows - Designing inbound and outbound integrations |
| Workday Studio | 20–25% | - Data transformation and mapping - Building advanced integrations - Debugging and deployment |
| Monitoring, Troubleshooting & Governance | 10–15% | - Logging, error handling, and monitoring tools - Integration lifecycle management - Performance optimization and best practices |
| Workday Integration Architecture & Fundamentals | 15–20% | - Core integration concepts and framework - Data exchange standards and formats - Integration system security and access control |
>> Workday-Pro-Integrations在線考題 <<
每個人都有自己的人生規劃,選擇不同得到的就不同,所以說選擇很重要。Testpdf Workday的Workday-Pro-Integrations考試認證培訓資料是幫助每個IT人士實現自己人生宏偉目標的最好的方式方法,它包括了試題及答案,並且和真實的考試題目不相上下,真的是所謂稱得上是最好的別無二選的培訓資料。
問題 #40
Refer to the following XML to answer the question below.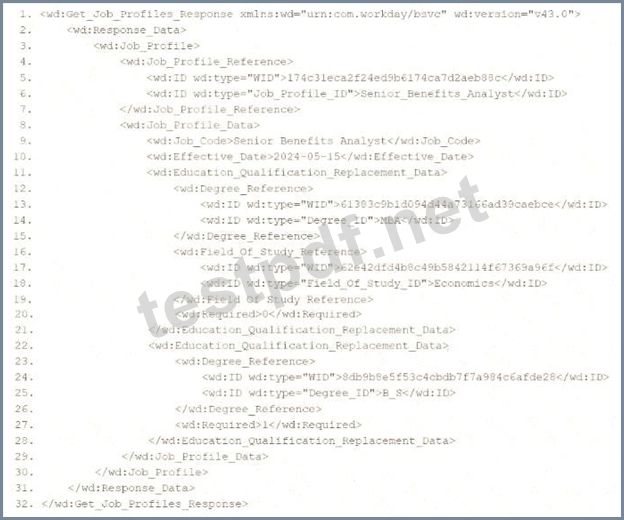
You are an integration developer and need to write XSLT to transform the output of an EIB which is making a request to the Get Job Profiles web service operation. The root template of your XSLT matches on the < wd:
Get_Job_Profiles_Response > element. This root template then applies templates against < wd:Job_Profile > .
What XPath syntax would be used to select the value of the ID element which has a wd:type attribute named Job_Profile_ID when the < xsl:value-of > element is placed within the template which matches on < wd:
Job_Profile > ?
答案:C
解題說明:
As an integration developer working with Workday, you are tasked with transforming the output of an Enterprise Interface Builder (EIB) that calls the Get_Job_Profiles web service operation. The provided XML shows the response from this operation, and you need to write XSLT to select the value of the < wd:ID > element where the wd:type attribute equals " Job_Profile_ID. " The root template of your XSLT matches on < wd:Get_Job_Profiles_Response > and applies templates to < wd:Job_Profile > . Within this template, you use the < xsl:value-of > element to extract the value. Let's analyze the XML structure, the requirement, and each option to determine the correct XPath syntax.
Understanding the XML and Requirement
The XML snippet provided is a SOAP response from the Get_Job_Profiles web service operation in Workday, using the namespace xmlns:wd= " urn:com.workday/bsvc " and version wd:version= " v43.0 " .
Key elements relevant to the question include:
* The root element is < wd:Get_Job_Profiles_Response > .
* It contains < wd:Response_Data > , which includes < wd:Job_Profile > elements.
* Within < wd:Job_Profile > , there is < wd:Job_Profile_Reference > , which contains multiple < wd:ID
> elements, each with a wd:type attribute:
* < wd:ID wd:type= " WID " > 1740d3eca2f2ed9b6174ca7d2ae88c8c < /wd:ID >
* < wd:ID wd:type= " Job_Profile_ID " > Senior_Benefits_Analyst < /wd:ID > The task is to select the value of the < wd:ID > element where wd:type= " Job_Profile_ID " (e.g., " Senior_Benefits_Analyst " ) using XPath within an XSLT template that matches < wd:Job_Profile > . The < xsl:value-of > element outputs the value of the selected node, so you need the correct XPath path from the < wd:Job_Profile > context to the specific < wd:ID > element with the wd:type attribute value " Job_Profile_ID.
"
Analysis of Options
Let's evaluate each option based on the XML structure and XPath syntax rules:
* Option A: wd:Job_Profile_Reference/wd:ID/wd:type= ' Job_Profile_ID '
* This XPath attempts to navigate from wd:Job_Profile_Reference to wd:ID, then to wd:type= ' Job_Profile_ID ' . However, there are several issues:
* wd:type= ' Job_Profile_ID ' is not valid XPath syntax. In XPath, to filter based on an attribute value, you use the attribute selector [@attribute= ' value ' ], not a direct comparison like wd:type= ' Job_Profile_ID ' .
* wd:type is an attribute of < wd:ID > , not a child element or node. This syntax would not select the < wd:ID > element itself but would be interpreted as trying to match a nonexistent child node or property, resulting in an error or no match.
* This option is incorrect because it misuses XPath syntax for attribute filtering.
* Option B: wd:Job_Profile_Reference/wd:ID/@wd:type= ' Job_Profile_ID '
* This XPath navigates to wd:Job_Profile_Reference/wd:ID and then selects the @wd:type attribute, comparing it to " Job_Profile_ID " with =@wd:type= ' Job_Profile_ID ' . However:
* The =@wd:type= ' Job_Profile_ID ' syntax is invalid in XPath. To filter based on an attribute value, you use [@wd:type= ' Job_Profile_ID ' ] as a predicate, not an equality comparison in this form.
* This XPath would select the wd:type attribute itself (e.g., the string " Job_Profile_ID " ), not the value of the < wd:ID > element. Since < xsl:value-of > expects a node or element value, selecting an attribute directly would not yield the desired " Senior_Benefits_Analyst
" value.
* This option is incorrect due to the invalid syntax and inappropriate selection of the attribute instead of the element value.
* Option C: wd:Job_Profile_Reference/wd:ID[@wd:type= ' Job_Profile_ID ' ]
* This XPath navigates from wd:Job_Profile_Reference to wd:ID and uses the predicate [@wd:
type= ' Job_Profile_ID ' ] to filter for < wd:ID > elements where the wd:type attribute equals " Job_Profile_ID. "
* In the XML, < wd:Job_Profile_Reference > contains:
* < wd:ID wd:type= " WID " > 1740d3eca2f2ed9b6174ca7d2ae88c8c < /wd:ID >
* < wd:ID wd:type= " Job_Profile_ID " > Senior_Benefits_Analyst < /wd:ID >
* The predicate [@wd:type= ' Job_Profile_ID ' ] selects the second < wd:ID > element, whose value is " Senior_Benefits_Analyst. "
* Since the template matches < wd:Job_Profile > , and < wd:Job_Profile_Reference > is a direct child of < wd:Job_Profile > , this path is correct:
* < wd:Job_Profile > # < wd:Job_Profile_Reference > # < wd:ID[@wd:type= ' Job_Profile_ID ' ] > .
* When used with < xsl:value-of select= " wd:Job_Profile_Reference/wd:ID[@wd:type= ' Job_Profile_ID ' ] " / > , it outputs " Senior_Benefits_Analyst, " fulfilling the requirement.
* This option is correct because it uses proper XPath syntax for attribute-based filtering and selects the desired < wd:ID > value.
* Option D: wd:Job_Profile_Reference/wd:ID/[@wd:type= ' Job_Profile_ID ' ]
* This XPath is similar to Option C but includes an extra forward slash before the predicate: wd:ID/
[@wd:type= ' Job_Profile_ID ' ]. In XPath, predicates like [@attribute= ' value ' ] are used directly after the node name (e.g., wd:ID[@wd:type= ' Job_Profile_ID ' ]), not separated by a slash. The extra slash is syntactically incorrect and would result in an error or no match, as it implies navigating to a child node that doesn't exist.
* This option is incorrect due to the invalid syntax.
Why Option C is Correct
Option C, wd:Job_Profile_Reference/wd:ID[@wd:type= ' Job_Profile_ID ' ], is the correct XPath syntax because:
* It starts from the context node < wd:Job_Profile > (as the template matches this element) and navigates to < wd:Job_Profile_Reference/wd:ID > , using the predicate [@wd:type= ' Job_Profile_ID ' ] to filter for the < wd:ID > element with wd:type= " Job_Profile_ID " .
* It correctly selects the value " Senior_Benefits_Analyst, " which is the content of the < wd:ID > element where wd:type= " Job_Profile_ID " .
* It uses standard XPath syntax for attribute-based filtering, aligning with Workday's XSLT implementation for web service responses.
* When used with < xsl:value-of > , it outputs the required value, fulfilling the question's requirement.
Practical Example in XSLT
Here's how this might look in your XSLT:
< xsl:template match= " wd:Job_Profile " >
< xsl:value-of select= " wd:Job_Profile_Reference/wd:ID[@wd:type= ' Job_Profile_ID ' ] " / >
< /xsl:template >
This would output " Senior_Benefits_Analyst " for the < wd:ID > element with wd:type= " Job_Profile_ID " in the XML.
Verification with Workday Documentation
The Workday Pro Integrations Study Guide and SOAP API Reference (available via Workday Community) detail the structure of the Get_Job_Profiles response and how to use XPath in XSLT for transformations. The XML structure shows < wd:Job_Profile_Reference > containing < wd:ID > elements with wd:type attributes, and the guide emphasizes using predicates like [@wd:type= ' value ' ] to filter based on attributes. This is a standard practice for navigating Workday web service responses.
Workday Pro Integrations Study Guide References
* Section: XSLT Transformations in EIBs - Describes using XSLT to transform web service responses, including selecting elements with XPath and attribute predicates.
* Section: Workday Web Services - Details the Get_Job_Profiles operation and its XML output structure, including < wd:Job_Profile_Reference > and < wd:ID > with wd:type attributes.
* Section: XPath Syntax - Explains how to use predicates like [@wd:type= ' Job_Profile_ID ' ] for attribute-based filtering in Workday XSLT.
* Workday Community SOAP API Reference - Provides examples of XPath navigation for Workday web service responses, including attribute selection.
Option C is the verified answer, as it correctly selects the < wd:ID > value with wd:type= " Job_Profile_ID " using the appropriate XPath syntax within the < wd:Job_Profile > template context.
問題 #41
How do you initially upload the XSLT file to a Document Transformation integration system?
答案:A
解題說明:
To upload an XSLT file to a Document Transformation integration system, you use the Configure Integration Attachment Service.
As per Workday documentation:
"The Configure Integration Attachment Service option on the Related Actions menu allows you to attach and manage XSLT files or other transformation documents used in Document Transformation integrations." This is the initial and correct method to upload the XSLT used for transforming incoming or outgoing XML.
Why the others are incorrect:
B . Configure Integration Attributes configures integration behavior, not attachments.
C and D reference invalid or misnamed tasks; they are not valid Workday tasks for XSLT upload.
問題 #42
What are the two valid data source options for an Outbound EIB?
答案:B
問題 #43
Refer to the following XML to answer the question below.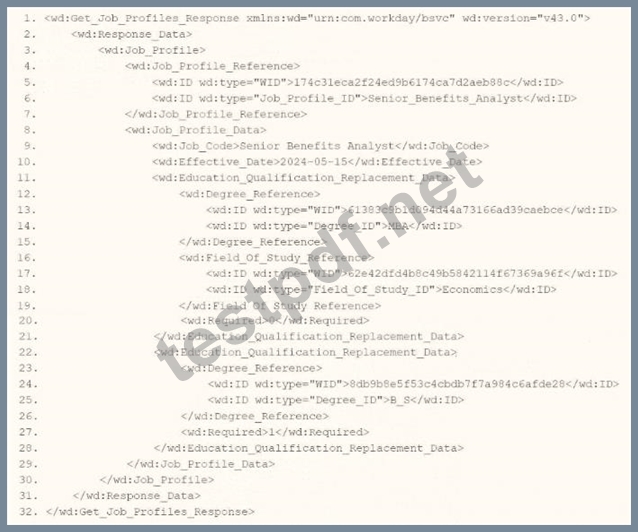
You are an integration developer and need to write XSLT to transform the output of an EIB which is making a request to the Get Job Profiles web service operation. The root template of your XSLT matches on the <wd:Get_Job_Profiles_Response> element. This root template then applies templates against <wd:Job_Profile>. What XPath syntax would be used to select the value of the ID element which has a wd:type attribute named Job_Profile_ID when the <xsl:value-of> element is placed within the template which matches on <wd:Job_Profile>?
答案:B
解題說明:
As an integration developer working with Workday, you are tasked with transforming the output of an Enterprise Interface Builder (EIB) that calls the Get_Job_Profiles web service operation. The provided XML shows the response from this operation, and you need to write XSLT to select the value of the <wd:ID> element where the wd:type attribute equals "Job_Profile_ID." The root template of your XSLT matches on <wd:Get_Job_Profiles_Response> and applies templates to <wd:Job_Profile>. Within this template, you use the <xsl:value-of> element to extract the value. Let's analyze the XML structure, the requirement, and each option to determine the correct XPath syntax.
Understanding the XML and Requirement
The XML snippet provided is a SOAP response from the Get_Job_Profiles web service operation in Workday, using the namespace xmlns:wd="urn:com.workday/bsvc" and version wd:version="v43.0". Key elements relevant to the question include:
The root element is <wd:Get_Job_Profiles_Response>.
It contains <wd:Response_Data>, which includes <wd:Job_Profile> elements.
Within <wd:Job_Profile>, there is <wd:Job_Profile_Reference>, which contains multiple <wd:ID> elements, each with a wd:type attribute:
<wd:ID wd:type="WID">1740d3eca2f2ed9b6174ca7d2ae88c8c</wd:ID>
<wd:ID wd:type="Job_Profile_ID">Senior_Benefits_Analyst</wd:ID>
The task is to select the value of the <wd:ID> element where wd:type="Job_Profile_ID" (e.g., "Senior_Benefits_Analyst") using XPath within an XSLT template that matches <wd:Job_Profile>. The <xsl:value-of> element outputs the value of the selected node, so you need the correct XPath path from the <wd:Job_Profile> context to the specific <wd:ID> element with the wd:type attribute value "Job_Profile_ID." Analysis of Options Let's evaluate each option based on the XML structure and XPath syntax rules:
Option A: wd:Job_Profile_Reference/wd:ID/wd:type='Job_Profile_ID'
This XPath attempts to navigate from wd:Job_Profile_Reference to wd:ID, then to wd:type='Job_Profile_ID'. However, there are several issues:
wd:type='Job_Profile_ID' is not valid XPath syntax. In XPath, to filter based on an attribute value, you use the attribute selector [@attribute='value'], not a direct comparison like wd:type='Job_Profile_ID'.
wd:type is an attribute of <wd:ID>, not a child element or node. This syntax would not select the <wd:ID> element itself but would be interpreted as trying to match a nonexistent child node or property, resulting in an error or no match.
This option is incorrect because it misuses XPath syntax for attribute filtering.
Option B: wd:Job_Profile_Reference/wd:ID/@wd:type='Job_Profile_ID'
This XPath navigates to wd:Job_Profile_Reference/wd:ID and then selects the @wd:type attribute, comparing it to "Job_Profile_ID" with =@wd:type='Job_Profile_ID'. However:
The =@wd:type='Job_Profile_ID' syntax is invalid in XPath. To filter based on an attribute value, you use [@wd:type='Job_Profile_ID'] as a predicate, not an equality comparison in this form.
This XPath would select the wd:type attribute itself (e.g., the string "Job_Profile_ID"), not the value of the <wd:ID> element. Since <xsl:value-of> expects a node or element value, selecting an attribute directly would not yield the desired "Senior_Benefits_Analyst" value.
This option is incorrect due to the invalid syntax and inappropriate selection of the attribute instead of the element value.
Option C: wd:Job_Profile_Reference/wd:ID[@wd:type='Job_Profile_ID']
This XPath navigates from wd:Job_Profile_Reference to wd:ID and uses the predicate [@wd:type='Job_Profile_ID'] to filter for <wd:ID> elements where the wd:type attribute equals "Job_Profile_ID." In the XML, <wd:Job_Profile_Reference> contains:
<wd:ID wd:type="WID">1740d3eca2f2ed9b6174ca7d2ae88c8c</wd:ID>
<wd:ID wd:type="Job_Profile_ID">Senior_Benefits_Analyst</wd:ID>
The predicate [@wd:type='Job_Profile_ID'] selects the second <wd:ID> element, whose value is "Senior_Benefits_Analyst." Since the template matches <wd:Job_Profile>, and <wd:Job_Profile_Reference> is a direct child of <wd:Job_Profile>, this path is correct:
<wd:Job_Profile> → <wd:Job_Profile_Reference> → <wd:ID[@wd:type='Job_Profile_ID']>.
When used with <xsl:value-of select="wd:Job_Profile_Reference/wd:ID[@wd:type='Job_Profile_ID']"/>, it outputs "Senior_Benefits_Analyst," fulfilling the requirement.
This option is correct because it uses proper XPath syntax for attribute-based filtering and selects the desired <wd:ID> value.
Option D: wd:Job_Profile_Reference/wd:ID/[@wd:type='Job_Profile_ID']
This XPath is similar to Option C but includes an extra forward slash before the predicate: wd:ID/[@wd:type='Job_Profile_ID']. In XPath, predicates like [@attribute='value'] are used directly after the node name (e.g., wd:ID[@wd:type='Job_Profile_ID']), not separated by a slash. The extra slash is syntactically incorrect and would result in an error or no match, as it implies navigating to a child node that doesn't exist.
This option is incorrect due to the invalid syntax.
Why Option C is Correct
Option C, wd:Job_Profile_Reference/wd:ID[@wd:type='Job_Profile_ID'], is the correct XPath syntax because:
It starts from the context node <wd:Job_Profile> (as the template matches this element) and navigates to <wd:Job_Profile_Reference/wd:ID>, using the predicate [@wd:type='Job_Profile_ID'] to filter for the <wd:ID> element with wd:type="Job_Profile_ID".
It correctly selects the value "Senior_Benefits_Analyst," which is the content of the <wd:ID> element where wd:type="Job_Profile_ID".
It uses standard XPath syntax for attribute-based filtering, aligning with Workday's XSLT implementation for web service responses.
When used with <xsl:value-of>, it outputs the required value, fulfilling the question's requirement.
Practical Example in XSLT
Here's how this might look in your XSLT:
<xsl:template match="wd:Job_Profile">
<xsl:value-of select="wd:Job_Profile_Reference/wd:ID[@wd:type='Job_Profile_ID']"/>
</xsl:template>
This would output "Senior_Benefits_Analyst" for the <wd:ID> element with wd:type="Job_Profile_ID" in the XML.
Verification with Workday Documentation
The Workday Pro Integrations Study Guide and SOAP API Reference (available via Workday Community) detail the structure of the Get_Job_Profiles response and how to use XPath in XSLT for transformations. The XML structure shows <wd:Job_Profile_Reference> containing <wd:ID> elements with wd:type attributes, and the guide emphasizes using predicates like [@wd:type='value'] to filter based on attributes. This is a standard practice for navigating Workday web service responses.
Workday Pro Integrations Study Guide Reference
Section: XSLT Transformations in EIBs - Describes using XSLT to transform web service responses, including selecting elements with XPath and attribute predicates.
Section: Workday Web Services - Details the Get_Job_Profiles operation and its XML output structure, including <wd:Job_Profile_Reference> and <wd:ID> with wd:type attributes.
Section: XPath Syntax - Explains how to use predicates like [@wd:type='Job_Profile_ID'] for attribute-based filtering in Workday XSLT.
Workday Community SOAP API Reference - Provides examples of XPath navigation for Workday web service responses, including attribute selection.
Option C is the verified answer, as it correctly selects the <wd:ID> value with wd:type="Job_Profile_ID" using the appropriate XPath syntax within the <wd:Job_Profile> template context.
問題 #44
What is the purpose of a namespace in the context of a stylesheet?
答案:D
解題說明:
In the context of a stylesheet, particularly within Workday ' s Document Transformation system where XSLT (Extensible Stylesheet Language Transformations) is commonly used, a namespace serves a critical role in defining the scope and identity of elements and attributes. The correct answer, as aligned with Workday's integration practices and standard XSLT principles, is that a namespace " provides elements you can use in your code. " Here's a detailed explanation:
* Definition and Purpose of a Namespace:
* A namespace in an XML-based stylesheet (like XSLT) is a mechanism to avoid naming conflicts by grouping elements and attributes under a unique identifier, typically a URI (Uniform Resource Identifier). This allows different vocabularies or schemas to coexist within the same document or transformation process without ambiguity.
* In XSLT, namespaces are declared in the stylesheet using the xmlns attribute (e.g., xmlns:xsl= "
http://www.w3.org/1999/XSL/Transform " for XSLT itself). These declarations define the set of elements and functions available for use in the stylesheet, such as < xsl:template > , < xsl:value- of > , or < xsl:for-each > .
* For example, when transforming Workday data (which uses its own XML schema), a namespace might be defined to reference Workday-specific elements, enabling the stylesheet to correctly identify and manipulate those elements.
* Application in Workday Context:
* In Workday's Document Transformation integrations, namespaces are essential when processing XML data from Workday (e.g., Core Connector outputs) or external systems. The namespace ensures that the XSLT processor recognizes the correct elements from the source XML and applies the transformation rules appropriately.
* Without a namespace, the processor might misinterpret elements with the same name but different meanings (e.g., < name > in one schema vs. another). By providing a namespace, the stylesheet gains access to a specific vocabulary of elements and attributes, enabling precise coding of transformation logic.
* Why Other Options Are Incorrect:
* B. Indicates the start and end tag names to output: This is incorrect because namespaces do not dictate the structure (start and end tags) of the output. That is determined by the XSLT template rules and output instructions (e.g., < xsl:output > or literal result elements). Namespaces only define the identity of elements, not their placement or formatting in the output.
* C. Restricts the data the processor can access: While namespaces help distinguish between different sets of elements, they do not inherently restrict data access. Restrictions are more a function of security settings or XPath expressions within the stylesheet, not the namespace itself.
* D. Controls the filename of the transformed result: Namespaces have no bearing on the filename of the output. In Workday, the filename of a transformed result is typically managed by the Integration Attachment Service or delivery settings (e.g., SFTP or email configurations), not the stylesheet's namespace.
* Practical Example:
* Suppose you're transforming a Workday XML file containing employee data into a custom format. The stylesheet might include:
< xsl:stylesheet version= " 1.0 " xmlns:xsl= " http://www.w3.org/1999/XSL/Transform " xmlns:wd= "
http://www.workday.com/ns " >
< xsl:template match= " wd:Employee " >
< EmployeeName > < xsl:value-of select= " wd:Name " / > < /EmployeeName >
< /xsl:template >
< /xsl:stylesheet >
* Here, the wd namespace provides access to Workday-specific elements like < wd:Employee > and < wd:Name > , which the XSLT processor can then use to extract and transform data.
Workday Pro Integrations Study Guide References:
* Workday Integration System Fundamentals: Explains XML and XSLT basics, including the role of namespaces in identifying elements within stylesheets.
* Document Transformation Module: Highlights how namespaces are used in XSLT to process Workday XML data, emphasizing their role in providing a vocabulary for transformation logic (e.g., " Understanding XSLT Namespaces " ).
* Core Connectors and Document Transformation Course Manual: Includes examples of XSLT stylesheets where namespaces are declared to handle Workday-specific schemas, reinforcing that they provide usable elements.
* Workday Community Documentation: Notes that namespaces are critical for ensuring compatibility between Workday's XML output and external system requirements in transformation scenarios.
問題 #45
......
你可以先在網上免費下載Testpdf為你提供的部分Workday Workday-Pro-Integrations認證考試的練習題和答案,一旦你決定了選擇了Testpdf,Testpdf會盡全力幫你通過考試。如果你發現我們提供的考試練習題和答案與實際考試練習題和答案有差別,不能使你通過考試,我們會立刻100%全額退款。
Workday-Pro-Integrations考證: https://www.testpdf.net/Workday-Pro-Integrations.html
此外,這些Testpdf Workday-Pro-Integrations考試題庫的部分內容現在是免費的:https://drive.google.com/open?id=1l-5KTUp-4Ki3JvWbIIOt42cFGGSNwgEd