DP-420 Unterlagen mit echte Prüfungsfragen der Microsoft Zertifizierung

Laden Sie die neuesten PrüfungFrage DP-420 PDF-Versionen von Prüfungsfragen kostenlos von Google Drive herunter: https://drive.google.com/open?id=1lO5rCOtPwl5lroqkJ4b4ozEFq80COlOT
Viele IT-Fachleute traümt von dem Microsoft DP-420 Zertifikat. Die Microsoft DP-420 Zertifizierungsprüfung ist eine Prüfung, die IT-Fachkenntnisse und Erfahrungen eines Menschen testet. Um die Prüfung zu bestehen braucht man genügende Fachkenntnisse. Um diese Kenntnisse zu meistern muss man viel Zeit und Energie kosten. PrüfungFrage ist eine Website, die Ihnen viel Zeit und Energie erspart und die relevanten Kenntnisse zur Microsoft DP-420 Zertifizierungsprüfung ergänzt. Wenn Sie Interesse an PrüfungFrage haben, können Sie im Internet teilweise die Fragen und Antworten zur Microsoft DP-420 Zertifizierungsprüfung von PrüfungFrage kostenlos als Probe herunterladen.
Microsoft DP-420 Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Design and implement data distribution | 5-10% | - Design and implement multi-region writes
- 1. Implement multi-region writes
- 2. Choose when to use multi-region writes
- 3. Implement conflict resolution policies
- Design and implement replication strategy
- 1. Choose a consistency model
- 2. Define automatic failover policies
- 3. Perform manual failovers
- 4. Choose when to distribute data
- 5. Evaluate consistency model impacts
|
| Topic 2: Maintain an Azure Cosmos DB solution | 25-30% | - Monitor and troubleshoot Azure Cosmos DB solutions
- 1. Monitor performance and availability
- 2. Implement backup and recovery strategies
- 3. Troubleshoot throughput issues
- 4. Monitor metrics and logs
|
| Topic 3: Optimize an Azure Cosmos DB solution | 15-20% | - Design and implement change feeds
- 1. Manage change feed instances
- 2. Develop Azure Functions triggers
- 3. Implement aggregation persistence
- 4. Consume change feeds using SDK
- Optimize query performance
- 1. Calculate query cost
- 2. Implement integrated cache
- 3. Adjust indexing policies
- 4. Retrieve request unit cost
- Define and implement indexing strategy
- 1. Choose read-heavy or write-heavy indexing
- 2. Optimize index performance
- 3. Choose appropriate index types
- 4. Implement composite indexes
- 5. Configure custom indexing policies
|
| Topic 4: Integrate an Azure Cosmos DB solution | 5-10% | - Implement solutions across services
- 1. Implement Azure AI Search integration
- 2. Aggregate and archive data
- 3. Integrate Azure Functions and Event Hubs
- 4. Enforce referential integrity
- 5. Use Change Feed for denormalization
- Enable analytical workloads
- 1. Configure Azure Cosmos DB Mirroring
- 2. Write data back from Spark
- 3. Enable analytical store
- 4. Query analytical store from Synapse
|
| Topic 5: Design and implement data models | 35-40% | - Implement server-side programming
- 1. Implement triggers
- 2. Implement user-defined functions
- 3. Write and deploy stored procedures
- Plan and implement sizing and scaling
- 1. Evaluate global distribution costs
- 2. Evaluate throughput and storage requirements
- 3. Configure throughput
- 4. Design resource governance and scaling
- 5. Choose between serverless, provisioned, and free tier
- Design and implement a non-relational data model for Azure Cosmos DB for NoSQL
- 1. Identify data and associated access patterns
- 2. Store multiple entity types in the same container
- 3. Reference between documents
- 4. Store multiple related entities in the same document
- 5. Denormalize data across documents
- 6. Identify partition key, id, and unique keys
- Implement data access
- 1. Implement patch operations
- 2. Use consistency and query request options
- 3. Implement SQL queries with arrays and aggregation
- 4. Use SDKs for CRUD operations
- 5. Manage transactional batch operations
- 6. Implement optimistic concurrency control
- Implement client connectivity options
- 1. Configure client-side threading and logging
- 2. Create database connections
- 3. Handle connection errors
- 4. Choose gateway or direct connectivity mode
- 5. Use Azure Cosmos DB emulator
- 6. Implement singleton client
- Design a data partitioning strategy
- 1. Choose a partitioning strategy
- 2. Choose a partition key
- 3. Plan for transactions with partition keys
- 4. Implement synthetic partition keys
- 5. Evaluate cross-partition query cost
- 6. Evaluate throughput and data distribution
|
>> DP-420 Ausbildungsressourcen <<
DP-420 Fragenpool - DP-420 Fragen&Antworten
Mit der Hilfe von PrüfungFrage brauchen Sie nicht so viel Geld für die Kurse oder viel Zeit und Energie für die Prüfung auszugeben. Sie können ganz einfach die Microsoft DP-420 (Designing and Implementing Cloud-Native Applications Using Microsoft Azure Cosmos DB)Prüfung erfolgreich ablegen. Die Software zur Microsoft DP-420 Zertifizierungsprüfung wird PrüfungFrage nach den echten Prüfungen in den letzten Jahren erforscht. Die Fragen und Antworten zur Microsoft DP-420 Zertifizierungsprüfung von PrüfungFrage sind den realen Fragen und Antworten sehr ähnlich.
Microsoft Designing and Implementing Cloud-Native Applications Using Microsoft Azure Cosmos DB DP-420 Prüfungsfragen mit Lösungen (Q194-Q199):
194. Frage
You are implementing an Azure Data Factory data flow that will use an Azure Cosmos DB (SQL API) sink to write a dataset. The data flow will use 2,000 Apache Spark partitions.
You need to ensure that the ingestion from each Spark partition is balanced to optimize throughput.
Which sink setting should you configure?
- A. Throughput
- B. Batch size
- C. Write throughput budget
- D. Collection action
Antwort: B
Begründung:
Batch size: An integer that represents how many objects are being written to Cosmos DB collection in each batch. Usually, starting with the default batch size is sufficient. To further tune this value, note:
Cosmos DB limits single request's size to 2MB. The formula is "Request Size = Single Document Size * Batch Size". If you hit error saying "Request size is too large", reduce the batch size value.
The larger the batch size, the better throughput the service can achieve, while make sure you allocate enough RUs to empower your workload.
Reference: https://docs.microsoft.com/en-us/azure/data-factory/connector-azure-cosmos-db
195. Frage
You have an Azure subscription that contains an Azure Cosmos DB for NoSQL database named DB1.
You develop a software as a service (SaaS) app named App1 that uses DB1. App1 will be used by multiple vendors to manage their customers.
You need to create a container in DB1 that will store customer and order details for each vendor. The solution must meet the following requirements:
* Each vendor must have a unique tenant ID.
* The performance of the container must be optimized for reads.
* Customer IDs can be duplicated across the container but must be unique for each vendor.
* The container must be optimized for concurrent queries from multiple customers. Each query will return data for a single vendor.
How should you configure the container?
- A. Add hierarchical partition key on (customer identifier, tenant identifier).
- B. Add a partition key to the customer ID and a unique key policy to the tenant ID.
- C. Add a partition key to the tenant ID and a unique key policy to the customer ID.
- D. Add hierarchical partition key on (tenant identifier, customer identifier).
Antwort: D
196. Frage
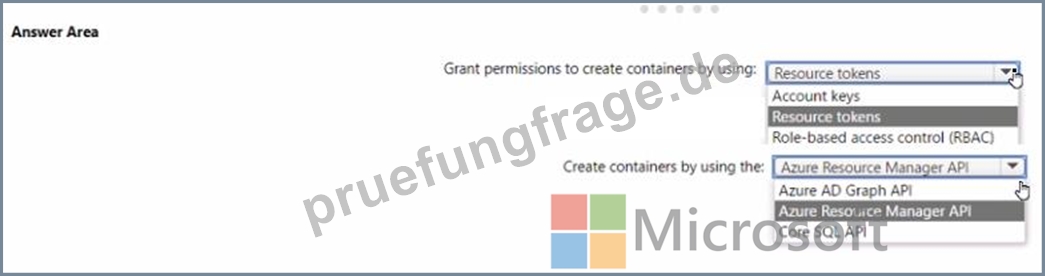
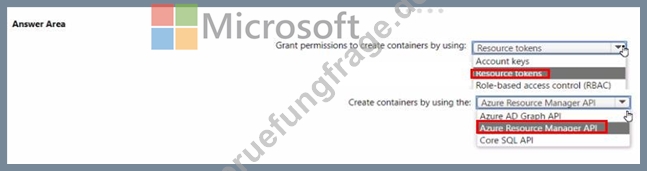
You have an Azure Cosmos DB for NoSQL account named account that has the disablekeyBasedletadatwriteAccess property enabled.
You are developing an app named App1 that will be used by a use1 named DevUser1 to create containers in account1. DevUser1 has a non-privileged user account in the Azure AD tenant.
You need to ensure that DevUser1 can use App1 to create containers in account1.
What should you do? To answer, select the appropriate options in the answer area.
NOTE Each correct selection is worth one point.
Antwort:
Begründung:
197. Frage
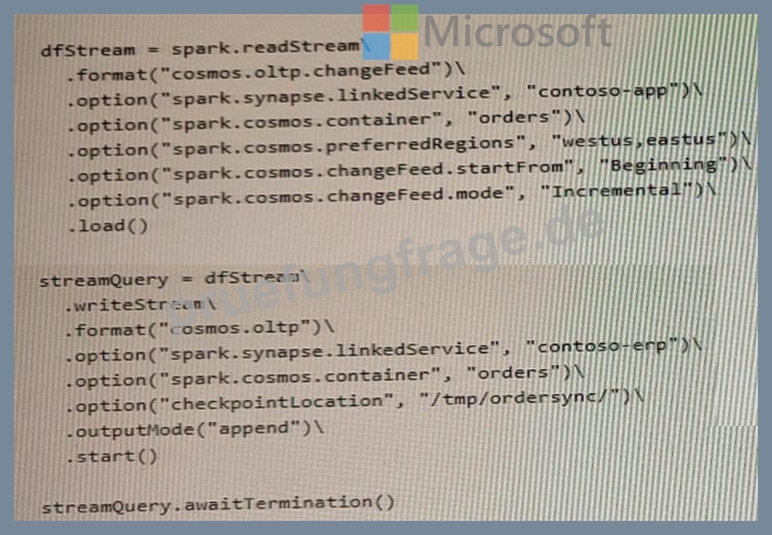
You have an Apache Spark pool in Azure Synapse Analytics that runs the following Python code in a notebook.
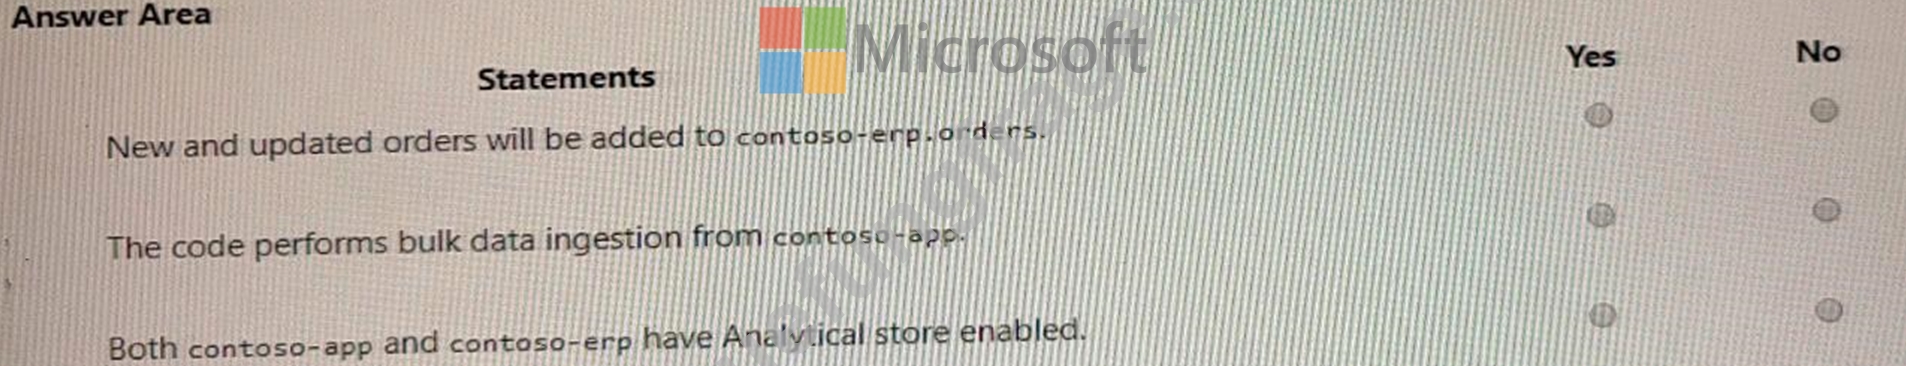
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Antwort:
Begründung:
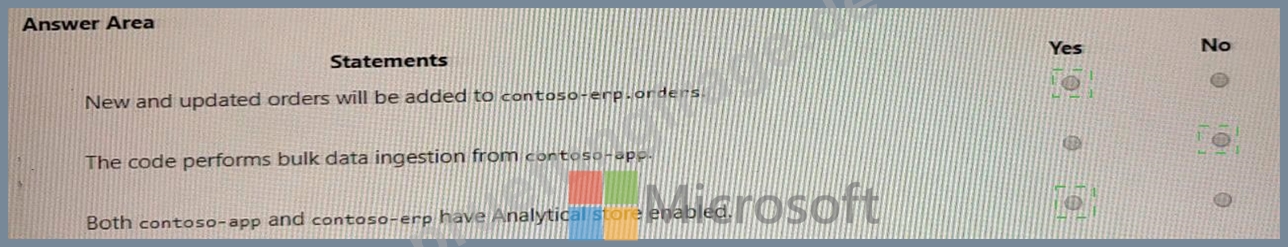
Explanation
New and updated orders will be added to contoso-erp.orders: Yes
The code performs bulk data ingestion from contoso-app: No
Both contoso-app and contoso-erp have Analytics store enabled: Yes
The code uses the spark.readStream method to read data from a container named orders in a database named contoso-app. The data is then filtered by a condition and written to another container named orders in a database named contoso-erp using the spark.writeStream method. The write mode is set to "append", which means that new and updated orders will be added to the destination container The code does not perform bulk data ingestion from contoso-app, but rather stream processing. Bulk data ingestion is a process of loading large amounts of data into a data store in batches. Stream processing is a process of continuously processing data as it arrives in real-time Both contoso-app and contoso-erp have Analytics store enabled, because they are both accessed by Spark pools using the spark.cosmos.oltp method. This method requires that the containers have Analytics store enabled, which is a feature that allows Spark pools to query data stored in Azure Cosmos DB containers using SQL APIs3.
198. Frage
You have an Azure Cosmos DB for NoSQL database that hosts a container named Contained. Contained stores product details. You have a query named Query1 that contains the following statements.
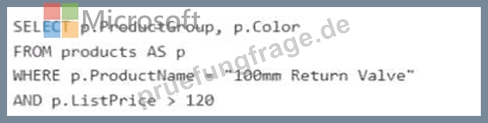
You need to optimize the performance of Query1 by using custom indexing. Which set of index components will optimize Query1?
- A. ListPrice DESC, ProductName ASC, ProductGroup ASC, Color ASC
- B. ProductName DESC, ListPrice ASC
- C. ListPrice ASC, ProductName ASC, ProductGroup ASC, Color ASC
- D. ListPrice ASC, ProductName ASC
Antwort: B
199. Frage
......
Als Anbieter des Microsoft DP-420 (Designing and Implementing Cloud-Native Applications Using Microsoft Azure Cosmos DB) IT-Prüfungskompendium bieten IT-Experten von PrüfungFrage ständig die Produkte von guter Qualität. Sie bieten den Kunden kostenlosen Online-Service rund um die Uhr und aktualisieren Microsoft DP-420 (Designing and Implementing Cloud-Native Applications Using Microsoft Azure Cosmos DB) Prüfungsfragen und Antworten auch am schnellsten.
DP-420 Fragenpool: https://www.pruefungfrage.de/DP-420-dumps-deutsch.html
- Die neuesten DP-420 echte Prüfungsfragen, Microsoft DP-420 originale fragen 🅰 URL kopieren ✔ www.echtefrage.top ️✔️ Öffnen und suchen Sie { DP-420 } Kostenloser Download 🖱DP-420 Pruefungssimulationen
- DP-420 Aktuelle Prüfung - DP-420 Prüfungsguide - DP-420 Praxisprüfung 🖐 Erhalten Sie den kostenlosen Download von ▶ DP-420 ◀ mühelos über 【 www.itzert.com 】 🤞DP-420 Testking
- DP-420 Testking 🏥 DP-420 Antworten 🗣 DP-420 Probesfragen 🔷 Suchen Sie auf der Webseite ➤ www.itzert.com ⮘ nach ▷ DP-420 ◁ und laden Sie es kostenlos herunter ⏳DP-420 Deutsche Prüfungsfragen
- Die neuesten DP-420 echte Prüfungsfragen, Microsoft DP-420 originale fragen 🛬 Suchen Sie auf ➠ www.itzert.com 🠰 nach ➤ DP-420 ⮘ und erhalten Sie den kostenlosen Download mühelos 👘DP-420 Online Tests
- Die seit kurzem aktuellsten Microsoft DP-420 Prüfungsunterlagen, 100% Garantie für Ihen Erfolg in der Prüfungen! 🚻 Suchen Sie einfach auf ➠ www.zertpruefung.de 🠰 nach kostenloser Download von 《 DP-420 》 😭DP-420 Deutsche Prüfungsfragen
- DP-420 Online Test 👒 DP-420 Antworten 🔯 DP-420 Demotesten 🍄 Öffnen Sie die Webseite ▷ www.itzert.com ◁ und suchen Sie nach kostenloser Download von ⏩ DP-420 ⏪ 🚠DP-420 Online Tests
- DP-420 Unterlage 🏣 DP-420 Prüfungs 🍞 DP-420 Lernhilfe 💿 Suchen Sie einfach auf ▷ www.zertpruefung.ch ◁ nach kostenloser Download von ➠ DP-420 🠰 🦢DP-420 Prüfungen
- Die seit kurzem aktuellsten Microsoft DP-420 Prüfungsunterlagen, 100% Garantie für Ihen Erfolg in der Prüfungen! 💂 Suchen Sie auf [ www.itzert.com ] nach ➡ DP-420 ️⬅️ und erhalten Sie den kostenlosen Download mühelos 🌄DP-420 Lernhilfe
- DP-420 Deutsche Prüfungsfragen 🚰 DP-420 Pruefungssimulationen 🤹 DP-420 Pruefungssimulationen 🌱 ☀ www.deutschpruefung.com ️☀️ ist die beste Webseite um den kostenlosen Download von ➽ DP-420 🢪 zu erhalten ☝DP-420 Online Test
- DP-420 Testfagen 🌼 DP-420 Deutsche Prüfungsfragen 💧 DP-420 Online Test 🚖 Suchen Sie auf der Webseite ☀ www.itzert.com ️☀️ nach ▷ DP-420 ◁ und laden Sie es kostenlos herunter 🚢DP-420 Lernhilfe
- DP-420 neuester Studienführer - DP-420 Training Torrent prep 🔺 Erhalten Sie den kostenlosen Download von ➠ DP-420 🠰 mühelos über 「 www.deutschpruefung.com 」 🐇DP-420 Quizfragen Und Antworten
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, vrcmods.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myspace.com, www.stes.tyc.edu.tw, p.me-page.com, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Kostenlose und neue DP-420 Prüfungsfragen sind auf Google Drive freigegeben von PrüfungFrage verfügbar: https://drive.google.com/open?id=1lO5rCOtPwl5lroqkJ4b4ozEFq80COlOT