The competition in IT industry is increasingly intense, so how to prove that you are indispensable talent? To pass the AI-500 certification exam is persuasive. What we can do for you is to let you faster and more easily pass the AI-500 Exam. Our Exam4Tests have owned more resources and experiences after development for years. Constant improvement of the software also can let you enjoy more efficient review process of AI-500 exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
| Topic 2: Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement guardrails
|
| Topic 3: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Implement observability and monitoring
|
| Topic 4: Develop multi-agent solutions in Azure | 30-35% | - Design and implement advanced prompt engineering strategies
|
>> Reliable AI-500 Exam Sample <<
We believe that the best brands are those that go beyond expectations. They don't just do the job – they go deeper and become the fabric of our lives. Therefore, as the famous brand, even though we have been very successful we have never satisfied with the status quo, and always be willing to constantly update the contents of our AI-500 exam torrent. Most important of all, as long as we have compiled a new version of the AI-500 Guide Torrent, we will send the latest version of our AI-500 training materials to our customers for free during the whole year after purchasing. We will continue to bring you integrated AI-500 guide torrent to the demanding of the ever-renewing exam, which will be of great significance for you to keep pace with the times.
NEW QUESTION # 24
You have a Microsoft Foundry Agent Service solution that includes two agents You need to configure memory for the agents. The solution must meet the following requirements:
* Isolate the memory between end users
* Isolate the memory between the agent domains.
* Support the deletion of one user ' s memory without deleting other users ' memory.
Solution: You create one memory store per end user and configure both agents to use each user ' s memory store with a static scope value.
Does this meet the goal?
Answer: B
Explanation:
Creating one memory store for each end user separates users, but allowing both agents to use that user ' s store with the same static scope does not isolate the two agent domains. Memories produced by one agent can occupy the same logical collection as memories produced by the other agent. Microsoft Foundry Memory uses the `scope` parameter to partition a store, so a design that needs both user and domain isolation must preserve both dimensions, commonly through separate agent stores plus per-user scope. The per-user deletion requirement can also be handled more efficiently by deleting a user ' s scope rather than operating a separate store for every user. Because the proposed design fails agent-domain separation, it does not meet all requirements. Therefore B, No, is correct. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Create and use memory in Foundry Agent Service
NEW QUESTION # 25
You are designing a Microsoft Foundry multi-agent solution for claims processing. The design includes multiple specialized agents.
You need to specify the agent personas. scopes, boundaries, and autonomy levels. The solution must meet the following requirements:
* Provide a clear owner for conflicts between specialist agents.
* Validate agent outputs before downstream agents consume the outputs.
* Prevent specialist agents from invoking tools outside the assigned domain.
* Isolate each business domain so that adding a specialist agent affects only that domain.
What should you do?
Answer: D
Explanation:
Domain-scoped sub-orchestrators under a claims supervisor provide the clearest ownership and isolation model. Each domain can contain its own specialists and tools, so adding a new specialist affects only that domain. The supervisor becomes the explicit authority for cross-domain conflicts. Requiring every domain output to satisfy a structured contract before it is consumed downstream provides a deterministic validation boundary instead of relying on unconstrained narrative summaries. Microsoft AI-500 architecture objectives emphasize agent scopes, tool boundaries, structured interfaces, and explicit control loops. Option B gates only the final settlement and therefore allows invalid intermediate outputs to propagate. Option D deliberately leaves conflict resolution to consuming domains, which violates the requirement for a clear owner. Option A lacks a strong validation contract. C is therefore the most robust architecture. The architecture should still be validated with representative end-to-end tests, but the selected component establishes the correct structural boundary first. Microsoft ' s AI-500 blueprint consistently favors explicit scopes, interfaces, and persistence or identity boundaries over prompt-only conventions.
Official Microsoft reference: AI-500 Study Guide - agent personas, scopes, boundaries, and workflows
NEW QUESTION # 26
You have a Microsoft Foundry Agent Sen/ice solution that includes two agents.
You need to configure memory for the agents. The solution must meet the following requirements:
* Isolate the memory between end users
* Isolate the memory between the agent domains.
* Support the deletion of one user ' s memory without deleting other users ' memory.
Solution: You create a dedicated memory store for each agent and set scope for each memory search tool to
{{Suserld}} Does this meet the goal?
Answer: A
Explanation:
A dedicated memory store for each agent establishes agent-domain isolation. Setting each memory search tool
' s scope to the current user identity establishes the second isolation dimension: users within the same agent domain receive separate logical memory collections. Microsoft Foundry Memory documents `scope` as the partitioning mechanism and specifically supports `{{$userId}}` for automatic per-user isolation. Memory associated with one scope can be deleted without removing memories stored under other scopes, which satisfies the deletion requirement. The source text renders the token imperfectly as `{{Suserld}}`; the current documented syntax is `{{$userId}}`. Interpreting the question as the documented user-scope token, the design satisfies domain isolation, user isolation, and per-user deletion. Therefore A, Yes, is correct. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex.
Official Microsoft reference: Create and use memory in Foundry Agent Service
NEW QUESTION # 27
You have a multi-agent Retrieval-Augmented Generation (RAG) solution that uses a Foundry IQ knowledge base. The solution includes a support agent and a policy agent.
You have an evaluation dataset that contains the following for each user query
* The expected source IDs
* Retrieved chunks in rank order
* The final agent response
You discover that an embedding model change and a custom analyzer change cause the failed traces shown in the following table.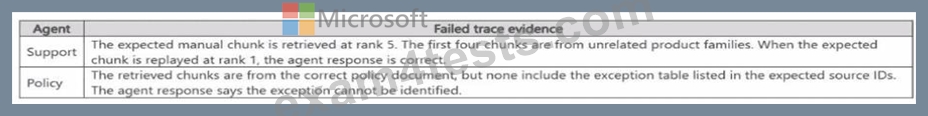
You need to isolate the failing parts of the RAG pipeline.
Which evaluator should you use for each agent? To answer, drag the appropriate evaluators to the correct agents. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.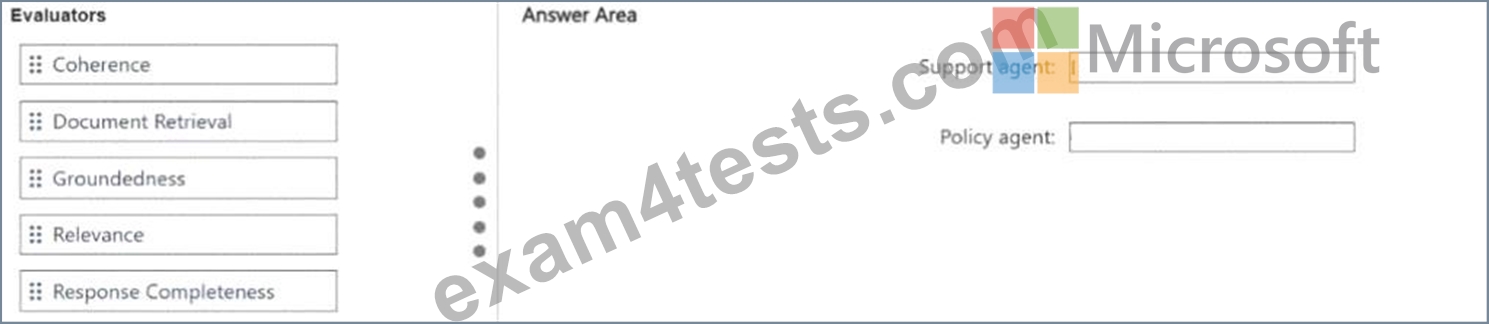
Answer:
Explanation: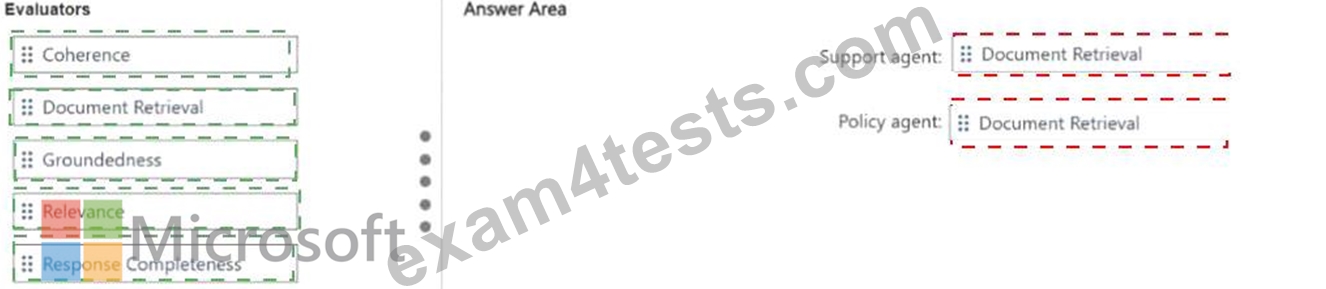
Explanation:
Support agent: Document Retrieval; Policy agent: Document Retrieval.
Both failures are retrieval failures and should therefore be diagnosed with the Document Retrieval evaluator.
The dataset includes expected source IDs and ranked retrieved chunks, which provides the retrieval ground truth required by that evaluator. For the support agent, the expected source appears too low in the ranking after unrelated chunks. For the policy agent, the required exception-table source is missing entirely.
Groundedness would evaluate whether the final response is supported by the context it actually received; it could therefore pass even when the retrieval stage failed to fetch a required source. Microsoft Foundry ' s Document Retrieval evaluator compares retrieved documents against labeled ground truth and reports ranking
/search metrics such as NDCG and Fidelity. The corrected answer is Document Retrieval for both agents. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators
NEW QUESTION # 28
You have a Microsoft Foundry ticket-triage solution that uses connected agents. Each subagent prompt includes instructions for allowed tools and a JSON handoff.
You need to add automated prompt evaluations. The solution must identify changes that cause the subagents to do the following:
* Skip mandated evidence gathering.
* Return payloads that downstream agents cannot process.
* Handle work outside their assigned responsibilities.
How should you configure the evaluation suite? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.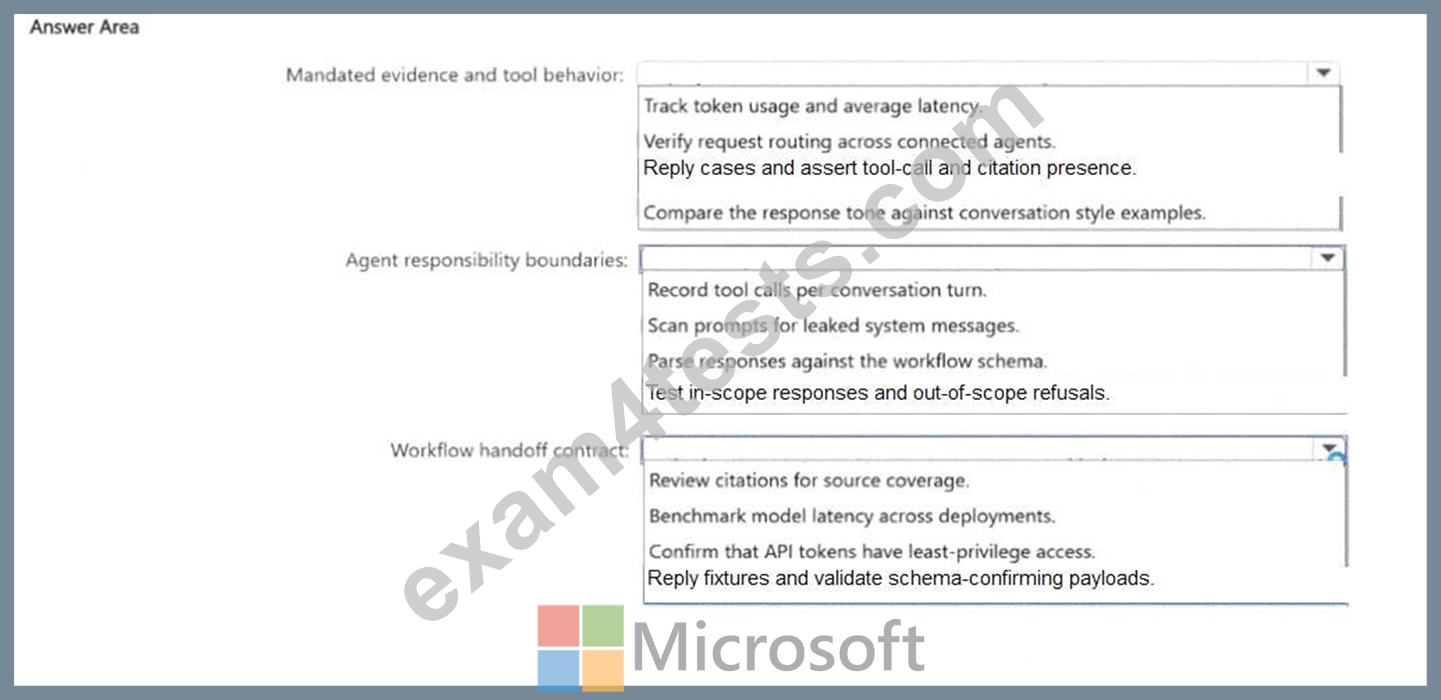
Answer:
Explanation: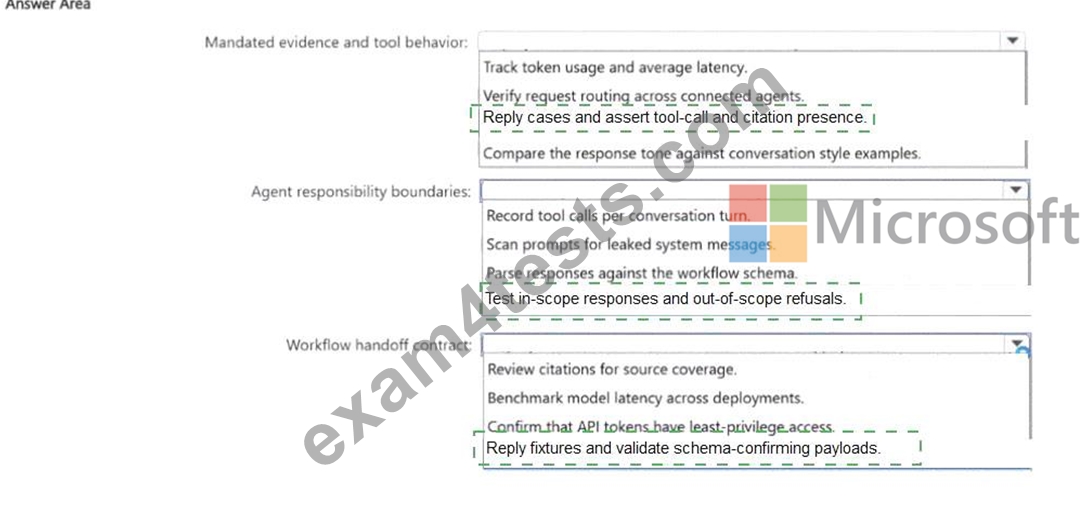
Explanation:
Mandated evidence/tool behavior: Replay cases and assert tool-call and citation presence; Agent responsibility boundaries: Test in-scope responses and out-of-scope refusals; Workflow handoff contract: Replay fixtures and validate schema-conforming payloads.
The three regressions target different interfaces and should be evaluated with tests that directly observe those interfaces. Required evidence gathering is a process behavior, so replayed cases should assert that mandated tool calls and citations occur. Responsibility boundaries are best tested with both positive and negative prompts: in-scope cases must be handled, while out-of-scope work should be refused or redirected. The JSON handoff is an interface contract, so replay fixtures should be validated against the expected schema to catch missing fields, renamed properties, and type changes before downstream agents fail. Microsoft Foundry ' s agent evaluators and evaluation datasets support process-level tool checks, task-adherence checks, and structured regression testing. The supplied mappings therefore correctly align each evaluation technique with the failure it is intended to detect. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - built-in evaluators and evaluation datasets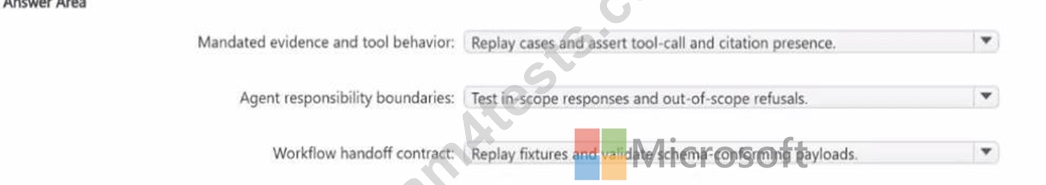
NEW QUESTION # 29
......
With years of experience in compiling top-notch relevant Microsoft AI-500 dumps questions, we also offer the Microsoft AI-500 practice test (online and offline) to help you get familiar with the actual exam environment. Therefore, if you have struggled for months to pass Microsoft AI-500 Exam, be rest assured you will pass this time with the help of our Microsoft AI-500 exam dumps. Every AI-500 exam candidate who has used our exam preparation material has passed the exam with flying colors.
AI-500 Free Sample: https://www.exam4tests.com/AI-500-valid-braindumps.html