ちなみに、JPTestKing Databricks-Certified-Professional-Data-Engineerの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=12wYbcRuoBDwxpxQCFdQK-3C9khKSa81U
君はまずネットで無料なDatabricksのDatabricks-Certified-Professional-Data-Engineer試験問題をダウンロードしてから 弊社の品質を確信してから、購入してください。JPTestKingは提供した商品は君の成功を全力で助けさしたげます。
Databricks Certified Professional Data Engineer Examは、Databricksを使用したデータエンジニアリングに関連する広範なトピックをカバーしており、データの取り込み、データ変換、データストレージ、およびデータオーケストレーションを含みます。試験はまた、Delta Lake、Apache Spark、およびDatabricks RuntimeなどのDatabricksツールやテクノロジーの熟達度も試験します。試験に合格することにより、候補者がDatabricksを使用して効率的かつスケーラブルなデータパイプラインを設計、構築、および管理するために必要なスキルと知識を持っていることを証明します。この認定資格は、業界の主要な組織によって認められているため、候補者の信頼性と市場価値を高めます。
>> Databricks-Certified-Professional-Data-Engineer日本語対策 <<
業界の他の製品とは対照的に、Databricks-Certified-Professional-Data-Engineerテストガイドの合格率は非常に高く、多くのユーザーが確認しています。 Databricks-Certified-Professional-Data-Engineer試験トレーニングを使用している限り、試験に合格することができます。試験に合格しなかった場合は、全額返金されます。 Databricks-Certified-Professional-Data-Engineer学習ガイドは、あなたと一緒に進歩し、彼ら自身の将来のために協力することを望んでいます。 Databricks Certified Professional Data Engineer Exam試験トレーニングガイドの合格率も高いため、努力が必要です。 Databricks-Certified-Professional-Data-Engineerテストガイドを選択した場合、一緒にこの高い合格率に貢献できると思います。
Databricks認定プロフェッショナルデータエンジニア試験は、DataBricksプラットフォーム上のデータパイプラインの構築、設計、管理に関する候補者の知識とスキルをテストするように設計されています。この試験では、データ処理、データストレージ、データ倉庫、データモデリング、データアーキテクチャなど、さまざまなトピックをカバーしています。候補者は、これらのトピックを深く理解し、実際のシナリオにそれらを適用できることが期待されています。
Databricks認定プロフェッショナルデータエンジニア認定は、DataBricksの使用に関するスキルと専門知識を検証したいデータエンジニアにとって貴重な資格です。この認定は、候補者がDataBricksを使用してデータソリューションを設計および実装するために必要な知識とスキルを持っていることを雇用主とクライアントに示しています。また、データエンジニアが競争力のある雇用市場で自分自身を区別するのに役立ち、キャリアの進歩の機会を提供します。
質問 # 212
A data engineer has developed a code block to perform a streaming read on a data source. The code block is
below:
1. (spark
2. .read
3. .schema(schema)
4. .format("cloudFiles")
5. .option("cloudFiles.format", "json")
6. .load(dataSource)
7. )
The code block is returning an error.
Which of the following changes should be made to the code block to configure the block to successfully
perform a streaming read?
正解:C
質問 # 213
The data engineering team maintains a table of aggregate statistics through batch nightly updates. This includes total sales for the previous day alongside totals and averages for a variety of time periods including the 7 previous days, year-to-date, and quarter-to-date. This table is namedstore_saies_summaryand the schema is as follows:
The tabledaily_store_salescontains all the information needed to updatestore_sales_summary. The schema for this table is:
store_id INT, sales_date DATE, total_sales FLOAT
Ifdaily_store_salesis implemented as a Type 1 table and thetotal_salescolumn might be adjusted after manual data auditing, which approach is the safest to generate accurate reports in thestore_sales_summary table?
正解:A
解説:
The daily_store_sales table contains all the information needed to update store_sales_summary. The schema of the table is:
store_id INT, sales_date DATE, total_sales FLOAT
The daily_store_sales table is implemented as a Type 1 table, which means that old values are overwritten by new values and no history is maintained. The total_sales column might be adjusted after manual data auditing, which means that the data in the table may change over time.
The safest approach to generate accurate reports in the store_sales_summary table is to use Structured Streaming to subscribe to the change data feed for daily_store_sales and apply changes to the aggregates in the store_sales_summary table with each update. Structured Streaming is a scalable and fault-tolerant stream processing engine built on Spark SQL. Structured Streaming allows processing data streams as if they were tables or DataFrames, using familiar operations such as select, filter, groupBy, or join. Structured Streaming also supports output modes that specify how to write the results of a streaming query to a sink, such as append, update, or complete. Structured Streaming can handle both streaming and batch data sources in a unified manner.
The change data feed is a feature of Delta Lake that provides structured streaming sources that can subscribe to changes made to a Delta Lake table. The change data feed captures both data changes and schema changes as ordered events that can be processed by downstream applications or services. The change data feed can be configured with different options, such as starting from a specific version or timestamp, filtering by operation type or partition values, or excluding no-op changes.
By using Structured Streaming to subscribe to the change data feed for daily_store_sales, one can capture and process any changes made to the total_sales column due to manual data auditing. By applying these changes to the aggregates in the store_sales_summary table with each update, one can ensure that the reports are always consistent and accurate with the latest data. Verified References: [Databricks Certified Data Engineer Professional], under "Spark Core" section; Databricks Documentation, under "Structured Streaming" section; Databricks Documentation, under "Delta Change Data Feed" section.
質問 # 214
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active user. They then modify their code to the following (leaving all other variables unchanged).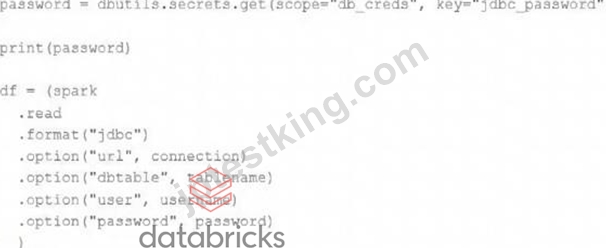
Which statement describes what will happen when the above code is executed?
正解:A
解説:
This is the correct answer because the code is using the dbutils.secrets.get method to retrieve the password from the secrets module and store it in a variable. The secrets module allows users to securely store and access sensitive information such as passwords, tokens, or API keys. The connection to the external table will succeed because the password variable will contain the actual password value. However, when printing the password variable, the string "redacted" will be displayed instead of the plain text password, as a security measure to prevent exposing sensitive information in notebooks. Verified References: [Databricks Certified Data Engineer Professional], under "Security and Governance" section; Databricks Documentation, under
"Secrets" section.
質問 # 215
A data architect is designing a Databricks solution to efficiently process data for different business requirements.
In which scenario should a data engineer use a materialized view compared to a streaming table?
正解:C
解説:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Materialized views in Databricks are optimized for precomputing and caching results of complex SQL queries, joins, and aggregations. They store query outputs physically and automatically refresh on a schedule or incremental change basis, drastically improving BI dashboard performance and reducing compute costs.
Conversely, streaming tables are designed for real-time data ingestion and processing, enabling event-driven analytics and low-latency use cases.
Databricks documentation explicitly recommends materialized views for analytical workloads with periodic updates and streaming tables for continuously updating sources. Therefore, the correct choice is C, where complex aggregations from large tables benefit most from materialized precomputation for fast reporting.
質問 # 216
A Delta Lake table was created with the below query: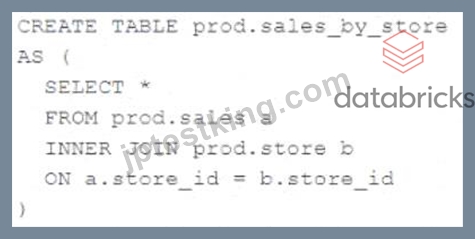
Consider the following query:
DROP TABLE prod.sales_by_store -
If this statement is executed by a workspace admin, which result will occur?
正解:B
解説:
When a table is dropped in Delta Lake, the table is removed from the catalog and the data is deleted. This is because Delta Lake is a transactional storage layer that provides ACID guarantees. When a table is dropped, the transaction log is updated to reflect the deletion of the table and the data is deleted from the underlying storage. References:
* https://docs.databricks.com/delta/quick-start.html#drop-a-table
* https://docs.databricks.com/delta/delta-batch.html#drop-table
質問 # 217
......
Databricks-Certified-Professional-Data-Engineer資格トレーニング: https://www.jptestking.com/Databricks-Certified-Professional-Data-Engineer-exam.html
P.S.JPTestKingがGoogle Driveで共有している無料の2026 Databricks Databricks-Certified-Professional-Data-Engineerダンプ:https://drive.google.com/open?id=12wYbcRuoBDwxpxQCFdQK-3C9khKSa81U