There are many ways to help you prepare for your Databricks Certified-Data-Engineer-Professional exam. Pass4cram provide a reliable training tools to help you prepare for your Databricks Certified-Data-Engineer-Professional exam certification. The Pass4cram Databricks Certified-Data-Engineer-Professional Exam Materials are including test questions and answers. Our materials are very good sofeware that through the practice test. Our materials will meet all of theIT certifications.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Topic 2: Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines - Apply AUTO CDC APIs and exactly-once semantics |
| Topic 3: Developing Code for Data Processing using Python and SQL | ~22% | - Manage dependencies, libraries, and UDFs - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader - Implement scalable Python/SQL code and project structures |
| Topic 4: Monitoring, Logging, and Troubleshooting | ~8% | - Use Spark UI, Query Profiler, and system tables - Diagnose common pipeline and job failures |
| Topic 5: Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations - Enforce data quality and quarantine bad data |
| Topic 6: Cost and Performance Optimization | ~13% | - Optimize queries, clusters, and storage - Leverage system tables and observability tools |
| Topic 7: CI/CD, Testing, and Deployment | ~6% | - Deploy with Declarative Automation Bundles, CLI, and REST API - Implement testing and deployment pipelines |
| Topic 8: Data Modeling | ~10% | - Design scalable Delta Lake schemas and clustering - Apply dimensional modeling techniques |
| Topic 9: Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs - Implement row-level security, column masking, and compliance |
>> Valid Exam Certified-Data-Engineer-Professional Vce Free <<
Our system is high effective and competent. After the clients pay successfully for the Certified-Data-Engineer-Professional certification material the system will send the products to the clients by the mails. The clients click on the links in the mails and then they can use the Certified-Data-Engineer-Professional prep guide materials immediately. It takes only a few minutes for you to make the successful payment for our Certified-Data-Engineer-Professional learning file. Our system will automatically send the updates of the Certified-Data-Engineer-Professional learning file to the clients as soon as the updates are available. So our system is wonderful.
NEW QUESTION # 83
The DevOps team has configured a production workload as a collection of notebooks scheduled to run daily using the Jobs UI. A new data engineering hire is onboarding to the team and has requested access to one of these notebooks to review the production logic.
What are the maximum notebook permissions that can be granted to the user without allowing accidental changes to production code or data?
Answer: D
NEW QUESTION # 84
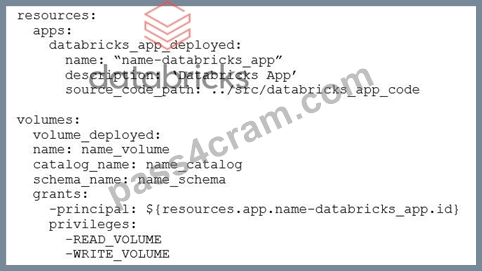
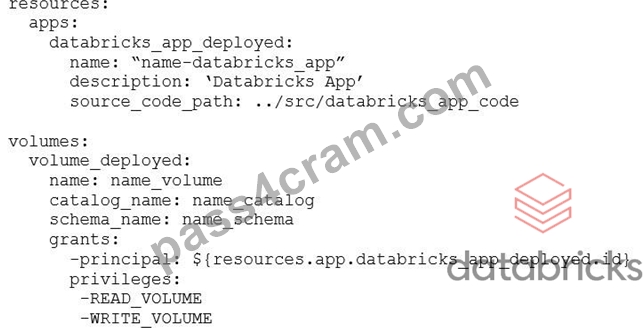
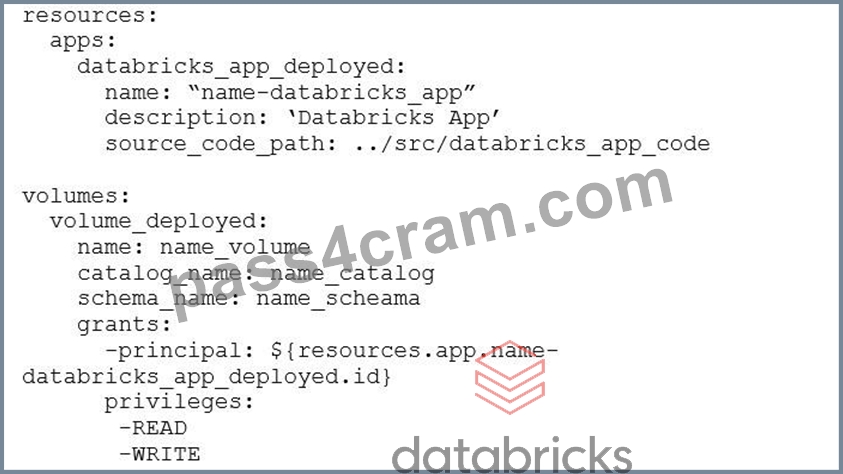
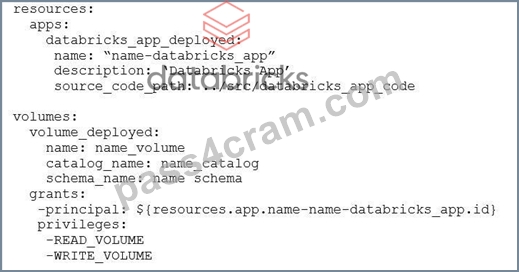
In a Databricks Asset Bundle project, in the file resources/app.yml, the data engineer would like to deploy a Databricks Apps databricks_app_deployed and Volume volume_deployed and grant the Service Principal behind Databricks Apps permissions to READ and WRITE to the Volume.
How should the data engineer achieve the deployment?
Answer: B
Explanation:
This configuration correctly references the service principal created for the Databricks App using the deployed app resource identifier, and it grants the required READ and WRITE privileges at the Volume level. The privileges are specified using the correct Volume-specific permissions, ensuring the Databricks App can securely access the Volume after deployment.
NEW QUESTION # 85
A data engineer wants to ingest a large collection of image files (JPEG and PNG) from cloud object storage into a Unity Catalog-managed table for analysis and visualization. Which two configurations and practices are recommended to incrementally ingest these images into the table? (Choose two.)
Answer: A,D
Explanation:
Databricks Auto Loader supports ingestion of binary file formats using the cloudFiles.format option. For ingesting JPEG or PNG image files, the correct setting is "BINARYFILE", which loads the raw binary content and file metadata into a DataFrame. Additionally, when processing files from object storage, it is best practice to apply pathGlobFilter to limit ingestion to specific file types and reduce unnecessary scanning of non-image files. Options like "IMAGE" or "TEXT" are invalid, and using volumes with SQL editors does not provide incremental ingestion. Therefore, combining Auto Loader with cloudFiles.format="BINARYFILE" and pathGlobFilter ensures scalable, incremental ingestion of image data into Unity Catalog tables.
NEW QUESTION # 86
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream for highly selective joins on a number of fields, and will also be leveraged by the machine learning team to filter on a handful of relevant fields, in total, 15 fields have been identified that will often be used for filter and join logic.
The data engineer is trying to determine the best approach for dealing with these nested fields before declaring the table schema.
Which of the following accurately presents information about Delta Lake and Databricks that may Impact their decision-making process?
Answer: B
Explanation:
Delta Lake, built on top of Parquet, enhances query performance through data skipping, which is based on the statistics collected for each file in a table. For tables with a large number of columns, Delta Lake by default collects and stores statistics only for the first 32 columns. These statistics include min/max values and null counts, which are used to optimize query execution by skipping irrelevant data files. When dealing with highly nested JSON structures, understanding this behavior is crucial for schema design, especially when determining which fields should be flattened or prioritized in the table structure to leverage data skipping efficiently for performance optimization.
NEW QUESTION # 87
A data team is automating a daily multi-task ETL pipeline in Databricks. The pipeline includes a notebook for ingesting raw data, a Python wheel task for data transformation, and a SQL query to update aggregates. They want to trigger the pipeline programmatically and see previous runs in the GUI. They need to ensure tasks are retried on failure and stakeholders are notified by email if any task fails. Which two approaches will meet these requirements? (Choose two.)
Answer: D,E
Explanation:
Databricks Jobs supports defining multi-task workflows that include notebooks, SQL statements, and Python wheel tasks. These can be configured with retry policies, dependency chains, and failure notifications. The correct practice, as stated in the documentation, is to use the Jobs REST API (/jobs/create) or Databricks Asset Bundles to define multi-task jobs, and then trigger them programmatically using /jobs/run-now, CLI, or SDK. This allows the team to maintain full job history, handle retries automatically, and receive alerts via configured email notifications. Using
/jobs/runs/submit creates one-off ad hoc runs without maintaining dependency visibility.
Therefore, options B and C together satisfy the operational, automation, and governance requirements.
NEW QUESTION # 88
......
In the major environment, people are facing more job pressure. So they want to get Databricks certification rise above the common herd. How to choose valid and efficient Certified-Data-Engineer-Professional guide torrent should be the key topic most candidates may concern. So now, it is right, you come to us. Our company is famous for its high-quality Certified-Data-Engineer-Professional Exam Questions in this field especially for Databricks certification exams. It has been accepted by thousands of candidates who practice our Certified-Data-Engineer-Professional study materials for their exam.
Pass Certified-Data-Engineer-Professional Guaranteed: https://www.pass4cram.com/Certified-Data-Engineer-Professional_free-download.html