P.S. Kostenlose 2026 Databricks Databricks-Generative-AI-Engineer-Associate Prüfungsfragen sind auf Google Drive freigegeben von Pass4Test verfügbar: https://drive.google.com/open?id=1P40yYVjWedwsvPmGtPJv0eqSBH8lmxLZ
Wenn Sie einige unserer Prüfungsfrage und Antworten für Databricks Databricks-Generative-AI-Engineer-Associate Zertifizierungsprüfung versucht haben, dann können Sie eine Wahl darüber treffen, Pass4Test zu kaufen oder nicht. Wir werden Ihnen mit 100% Bequemlichkeit und Garantie bieten. Denken Sie bitte daran, dass nur Pass4Test Ihen zum Bestehen der Databricks Databricks-Generative-AI-Engineer-Associate Zertifizierungsprüfung verhelfen kann.
| Thema | Einzelheiten |
|---|---|
| Thema 1 |
|
| Thema 2 |
|
| Thema 3 |
|
| Thema 4 |
|
>> Databricks-Generative-AI-Engineer-Associate Originale Fragen <<
Wir sind der Schnellste, der daa Databricks Databricks-Generative-AI-Engineer-Associate Zertifikat erhält; wir sind noch der höchste, der Ihre Interessen schützt. Wir sind Pass4Test. Pass4Test kann Ihnen versprechen, dass die Testaufgaben von Databricks Databricks-Generative-AI-Engineer-Associate Zertifizierungsprüfung 100% richtig und ganz umfassend sind. Nachdem Sie die Testfragen zur Databricks Databricks-Generative-AI-Engineer-Associate Zertifizierung gekauft haben, werden Sie kostenlos die einjährige Aktualisierung genießen.
70. Frage
Which TWO chain components are required for building a basic LLM-enabled chat application that includes conversational capabilities, knowledge retrieval, and contextual memory?
Antwort: A,E
Begründung:
Building a basic LLM-enabled chat application with conversational capabilities, knowledge retrieval, and contextual memory requires specific components that work together to process queries, maintain context, and retrieve relevant information. Databricks' Generative AI Engineer documentation outlines key components for such systems, particularly in the context of frameworks like LangChain or Databricks' MosaicML integrations. Let's evaluate the required components:
* Understanding the Requirements :
* Conversational capabilities : The app must generate natural, coherent responses.
* Knowledge retrieval : It must access external or domain-specific knowledge.
* Contextual memory : It must remember prior interactions in the conversation.
* Databricks Reference: " A typical LLM chat application includes a memory component to track conversation history and a retrieval mechanism to incorporate external knowledge " ( " Databricks Generative AI Cookbook, " 2023).
* Evaluating the Options :
* A. (Q) : This appears incomplete or unclear (possibly a typo). Without further context, it's not a valid component.
* B. Vector Stores : These store embeddings of documents or knowledge bases, enabling semantic search and retrieval of relevant information for the LLM. This is critical for knowledge retrieval in a chat application.
* Databricks Reference : " Vector stores, such as those integrated with Databricks' Lakehouse, enable efficient retrieval of contextual data for LLMs " ( " Building LLM Applications with Databricks " ).
* C. Conversation Buffer Memory : This component stores the conversation history, allowing the LLM to maintain context across multiple turns. It's essential for contextual memory.
* Databricks Reference : " Conversation Buffer Memory tracks prior user inputs and LLM outputs, ensuring context-aware responses " ( " Generative AI Engineer Guide " ).
* D. External tools : These (e.g., APIs or calculators) enhance functionality but aren't required for a basic chat app with the specified capabilities.
* E. Chat loaders : These might refer to data loaders for chat logs, but they're not a core chain component for conversational functionality or memory.
* F. React Components : These relate to front-end UI development, not the LLM chain's backend functionality.
* Selecting the Two Required Components :
* For knowledge retrieval , Vector Stores (B) are necessary to fetch relevant external data, a cornerstone of Databricks' RAG-based chat systems.
* For contextual memory , Conversation Buffer Memory (C) is required to maintain conversation history, ensuring coherent and context-aware responses.
* While an LLM itself is implied as the core generator, the question asks for chain components beyond the model, making B and C the minimal yet sufficient pair for a basic application.
Conclusion : The two required chain components are B. Vector Stores and C. Conversation Buffer Memory
, as they directly address knowledge retrieval and contextual memory, respectively, aligning with Databricks' documented best practices for LLM-enabled chat applications.
71. Frage
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here's a sample email: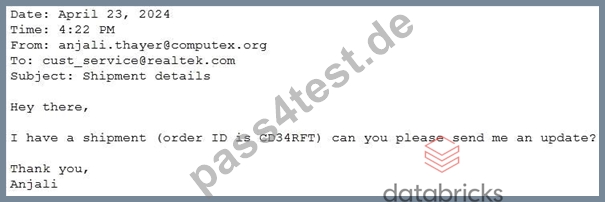
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
Antwort: A
Begründung:
Problem Context: The goal is to parse emails to extract certain pieces of information and output this in a structured JSON format. Clarity and specificity in the prompt design will ensure higher accuracy in the LLM' s responses.
Explanation of Options:
* Option A: Provides a general guideline but lacks an example, which helps an LLM understand the exact format expected.
* Option B: Includes a clear instruction and a specific example of the output format. Providing an example is crucial as it helps set the pattern and format in which the information should be structured, leading to more accurate results.
* Option C: Does not specify that the output should be in JSON format, thus not meeting the requirement.
* Option D: While it correctly asks for JSON format, it lacks an example that would guide the LLM on how to structure the JSON correctly.
Therefore,Option Bis optimal as it not only specifies the required format but also illustrates it with an example, enhancing the likelihood of accurate extraction and formatting by the LLM.
72. Frage
After changing the response generating LLM in a RAG pipeline from GPT-4 to a model with a shorter context length that the company self-hosts, the Generative AI Engineer is getting the following error:
What TWO solutions should the Generative AI Engineer implement without changing the response generating model? (Choose two.)
Antwort: A,C
Begründung:
* Problem Context : After switching to a model with a shorter context length, the error message indicating that the prompt token count has exceeded the limit suggests that the input to the model is too large.
* Explanation of Options :
* Option A: Use a smaller embedding model to generate - This wouldn ' t necessarily address the issue of prompt size exceeding the model's token limit.
* Option B: Reduce the maximum output tokens of the new model - This option affects the output length, not the size of the input being too large.
* Option C: Decrease the chunk size of embedded documents - This would help reduce the size of each document chunk fed into the model, ensuring that the input remains within the model ' s context length limitations.
* Option D: Reduce the number of records retrieved from the vector database - By retrieving fewer records, the total input size to the model can be managed more effectively, keeping it within the allowable token limits.
* Option E: Retrain the response generating model using ALiBi - Retraining the model is contrary to the stipulation not to change the response generating model.
Options C and D are the most effective solutions to manage the model's shorter context length without changing the model itself, by adjusting the input size both in terms of individual document size and total documents retrieved.
73. Frage
Which TWO chain components are required for building a basic LLM-enabled chat application that includes conversational capabilities, knowledge retrieval, and contextual memory?
Antwort: A,E
Begründung:
Building a basic LLM-enabled chat application with conversational capabilities, knowledge retrieval, and contextual memory requires specific components that work together to process queries, maintain context, and retrieve relevant information. Databricks' Generative AI Engineer documentation outlines key components for such systems, particularly in the context of frameworks like LangChain or Databricks' MosaicML integrations. Let's evaluate the required components:
* Understanding the Requirements:
* Conversational capabilities: The app must generate natural, coherent responses.
* Knowledge retrieval: It must access external or domain-specific knowledge.
* Contextual memory: It must remember prior interactions in the conversation.
* Databricks Reference:"A typical LLM chat application includes a memory component to track conversation history and a retrieval mechanism to incorporate external knowledge"("Databricks Generative AI Cookbook," 2023).
* Evaluating the Options:
* A. (Q): This appears incomplete or unclear (possibly a typo). Without further context, it's not a valid component.
* B. Vector Stores: These store embeddings of documents or knowledge bases, enabling semantic search and retrieval of relevant information for the LLM. This is critical for knowledge retrieval in a chat application.
* Databricks Reference:"Vector stores, such as those integrated with Databricks' Lakehouse, enable efficient retrieval of contextual data for LLMs"("Building LLM Applications with Databricks").
* C. Conversation Buffer Memory: This component stores the conversation history, allowing the LLM to maintain context across multiple turns. It's essential for contextual memory.
* Databricks Reference:"Conversation Buffer Memory tracks prior user inputs and LLM outputs, ensuring context-aware responses"("Generative AI Engineer Guide").
* D. External tools: These (e.g., APIs or calculators) enhance functionality but aren't required for a basicchat app with the specified capabilities.
* E. Chat loaders: These might refer to data loaders for chat logs, but they're not a core chain component for conversational functionality or memory.
* F. React Components: These relate to front-end UI development, not the LLM chain's backend functionality.
* Selecting the Two Required Components:
* Forknowledge retrieval, Vector Stores (B) are necessary to fetch relevant external data, a cornerstone of Databricks' RAG-based chat systems.
* Forcontextual memory, Conversation Buffer Memory (C) is required to maintain conversation history, ensuring coherent and context-aware responses.
* While an LLM itself is implied as the core generator, the question asks for chain components beyond the model, making B and C the minimal yet sufficient pair for a basic application.
Conclusion: The two required chain components areB. Vector StoresandC. Conversation Buffer Memory, as they directly address knowledge retrieval and contextual memory, respectively, aligning with Databricks' documented best practices for LLM-enabled chat applications.
74. Frage
A Generative AI Engineer has been reviewing issues with their company ' s LLM-based question-answering assistant and has determined that a technique called prompt chaining could help alleviate some performance concerns. However, to suggest this to their team, they have to clearly explain how it works and how it can benefit their question-answering assistant. Which explanation do they communicate to the team?
Antwort: D
Begründung:
Prompt chaining is a fundamental design pattern in LLM application development used to handle complexity.
Instead of sending a single, massive, and highly complex prompt to an LLM-which often results in reasoning errors or hallucinations-chaining breaks the logic into a sequence of smaller, targeted steps. For example, a legal assistant might first chain a step to " identify the legal jurisdiction, " followed by a step to " extract relevant statutes, " and finally a step to " summarize the findings. " This modularity improves reliability because each prompt has a narrower focus, making it easier for the model to follow instructions accurately. While it may actually increase latency (contradicting B) and cost (contradicting D) due to multiple API calls, the primary engineering benefit is the significant boost in the quality and robustness of the output.
It also allows for intermediate validation and error handling between steps, which is impossible in a single- call architecture.
75. Frage
......
Heute legen immer mehr IT Profis großen Wert auf Databricks Databricks-Generative-AI-Engineer-Associate Prüfungszertifizierung. Sie wird ein Maßstab für die IT-Fähigkeiten einer Person. Viele Leute leiden darunter, wie sich auf die Databricks Databricks-Generative-AI-Engineer-Associate Prüfung vorzubereiten. Allerdings sind Sie glücklich. Wenn Sie diese den Artikel gelesen haben, finden Sie doch die beste Vorbereitungsweise für Databricks Databricks-Generative-AI-Engineer-Associate Prüfung. Die Databricks Databricks-Generative-AI-Engineer-Associate Prüfungssoftware von unserem Pass4Test Team zu benutzen bedeutet, dass Ihre Prüfungszertifizierung der Databricks Databricks-Generative-AI-Engineer-Associate ist gesichert. Zaudern Sie noch? Laden Sie unsere kostenfreie Demo und Probieren Sie mal!
Databricks-Generative-AI-Engineer-Associate PDF Testsoftware: https://www.pass4test.de/Databricks-Generative-AI-Engineer-Associate.html
P.S. Kostenlose und neue Databricks-Generative-AI-Engineer-Associate Prüfungsfragen sind auf Google Drive freigegeben von Pass4Test verfügbar: https://drive.google.com/open?id=1P40yYVjWedwsvPmGtPJv0eqSBH8lmxLZ