The Microsoft DP-800 exam questions of Prep4cram mainly come in three formats: Developing AI-Enabled Database Solutions (DP-800) dumps PDF, Web-Based DP-800 Practice Exam and Desktop Developing AI-Enabled Database Solutions (DP-800) Practice Test Software. With thousands of satisfied customers, you can start your preparation for Developing AI-Enabled Database Solutions (DP-800) certification with Prep4cram.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Reliable DP-800 Braindumps Book <<
All Microsoft DP-800 exam dumps formats are being offered at the best price. The real Microsoft DP-800 Dumps are ready for download. Just pay an affordable DP-800 exam questions charge and start preparing. Prep4cram resolves every problem of the test aspirants with reliable Developing AI-Enabled Database Solutions DP-800 Practice Test material.
NEW QUESTION # 44
Which SQL feature is commonly used to integrate AI-generated insights?
Answer: A
Explanation:
AI models (like OpenAI) are typically accessed via APIs, which SQL apps call externally.
NEW QUESTION # 45
You have an Azure SQL database that contains tables named dbo.ProduetDocs and dbo.
ProductuocsEnbeddings. dbo.ProductOocs contains product documentation and the following columns:
* Docld (int)
* Title (nvdrchdr(200))
* Body (nvarthar(max))
* LastHodified (datetime2)
The documentation is edited throughout the day. dbo.ProductDocsEabeddings contains the following columns:
* Dotid (int)
* ChunkOrder (int)
* ChunkText (nvarchar(aax))
* Embedding (vector(1536))
The current embedding pipeline runs once per night
Vou need to ensure that embeddings are updated every time the underlying documentation content changes The solution must NOT ' equire a nightly batch process.
What should you include in the solution?
Answer: A
Explanation:
The requirement is to ensure embeddings are updated every time the underlying content changes without relying on a nightly batch job. The right design is to enable change tracking on the source table so an external process can identify which rows changed and regenerate embeddings only for those rows. Microsoft documents that change detection mechanisms are used to pick up new and updated rows incrementally , which is the right pattern when you need near-continuous refresh instead of full nightly rebuilds.
This is better than:
* A. fixed-size chunking , which affects chunk strategy but not change detection.
* B. a smaller embedding model , which affects model cost/latency but not update triggering.
* C. table triggers , which would push embedding-maintenance logic directly into write operations and is generally not the best design for AI-processing pipelines. The question specifically asks for a solution that replaces the nightly batch requirement, not one that performs heavyweight work inline during every transaction.
NEW QUESTION # 46
You have a SQL database in Microsoft Fabric that contains a table named dbo.Orders. dbo.Orders has a clustered index, contains three years of data, and is partitioned by a column named OrderDate by month.
You need to remove all the rows for the oldest month. The solution must minimize the impact on other queries that access the data in dbo.Orders.
Solution: Identify the partition scheme for the oldest month, and then run the following Transact-SQL statement:
SQL
ALTER TABLE dbo.Orders
DROP PARTITION SCHEME {partition_scheme_name};
Does this meet the goal?
Answer: A
NEW QUESTION # 47
You have an Azure SQL database that contains a table named knowledgebase, knowledgebase stores human resources (HR) policy documents and contains columns named title, content, category, and embedding.
You have an application named App1. App1 queries two relational tables named employee_pnofiles and benefits_enrollnent that contain HR data. App1 hosts a chatbot that calls a large language model (LLM) directly.
Users report that the chatbot answers general HR questions correctly but provides outdated or incorrect answers when policies change. The chatbot also fails to answer questions that reference internal policy documents by title or category.
You need to recommend a Retrieval Augmented Generation (RAG) solution to resolve the chatbot issues.
What should you recommend? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.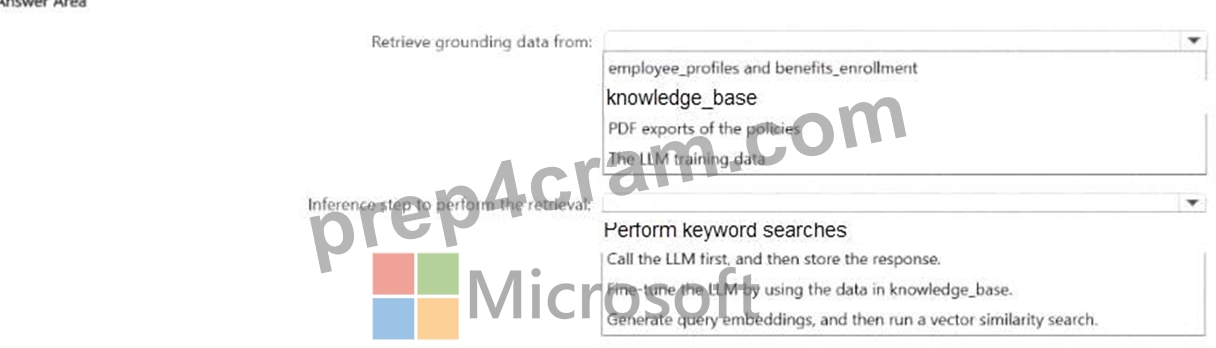
Answer:
Explanation: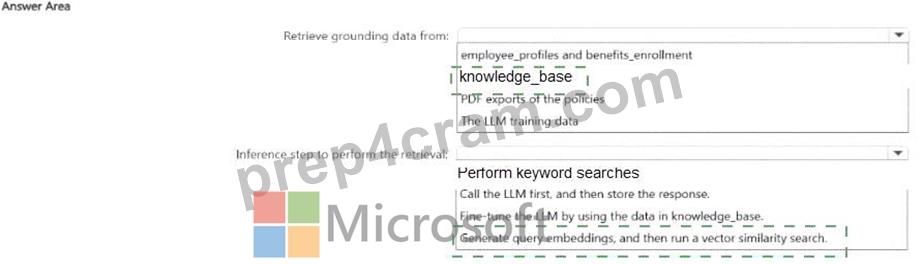
Explanation: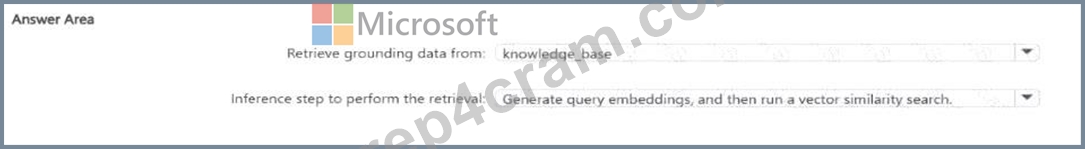
The correct recommendation is to retrieve grounding data from knowledge_base and, at inference time, generate query embeddings and run a vector similarity search .
The chatbot currently answers some general HR questions but fails when policies change and when users ask about internal policy documents by title or category . That is exactly the kind of problem RAG is meant to solve: ground the LLM in the organization's proprietary content instead of relying on the model's training data or unrelated transactional tables. Microsoft's RAG guidance states that RAG extends LLMs by grounding responses in your own content and that, for agentic retrieval, knowledge bases unify knowledge sources for retrieval.
So the grounding data should come from knowledge_base , because that table stores the HR policy documents and already includes fields like title, content, category, and embedding. Those are the fields directly tied to the missing and outdated policy answers. By contrast:
* employee_profiles and benefits_enrollment are operational HR tables, not the authoritative store for policy-document grounding.
* PDF exports of the policies would be inferior to querying the indexed/structured knowledge base already prepared for retrieval.
* The LLM training data is specifically the wrong source when the issue is outdated internal content.
For the retrieval step, Microsoft's guidance says to use embeddings for vector queries and notes that vector similarity search matches concepts, not exact terms . This is especially important because users ask about policy documents by title or category and also phrase questions in ways that might not exactly match document wording. Generating a query embedding and then running a vector similarity search is the appropriate retrieval step in a RAG pipeline.
NEW QUESTION # 48
You have an Azure SQL database that contains a table named Rooms. Rooms was created by using the following transact-SQL statement.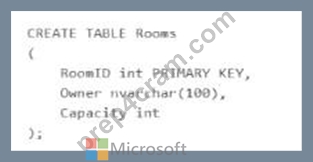
You discover that some records in the Rooms table contain NULL values for the Owner field. You need to ensure that all future records have a value for the Owner field. What should you add?
Answer: A
Explanation:
The table definition allows Owner to be nullable because it was created as Owner nvarchar(100) without NOT NULL. Since the question asks what to add so that future rows must have a value, a check constraint such as CHECK (Owner IS NOT NULL) is the appropriate choice. Microsoft documents that check constraints validate future INSERT and UPDATE operations against the constraint condition.
The other options do not solve the requirement:
* A foreign key enforces referential integrity, not non-null entry by itself.
* A nonclustered index does not require values to be present.
* A unique constraint prevents duplicate values but still does not serve as the right mechanism here for enforcing presence across future writes. Microsoft's constraint documentation also notes that primary- key columns are implicitly NOT NULL, which helps distinguish nullability enforcement from other constraint types.
NEW QUESTION # 49
......
It is not hard to find that there are many different kinds of products in the education market now. It may be difficult for users to determine the best way to fit in the complex choices. We can tell you with confidence that the DP-800 practice materials are superior in all respects to similar products. First, users can have a free trial of DP-800 test prep, to help users better understand the DP-800 Study Guide. If the user discovers that the product is not appropriate for him, the user can choose another type of learning material. Respect the user's choice, will not impose the user must purchase the DP-800 practice materials. We can meet all the requirements of the user as much as possible, to help users better pass the qualifying exams.
DP-800 Practice Tests: https://www.prep4cram.com/DP-800_exam-questions.html