Wenn Sie sich auf Microsoft AI-500 Prüfung vorbereiten, ist es nicht eine gute Weise für Sie, alle Kenntnisse für die Prüfungen ziellos auswendig zu lernen. Tatsächlich gibt es die Lernmethode, die Microsoft AI-500 Prüfung leichter zu bestehen. Wenn Sie die guten Geräte benutzen, können Sie weniger Zeit verwenden. Und Es ist auch die Garantie, die Microsoft AI-500 Prüfung zu bestehen. Was ist das Gerät? Natürlich ist die Microsoft AI-500 Dumps von EchteFrage.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Develop multi-agent solutions in Azure | 30-35% | - Implement agent memory, context management, and knowledge integration
|
| Topic 2: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Implement observability and monitoring
|
| Topic 3: Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
| Topic 4: Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement guardrails
|
>> Microsoft AI-500 Prüfungen <<
Sie können im Internet teilweise die Fragenkatalogen zur Microsoft AI-500 Zertifizierungsprüfung von EchteFrage kostenlos herunterladen. Dann werden Sie mehr Vertrauen in unsere Produkte haben. Sie können sich dann gut auf Ihre Microsoft AI-500 Zertifizierungsprüfung vorbereiten. Schicken bitte schnell die Produkte von EchteFrage in den Warenkorb.
10. Frage
You have a Microsoft Foundry agent that completes benefits enrollment during a single user conversation The agent collects the required enrollment fields during 15 turns. Users can correct earlier values before final submission. The current implementation sends the complete transcript with every model request.
You need to change the context accumulation strategy for the active enrollment. The solution must meet the following requirements:
* Preserve the latest value for each required enrollment field until submission.
* Bound the maximum number of tokens sent with each model request
* Preserve user corrections until submission.
* Prevent durable cross-session memory.
What should you do?
Antwort: C
Begründung:
The application must preserve the latest authoritative value of each enrollment field even when the user corrects an earlier value, while also placing a firm bound on prompt size. A session-scoped enrollment-state snapshot provides deterministic structured state: each correction overwrites the previous field value. A recent- turn sliding window then preserves enough conversational context for natural interaction without resending the full 15-turn transcript. Response chaining with a fixed number of prior turns can lose an important field once it falls outside the retained history. Summarization can omit or distort corrected values, and automatic truncation likewise offers no guarantee that the latest value of every required field survives. Because the state is scoped only to the active enrollment and is not written to long-term memory, the design also avoids durable cross-session memory. Therefore A is correct. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Microsoft Agent Framework - workflow state and context management
11. Frage
You have a Microsoft Foundry multi-agent solution that uses Microsoft Agent Framework and LangGraph.
Telemetry from the workload is sent to Application Insights.
You need to implement observability components to meet the following requirements:
* Support the investigation of user interactions across agents, models, tools, functions, and API boundaries without relying on verbose production logs.
* Produce recurring and comparable measurements of deployed response quality and safety over time.
What should you use? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.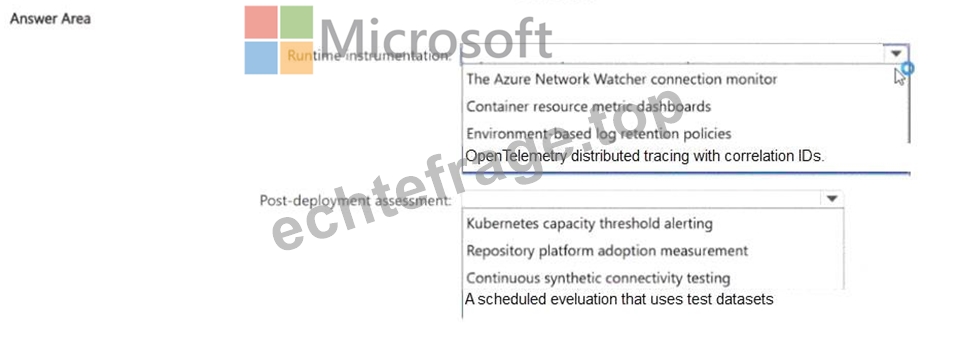
Antwort:
Begründung: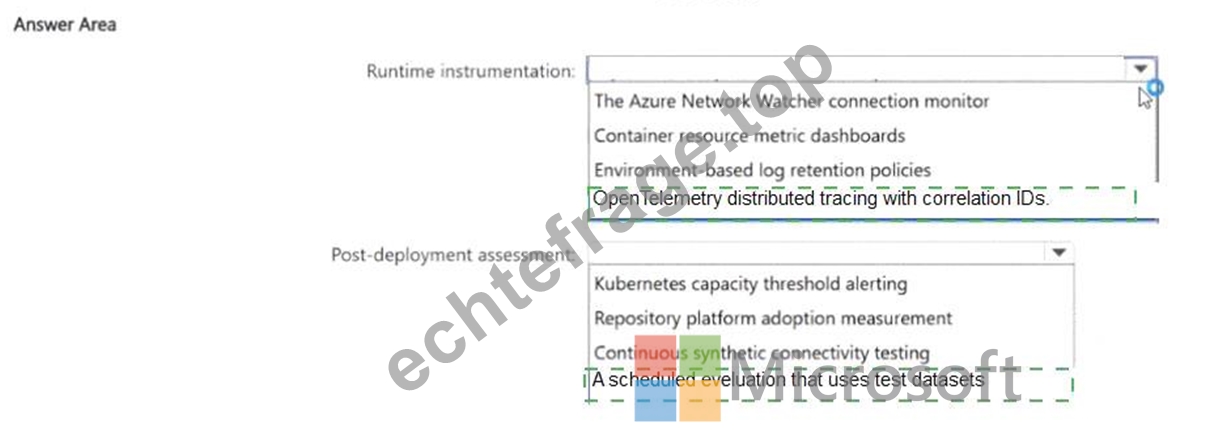
Explanation:
Runtime instrumentation: OpenTelemetry distributed tracing with correlation IDs; Post-deployment assessment: A scheduled evaluation that uses test datasets.
Distributed tracing is the correct runtime mechanism because the objective is to reconstruct a user interaction across agents, models, tools, functions, and API boundaries without relying on verbose log text. Microsoft Foundry uses OpenTelemetry-compatible traces and Application Insights so related spans can be correlated into one execution path. Correlation identifiers allow operators to isolate one conversation and inspect where latency, failures, or unexpected behavior originated. The second requirement is different: it asks for recurring, comparable measurements of deployed response quality and safety. Scheduled evaluations against stable test datasets provide that longitudinal benchmark and are more appropriate than ad hoc tracing or infrastructure- only dashboards. Together, OpenTelemetry answers "what happened in this run?" while scheduled evaluation answers "is behavior getting better or worse over time?" The selected pair therefore covers both operational diagnosis and quality regression monitoring. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry observability concepts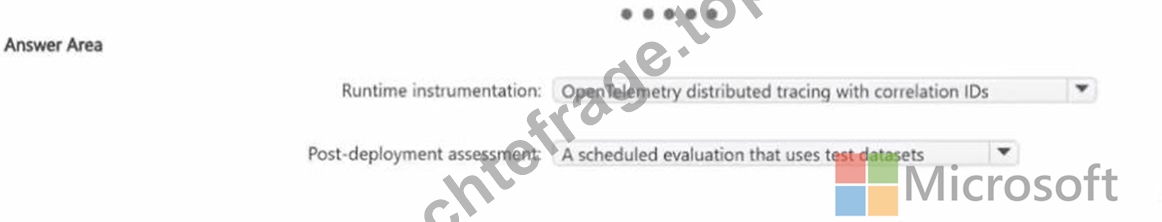
12. Frage
You are designing Microsoft Foundry multi-agent solution. The agents will use Agent-to-Agent (A2A) delegation and access separate Azure Storage containers within a resource group named RG1.
You need to recommend identity components for the design. The solution must meet the following requirements:
* Eliminate stored application secrets.
* Limit the impact of a compromised agent or deployment.
Solution: Use delegated user permissions for agent actions. Assign Azure roles by using a shared security group. Does this meet the goal?
Antwort: A
Begründung:
The proposed solution uses delegated user permissions for agent actions and assigns Azure roles through one shared security group. Even if it avoids storing an application secret, it does not create strong per-agent authorization boundaries. Sharing downstream permissions through one group can allow a compromised agent to inherit access intended for other agents, which conflicts with the requirement to limit blast radius.
Microsoft Foundry identity guidance recommends distinct logical agent/workload identities and narrowly scoped role assignments when agents have different resource responsibilities or audit requirements. Delegated user access is appropriate when an operation genuinely needs the signed-in user ' s authorization context, not as a general service-to-service isolation model for autonomous A2A workers. Therefore the proposed design does not meet both goals, and B, No, remains correct. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools.
Official Microsoft reference: Microsoft Foundry agent identity
13. Frage
You are designing a Microsoft Foundry multi-agent solution. The solution includes a triage agent that receives a request and passes the request to one of three specialist agents.
Only one agent will be active at a time. The active agent must be able to transfer control to a better-suited agent based on context.
Which orchestration pattern should you recommend for the planned solution?
Antwort: B
Begründung:
Only one agent should be active at a time, and the active agent must be able to transfer control dynamically when another specialist is better suited. Microsoft Agent Framework defines handoff orchestration for precisely that situation: task and conversational ownership move from one agent to another according to context. Concurrent orchestration would activate multiple specialists at the same time, contradicting the requirement. Sequential orchestration follows a predetermined order rather than allowing contextual transfer.
Group chat keeps multiple agents participating in a shared conversation rather than modeling single-owner control. The decisive requirement is therefore transfer of ownership, not merely calling another agent for a subtask. That makes B, handoff, the correct orchestration pattern. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Microsoft Agent Framework - Handoff orchestration
14. Frage
You have a multi-agent Retrieval-Augmented Generation (RAG) solution that uses a Foundry IQ knowledge base. The solution includes a support agent and a policy agent.
You have an evaluation dataset that contains the following for each user query
* The expected source IDs
* Retrieved chunks in rank order
* The final agent response
You discover that an embedding model change and a custom analyzer change cause the failed traces shown in the following table.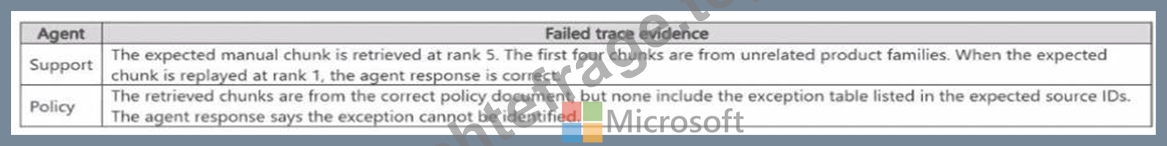
You need to isolate the failing parts of the RAG pipeline.
Which evaluator should you use for each agent? To answer, drag the appropriate evaluators to the correct agents. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.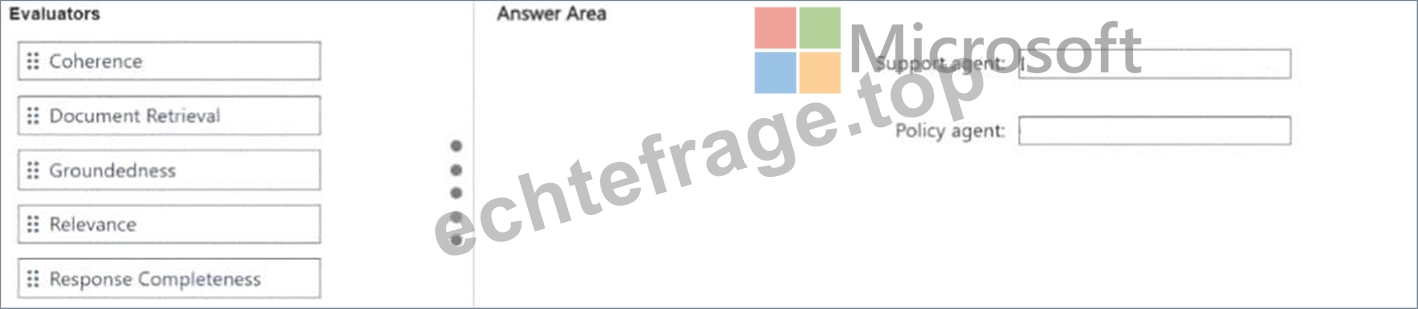
Antwort:
Begründung: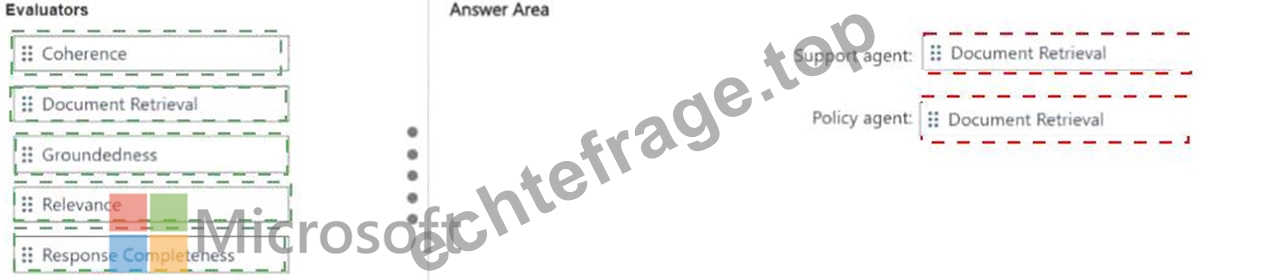
Explanation:
Support agent: Document Retrieval; Policy agent: Document Retrieval.
Both failures are retrieval failures and should therefore be diagnosed with the Document Retrieval evaluator.
The dataset includes expected source IDs and ranked retrieved chunks, which provides the retrieval ground truth required by that evaluator. For the support agent, the expected source appears too low in the ranking after unrelated chunks. For the policy agent, the required exception-table source is missing entirely.
Groundedness would evaluate whether the final response is supported by the context it actually received; it could therefore pass even when the retrieval stage failed to fetch a required source. Microsoft Foundry ' s Document Retrieval evaluator compares retrieved documents against labeled ground truth and reports ranking
/search metrics such as NDCG and Fidelity. The corrected answer is Document Retrieval for both agents. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators
15. Frage
......
Die Bestehensquote mit einer Höhe von fast 100% ist das beste Geschenk von unseren Kunden. Wir hoffen, dass unsere Microsoft AI-500 Prüfungsunterlagen mehr aufstrebenden Leuten helfen, Microsoft AI-500 Prüfung zu bestehen. Unser Team überprüfen jeden Tag die Aktualisierungsstand vieler IT-Zertifizierungsprüfungen. Sie können auf unsere Microsoft AI-500 vertrauen, weil sie die neuesten und umfassendesten Unterlagen enthält.
AI-500 Online Tests: https://www.echtefrage.top/AI-500-deutsch-pruefungen.html