Nutanix証明書を取得することは、あなたのキャリアにおける地位を高める素晴らしく迅速な方法です。 NCP-BC-7.5試験に合格するというこの目標を達成するには、外部の支援が必要です。弊社が市場で最も人気のあるベンダーであるため、このリンクをクリックすると幸運です。私たちはこのキャリアに10年以上携わっており、NCP-BC-7.5試験問題では、夢のNutanix認定を得るための支援を受けるだけでなく、オンラインで一流のサービスを楽しむことができます。
| Section | Objectives |
|---|---|
| Replication and Failover Architecture | - Network segmentation for BCDR environments - Failover readiness validation - Recovery site capacity management - Synchronous replication across sites - Asynchronous replication planning |
| Nutanix Disaster Recovery Solutions | - Configuring and managing replication policies - Failover procedures and execution - Metro Availability configuration and management - Integration with third-party backup solutions - Recovery workflows using Nutanix native tools |
| Monitoring, Testing and Troubleshooting | - Documenting runbooks for incident response - Diagnosing network, storage and replication failures - Non-disruptive recovery testing - Troubleshooting permission issues and misconfigured DR environments - Setting up alerts for replication lag - Resolving third-party backup integration problems |
| Data Protection and Snapshots | - Storage configuration for BCDR - Incremental backup implementation - Snapshot retention policies design - Snapshot scheduling and management - Data restoration at VM and application level |
| Security and Hardening | - Security best practices for replication - RBAC implementation for disaster recovery - Approval policies configuration - Designing secure BCDR environments |
| BCDR Fundamentals and Requirements Interpretation | - Selecting appropriate replication types (async, near-sync, synchronous, metro) - Availability metrics and SLA definitions - Understanding RTO and RPO concepts and business impact analysis - Defining recovery strategies aligned to business requirements and risk tolerance - Translating business requirements into resilient recovery architectures |
Nutanixは、コンピューターで勉強したい人もいれば、携帯電話で勉強したい人もいます。 NCP-BC-7.5の学習トレントは、iPod、携帯電話、コンピューターなど、ほぼすべての電子デバイスをサポートできるためです。 Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5急流を購入することを選択した場合、電子機器で学習教材を使用する機会があります。 NCP-BC-7.5テストトレントは、あなたが自分自身を改善し、想像を超えた進歩を遂げるのに役立つと信じています。 あなたが私たちのNCP-BC-7.5学習トレントを購入した場合、私たちのNutanix Certified Professional - Business Continuity (NCP-BC) 7.5学習教材があなたを失望させないことを確認することができます
質問 # 97
An administrator configures disaster recovery between an on-premises AZ and a Nutanix Cloud AZ. After enabling DR and assigning protection policies to several VMs with volume groups, the administrator initiates failover and notices the VMs do not have their volume groups attached. Investigation reveals:
* The clusters are successfully paired in Prism Central.
* Protection policies and replication schedules are configured correctly.
* Recovery plan validation completes successfully.
* Required firewall ports between sites are confirmed open.
* Management IP addresses are reachable in both directions.
Despite this, the administrator observes the volume groups are still not attached. Which network-related prerequisite is most likely misconfigured?
正解:C
解説:
Nutanix Volume Groups (VGs) provide block-level storage to virtual machines, often used for high- performance databases or shared storage clusters. Unlike standard vDisks, which are managed directly as part of the VM ' s hardware definition, VGs are presented as iSCSI targets. In a Disaster Recovery scenario, when a VM is recovered at a new site, it must be able to " find " and re-attach these Volume Groups to resume operation.
For this attachment to succeed, especially across different clusters or into a Nutanix Cloud AZ, both the source and recovery clusters must have a " Data Services IP Address " configured. The Data Services IP acts as the cluster-wide iSCSI target portal. When a VM fails over, the Nutanix orchestration engine uses this IP to coordinate the iSCSI login and mapping of the Volume Group to the guest OS. If this IP is missing on either cluster, the internal iSCSI redirection and handoff mechanisms will fail, even if the general management networking and Protection Policies are perfectly healthy. This is a common " Day 1 " configuration error because management connectivity (Prism) works without a Data Services IP, but block-level services like VGs and certain NGT features strictly require it. Verifying and configuring the Data Services IP at both availability zones is the primary fix for Volume Group attachment failures during DR failover.
質問 # 98
A Veeam backup job is configured to use Nutanix application-consistent snapshots for several Windows VMs. Crash-consistent snapshots succeed, but Veeam reports that application-consistent snapshots fail with errors related to VSS processing. Upon investigation, the administrator confirms:
* The VMs are powered on.
* Network connectivity between the backup server and cluster is healthy.
Which configuration should the administrator verify to resolve the issue?
正解:B
解説:
Application-consistent snapshots are critical for ensuring data integrity for transactional workloads, such as databases. In a Nutanix AHV or ESXi environment, the cluster achieves application consistency by communicating with the guest operating system ' s Volume Shadow Copy Service (VSS). This communication is facilitated exclusively through Nutanix Guest Tools (NGT). When NGT is installed and enabled, it provides a VSS hardware provider that Nutanix uses to " quiesce " (pause/stabilize) the application
' s I/O and flush pending writes to the disk before the snapshot is taken. If crash-consistent snapshots are working but application-consistent ones are failing, it is a primary indicator that the VSS hooks provided by NGT are either missing, outdated, or not communicating correctly with the Nutanix cluster services. Without NGT, the system cannot verify the internal state of the guest OS, leading to VSS processing errors in third- party backup solutions like Veeam or Commvault. Ensuring NGT is installed and the NGT agent is running within the guest VM is the mandatory first step to resolving any snapshot failure involving application-level consistency.
質問 # 99
An administrator wants to run a test failover and maps the primary production virtual network to the recovery site production virtual network for the test. What are the two most likely outcomes? (Choose two.)
正解:B、D
解説:
The fundamental purpose of a " Test Failover " in Nutanix Disaster Recovery is to provide a non-disruptive way to validate the recovery process. During this test, virtual machines are cloned from their most recent snapshots and powered on at the recovery site. If an administrator incorrectly maps the " Test Network " to the actual " Production Network " (VLAN/Subnet) at the recovery site, they create two significant risks.
First, this configuration can lead to immediate IP address conflicts. Because the test VMs have the exact same IP addresses as the live production VMs, having them active on the same logical production network will disrupt routing and potentially cause service outages for real users. Second, it defeats the " isolation " between production and test workflows. A valid DR test should occur in a " sandbox " where test applications can crash or exhibit errors without any possibility of affecting the live environment. By using the production network, the administrator is effectively running a " live " test on the production infrastructure, which is a dangerous violation of standard BCDR best practices. To avoid these outcomes, the administrator must map the test network to a dedicated, isolated VLAN or overlay network at the recovery AZ that has no physical or logical path back to the production segment.
質問 # 100
A VM is protected in an Async Protection Policy with a schedule for every 1 hour. The replications are completing successfully every hour. The VM hosts a critical application and cannot afford any data loss. The administrator unprotects the VM from the Async Policy and protects the VM in a Synchronous policy. The administrator also notices that the VM is not entering the " Sync " state and is stuck in syncing for a long time. The administrator notices the error in the logs:
Enabling stretch for entity TestVM failed while notifying vm service due to error Acropolis failed to handle VmSyncRepEnable request for VM TestVM Failed to connect to remote Anduril What port needs to be allowed between the clusters to fix the issue?
正解:C
解説:
In a Nutanix environment, Synchronous replication (including Metro Availability and Synchronous Protection Policies) relies on a specialized service known as Anduril to manage the real-time mirroring and state transitions of virtual machines. While standard asynchronous replication primarily uses ports 2009 (Stargate) for data transfer and 2020 (Cerebro) for metadata and replication management, synchronous replication introduces additional requirements for low-latency communication between the Anduril services on the source and destination clusters.
The error message " Failed to connect to remote Anduril " specifically indicates that the local cluster ' s management plane is unable to communicate with the remote cluster ' s synchronous replication manager.
TCP port 2036 is the dedicated port for cross-cluster communication between Anduril services. This port is used to negotiate the " stretch " of the VM across sites, coordinate the initial sync, and maintain the health heartbeat required for high-availability failover decisions. If port 2036 is blocked by a physical or virtual firewall between the clusters, the " VmSyncRepEnable " request will time out or fail, preventing the VM from ever entering the " Sync " (Active-Active) state. Troubleshooting synchronous replication always begins with verifying that the 5ms latency requirement is met and that port 2036 is open alongside the standard ports 2009 and 2020 to ensure both data and control traffic can flow without interruption between availability zones.
質問 # 101
An administrator is troubleshooting a hung replication. When checking the replication status, the complete percent and bytes completed do not increase. The administrator checks the Stargate logs on the destination cluster and confirms the writes are failing with " nfs status 28 " . Checking the container info on the destination cluster, free space on the container is 0. The administrator confirms that there is sufficient space available in the storage pool. What could be the reason for free space on the container to be 0?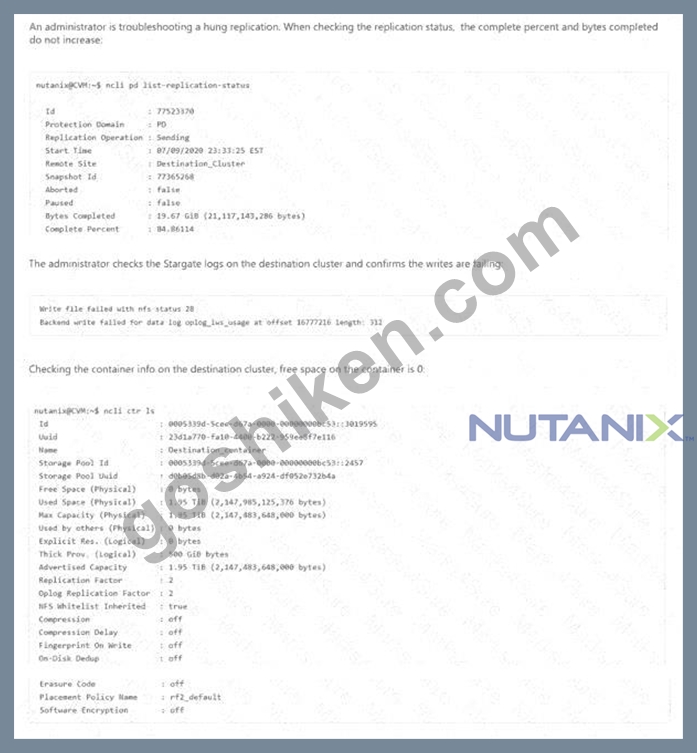
正解:A
解説:
In a Nutanix environment, " Advertised Capacity " is a logical limit (a quota) that an administrator can set on a specific storage container. Even if the physical storage pool has terabytes of free space, if a container ' s advertised capacity is reached, the hypervisor and the Nutanix services will perceive the container as being
100% full.
In this troubleshooting scenario, the " nfs status 28 " error code is a standard indicator for " No space left on device " . Since the administrator confirmed the pool is healthy, the logical limit on the container is the only remaining bottleneck. Replication jobs will " hang " because the destination Stargate service cannot write the incoming data blocks to a container that reports zero free space. To resolve this, the administrator must either increase the advertised capacity value in Prism or remove the limit entirely to allow the container to consume the available physical space in the pool. This highlights a common configuration " trap " where logical quotas-intended for multi-tenant management-can inadvertently block critical BCDR processes like replication if not monitored or sized correctly according to the protected VM growth.
質問 # 102
......
Nutanix NCP-BC-7.5認定試験の難しさで近年にほとんどの受験生は資格認定試験に合格しなっかたと良く知られます。だから、我々社の有効な試験問題集は長年にわたりNutanix NCP-BC-7.5認定資格試験問題集作成に取り組んだIT専門家によって書いてます。実際の試験に表示される質問と正確な解答はあなたのNutanix NCP-BC-7.5認定資格試験合格を手伝ってあげます。
NCP-BC-7.5試験: https://www.goshiken.com/Nutanix/NCP-BC-7.5-mondaishu.html