What's more, part of that Actual4Exams Databricks-Certified-Data-Engineer-Associate dumps now are free: https://drive.google.com/open?id=19cKnuvbZ5VLWfTuj56Rx0AY2YfoI2OPb
There is no exaggeration that you can be confident about your coming exam just after studying with our Databricks-Certified-Data-Engineer-Associate preparation materials for 20 to 30 hours. Tens of thousands of our customers have benefited from our Databricks-Certified-Data-Engineer-Associate Exam Dumps and passed their exams with ease. The data showed that our high pass rate is unbelievably 98% to 100%. Without doubt, your success is 100% guaranteed with our Databricks-Certified-Data-Engineer-Associate training guide.
| Section | Objectives |
|---|---|
| Data Governance and Quality | - Data access control and governance - Unity Catalog basics - Data quality concepts and management |
| Data Ingestion and ELT Development | - Handling structured and semi-structured data - ETL patterns and transformations - Data ingestion using Spark SQL and PySpark |
| Data Processing and Transformations | - Delta Lake fundamentals (tables, transactions, optimization) - Apache Spark SQL operations (joins, aggregations, filtering) - User-defined functions (UDFs) - PySpark DataFrame transformations |
| Productionizing Data Pipelines | - Scheduling and monitoring jobs - Databricks Workflows / Jobs orchestration - Pipeline deployment and operationalization |
| Databricks Lakehouse Platform Fundamentals | - Workspace, architecture, and core platform concepts - Clusters, notebooks, and basic Databricks environment usage |
>> Databricks-Certified-Data-Engineer-Associate Valid Exam Voucher <<
By sitting in these scenarios, you will be able to kill test anxiety. As a result, you will take the final Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) exam with no fear. The web-based Databricks-Certified-Data-Engineer-Associate practice exam software not only works on Windows but also on Linux, iOS, Mac, and Android. Furthermore, this online software of the Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) practice test is compatible with Internet Explorer, MS Edge, Chrome, Firefox, Safari, and Opera.
NEW QUESTION # 124
A data engineer is onboarding a new bronze ingestion pipeline in Databricks with Unity Catalog.
The team wants Databricks to handle storage layout, apply platform optimizations over time, and simplify lifecycle management so that when a table is dropped, its underlying data is also cleaned up according to Databricks-managed retention policies.
Which table type should the data engineer create for these ingestion tables?
Answer: D
Explanation:
Managed tables allow Unity Catalog and Databricks to control both metadata and underlying data storage, enabling automatic optimizations, simplified lifecycle management, and cleanup of data files when tables are dropped according to platform-managed policies.
NEW QUESTION # 125
A data engineer is maintaining an ETL pipeline code with a GitHub repository linked to their Databricks account. The data engineer wants to deploy the ETL pipeline to production as a databricks workflow. Which approach should the data engineer use?
Answer: B
Explanation:
The best practice for deploying ETL pipelines to production is to use Databricks Asset Bundles (DAB) with GitHub integration. DAB provides a declarative YAML-based structure for defining workflows and resources, supports CI/CD, and integrates seamlessly with GitHub, enabling version-controlled, automated deployments to production.
NEW QUESTION # 126
A data engineer is designing a data pipeline. The source system generates files in a shared directory that is also used by other processes. As a result, the files should be kept as is and will accumulate in the directory. The data engineer needs to identify which files are new since the previous run in the pipeline, and set up the pipeline to only ingest those new files with each run.
Which of the following tools can the data engineer use to solve this problem?
Answer: A
Explanation:
Auto Loader is a tool that can incrementally and efficiently process new data files as they arrive in cloud storage without any additional setup. Auto Loader provides a Structured Streaming source called cloudFiles, which automatically detects and processes new files in a given input directory path on the cloud file storage. Auto Loader also tracks the ingestion progress and ensures exactly-once semantics when writing data into Delta Lake. Auto Loader can ingest various file formats, such as JSON, CSV, XML, PARQUET, AVRO, ORC, TEXT, and BINARYFILE. Auto Loader has support for both Python and SQL in Delta Live Tables, which are a declarative way to build production-quality data pipelines with Databricks. Reference: What is Auto Loader?, Get started with Databricks Auto Loader, Auto Loader in Delta Live Tables
NEW QUESTION # 127
A global retail company sells products across multiple categories (e.g.. Electronics, Clothing) and regions (e.
g.. North. South, East. West). The sales team has provided the data engineer with a PySpark dataframe named sales_df as below and the team wants the data engineer to analyze the sales data to help them make strategic decisions.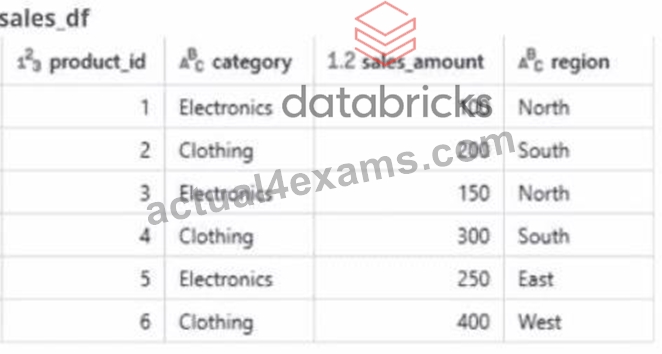
Answer: B
NEW QUESTION # 128
Which of the following must be specified when creating a new Delta Live Tables pipeline?
Answer: D
Explanation:
Option E is the correct answer because it is the only mandatory requirement when creating a new Delta Live Tables pipeline. A pipeline is a data processing workflow that contains materialized views and streaming tables declared in Python or SQL source files. Delta Live Tables infers the dependencies between these tables and ensures updates occur in the correct order. To create a pipeline, you need to specify at least one notebook library to be executed, which contains the Delta Live Tables syntax. You can also specify multiple libraries of different languages within your pipeline. The other options are optional or not applicable for creating a pipeline. Option A is not required, but you can optionally provide a key-value pair configuration to customize the pipeline settings, such as the storage location, the target schema, the notifications, and the pipeline mode.
Option B is not applicable, as the DBU/hour cost is determined by the cluster configuration, not the pipeline creation. Option C is not required, but you can optionally specify a storage location for the output data from the pipeline. If you leave it empty, the system uses a default location. Option D is not required, but you can optionally specify a location of a target database for the written data, either in the Hive metastore or the Unity Catalog.
Tutorial: Run your first Delta Live Tables pipeline, What is Delta Live Tables?, Create a pipeline, Pipeline configuration.
NEW QUESTION # 129
......
Believe that users will get the most satisfactory answer after consultation on our Databricks-Certified-Data-Engineer-Associate exam questions. Our online service staff is professionally trained, and users' needs about Databricks-Certified-Data-Engineer-Associate test guide can be clearly understood by them. The most complete online service of our company will be answered by you, whether it is before the purchase of Databricks-Certified-Data-Engineer-Associate training guide or the installation process, or after using the Databricks-Certified-Data-Engineer-Associate latest questions, no matter what problem the user has encountered. We will give you the best service and suggestion on the Databricks-Certified-Data-Engineer-Associate study material.
Test Databricks-Certified-Data-Engineer-Associate Cram: https://www.actual4exams.com/Databricks-Certified-Data-Engineer-Associate-valid-dump.html
DOWNLOAD the newest Actual4Exams Databricks-Certified-Data-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=19cKnuvbZ5VLWfTuj56Rx0AY2YfoI2OPb