What's more, part of that ExamDiscuss SPLK-2002 dumps now are free: https://drive.google.com/open?id=1MqCqUFSIxs-x1eqwWSabb_hsLQ78Lcxf
ExamDiscuss serves as a most important source of IT certification information. You can find learning materials and study guides. If you are interesting in our ExamDiscuss Splunk SPLK-2002 exam dumps, you can depend on our ExamDiscuss to make a sound choice. ExamDiscuss Splunk SPLK-2002 test packed so much with the latest information about the certification training. By using our ExamDiscuss Splunk SPLK-2002 practice test, you have made preparations for the exam.
| Section | Objectives |
|---|---|
| Managing Search Heads | - Explain the configuration of search heads - Describe search head pooling and clustering - Describe the deployment of apps to search heads |
| Data Collection and Ingestion | - Describe data collection techniques - Explain the use of Indexers and Heavy Forwarders - Describe data routing and filtering |
| Introducing Splunk Architecture | - Describe the relationship between components - Identify Splunk components - Identify the roles of each component |
| Monitoring and Scaling a Splunk Deployment | - Describe scaling strategies - Explain resource allocation and performance tuning - Identify monitoring tools and dashboards |
| Troubleshooting a Splunk Deployment | - Explain the use of internal logs - Identify common issues and error messages - Describe troubleshooting techniques |
| Managing Forwarders | - Identify configuration methods - Explain forwarder management - Describe the types of forwarders |
| Configuring Distributed Search | - Define search head clustering - Explain the role of search heads and indexers - Describe the operation of distributed search |
| Planning and Designing a Splunk Deployment | - Describe the key planning and design considerations - Determine the appropriate license volume and type - List the data and resource requirements |
| Managing Indexers and Indexer Clusters | - Describe indexer cluster architecture - Explain the management of indexer configurations - Describe methods for troubleshooting indexer clusters |
>> Test SPLK-2002 Preparation <<
There are a lot of excellent experts and professors in our company. The high quality of the SPLK-2002 study materials from our company resulted from their constant practice, hard work and their strong team spirit. After a long period of research and development, our SPLK-2002 study materials have been the leader study materials in the field. We have taken our customers’ suggestions of the SPLK-2002 Study Materials seriously, and according to these useful suggestions, we have tried our best to perfect the SPLK-2002 study materials from our company just in order to meet the need of these customers well.
NEW QUESTION # 101
When should multiple search pipelines be enabled?
Answer: B
Explanation:
Explanation/Reference: https://answers.splunk.com/answers/617608/can-we-increase-parallelingestionpipelines-in-a-
he.html
NEW QUESTION # 102
(Which of the following must be included in a deployment plan?)
Answer: B
Explanation:
According to Splunk's Deployment Planning and Implementation Guidelines, one of the most critical elements of a Splunk deployment plan is a comprehensive data source inventory and current logging details.
This information defines the scope of data ingestion and directly influences sizing, architecture design, and licensing.
A proper deployment plan should identify:
* All data sources (such as syslogs, application logs, network devices, OS logs, databases, etc.)
* Expected daily ingest volume per source
* Log formats and sourcetypes
* Retention requirements and compliance constraints
This data forms the foundation for index sizing, forwarder configuration, and storage planning. Without a well-defined data inventory, Splunk architects cannot accurately determine hardware capacity, indexing load, or network throughput requirements.
While stakeholder mapping, topology diagrams, and continuity plans (Options A, B, D) are valuable in a broader IT project, Splunk's official guidance emphasizes logging details and source inventory as mandatory for a deployment plan. It ensures that the Splunk environment is properly sized, licensed, and aligned with business data visibility goals.
References (Splunk Enterprise Documentation):
* Splunk Enterprise Deployment Planning Manual - Data Source Inventory Requirements
* Capacity Planning for Indexer and Search Head Sizing
* Planning Data Onboarding and Ingestion Strategies
* Splunk Architecture and Implementation Best Practices
NEW QUESTION # 103
When troubleshooting a situation where some files within a directory are not being indexed, the ignored files are discovered to have long headers. What is the first thing that should be added to inputs.conf?
Answer: D
Explanation:
* inputs.conf is a configuration file that contains settings for various types of data inputs, such as files, directories, network ports, scripts, and so on1.
* initCrcLength is a setting that specifies the number of characters that the input uses to calculate the CRC (cyclic redundancy check) of a file1. The CRC is a value that uniquely identifies a file based on its content2.
* crcSalt is another setting that adds a string to the CRC calculation to force the input to consume files that have matching CRCs1. This can be useful when files have identical headers or when files are renamed or rolled over2.
* When troubleshooting a situation where some files within a directory are not being indexed, the ignored files are discovered to have long headers, the first thing that should be added to inputs.conf is to increase the value of initCrcLength. This is because by default, the input only performs CRC checks against the first 256 bytes of a file, which means that files with long headers may have matching CRCs and be skipped by the input2. By increasing the value of initCrcLength, the input can use more characters from the file to calculate the CRC, which can reduce the chances of CRC collisions and ensure that different files are indexed3.
* Option C is the correct answer because it reflects the best practice for troubleshooting this situation.
Option A is incorrect because decreasing the value of initCrcLength would make the CRC calculation less reliable and more prone to collisions. Option B is incorrect because adding a crcSalt with a static string would not help differentiate files with long headers, as they would still have matching CRCs. Option D is incorrect because adding a crcSalt with the <SOURCE> attribute would add the full directory path to the CRC calculation, which would not help if the files are in the same directory2.
References:
1: inputs.conf - Splunk Documentation 2: How the Splunk platform handles log file rotation 3: Solved:
Configure CRC salt - Splunk Community
NEW QUESTION # 104
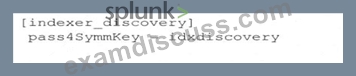
Which of the following server. conf stanzas indicates the Indexer Discovery feature has not been fully configured (restart pending) on the Master Node?



Answer: A
Explanation:
The Indexer Discovery feature enables forwarders to dynamically connect to the available peer nodes in an indexer cluster. To use this feature, the manager node must be configured with the [indexer_discovery] stanza and a pass4SymmKey value. The forwarders must also be configured with the same pass4SymmKey value and the master_uri of the manager node. The pass4SymmKey value must be encrypted using the splunk
_encrypt command. Therefore, option A indicates that the Indexer Discovery feature has not been fully configured on the manager node, because the pass4SymmKey value is not encrypted. The other options are not related to the Indexer Discovery feature. Option B shows the configuration of a forwarder that is part of an indexer cluster. Option C shows the configuration of a manager node that is part of an indexer cluster. Option D shows an invalid configuration of the [indexer_discovery] stanza, because the pass4SymmKey value is not encrypted and does not match the forwarders' pass4SymmKey value12
1: https://docs.splunk.com/Documentation/Splunk/9.1.2/Indexer/indexerdiscovery 2: https://docs.splunk.com
/Documentation/Splunk/9.1.2/Security
/Secureyourconfigurationfiles#Encrypt_the_pass4SymmKey_setting_in_server.conf
NEW QUESTION # 105
A single-site indexer cluster has a replication factor of 3, and a search factor of 2. What is true about this cluster?
Answer: B
Explanation:
A single-site indexer cluster is a group of Splunk Enterprise instances that index and replicate data across the cluster1. A bucket is a directory that contains indexed data, along with metadata and other information2. A replication factor is the number of copies of each bucket that the cluster maintains1. A search factor is the number of searchable copies of each bucket that the cluster maintains1. A searchable copy is a copy that contains both the raw data and the index files3. A search head is a Splunk Enterprise instance that coordinates the search activities across the peer nodes1.
Option D is the correct answer because it reflects the definitions of replication factor and search factor. The cluster will ensure that there are at least three copies of each bucket, one on each peer node, to satisfy the replication factor of 3. The cluster will also ensure that there are at least two searchable copies of each bucket, one primary and one searchable, to satisfy the search factor of 2. The primary copy is the one that the search head uses to run searches, and the searchable copy is the one that can be promoted to primary if the original primary copy becomes unavailable3.
Option A is incorrect because it confuses the replication factor and the search factor. The cluster will ensure there are at least three copies of each bucket, not two, to meet the replication factor of 3. The cluster will ensure there are at least two copies of searchable metadata, not three, to meet the search factor of 2.
Option B is incorrect because it uses the wrong terms. The cluster will ensure there are at least, not at most, three copies of each bucket, to meet the replication factor of 3. The cluster will ensure there are at least, not at most, two copies of searchable metadata, to meet the search factor of 2.
Option C is incorrect because it has nothing to do with the replication factor or the search factor. The cluster does not limit the number of search heads that can access the bucket at the same time. The search head can search across multiple clusters, and the cluster can serve multiple search heads1.
1: The basics of indexer cluster architecture - Splunk Documentation 2: About buckets - Splunk Documentation 3: Search factor - Splunk Documentation
NEW QUESTION # 106
......
Every day is new beginning; we will have a good mood. Hot and outstanding IT certification will be a good beginning for your IT career road. Splunk SPLK-2002 current exam content will be a strong helper for you. If you want to realize your dream and get a certification, ExamDiscuss provide the best valid Splunk SPLK-2002 Current Exam Content materials to help you pass tests. And you will have a great progress in a short time.
Test SPLK-2002 Score Report: https://www.examdiscuss.com/Splunk/exam/SPLK-2002/
DOWNLOAD the newest ExamDiscuss SPLK-2002 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1MqCqUFSIxs-x1eqwWSabb_hsLQ78Lcxf