ValidTorrent can provide a shortcut for you and save you a lot of time and effort. ValidTorrent will provide good training tools for your Microsoft Certification DP-800 Exam and help you pass Microsoft certification DP-800 exam. If you see other websites provide relevant information to the website, you can continue to look down and you will find that in fact the information is mainly derived from our ValidTorrent. Our ValidTorrent provide the most comprehensive information and update fastest.
| Section | Objectives |
|---|---|
| Integrate AI capabilities with database systems | - Use Azure AI services with database workloads - Implement AI-assisted data processing |
| Monitor, troubleshoot, and maintain solutions | - Troubleshooting data pipeline issues - Monitoring database health and performance |
| Design and implement data solutions | - Design database solutions using Azure data services - Implement data storage and data processing solutions |
| Develop and manage database solutions | - Optimize performance and scalability - Ensure security and compliance of data solutions |
>> Reliable DP-800 Exam Vce <<
The Microsoft DP-800 Exam Questions give you a complete insight into each chapter and an easy understanding with simple and quick-to-understand language. The Microsoft DP-800 exam dumps are the best choice to make. The common problem Microsoft DP-800 Exam applicants face is seeking updated and real Microsoft DP-800 practice test questions to prepare successfully for the cherished Developing AI-Enabled Database Solutions DP-800 certification exam.
NEW QUESTION # 79
You need to recommend a solution to lesolve the slow dashboard query issue. What should you recommend?
Answer: C
Explanation:
The best recommendation is B because the slow query filters on FleetId and returns LastUpdatedUtc , EngineStatus , and BatteryHealth . A nonclustered index with FleetId as the key column allows the optimizer to perform an index seek instead of a clustered index scan, and including the other selected columns makes the index covering , which reduces extra lookups and I/O. Microsoft's SQL Server indexing guidance states that a nonclustered index with included columns can significantly improve performance when all query columns are available in the index, because the optimizer can satisfy the query directly from the index.
The query is:
SELECT VehicleId, LastUpdatedUtc, EngineStatus, BatteryHealth
FROM dbo.VehicleHealthSummary
WHERE FleetId = @FleetId
ORDER BY LastUpdatedUtc DESC;
Among the given choices, FleetId is the most important search argument because it appears in the WHERE predicate. Microsoft's index design guidance recommends putting columns used for searching in the key and using nonkey included columns to cover the rest of the query efficiently.
Why the other options are weaker:
* A is not appropriate because changing the clustered index to LastUpdatedUtc would not target the main filter predicate on FleetId, and a table can have only one clustered index.
* C makes LastUpdatedUtc the key, which is poor for a query whose primary filter is FleetId.
* D is not the right answer here because the query requirement does not specify only recent rows, and filtered indexes are meant for a well-defined subset; this option also uses a time-based expression that is not aligned to the stated query pattern.
Strictly speaking, the most optimal design for both filtering and ordering would usually be a composite key like (FleetId, LastUpdatedUtc), but since that is not one of the available options, B is the correct exam answer.
NEW QUESTION # 80
You need to meet the development requirements for the FeedbackJson column How should you complete the Transact SQL query? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.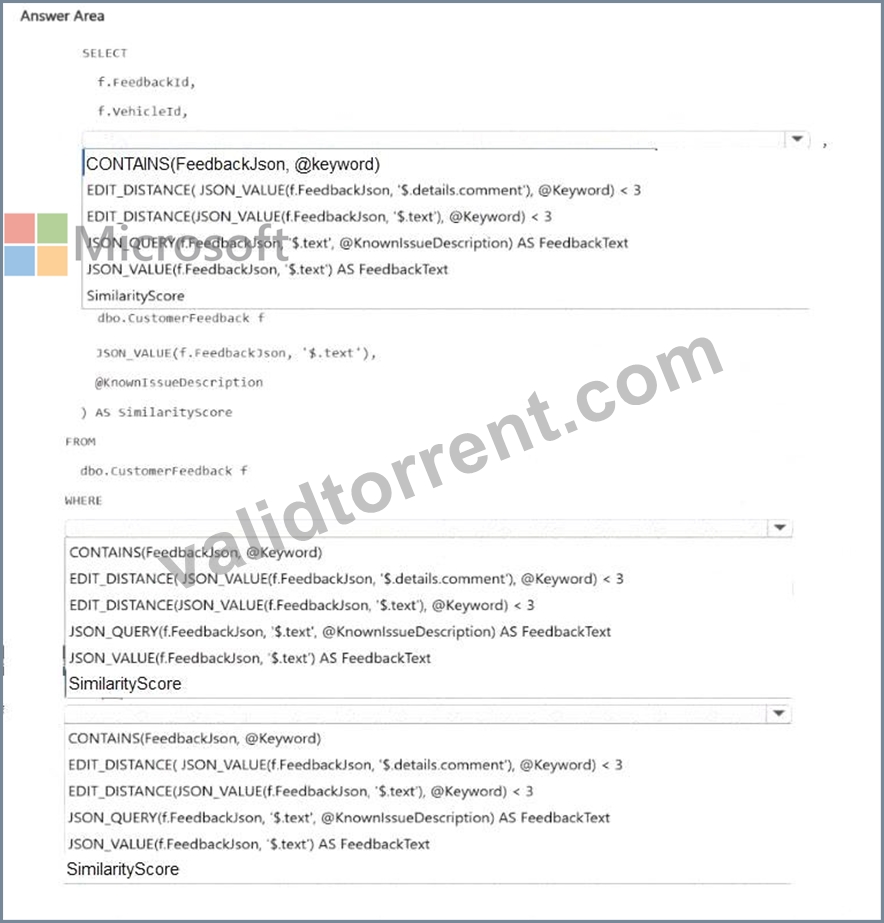
Answer:
Explanation: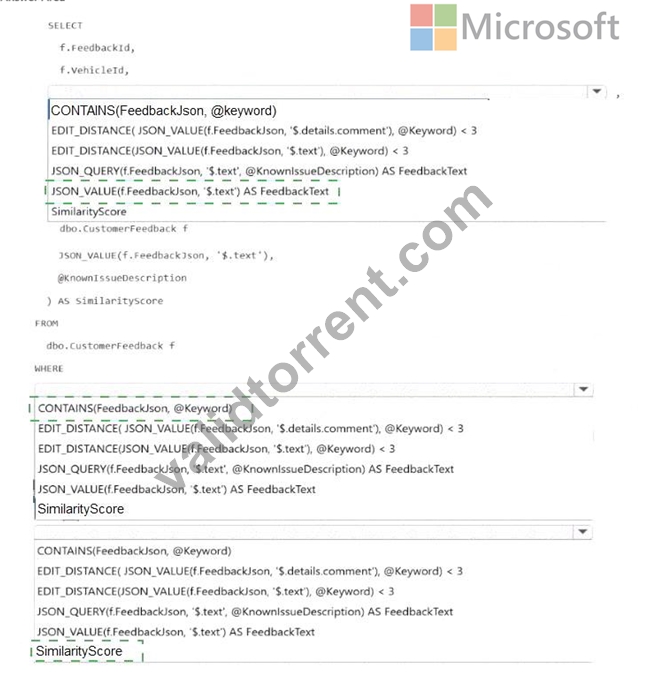
Explanation:
JSON_VALUE(f.FeedbackJson, ' $.text ' ) AS FeedbackText
CONTAINS(FeedbackJson, @Keyword)
SimilarityScore
These three selections are the correct way to complete the query because they align exactly with the stated requirements for the FeedbackJson column.
First, to extract the customer feedback text from the JSON document , the correct expression is JSON_VALUE(f.FeedbackJson, ' $.text ' ) AS FeedbackText . Microsoft documents that JSON_VALUE is used to extract a scalar value from JSON, while JSON_QUERY is used for returning an object or array .
Since $.text is the textual feedback string, JSON_VALUE is the correct function.
Second, to filter rows where the JSON text contains a keyword , the best choice is CONTAINS (FeedbackJson, @Keyword) . The scenario explicitly states that FeedbackJson already has a full-text index
, and Microsoft documents that CONTAINS is the full-text predicate used in the WHERE clause to search full-text indexed character data. That makes it more appropriate than using EDIT_DISTANCE for keyword filtering.
Third, to order the results by similarity score, highest first , the correct item is SimilarityScore in the ORDER BY clause, which would be paired with DESC in the query. This matches the requirement to sort by the computed fuzzy similarity value. The DP-800 study guide specifically includes writing queries that use fuzzy string matching functions such as EDIT_DISTANCE, which supports the earlier computed SimilarityScore expression in the query.
NEW QUESTION # 81
You have an Azure SQL database That contains a table named dbo.Products, dbo.Products contains three columns named Embedding Category, and Price. The Embedding column is defined as VECTOR(1536).
You use Ai_GENERME_EMBEDOINGS and VECTOR_SEARCH to support semantic search and apply additional filters on two columns named Category and Price.
You plan to change the embedding model from text-embedding-ada-002 to text-embedding-3-smalL Existing rows already contain embeddings in the Embedding column.
You need to implement the model change. Applications must be able to use VECTOR_SEARCH without runtime errors.
What should you do first?
Answer: C
NEW QUESTION # 82
You have a SQL database in Microsoft Fabric that contains a column named Payload. pay load stores customer data in JSON documents that have the following format.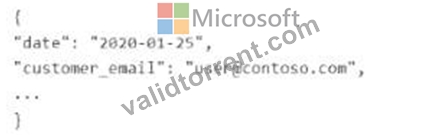
Data analysis shows that some customers have subaddressing in their email address, for example, user1+promo@contoso.com.
You need to return a normalized email value that removes the subaddressing, for example, user! + promo@contoso.com must be normalized to userl@contoso.com.
Which Transact SQL expression should you use?