BTW, DOWNLOAD part of ExamDiscuss DP-800 dumps from Cloud Storage: https://drive.google.com/open?id=1PRYUDLv-zezCwar4vlw3EIrglDdmRLH-
At least 2/3 top 500 global companies choose Microsoft electronic business software products as their key products or daily use. So if you get a Microsoft certification you will be outstanding over others. Candidates want to pass DP-800 exam, the fastest and convenient method is to use our DP-800 Study Guide, many candidates choose this method to pass exam. You also can make this as practice exam materials or use test engine file to test like the real test scene.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
Do you often envy the colleagues around you can successfully move to a larger company to achieve the value of life? Are you often wondering why your classmate, who has scores similar to yours, can receive a large company offer after graduation and you are rejected? In fact, what you lack is not hard work nor luck, but DP-800 Guide question. With DP-800 question torrent, you will suddenly find the joy of learning and you will pass the professional qualification exam very easily.
NEW QUESTION # 80
You have an Azure SQL database named SalesDB that contains a table named dbo. Articles, dbo.Articles contains two million articles with embeddmgs. The articles are updated frequently throughout the day.
You query the embeddings by using VECTOR_SEARQi
Users report that semantic search results do NOT reflect the updates until the following day.
Vou need to ensure that the embeddings are updated whenever the articles change. The solution must minimize CPU usage on SalesDB Which embedding maintenance method should you implement?
Answer: D
Explanation:
The correct answer is B because the problem is not the vector search operator itself. The problem is that embeddings are becoming stale when article content changes . Microsoft documents that change data capture (CDC) tracks insert, update, and delete operations on source tables, which makes it the right mechanism to identify only the rows that changed.
This also best satisfies the requirement to minimize CPU usage on SalesDB . With CDC, the database only records the row changes, and the embedding regeneration work can be moved to an external process such as an Azure Functions app. That avoids running embedding generation inline inside the database for every update and avoids repeatedly recalculating embeddings for unchanged rows. In contrast, an hourly full-table regeneration would be extremely wasteful on a table with two million frequently updated articles, and a trigger that calls embedding generation per row would push expensive AI work into the transactional path of the database.
Option A is incorrect because changing from VECTOR_SEARCH to VECTOR_DISTANCE does not regenerate embeddings; it only changes the retrieval method. Microsoft states that VECTOR_SEARCH is the ANN search function, while VECTOR_DISTANCE performs exact distance calculation, so neither option addresses stale embedding data.
So the right design is:
* use CDC to detect only changed articles,
* process those changes outside the database,
* regenerate embeddings only for changed rows,
* write back the refreshed embeddings for current semantic search results.
NEW QUESTION # 81
You have an Azure SQL database that contains a table named dbo.ManualChunks. dbo.HonualChunks contains product manuals A retrieval query already returns the top five matching chunks as nvarchar(max) text.
You need to call an Azure OpenAI REST endpomt for chat completions. The request body must include both the user question and theretiieved chunks.
You write the following Transact-SQL code.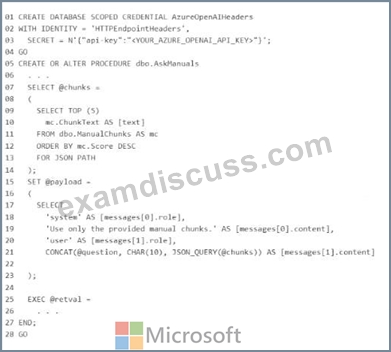
What should you insert at line 22?
Answer: C
Explanation:
The correct insertion at line 22 is FOR JSON PATH, WITHOUT_ARRAY_WRAPPER .
The request body for the Azure OpenAI chat completions call must be a single JSON object containing the messages array with both the system/user content and the retrieved chunks. Microsoft documents that FOR JSON PATH is the preferred way to shape JSON output, especially when you want precise control over nested property names like messages[0].role and messages[1] .content.
The key detail is WITHOUT_ARRAY_WRAPPER . By default, FOR JSON returns results enclosed in square brackets as a JSON array. Microsoft documents that WITHOUT_ARRAY_WRAPPER removes those brackets so a single JSON object is produced instead. That is exactly what is needed here for @payload, because the stored procedure is building one request body, not an array of request bodies.
NEW QUESTION # 82
You have an Azure SQL database.
You need to create a scalar user-defined function (UDF) that returns the number of whole years between an input parameter named @OrderDate and the current date/time as a single positive integer. The function must be created in Azure SQL Database.
You write the following code.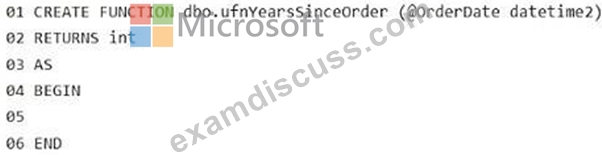
What should you insert at line 05?
Answer: A
Explanation:
Use RETURN to produce the scalar value of the function.
In an Azure SQL Database scalar function (a user-defined function that returns a single value), you must use the RETURN statement to return the scalar value.
The RETURN statement immediately terminates the function's execution and returns the value specified in its argument to the calling statement or procedure. The value returned must be of the data type specified in the RETURNS clause of the function definition.
The second argument to DATEDIFF should be @OrderDate as it is the start date, while the third argument is the end date, which is the current date.
Note:
DATEDIFF (Transact-SQL)
This function returns the count (as a signed integer value) of the specified datepart boundaries crossed between the specified startdate and enddate.
Syntax
DATEDIFF ( datepart , startdate , enddate )
Arguments
datepart
Specifies the units in which DATEDIFF reports the difference between the startdate and enddate.
Commonly used datepart units include month or second.
Reference:
https://learn.microsoft.com/en-us/sql/t-sql/functions/datediff-transact-sql
NEW QUESTION # 83
You have an Azure SQL database that contains a table named knowledgebase, knowledgebase stores human resources (HR) policy documents and contains columns named title, content, category, and embedding.
You have an application named App1. App1 queries two relational tables named employee_pnofiles and benefits_enrollnent that contain HR data. App1 hosts a chatbot that calls a large language model (LLM) directly.
Users report that the chatbot answers general HR questions correctly but provides outdated or incorrect answers when policies change. The chatbot also fails to answer questions that reference internal policy documents by title or category.
You need to recommend a Retrieval Augmented Generation (RAG) solution to resolve the chatbot issues.
What should you recommend? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.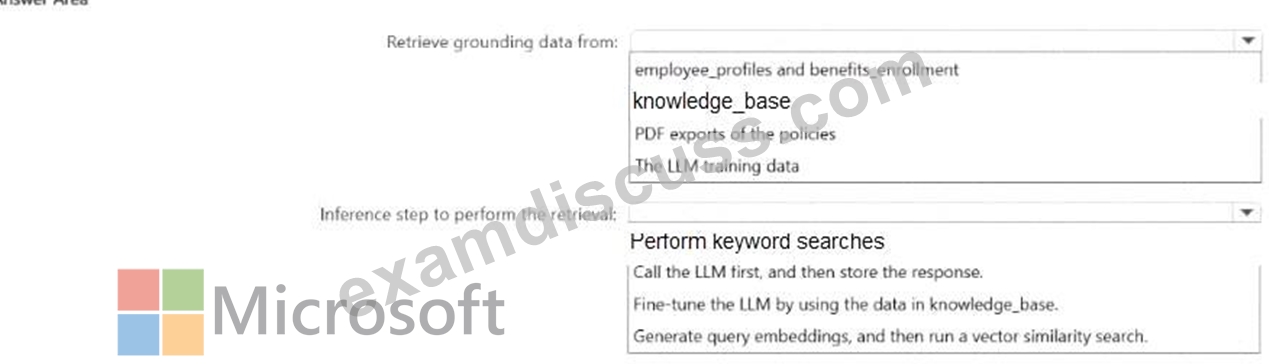
Answer:
Explanation: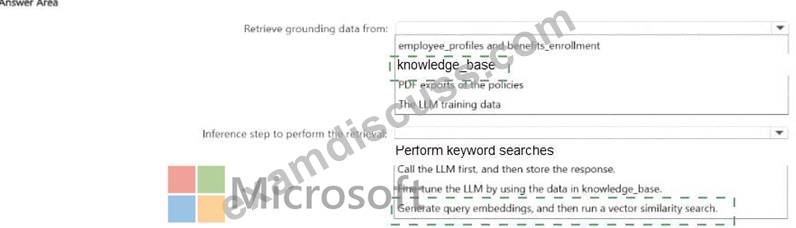
Explanation: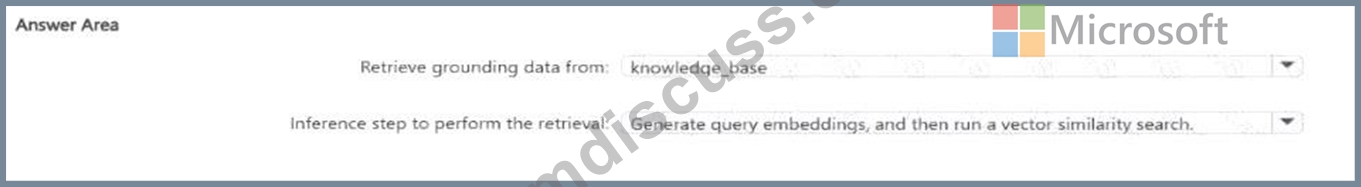
The correct recommendation is to retrieve grounding data from knowledge_base and, at inference time, generate query embeddings and run a vector similarity search .
The chatbot currently answers some general HR questions but fails when policies change and when users ask about internal policy documents by title or category . That is exactly the kind of problem RAG is meant to solve: ground the LLM in the organization's proprietary content instead of relying on the model's training data or unrelated transactional tables. Microsoft's RAG guidance states that RAG extends LLMs by grounding responses in your own content and that, for agentic retrieval, knowledge bases unify knowledge sources for retrieval.
So the grounding data should come from knowledge_base , because that table stores the HR policy documents and already includes fields like title, content, category, and embedding. Those are the fields directly tied to the missing and outdated policy answers. By contrast:
* employee_profiles and benefits_enrollment are operational HR tables, not the authoritative store for policy-document grounding.
* PDF exports of the policies would be inferior to querying the indexed/structured knowledge base already prepared for retrieval.
* The LLM training data is specifically the wrong source when the issue is outdated internal content.
For the retrieval step, Microsoft's guidance says to use embeddings for vector queries and notes that vector similarity search matches concepts, not exact terms . This is especially important because users ask about policy documents by title or category and also phrase questions in ways that might not exactly match document wording. Generating a query embedding and then running a vector similarity search is the appropriate retrieval step in a RAG pipeline.
NEW QUESTION # 84
You have an Azure SQL database that contains a table named Rooms. Rooms was created by using the following transact-SQL statement.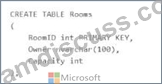
You discover that some records in the Rooms table contain NULL values for the Owner field. You need to ensure that all future records have a value for the Owner field. What should you add?
Answer: A
Explanation:
The table definition allows Owner to be nullable because it was created as Owner nvarchar(100) without NOT NULL. Since the question asks what to add so that future rows must have a value, a check constraint such as CHECK (Owner IS NOT NULL) is the appropriate choice. Microsoft documents that check constraints validate future INSERT and UPDATE operations against the constraint condition.
The other options do not solve the requirement:
* A foreign key enforces referential integrity, not non-null entry by itself.
* A nonclustered index does not require values to be present.
* A unique constraint prevents duplicate values but still does not serve as the right mechanism here for enforcing presence across future writes. Microsoft's constraint documentation also notes that primary- key columns are implicitly NOT NULL, which helps distinguish nullability enforcement from other constraint types.
NEW QUESTION # 85
......
It is worth mentioning that, the simulation test is available in our software version. With the simulation test, all of our customers will get accustomed to the DP-800 exam easily, and get rid of bad habits, which may influence your performance in the real DP-800 exam. In addition, the mode of DP-800 learning guide questions and answers is the most effective for you to remember the key points. During your practice process, the DP-800 Test Questions would be absorbed, which is time-saving and high-efficient. Considerate 24/7 service shows our attitudes, we always consider our candidates’ benefits and we guarantee that our DP-800 test questions are the most excellent path for you to pass the exam.
Pass4sure DP-800 Exam Prep: https://www.examdiscuss.com/Microsoft/exam/DP-800/
BTW, DOWNLOAD part of ExamDiscuss DP-800 dumps from Cloud Storage: https://drive.google.com/open?id=1PRYUDLv-zezCwar4vlw3EIrglDdmRLH-