DOWNLOAD the newest Pass4SureQuiz AI-103 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1I8bdrssJKajku5QQS87YIAKV3H2DeyO8
In order to help you save more time, we will transfer AI-103 test guide to you within 10 minutes online after your payment and guarantee that you can study these materials as soon as possible to avoid time waste. We believe that time is the most valuable things in the world. This is why we are dedicated to improve your study efficiency and production. Moreover if you have a taste ahead of schedule, you can consider whether our AI-103 Exam Torrent is suitable to you or not, thus making the best choice. What’s more, if you become our regular customers, you can enjoy more membership discount and preferential services.
| Section | Weight | Objectives |
|---|---|---|
| Implement computer vision solutions | 10–15% | - Implement image analysis and processing
|
| Implement information extraction and knowledge mining | 10–15% | - Extract structured data from documents
|
| Implement text and speech analysis solutions | 10–15% | - Implement natural language processing
|
| Implement generative AI and agentic solutions | 30–35% | - Design and implement intelligent agents
|
| Plan and manage Azure AI solutions | 25–30% | - Design Azure AI infrastructure
|
why you need the AI-103 exam questions to help you pass the exam more smoothly and easily? There are a lot of the benefits of the AI-103 study guide. Firstly, a little practice can perfect you to answer all AI-103 new questions in the real exam scenario. Secondly, another amazing benefit of doing the AI-103 Practice Tests is that you can easily come to know the real exam format and develop your skills to answer all questions without any confusion. Hence, you can develop your pass percentage.
NEW QUESTION # 15
You have a Microsoft Foundry resource named Al1 that hosts three deployments of the GPT 3.5 model. Each deployment is optimized for a unique workload.
You plan to deploy three apps. Each app will access AM by using the REST API and will use the deployment that was optimized for the apps intended workload.
You need to provide each app with access to All and the appropriate deployment. The solution must ensure that only the apps can access AH.
What should you use to provide access to AI1. and what should each app use to connect to its appropriate deployment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.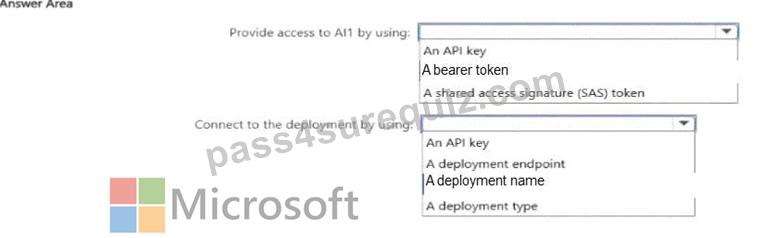
Answer:
Explanation: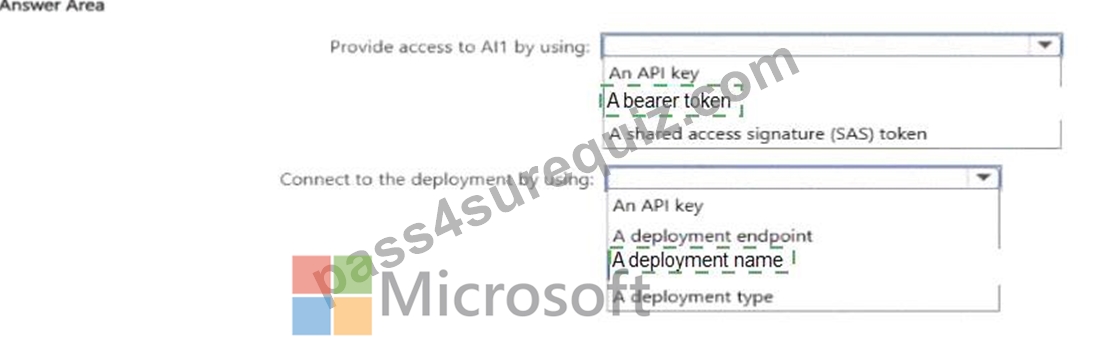
Explanation: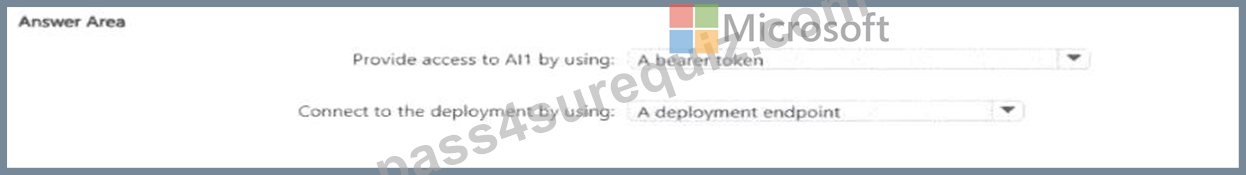
Use Microsoft Entra ID authentication and pass an OAuth 2.0 bearer token in the REST request's Authorization header. Assign the required inference role, such as Cognitive Services User , only to each application's managed identity or service principal. This authenticates the applications as distinct security principals and supports resource-scoped RBAC, auditing, token expiration, and immediate access revocation.
Microsoft recommends Entra ID for production workloads because API keys are static, resource-wide secrets that cannot identify individual callers or provide granular authorization.
Each application must specify its appropriate deployment name when making an inference request. Foundry deployments assign a unique name and configuration to each deployed model. In the deployment-level REST API, that name appears in the request route:
/openai/deployments/{deployment-name}/chat/completions
The resource endpoint and authentication mechanism can remain common across all three applications, while the deployment name directs each request to the GPT-3.5 deployment optimized for that application's workload. A deployment type describes capacity or provisioning characteristics and does not select a particular deployed model.
Study Guide alignment: configure authentication, managed identities, RBAC, model deployments, and REST-based model consumption.
NEW QUESTION # 16
You have a Microsoft Foundry project that contains an agent.
The agent uses Azure AI Search as the retriever.
You plan to ingest PDF into an Azure AI Search index to ensure that the agent can ground responses in texts in both documents and embedded images.
Users require citations that link to the source files.
You need to ensure that during indexing, the images are extracted into a structure that can be used as input for the built-in optical character recognition (OCR) skill.
Which indexing approach should you use?
Answer: C
Explanation:
The best configuration step an indexer to extract image data into a normalized_images collection.
Cracking Foundation: In Azure AI Search, document cracking automatically separates textual data from visual content. To make embedded images available to image-processing skills like OCR, the indexer must be explicitly configured with an imageAction configuration property (such as generateNormalizedImages or generateNormalizedImagePerPage).
Input Structure for OCR: This indexer step extracts embedded images from the PDF and restructures them into an internal normalized_images array (accessed via the path
/document/normalized_images/*). The built-in OCR skill strictly requires this normalized image collection format as its input payload.
Incorrect:
[Not C]
Content Field Limitations: The /document/content field generated during document cracking holds only the raw text extracted from the file. It does not contain the binary data or structural properties of embedded images.
Targeting Errors: Pointing an OCR skill directly at the raw text content field would fail to analyze the actual images, leaving the agent unable to ground answers in visual elements like diagrams or embedded infographics.
Reference:
https://docs.azure.cn/en-us/search/tutorial-skillset
NEW QUESTION # 17
You need to configure personalized user interactions for Agent1 based on the business requirements. What should you include in the solution?
Answer: B
Explanation:
Agent1 requires memory because the business requirement explicitly states that the agent must retain conversation context and recall relevant information during future interactions. Microsoft Foundry Agent Service memory provides persistent knowledge that can be retained and retrieved across separate conversations, sessions, devices, and workflows. It can store meaningful information extracted from prior interactions, including user preferences, relevant facts, and summarized context, and then retrieve that information when personalizing later responses.
Short-term memory maintains context within the current conversation. Long-term memory supports continuity across future sessions, which directly addresses Contoso's requirement. Memory scopes should be associated with individual user identities so that one customer's stored information cannot be retrieved during another customer's interaction.
Guardrails enforce safety or behavioral restrictions but do not provide conversation recall. Tools enable the agent to access external systems, while instructions define the agent's role and operating boundaries. Neither tools nor instructions persist user-specific information across sessions.
The AI-103 Study Guide maps this requirement to choose appropriate memory, tool, and knowledge integration services and build agents that integrate retrieval, function calling, and conversation memory
.
NEW QUESTION # 18
You have a Microsoft Foundry project that generates short promotional product videos.
After several clips are approved, reviewers notice a small watermark in the top-right corner of some videos.
You need to remove the watermark without regenerating the videos.
What should you do?
Answer: C
Explanation:
The correct action to take is to apply a mask-based inpainting edit to the affected part of the video.
This is the only option that directly modifies the existing, approved video files. Inpainting allows you to isolate the specific top-right corner using a mask and seamlessly blend it with the surrounding pixels to erase the watermark without altering or regenerating the rest of the video footage.
Reference:
https://openart.ai/features/ai-video-inpainting/
NEW QUESTION # 19
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have a multimodal AI generative model that accepts image uploads and uses extracted image text to generate responses.
You discover that users can upload unsafe images and embed hidden instructions into images to manipulate the model.
You need to implement controls to mitigate the risk.
Solution: You configure a prompt shield for user prompts.
Does this meet the goal?
Answer: A
Explanation:
Correct:
* You configure a prompt shield for documents.
Prompt Shield for Documents: Highly Effective (Critical Defense)
How it helps: This shield specifically scans untrusted, third-party data inputs (like external documents or text extracted from uploaded images).
Mechanism: It evaluates the extracted image text before it is sent to the LLM to identify hidden jail
* You configure a prompt shield for user prompts.
Prompt Shield for User Prompts: Partially Effective (Defense in Depth)
How it helps: This shield targets direct jailbreak attempts written manually by the user in the text prompt field accompanying the upload.
Mechanism: It prevents the user from typing supporting instructions that prime the model to execute the hidden instructions found within the image.
* You configure image moderation to block unsafe content before processing the images.
Implementing rigorous image moderation is one of the most effective ways to secure multimodal AI systems against these threats. Moderation acts as a necessary gatekeeper, preventing malicious inputs from ever reaching the generative model.
Incorrect:
* You configure protected material detection.
Protected Material Detection: Ineffective for this Threat
Why it does not help: This feature is designed to scan model outputs to prevent the generation of copyrighted text, proprietary source code, or licensed imagery.
Limitation: It does not scan inputs for adversarial instructions and will not prevent a user from manipulating the model's logic.
Reference:
https://www.upgrad.com/blog/what-is-multimodal-ai/
https://learn.microsoft.com/en-us/azure/ai-services/content-safety/concepts/jailbreak-detection
NEW QUESTION # 20
......
The Pass4SureQuiz is a leading platform that has been helping the Developing AI Apps and Agents on Azure (AI-103) exam candidates in exam preparation and boosting their confidence to pass the final AI-103 exam. The Pass4SureQuiz is offering real, valid, and updated Developing AI Apps and Agents on Azure (AI-103) practice questions. These Developing AI Apps and Agents on Azure (AI-103) exam questions are verified by Microsoft AI-103 exam trainers. They work closely and check all Developing AI Apps and Agents on Azure (AI-103) exam dumps one by one and they ensure the best possible answers to Developing AI Apps and Agents on Azure (AI-103) exam dumps.
AI-103 Certification Test Questions: https://www.pass4surequiz.com/AI-103-exam-quiz.html
2026 Latest Pass4SureQuiz AI-103 PDF Dumps and AI-103 Exam Engine Free Share: https://drive.google.com/open?id=1I8bdrssJKajku5QQS87YIAKV3H2DeyO8