Our company has realized that a really good product is not only reflected on the high quality but also the consideration service. So we not only provide all people with the DP-750 test training materials with high quality, but also we are willing to offer the fine service system for the customers, these guarantee the customers can get. If you decide to buy the DP-750 learn prep from our company, we are glad to answer your all questions about the DP-750 study materials. We believe that you will make the better choice for yourself by our consideration service on the DP-750 exam questions.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30-35% | - Data quality and validation
|
| Topic 2: Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Topic 3: Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
| Topic 4: Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
The updated Microsoft DP-750 exam questions are available in three different but high-in-demand formats. With the aid of practice questions for the Microsoft DP-750 exam, you may now take the exam at home. You can understand the fundamental ideas behind the Microsoft DP-750 Test Dumps using the goods. The Microsoft DP-750 exam questions are affordable and updated, and you can use them without any guidance.
NEW QUESTION # 23
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! contains three tasks named Task1, Task2. and Task3.
If Task1 fails, Task2 and Task3 must be prevented from running. Successfully completed tasks must NOT rerun during recovery.
You need to configure Job1 to support controlled failure handling and recovery What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.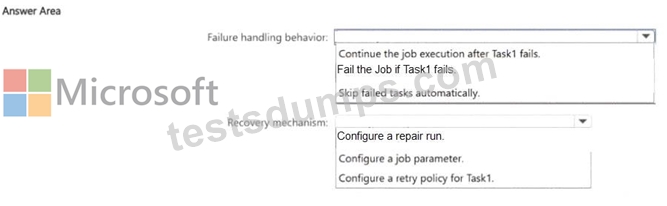
Answer:
Explanation: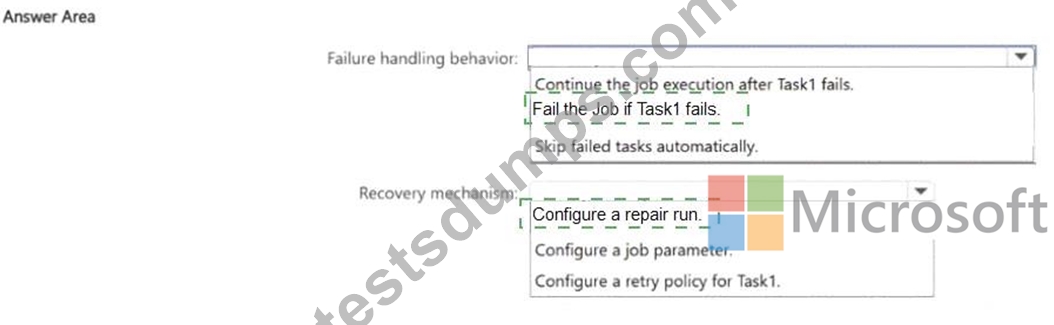
Explanation:
Two configurations are needed:
Task dependency with 'All succeeded' run condition: Set Task2 and Task3 to depend on Task1. Change the run condition on Task2 and Task3 to 'All succeeded' - this means they only execute when all their upstream dependencies (Task1) have succeeded. If Task1 fails, both downstream tasks are skipped automatically, not run with failed inputs.
Repair run for recovery: Lakeflow Jobs' Repair Run feature lets you re-execute only the tasks that failed (Task1 in this case) and their dependents (Task2 and Task3 if they were skipped), while skipping Task1 and any other tasks that already completed successfully. Successfully completed tasks are never re-executed during repair - their results are reused as-is.
Together these provide both controlled failure propagation (nothing runs downstream of a failure) and efficient recovery.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/repair-job-failures
NEW QUESTION # 24
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Table1. Table1 stores customer data.
You need to implement a data retention solution that meets the following requirements:
- Deleted data must be retained for 30 days to support audits.
- Deleted data that is older than 30 days must be removed permanently.
- The solution must minimize administrative effort
Which two properties should you configure? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,B
Explanation:
To configure an Azure Databricks managed Delta table to retain deleted data for 30 days and minimize administrative overhead, you must set the following table properties:
delta.logRetentionDuration: Set this to interval 30 days. This property controls how long the transaction log history is kept, which is essential for audit trails and time travel.delta.
deletedFileRetentionDuration: Set this to interval 30 days. This property determines the threshold for when deleted data files become eligible for permanent removal by the VACUUM command.
Reference:
https://docs.databricks.com/aws/en/delta/history
NEW QUESTION # 25
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to implement a daily batch data process that requires complex and highly customized Python transformations. The solution must minimize additional complexity.
What should you include in the solution?
Answer: A
Explanation:
A Databricks notebook provides the flexibility required to implement complex, highly customized Python and PySpark transformations. Scheduling that notebook as a Lakeflow Jobs task supplies native daily orchestration, monitoring, retries, and compute management without introducing another service. Azure Data Factory data flows are oriented toward visually designed transformations and would add external orchestration complexity for logic already implemented most naturally in Python. A continuous job is inappropriate because the workload runs once per day rather than continuously. Spark Declarative Pipelines is effective for declarative batch and streaming ETL, but it is less direct when the core requirement emphasizes highly customized procedural Python transformations. A notebook task therefore provides the necessary programming freedom while keeping scheduling and operation inside Azure Databricks.
NEW QUESTION # 26
You have an Azure Databricks workspace that contains the objects shown in the following table.
Name | Type
Catalog1 | Catalog
Schema1 | Schema
Sales1 | Table
Notebook1 | Notebook
Space1 | AI/BI Genie space
Users often use the following words to refer to a sale: transaction, event, order, and invoice.
You need to create a knowledge store. The solution must ensure that when the users use any of the words in Space1, Genie queries the Sales1 table. Any other Genie spaces must remain unaffected.
To which object should you add the instructions?
Answer: D
Explanation:
The instructions must be added to Space1 because a Genie knowledge store is scoped to the individual Genie space, now called a Genie Agent. Adding synonyms and business-language instructions there teaches Space1 that "transaction," "event," "order," and "invoice" refer to sales information in Sales1. The configuration affects only that Genie space, satisfying the requirement that other spaces remain unchanged. Adding instructions to Sales1 or Schema1 would modify shared Unity Catalog metadata and could affect other consumers of those objects. Notebook1 is unrelated to the semantic instructions used by Genie when converting natural-language questions into SQL. Genie knowledge stores contain space-specific definitions, synonyms, join relationships, SQL expressions, and prompt-matching guidance without changing the underlying Unity Catalog objects. Microsoft Learn
NEW QUESTION # 27
You have an Azure Databricks workspace named Workspace1.
You create a compute cluster named Cluser1 that will be used to ingest data.
You need to install the required libraries on Cluster1. The solution must use Unity Catalog for access control.
What should you do?
Answer: C
Explanation:
A Unity Catalog volume is the appropriate location because it provides governed file storage with permissions managed through Unity Catalog. After uploading the library package to the volume, it can be configured as a cluster library on Cluster1. This approach permits centralized access control, auditing, and lifecycle management. Option A installs the library without placing its source under Unity Catalog governance. Option B provides notebook-scoped dependency management but does not, by itself, satisfy the requirement that Unity Catalog control access to the library artifact. A schema is a logical container for tables, views, functions, models, and volumes; a library file cannot be uploaded directly to the schema itself, eliminating option D. Unity Catalog volumes explicitly support storing cluster libraries and job dependencies. Microsoft Learn
NEW QUESTION # 28
......
As you all know that practicing with the wrong preparation material will waste your valuable money and many precious study hours. So you need to choose the most proper and verified preparation material with caution. Preparation material for the DP-750 exam questions from TestsDumps helps to break down the most difficult concepts into easy-to-understand examples. Also, you will find that all the included questions are based on the last and updated DP-750 Exam Dumps version. We are sure that using TestsDumps's Microsoft Exam Questions preparation material will support you in passing the DP-750 exam with confidence.
Study DP-750 Material: https://www.testsdumps.com/DP-750_real-exam-dumps.html