P.S. Kostenlose 2026 Google Professional-Machine-Learning-Engineer Prüfungsfragen sind auf Google Drive freigegeben von ITZert verfügbar: https://drive.google.com/open?id=1A3OI6boOMEECt7rhbqrseSUGX8yMF6yI
Warum wählen viele Leute die Schulungsunterlagen zur Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung von ITZert? Es gibt auch andere Websites, die Schulungsressourcen zur Professional-Machine-Learning-Engineer Zertifizierungsprüfung bietet. Unser ITZert stellt Ihnen die echten Prüfungsmaterialien zur Verfügung. Unser Eliteteam, Zertifizierungsexperten, Techniker und berühmte Linguisten bearbeiten die neueste Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung. Deshalb klicken Sie ITZert Website, wenn Sie die Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung bestehen wollen. Mit ITZert können Sie Ihren Traum Schritt für Schritt verwirklichen.
Die Google Professional Machine Learning Engineer Zertifizierungsprüfung besteht aus Multiple-Choice-Fragen und leistungsbezogenen Szenarien, die Ihre Fähigkeit testen, Machine-Learning-Modelle auf der Google Cloud Platform zu entwerfen und umzusetzen. Die Prüfung umfasst eine Vielzahl von Themen, einschließlich Datenverarbeitung, Modelltraining und -bewertung sowie Bereitstellung von Machine-Learning-Modellen in einer Produktionsumgebung.
>> Professional-Machine-Learning-Engineer Fragen&Antworten <<
Die Zertifizierungsprüfung von Google Professional-Machine-Learning-Engineer ist ein unerlässlicher Teil im IT-Bereich. Aber wie kann man in kurzer Zeit bessere Resulate bei weniger Einsatz erzielen? ITZert ist Ihre beste Wahl. Die Schulungsunterlagen zur Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung von ITZert sind von erfahrenen IT-Experten entworfen, deren Korrktheit zweifellos ist. Wenn Sie noch besorgt sind, können Sie einen Teil von den kostenlosen Testaufgaben und Antworten herunterladen, bevor Sie die Schulungsunterlagen von ITZert benutzen.
Die Google Professional Machine Learning Engineer-Prüfung ist eine Zertifizierung auf fortgeschrittenem Niveau, die von Google Cloud angeboten wird. Diese Zertifizierung richtet sich an Personen, die umfangreiche Erfahrung in Machine Learning haben und Experten auf diesem Gebiet werden möchten. Die Prüfung soll die Fähigkeiten des Kandidaten im Entwurf, der Entwicklung und dem Deployment von Machine-Learning-Modellen mit Hilfe von Google Cloud-Technologien testen.
260. Frage
You have deployed a scikit-learn model to a Vertex Al endpoint using a custom model server. You enabled auto scaling; however, the deployed model fails to scale beyond one replica, which led to dropped requests.
You notice that CPU utilization remains low even during periods of high load. What should you do?
Antwort: A
Begründung:
Auto scaling is a feature that allows you to automatically adjust the number of prediction nodes based on the traffic and load of your deployed model 1 . However, auto scaling depends on the CPU utilization of your prediction nodes, which is the percentage of CPU resources used by your model server 1 . If your CPU utilization is low, even during periods of high load, it means that your model server is not fully utilizing the available CPU resources, and thus au to scaling will not trigger more replicas 2 .
On e possible reason for low CPU utilization is that your model server is using a single worker process to handle prediction requests 3 . A worker process is a subprocess that runs your model code and handles prediction requests 3 . If you have only one worker process, it can only handle one request at a time, which can lead to dropped requests when the traffic is high 3 . To increase the CPU utilization and the throughput of your model server, you can increase the number of worker processes, which will allow your model server to handle multiple requests in parallel 3 .
To increase the number of workers i n your model server, you need to modify your custom model server code and use the --workers flag to specify the number of worker processes you want to use 3 . For example, if you are using a Gunicorn server, you can use the following command to start your model server with four worker processes:
gunicorn --bind :$PORT --workers 4 --threads 1 --timeout 60 main:app
By increasing the number of workers in your model server, you can increase the CPU utilization of your prediction nodes, and thus enable auto scaling to scale beyond one replica.
The other options are not suitable for your scenario, because they either do not address the root cause of low CPU utilization, such as attaching a GPU or scheduling scaling, or they do not enable auto scaling, such as increasing the minReplicaCount, which is a fixed number of nodes that will always run regardless of the traffi c 1 .
:
Scaling prediction nodes | Vertex AI | Google Cloud
Troubleshooting | Vertex AI | Google Cloud
Using a custom prediction routine with online prediction | Vertex AI | Google Cloud
261. Frage
You work for a telecommunications company. You're building a model to predict which customers may fail to pay their next phone bill. The purpose of this model is to proactively offer at-risk customers assistance such as service discounts and bill deadline extensions. The data is stored in BigQuery and the predictive features that are available for model training include:
- Customer_id
- Age
- Salary (measured in local currency)
- Sex
- Average bill value (measured in local currency)
- Number of phone calls in the last month (integer)
- Average duration of phone calls (measured in minutes)
You need to investigate and mitigate potential bias against disadvantaged groups, while preserving model accuracy.
What should you do?
Antwort: D
262. Frage
You manage a team of data scientists who use a cloud-based backend system to submit training jobs. This system has become very difficult to administer, and you want to use a managed service instead. The data scientists you work with use many different frameworks, including Keras, PyTorch, theano. Scikit-team, and custom libraries. What should you do?
Antwort: A
Begründung:
A cloud-based backend system is a system that runs on a cloud platform and provides services or resources to other applications or users. A cloud-based backend system can be used to submit training jobs, which are tasks that involve training a machine learning model on a given dataset using a specific framework and configuration1 However, a cloud-based backend system can also have some drawbacks, such as:
* High maintenance: A cloud-based backend system may require a lot of administration and management, such as provisioning, scaling, monitoring, and troubleshooting the cloud resources and services. This can be time-consuming and costly, and may distract from the core business objectives2
* Low flexibility: A cloud-based backend system may not support all the frameworks and libraries that the data scientists need to use for their training jobs. This can limit the choices and capabilities of the data scientists, and affect the quality and performance of their models3
* Poor integration: A cloud-based backend system may not integrate well with other cloud services or
* tools that the data scientists need to use for their machine learning workflows, such as data processing, model deployment, or model monitoring. This can create compatibility and interoperability issues, and reduce the efficiency and productivity of the data scientists.
Therefore, it may be better to use a managed service instead of a cloud-based backend system to submit training jobs. A managed service is a service that is provided and operated by a third-party provider, and offers various benefits, such as:
* Low maintenance: A managed service handles the administration and management of the cloud resources and services, and abstracts away the complexity and details of the underlying infrastructure. This can save time and money, and allow the data scientists to focus on their core tasks2
* High flexibility: A managed service can support multiple frameworks and libraries that the data scientists need to use for their training jobs, and allow them to customize and configure their training environments and parameters. This can enhance the choices and capabilities of the data scientists, and improve the quality and performance of their models3
* Easy integration: A managed service can integrate seamlessly with other cloud services or tools that the data scientists need to use for their machine learning workflows, and provide a unified and consistent interface and experience. This can solve the compatibility and interoperability issues, and increase the efficiency and productivity of the data scientists.
One of the best options for using a managed service to submit training jobs is to use the AI Platform custom containers feature to receive training jobs using any framework. AI Platform is a Google Cloud service that provides a platform for building, deploying, and managing machine learning models. AI Platform supports various machine learning frameworks, such as TensorFlow, PyTorch, scikit-learn, and XGBoost, and provides various features, such as hyperparameter tuning, distributed training, online prediction, and model monitoring.
The AI Platform custom containers feature allows the data scientists to use any framework or library that they want for their training jobs, and package their training application and dependencies as a Docker container image. The data scientists can then submit their training jobs to AI Platform, and specify the container image and the training parameters. AI Platform will run the training jobs on the cloud infrastructure, and handle the scaling, logging, and monitoring of the training jobs. The data scientists can also use the AI Platform features to optimize, deploy, and manage their models.
The other options are not as suitable or feasible. Configuring Kubeflow to run on Google Kubernetes Engine and receive training jobs through TFJob is not ideal, as Kubeflow is mainly designed for TensorFlow-based training jobs, and does not support other frameworks or libraries. Creating a library of VM images on Compute Engine and publishing these images on a centralized repository is not optimal, as Compute Engine is a low-level service that requires a lot of administration and management, and does not provide the features and integrations of AI Platform. Setting up Slurm workload manager to receive jobs that can be scheduled to run on your cloud infrastructure is not relevant, as Slurm is a tool for managing and scheduling jobs on a cluster of nodes, and does not provide a managed service for training jobs.
References: 1: Cloud computing 2: Managed services 3: Machine learning frameworks : [Machine learning workflow] : [AI Platform overview] : [Custom containers for training]
263. Frage
You are going to train a DNN regression model with Keras APIs using this code: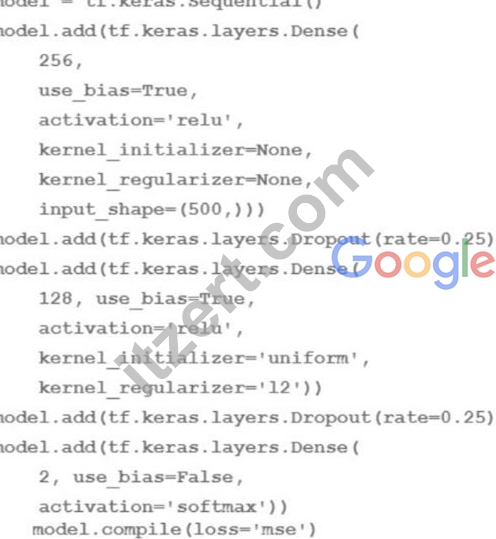
How many trainable weights does your model have? (The arithmetic below is correct.)
Antwort: A
264. Frage
You work for a biotech startup that is experimenting with deep learning ML models based on properties of biological organisms. Your team frequently works on early-stage experiments with new architectures of ML models, and writes custom TensorFlow ops in C++. You train your models on large datasets and large batch sizes. Your typical batch size has 1024 examples, and each example is about 1 MB in size. The average size of a network with all weights and embeddings is 20 GB. What hardware should you choose for your models?
Antwort: B
265. Frage
......
Professional-Machine-Learning-Engineer Simulationsfragen: https://www.itzert.com/Professional-Machine-Learning-Engineer_valid-braindumps.html
Laden Sie die neuesten ITZert Professional-Machine-Learning-Engineer PDF-Versionen von Prüfungsfragen kostenlos von Google Drive herunter: https://drive.google.com/open?id=1A3OI6boOMEECt7rhbqrseSUGX8yMF6yI