
DOWNLOAD the newest DumpsQuestion MLA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=15GrrB9ibw3g_8V9Km0QD8hcePs3SVe5h
We stress the primacy of customers’ interests, and make all the preoccupation based on your needs on the MLA-C01 study materials. We assume all the responsibilities that our MLA-C01 practice braindumps may bring. They are a bunch of courteous staff waiting for offering help 24/7. You can definitely contact them when getting any questions related with our MLA-C01 Preparation quiz. And you will be satified by their professional guidance.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Latest Braindumps MLA-C01 Ebook <<
MLA-C01 exam certification is considered as a standard in measuring your professional skills in your industry. Besides, those possessing the Amazon MLA-C01 certification are more likely to receive higher salaries. So it is very necessary to get MLA-C01 certification. Here, DumpsQuestion MLA-C01 free pdf download can give you some reference. First, you should have preview about the content of MLA-C01 real test. Amazon MLA-C01 contains the comprehensive contents with explanations where is available. With the assist of MLA-C01 training material, you will get success.
NEW QUESTION # 195
An ML engineer is using a training job to fine-tune a deep learning model in Amazon SageMaker Studio. The ML engineer previously used the same pre-trained model with a similar dataset. The ML engineer expects vanishing gradient, underutilized GPU, and overfitting problems.
The ML engineer needs to implement a solution to detect these issues and to react in predefined ways when the issues occur. The solution also must provide comprehensive real-time metrics during the training.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: B
NEW QUESTION # 196
An ML engineer wants to run a training job on Amazon SageMaker AI by using multiple GPUs. The training dataset is stored in Apache Parquet format.
The Parquet files are too large to fit into the memory of the SageMaker AI training instances.
Which solution will fix the memory problem?
Answer: A
Explanation:
Large Parquet files can cause out-of-memory (OOM) issues during training if individual files exceed the memory capacity of the training instances. AWS documentation recommends repartitioning large datasets into smaller files to enable efficient streaming and parallel loading.
By using Apache Spark on Amazon EMR to repartition the Parquet files, the ML engineer can split the dataset into multiple smaller files that can be read incrementally during training. This approach avoids loading a single large file into memory and improves data parallelism.
Attaching larger EBS volumes increases storage capacity but does not solve memory constraints. Switching to memory-optimized instances increases cost and is not necessary when the dataset can be restructured.
SageMaker distributed data parallelism focuses on model parameter synchronization across GPUs, not dataset file size.
AWS best practices explicitly recommend partitioning large Parquet datasets to improve memory efficiency during training.
Therefore, Option B is the correct and AWS-aligned solution.
NEW QUESTION # 197
A company needs to create a central catalog for all the company's ML models. The models are in AWS accounts where the company developed the models initially. The models are hosted in Amazon Elastic Container Registry (Amazon ECR) repositories.
Which solution will meet these requirements?
Answer: B
NEW QUESTION # 198
A company has deployed a model to predict the churn rate for its games by using Amazon SageMaker Studio.
After the model is deployed, the company must monitor the model performance for data drift and inspect the report. Select and order the correct steps from the following list to model monitor actions. Select each step one time. (Select and order THREE.) .
Check the analysis results on the SageMaker Studio console. .
Create a Shapley Additive Explanations (SHAP) baseline for the model by using Amazon SageMaker Clarify.
Schedule an hourly model explainability monitor.
Answer:
Explanation: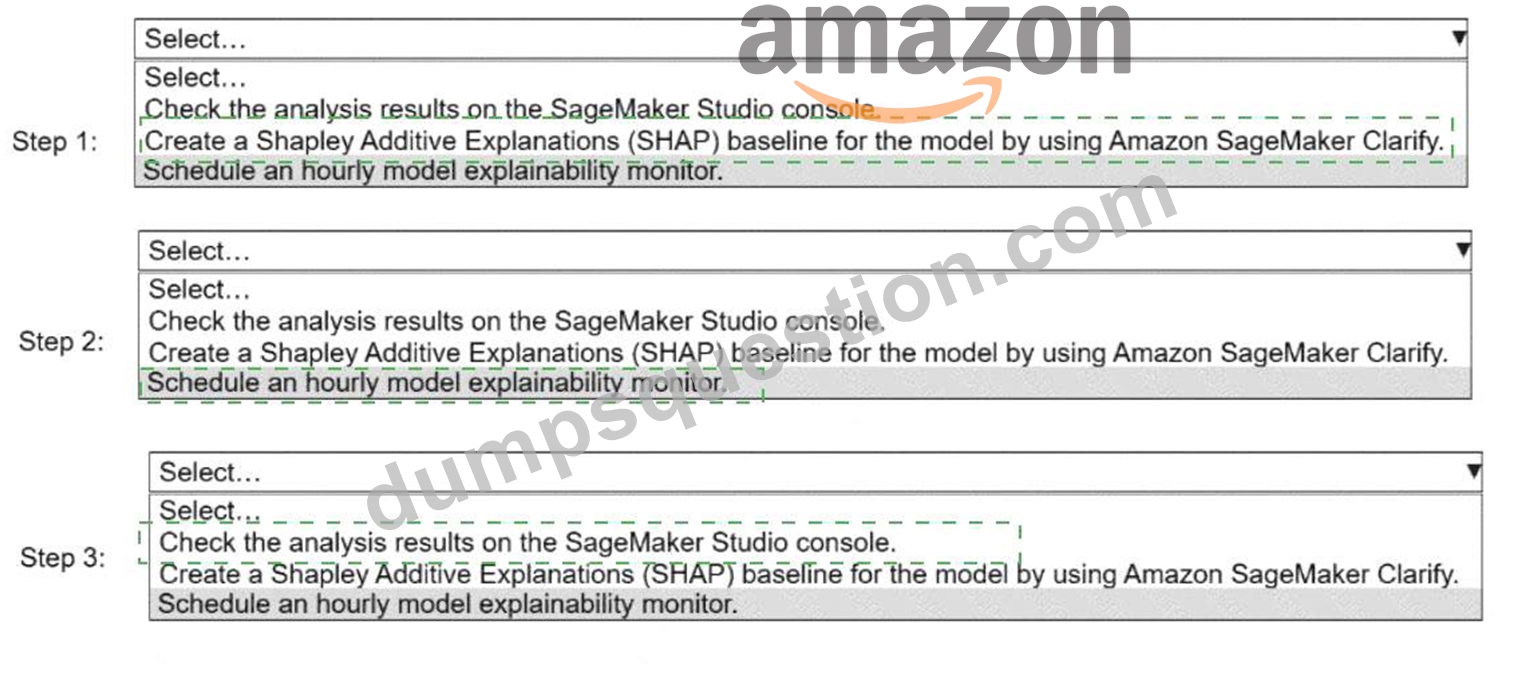
Explanation:
Step 1:
Create a Shapley Additive Explanations (SHAP) baseline for the model by using Amazon SageMaker Clarify.
Step 2:
Schedule an hourly model explainability monitor.
Step 3:
Check the analysis results on the SageMaker Studio console.
When monitoring a deployed model for data drift and explainability, AWS prescribes a specific workflow using SageMaker Clarify and SageMaker Model Monitor:
Create a SHAP baseline (Step 1)Before any monitoring can occur, SageMaker Clarify must establish a baseline explainability configuration. This baseline captures the reference SHAP values for feature importance using training or baseline data. Model Monitor uses this baseline to compare future inferences and detect drift in feature attributions.
Schedule the model explainability monitor (Step 2)After the baseline is created, an explainability monitoring schedule must be configured (hourly in this case). The monitor periodically analyzes inference data, compares it against the SHAP baseline, and generates reports that highlight drift or anomalies in feature contributions.
Inspect results in SageMaker Studio (Step 3)Once monitoring jobs run, SageMaker stores the analysis results in Amazon S3 and surfaces them in the SageMaker Studio console, where engineers can review metrics, violations, and visual reports.
This sequence is mandatory because:
A monitor cannot run without a baseline
Results cannot be reviewed until the monitor executes
NEW QUESTION # 199
A company needs to ingest data from data sources into Amazon SageMaker Data Wrangler. The data sources are Amazon S3, Amazon Redshift, and Snowflake. The ingested data must always be up to date with the latest changes in the source systems.
Which solution will meet these requirements?
Answer: A
Explanation:
Amazon SageMaker Data Wrangler supports both direct and cataloged connections. To ensure data is always up to date, AWS recommends using cataloged connections backed by AWS Glue Data Catalog.
Cataloged connections allow Data Wrangler to reference the source systems dynamically, ensuring that each import reflects the latest data changes without manual reconfiguration. This approach supports Amazon S3, Amazon Redshift, and Snowflake and integrates securely using managed credentials.
Direct connections are point-in-time imports and do not automatically reflect schema or data updates. Glue and Lambda-based solutions introduce unnecessary complexity and operational overhead.
Therefore, using cataloged connections in Data Wrangler is the correct solution.
NEW QUESTION # 200
......
DumpsQuestion AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam questions are the best because these are so realistic! It feels just like taking a real MLA-C01 exam, but without the stress! Our MLA-C01 Practice Test software is the answer if you want to score higher on your real Amazon MLA-C01 certification exam and achieve your academic goals.
MLA-C01 Updated Dumps: https://www.dumpsquestion.com/MLA-C01-exam-dumps-collection.html
P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by DumpsQuestion: https://drive.google.com/open?id=15GrrB9ibw3g_8V9Km0QD8hcePs3SVe5h