With the rapid development of IT technology, the questions in the IT certification exam are also changing. Therefore, Itcertmaster also keeps updating test questions and answers. And if you purchase Itcertmaster Microsoft DP-800 Practice Test materials, we will provide you with free updates for a year. As long as the questions updates, Itcertmaster will immediately send the latest questions and answers to you which guarantees that you can get the latest materials at any time. Itcertmaster can not only help you pass the test, but also help you learn the latest knowledge. Never pass up a good chance to have the substantial materials.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Design and develop database solutions | 35-40% | - Design database solutions
|
| Topic 2: Secure, optimize, and deploy database solutions | 35-40% | - Deploy and maintain solutions
|
| Topic 3: Implement AI capabilities in database solutions | 25-30% | - Use AI-assisted development tools
|
The Microsoft DP-800 exam questions are being updated on a regular basis. As you know the Microsoft DP-800 exam syllabus is being updated on a regular basis. To add all these changes in the Microsoft DP-800 exam dumps we have hired a team of exam experts. They regularly update the DP-800 Practice Questions as per the latest DP-800 exam syllabus. So you have the option to get free Developing AI-Enabled Database Solutions exam questions update for up to 1 year from the date of DP-800 PDF dumps purchase.
NEW QUESTION # 77
Which service enables natural language querying over SQL data?
Answer: A
Explanation:
Azure OpenAI Service allows users to query structured SQL data using natural language via LLMs.
NEW QUESTION # 78
You have an Azure SQL database that stores sales data and contains tables named Sales and Products . Sales contains three columns named SalesDate , ProductKey , and TotalSale .
Sales is 10 TB and is loaded nightly by using a batch process. Most reporting queries scan large portions of Sales , filter on SalesDate or ProductKey , and use SUM() to aggregate TotalSale .
Products is relatively small and is used primarily for point lookups and joins to Sales .
You need to recommend which indexes to create to optimize the reporting queries. The solution must minimize storage requirements.
Which type of index should you recommend for each table? To answer, drag the appropriate index types to the correct tables. Each index type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.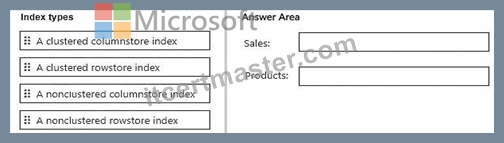
Answer:
Explanation:
Explanation:
* Sales # A clustered columnstore index
* Products # A clustered rowstore index
For Sales , the correct choice is a clustered columnstore index . Microsoft identifies clustered columnstore indexes as the standard storage choice for large fact tables and analytical/data-warehouse workloads . The Sales table is 10 TB, loaded in nightly batches, and its reporting queries scan large portions of the table and perform aggregations such as SUM(TotalSale) . Those are exactly the workload characteristics that benefit from columnstore storage, batch-mode execution, aggregate pushdown, and high compression. Microsoft also notes that clustered columnstore indexes can provide substantial storage reduction compared with traditional uncompressed rowstore structures, which directly supports the requirement to minimize storage requirements .
For Products , the correct choice is a clustered rowstore index . Microsoft states that rowstore B-tree indexes perform best for point lookups, equality searches, and small-range retrieval , whereas columnstore is optimized for large analytical scans. Since Products is relatively small and primarily supports point lookups and joins to Sales , a rowstore structure is the better fit.
A nonclustered columnstore index would retain the underlying rowstore and add another compressed copy of selected columns, increasing storage. That is more appropriate for real-time analytics over an OLTP table, not for this dedicated large analytical fact table.
NEW QUESTION # 79
You have a GitHub Actions workflow that builds and deploys an Azure SQL database. The schema is stored in a GitHub repository as an SDK-style SQL database project.
Following a code review, you discover that you need to generate a report that shows whether the production schema has diverged from the model in source control.
Which action should you add to the pipeline?
Answer: C
Explanation:
To generate a report showing the differences between your source control and the production database, you should use the sql-action (officially Azure/sql-action@v2).
Specifically, you need to set the action parameter to DriftReport.
When configured this way, the action compares your .dacpac file (built from your SQL project) against the target production database. It generates an HTML or XML report detailing any "drift"-- changes made directly to production that aren't in your code.
Reference:
https://learn.microsoft.com/en-us/sql/tools/sqlpackage/sqlpackage-deploy-drift-report
NEW QUESTION # 80
You have a SQL database in Microsoft Fabric that contains a column named Payload. pay load stores customer data in JSON documents that have the following format.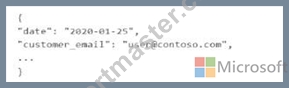
Data analysis shows that some customers have subaddressing in their email address, for example, user1+promo@contoso.com.
You need to return a normalized email value that removes the subaddressing, for example, user! + promo@contoso.com must be normalized to userl@contoso.com.
Which Transact SQL expression should you use?