In comparison to others, Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam dumps are priced at a reasonable price. It is possible to prepare using DP-750 exam using a pdf file anytime according to the hectic routines. If you are confused regarding its quality DP-750 exam dumps, download the free trial to assist you make a final decision prior to purchasing. All exam dumps and patterns are made to follow the style of actual exam dumps. Therefore, it increases your chances of success in the Real DP-750 Exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Topic 2: Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Topic 3: Prepare and process data | 30-35% | - Data ingestion
|
| Topic 4: Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
Our DP-750 test prep attaches great importance to a skilled, trained and motivated workforce as well as the company’s overall performance. Adhere to new and highly qualified DP-750 quiz guide to meet the needs of customer, we are also committed to providing the first -class after-sale service. There will be our customer service agents available 24/7 for your supports; any request for further assistance or information about DP-750 Exam Torrent will receive our immediate attention. And you can contact us online or send us email on the DP-750 training questions.
NEW QUESTION # 82
Hotspot Question
You have an Azure Databricks workspace.
You have an Azure key vault named kv-secure that stores a secret named storageKey. The value of storageKey is managed and updated by the cloud security team at your company.
You need to enable a Databricks notebook named Notebook1 to retrieve the value of storageKey securely at runtime. The solution must follow the principle of least privilege and always retrieve the latest value.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.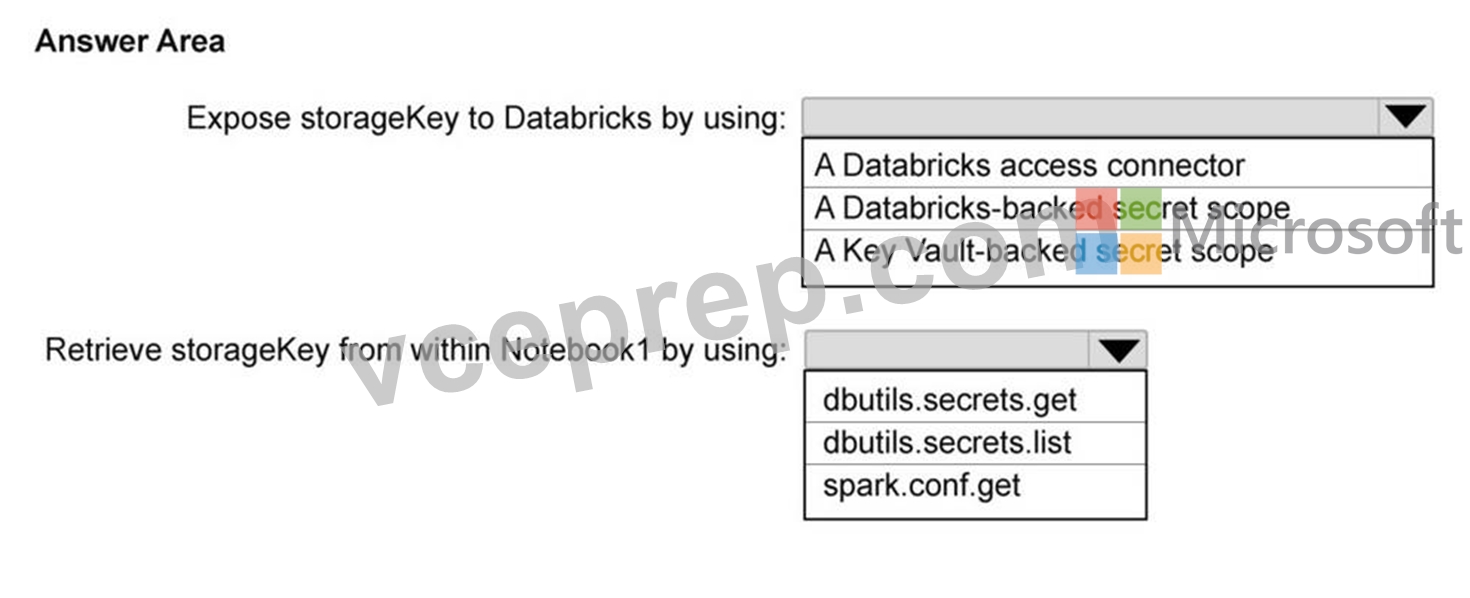
Answer:
Explanation: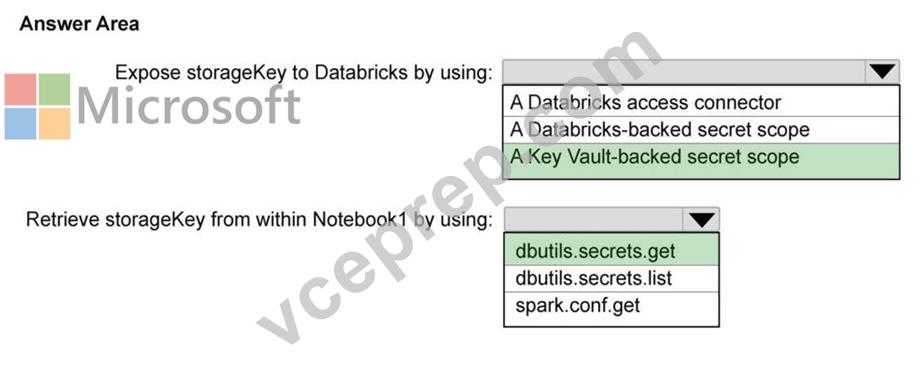
NEW QUESTION # 83
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales.
Sales stores transaction data and contains the following columns:
- transaction_id (string)
- transaction_date (date)
- amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
- amount must be greater than 0.
- transaction_id must never be null.
- Invalid records must be rejected when data is written to the Sales
table.
What should you do?
Answer: B
Explanation:
To enforce these table-level data quality rules and automatically reject any invalid write operations in Azure Databricks, you must configure NOT NULL and CHECK constraints on the Delta table using standard SQL commands.
In Delta Lake, these constraints are enforced instantly on write. If an incoming record violates any of them, the entire transaction fails, and the invalid records are rejected.
1. Enforce transaction_id Cannot Be Null
Add a NOT NULL constraint to the transaction_id column. This blocks any write attempt containing a null identifier.
ALTER TABLE sales_data ALTER COLUMN transaction_id SET NOT NULL;
2. Enforce amount Must Be Greater Than 0
Add a CHECK constraint to the table to validate that the amount values strictly exceed zero.
ALTER TABLE sales_data ADD CONSTRAINT check_amount_positive CHECK (amount > 0); Reference:
https://docs.databricks.com/aws/en/tables/constraints
NEW QUESTION # 84
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two catalogs named Catalog1 and Catalog2.
An external application uses a service principal named SP1 to connect to a SQL warehouse.
You need to ensure that SP1 can query the data in Catalog1 and Catalog2. The solution must follow the principle of least privilege.
Which permissions should you grant to SP1 for the catalogs?
Answer: B
Explanation:
To ensure a service principal can query data in two specific catalogs while maintaining the principle of least privilege, you must assign the following permissions for each catalog:
Unified Catalog Permissions
USE CATALOG on the specific catalog: This is a prerequisite that allows the principal to see the catalog and its child objects.
USE SCHEMA on the schemas containing the data: This allows the principal to interact with the schemas within that catalog.
SELECT on the specific tables or views: This provides the actual read access required to query the data.
Reference:
https://learn.microsoft.com/en-us/purview/data-governance-roles-permissions
NEW QUESTION # 85
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Sales_orders.
Sales_orders stores historical sales data.
You receive a daily CSV file daily that contains new sales records only. The file does NOT contain updates to existing rows.
You need to load the daily data into Sales_orders. The solution must meet the following requirements:
- Preserve the existing data.
- Add only the new records.
- Minimize processing effort.
Which command should include in the loading strategy?
Answer: B
Explanation:
The best command for this scenario is INSERT INTO.
The INSERT INTO command appends new rows directly to the end of an existing Delta table.
Because your daily CSV file contains only new records and zero updates to existing rows, simply appending the data completely satisfies your requirements. It leaves all historical data untouched and requires the absolute lowest processing power because Databricks does not need to scan, modify, or rewrite any existing files.
Incorrect:
The UPDATE command is used to modify values in rows that already exist in the table based on a matching condition. It cannot be used to add entirely new rows to a table, and it requires a heavy scan of the data to find matches, which violates the requirement to keep processing low.
The INSERT OVERWRITE command deletes all the existing historical data in the table (or a specific partition) and replaces it with the data from the new CSV file. Using this would erase your historical sales data.
Reference:
https://medium.com/@jithujosekokken/understanding-data-patterns-in-medallion-architecture-full- incremental-and-change-only-loads-e33db28e51f4
NEW QUESTION # 86
You have an Azure Databricks workspace.
You have an Apache Spark Structured Streaming job named Job1 that processes data continuously and fails periodically due to transient errors.
You need to ensure that Job1 meets the following requirements:
- Resumes processing from the point that Job1 failed
- Minimizes how long it takes to restart Job1
- Minimizes the costs to restart Job1
What should you do?
Answer: D
Explanation:
You must use checkpointing.
Checkpointing is the native Apache Spark mechanism designed specifically to handle failures in Structured Streaming jobs. It saves the exact execution state and progress to cloud storage (like Azure Data Lake Storage), allowing the job to resume precisely where it left off without data loss.
Resumes from Failure Point: The checkpoint directory stores the stream offsets. When restarted, Spark reads these offsets to pick up exactly where it failed.
Minimizes Restart Time: By saving the state, Spark does not need to recompute historical streaming data or re-evaluate the entire stream architecture from scratch.
Minimizes Restart Costs: It prevents the reprocessing of duplicate data, saving valuable cluster compute time and reducing cloud infrastructure costs.
Reference:
https://www.linkedin.com/posts/shilpa-das-ln_what-is-checkpointing-in-spark-checkpointing- activity-7297113790393815041-AhPg
NEW QUESTION # 87
......
There are many benefits after you pass the DP-750 certification such as you can enter in the big company and double your wage. Our DP-750 study materials boost high passing rate and hit rate so that you needn’t worry that you can’t pass the test too much. We provide free tryout before the purchase to let you decide whether it is valuable or not by yourself. To further understand the merits and features of our DP-750 Practice Engine, you should try it first!
DP-750 Test Discount: https://www.vceprep.com/DP-750-latest-vce-prep.html