Are you trying to pass the DP-750 exam to get the longing DP-750 certification? As we know, there are a lot of the advantages of the certification, such as higher salaries, better job positions and so on. Perhaps at this moment, you need the help of our DP-750 Study Materials. As our company's flagship product, it has successfully helped countless candidates around the world to obtain the coveted DP-750 certification.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Topic 2: Prepare and process data | 30–35% | - Optimize and manage data storage
|
| Topic 3: Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Topic 4: Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
Most of the candidates who plan to take the DP-750 certification exam lack updated practice questions to ace it on the first attempt. Due to this, they fail the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) test, losing money and time. And in some cases, applicants fail on the second attempt as well because they don't prepare with DP-750 Actual Exam questions. This results in not only the loss of resources but also the motivation of the candidate.
NEW QUESTION # 65
You have an Azure Databricks workspace.
You have an Apache Spark Structured Streaming job named Job1 that processes data continuously and fails periodically due to transient errors.
You need to ensure that Job1 meets the following requirements:
- Resumes processing from the point that Job1 failed
- Minimizes how long it takes to restart Job1
- Minimizes the costs to restart Job1
What should you do?
Answer: B
Explanation:
You must use checkpointing.
Checkpointing is the native Apache Spark mechanism designed specifically to handle failures in Structured Streaming jobs. It saves the exact execution state and progress to cloud storage (like Azure Data Lake Storage), allowing the job to resume precisely where it left off without data loss.
Resumes from Failure Point: The checkpoint directory stores the stream offsets. When restarted, Spark reads these offsets to pick up exactly where it failed.
Minimizes Restart Time: By saving the state, Spark does not need to recompute historical streaming data or re-evaluate the entire stream architecture from scratch.
Minimizes Restart Costs: It prevents the reprocessing of duplicate data, saving valuable cluster compute time and reducing cloud infrastructure costs.
Reference:
https://www.linkedin.com/posts/shilpa-das-ln_what-is-checkpointing-in-spark-checkpointing- activity-7297113790393815041-AhPg
NEW QUESTION # 66
You have an Azure Databticks workspace that contains an all-purpose compute cluster named Cluster1.
Cluser1 is used for
interactive development.
You need to configure Cluster1 to meet the following requirements:
* Automatically add and remove worker nodes based on workload demand
* Automatically shut down when the cluster has been idle for a specific period.
What should you configure for each requirement? To answer, drag the appropriate options to the correct requirements. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.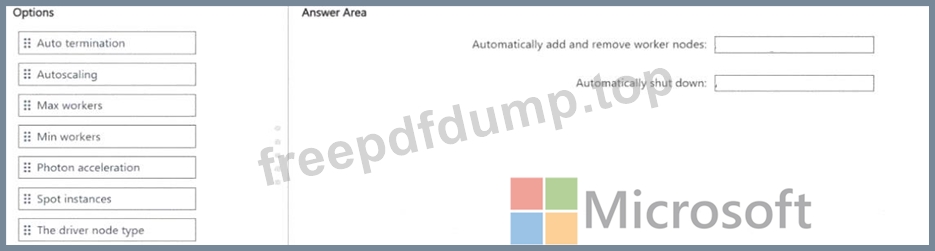
Answer:
Explanation: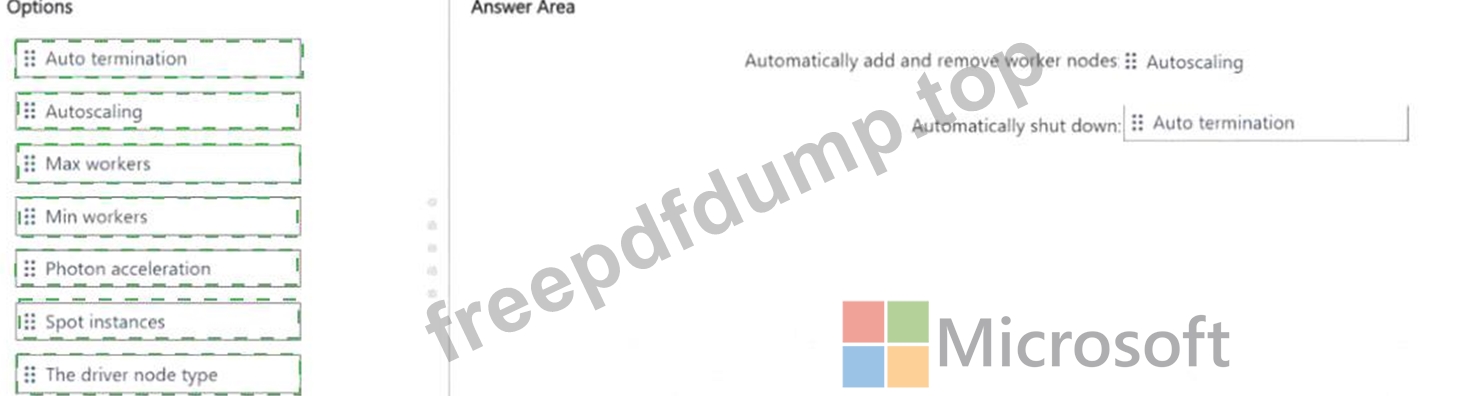
Explanation:
Two separate cluster settings address the two requirements:
Autoscaling handles the first requirement - dynamically adding workers when the workload is heavy and removing them when it lightens. You set a minimum and maximum node count, and Databricks adjusts the cluster size between those bounds based on task queue depth.
Auto-termination handles the second - the cluster shuts itself down after a configurable idle period (e.g., 30 minutes with no active queries), preventing wasted spend on a development cluster left running overnight.
These two settings are independent and complementary: autoscaling manages horizontal elasticity during active use, while auto-termination manages complete shutdown during inactivity. Both are configured in the cluster creation UI under the Compute section.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/configure#autoscaling
NEW QUESTION # 67
You need to configure compute for the ingestion of telemetry data. The solution must meet the data ingestion and processing requirements.
What should you do?
Answer: A
Explanation:
The correct answer is A. Photon is Azure Databricks' native vectorized query engine, written in C++, designed to accelerate data ingestion and SQL-heavy workloads significantly over the standard Spark JVM path. Enabling it on a job compute cluster directly addresses Contoso's requirement for 'fast and consistent performance for BI workloads' and 'production ingestion workloads that can scale automatically during telemetry spikes.' Photon integrates transparently - no code changes are needed - and pairs well with autoscaling job clusters to handle the bursty 40,000-sensor telemetry load.
Option B contradicts the isolation requirement: Contoso explicitly needs production and development separated, not merged onto shared compute. Option C with a fixed large node gives peak capacity at all times, driving up costs even during quiet periods. Option D disabling autoscaling is the opposite of what's needed - telemetry spikes require elastic scaling, not a locked node count.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/photon
NEW QUESTION # 68
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! processes raw data files stored in Azure Storage.
New files arrive at unpredictable intervals.
You need to ensure that Job1 starts automatically when new files arrive and does NOT consume compute resources when no data is available.
Which type of job trigger should you use?
Answer: B
Explanation:
The correct answer is C - File Arrival trigger.
File Arrival monitors a specified Azure Storage path and fires a job run each time a new file lands there. This ticks both requirements: Job1 starts automatically in response to new data (no human involvement), and when no files arrive, no job runs - no cluster spins up, no compute cost is incurred.
Option A (scheduled) runs at fixed intervals regardless of whether files are waiting. A quiet weekend still kicks off hourly (or daily) runs, burning compute for nothing. Option B (continuous) keeps the job running perpetually, consuming resources even during long gaps between file arrivals - exactly what 'does NOT consume compute resources when no data is available' rules out. Option D (manual) requires a person to trigger every run, which is unsuitable for unpredictable arrival patterns.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/triggers#file-arrival-trigger
NEW QUESTION # 69
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 runs every hour.
Occasionally, Job1 takes longer than one hour to complete.
You need to configure the job scheduling behavior to meet the following requirements:
* Overlapping runs must be prevented to avoid data corruption.
* Scheduled runs must not be discarded when another run is already active.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.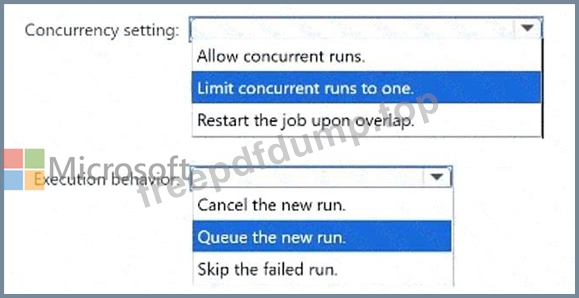
Answer:
Explanation: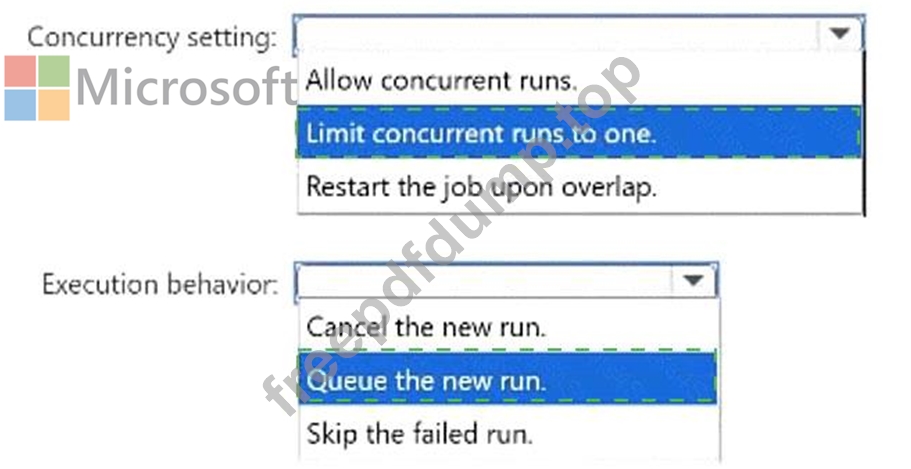
Explanation:
Concurrency setting: Limit concurrent runs to one.
Execution behavior: Queue the new run.
Limiting concurrent runs to one ensures that only one instance of Job1 can execute at a time. This prevents two hourly runs from simultaneously modifying the same tables, files, checkpoints, or downstream systems, thereby reducing the risk of duplicate processing and data corruption. When a scheduled trigger occurs while an earlier execution is still active, queueing the new run preserves that execution and starts it after the active run finishes. Allowing concurrent runs would violate the non-overlap requirement. Restarting the job during an overlap could interrupt partially completed work. Canceling the new run or skipping it would avoid simultaneous execution, but the scheduled processing interval could be lost. Single-run concurrency combined with queueing therefore serializes the executions without discarding scheduled work.
NEW QUESTION # 70
......
If you feel unconfident in self-preparation for your DP-750 test and want to get professional aid of questions and answers, FreePdfDump DP-750 test questions materials will guide you and help you to pass the certification exams in one shot. If you want to know our DP-750 Test Questions materials, you can download our free demo now. Our demo is a small part of the complete charged version. Also you can ask us any questions about DP-750 exam any time as you like.
Valid DP-750 Test Voucher: https://www.freepdfdump.top/DP-750-valid-torrent.html