BONUS!!! Download part of Pass4cram Databricks-Certified-Professional-Data-Engineer dumps for free: https://drive.google.com/open?id=17HOElK75bY7g8UTG5cYlhoVn-asoClbF
In order to make all customers feel comfortable, our company will promise that we will offer the perfect and considerate service for all customers. If you buy the Databricks-Certified-Professional-Data-Engineer study materials from our company, you will have the right to enjoy the perfect service. We have employed a lot of online workers to help all customers solve their problem. If you have any questions about the Databricks-Certified-Professional-Data-Engineer Study Materials, do not hesitate and ask us in your anytime, we are glad to answer your questions and help you use our Databricks-Certified-Professional-Data-Engineer study materials well. We believe our perfect service will make you feel comfortable when you are preparing for your exam.
| Section | Objectives |
|---|---|
| Production Pipelines and Orchestration | - Automate ETL pipelines and scheduling - Build and manage workflows using Databricks Jobs - Pipeline reliability and fault tolerance |
| Security, Governance, Monitoring, and Optimization | - Cost optimization and performance tuning - Implement Unity Catalog governance and access control - Monitor and optimize Spark workloads |
| Data Ingestion and Transformation | - Transform and clean datasets using Spark SQL and DataFrame APIs - Ingest data using Apache Spark and Databricks - Handle batch and streaming data pipelines |
| Data Modeling and Storage | - Design scalable data lakehouse architectures - Schema evolution and data partitioning strategies - Delta Lake table design and optimization |
>> Dump Databricks-Certified-Professional-Data-Engineer Collection <<
Our Databricks-Certified-Professional-Data-Engineer study guide provides free trial services, so that you can learn about some of our topics and how to open the software before purchasing. During the trial period of our Databricks-Certified-Professional-Data-Engineer study materials, the PDF versions of the sample questions are available for free download, and both the pc version and the online version can be illustrated clearly. You can contact us at any time if you have any difficulties on our Databricks-Certified-Professional-Data-Engineer Exam Questions in the purchase or trial process. We will provide professional personnel to help you remotely on the Databricks-Certified-Professional-Data-Engineer training guide.
NEW QUESTION # 175
Which of the following Structured Streaming queries is performing a hop from a Bronze table to a Silver
table?
Answer: C
NEW QUESTION # 176
A data ingestion task requires a one-TB JSON dataset to be written out to Parquet with a target part-file size of 512 MB. Because Parquet is being used instead of Delta Lake, built-in file-sizing features such as Auto- Optimize and Auto-Compaction cannot be used.
Which strategy will yield the best performance without shuffling data?
Answer: E
Explanation:
For this scenario where a one-TB JSON dataset needs to be converted into Parquet format without employing Delta Lake ' s auto-sizing features, the goal is to avoid unnecessary data shuffles and yet ensure optimal file sizes for the output Parquet files. Here's a breakdown of why option A is most suitable:
* Setting maxPartitionBytes: The spark.sql.files.maxPartitionBytes configuration controls the size of blocks that Spark reads from the data source (in this case, the JSON files) but also influences the output size of files when data is written without repartition or coalesce operations. Setting this parameter to
512 MB directly addresses the requirement to manage the output file size effectively.
* Data Ingestion and Processing:
* Ingesting Data: Load the JSON dataset into a DataFrame.
* Applying Transformations: Perform any required narrow transformations that do not involve shuffling data (like filtering or adding new columns).
* Writing to Parquet: Directly write the transformed DataFrame to Parquet files. The setting for maxPartitionBytes ensures that each part-file is approximately 512 MB, meeting the requirement for part-file size without additional steps to repartition or coalesce the data.
* Performance Consideration: This approach is optimal because:
* It avoids the overhead of shuffling data, which can be significant, especially with large datasets.
* It directly ties the read/write operations to a configuration that matches the target output size, making it efficient in terms of both computation and I/O operations.
* Alternative Options Analysis:
* Option B and D: Involves repartitioning, which would trigger a shuffle of the data, contradicting the requirement to avoid shuffling for performance reasons.
* Option C: Uses coalesce, which is less intensive than repartition but can still lead to uneven partition sizes and does not directly control the output file size as effectively as setting maxPartitionBytes.
* Option E: Setting shuffle partitions to 512 doesn't directly control the output file size for writing to Parquet and could lead to smaller files depending on the dataset ' s partitioning post- transformations.
References
* Apache Spark Configuration
* Writing to Parquet Files in Spark
NEW QUESTION # 177
A junior data engineer has manually configured a series of jobs using the Databricks Jobs UI. Upon reviewing their work, the engineer realizes that they are listed as the "Owner" for each job. They attempt to transfer "Owner" privileges to the "DevOps" group, but cannot successfully accomplish this task.
Which statement explains what is preventing this privilege transfer?
Answer: A
Explanation:
The reason why the junior data engineer cannot transfer "Owner" privileges to the "DevOps" group is that Databricks jobs must have exactly one owner, and the owner must be an individual user, not a group. A job cannot have more than one owner, and a job cannot have a group as an owner. The owner of a job is the user who created the job, or the user who was assigned the ownership by another user. The owner of a job has the highest level of permission on the job, and can grant or revoke permissions to other users or groups. However, the owner cannot transfer the ownership to a group, only to another user. Therefore, the junior data engineer's attempt to transfer "Owner" privileges to the "DevOps" group is not possible. Reference:
Jobs access control: https://docs.databricks.com/security/access-control/table-acls/index.html Job permissions: https://docs.databricks.com/security/access-control/table-acls/privileges.html#job-permissions
NEW QUESTION # 178
A data engineer wants to create a cluster using the Databricks CLI for a big ETL pipeline. The cluster should have five workers, one driver of type i3.xlarge, and should use the '14.3.x-scala2.12' runtime.
Which command should the data engineer use?
Answer: D
Explanation:
The Databricks CLI allows users to manage clusters using command-line commands. The correct command for creating a cluster follows a specific format.
Key Components in the Command:
* Command Type: databricks compute create is the correct syntax for creating a new compute resource (cluster).
* Runtime Version: '14.3.x-scala2.12' specifies the Databricks runtime to use.
* Workers: --num-workers 5 sets the number of worker nodes to 5.
* Node Type: --node-type-id i3.xlarge defines the hardware configuration.
* Cluster Name: --cluster-name DataEngineer_cluster assigns a recognizable name to the cluster.
Evaluation of Options:
* Option A (databricks clusters create ...)
* Incorrect: databricks clusters create is not a valid command in the Databricks CLI v0.205.
* The correct CLI command for cluster creation is databricks compute create.
* Option B (databricks clusters add ...)
* Incorrect: databricks clusters add is not a valid CLI command.
* Option C (databricks compute add ...)
* Incorrect: databricks compute add is not a valid CLI command.
* Option D (databricks compute create ...)
* Correct: databricks compute create is the correct command for creating a cluster.
Conclusion:
The correct command to create a cluster with five workers, an i3.xlarge node type, and Databricks runtime
14.3.x-scala2.12 is:
databricks compute create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster Thus, the correct answer is D.
References:
Databricks CLI Documentation
NEW QUESTION # 179
Review the following error traceback: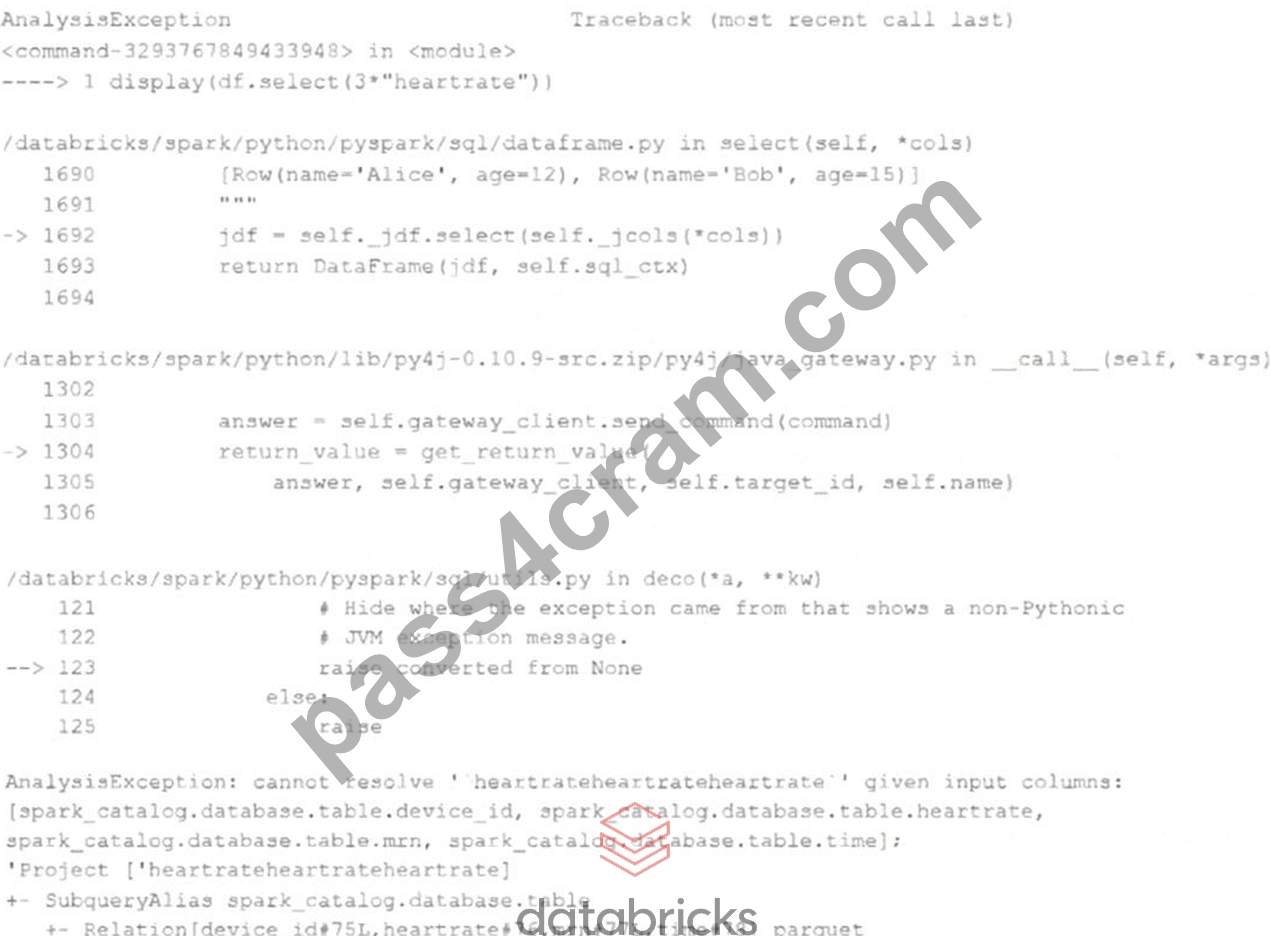
Which statement describes the error being raised?
Answer: B
Explanation:
The error being raised is an AnalysisException, which is a type of exception that occurs when Spark SQL cannot analyze or execute a query due to some logical or semantic error1. In this case, the error message indicates that the query cannot resolve the column name 'heartrateheartrateheartrate' given the input columns
'heartrate' and 'age'. This means that there is no column in the table named 'heartrateheartrateheartrate', and the query is invalid. A possible cause of this error is a typo or a copy-paste mistake in the query. To fix this error, the query should use a valid column name that exists in the table, such as
'heartrate'. References: AnalysisException
NEW QUESTION # 180
......
Thousands of Databricks Certified Professional Data Engineer Exam exam aspirants have already passed their Databricks Databricks-Certified-Professional-Data-Engineer certification exam and they all got help from top-notch and easy-to-use Databricks Databricks-Certified-Professional-Data-Engineer Exam Questions. You can also use the Pass4cram Databricks-Certified-Professional-Data-Engineer exam questions and earn the badge of Databricks Databricks-Certified-Professional-Data-Engineer certification easily.
New Databricks-Certified-Professional-Data-Engineer Exam Fee: https://www.pass4cram.com/Databricks-Certified-Professional-Data-Engineer_free-download.html
2026 Latest Pass4cram Databricks-Certified-Professional-Data-Engineer PDF Dumps and Databricks-Certified-Professional-Data-Engineer Exam Engine Free Share: https://drive.google.com/open?id=17HOElK75bY7g8UTG5cYlhoVn-asoClbF