Itcertkr MLA-C01 최신 PDF 버전 시험 문제집을 무료로 Google Drive에서 다운로드하세요: https://drive.google.com/open?id=1fpt1T9GZI2M9OiaedmqxfNzenHxB8aEl
Amazon MLA-C01 덤프가 고객님의 기대를 가득 채워드릴수 있도록 정말로 노력하고 있는 Itcertkr랍니다. Amazon MLA-C01 덤프는 pdf버전과 소프트웨어버전으로만 되어있었는데 최근에는 휴대폰에서가 사용가능한 온라인버전까지 개발하였습니다. 날따라 새로운 시스템을 많이 개발하여 고객님께 더욱 편하게 다가갈수 있는 Itcertkr가 되겠습니다.
| 주제 | 소개 |
|---|---|
| 주제 1 |
|
| 주제 2 |
|
| 주제 3 |
|
| 주제 4 |
|
Amazon 인증 MLA-C01시험이 너무 어려워서 시험 볼 엄두도 나지 않는다구요? Itcertkr 덤프만 공부하신다면 IT인증시험공부고민은 이젠 그만 하셔도 됩니다. Itcertkr에서 제공해드리는Amazon 인증 MLA-C01시험대비 덤프는 덤프제공사이트에서 가장 최신버전이여서 시험패스는 한방에 갑니다. Amazon 인증 MLA-C01시험뿐만 아니라 IT인증시험에 관한 모든 시험에 대비한 덤프를 제공해드립니다. 많은 애용 바랍니다.
질문 # 231
A hospital wants to predict patient outcomes for the coming year An ML engineer must improve several existing ML models that currently perform poorly.
Select the correct regularization method from the following list to improve each model Select each regularization method one time, more than one time, or not at all. (Select THREE.)
* L1 regularization
* L2 regularization
* Early stopping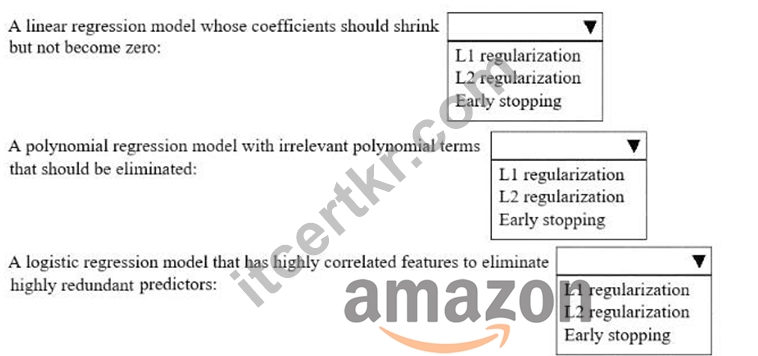
정답:
설명: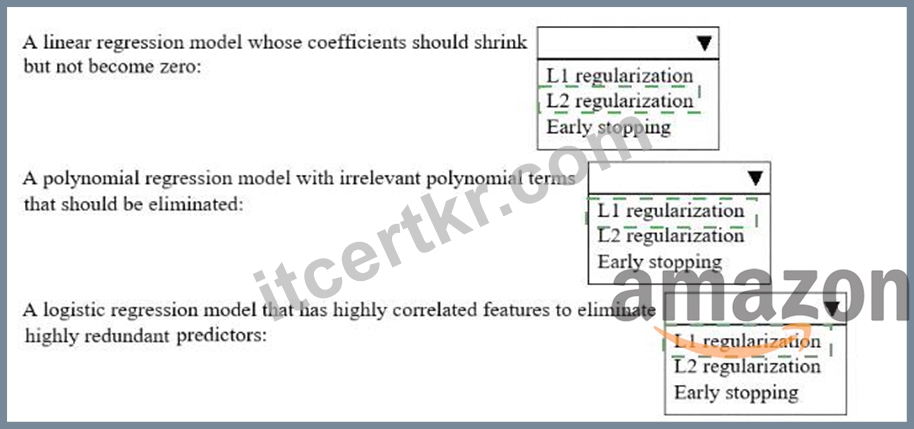
Explanation:
Linear regression model whose coefficients should shrink but not become zero answer: L2 regularization AWS says L2 produces smaller overall weight values and is the right fit when coefficients should be reduced without being forced to zero.
Polynomial regression model with irrelevant polynomial terms that should be eliminated answer: L1 regularization AWS says L1 reduces the number of features used by pushing small weights to zero , which matches elimination of irrelevant terms.
Logistic regression model that has highly correlated features to eliminate highly redundant predictors L1 regularization This is the nuanced one. AWS says L2 stabilizes weights when there is high correlation between features , but because the question explicitly says eliminate highly redundant predictors , L1 is the better match since it creates sparsity and removes predictors by zeroing coefficients.
질문 # 232
An ML engineer is training a simple neural network model. The ML engineer tracks the performance of the model over time on a validation dataset. The model's performance improves substantially at first and then degrades after a specific number of epochs.
Which solutions will mitigate this problem? (Choose two.)
정답:A,C
설명:
Early stopping halts training once the performance on the validation dataset stops improving. This prevents the model from overfitting, which is likely the cause of performance degradation after a certain number of epochs.
Dropout is a regularization technique that randomly deactivates neurons during training, reducing overfitting by forcing the model to generalize better. Increasing dropout can help mitigate the problem of performance degradation due to overfitting.
질문 # 233
A financial company receives a high volume of real-time market data streams from an external provider. The streams consist of thousands of JSON records every second.
The company needs to implement a scalable solution on AWS to identify anomalous data points.
Which solution will meet these requirements with the LEAST operational overhead?
정답:C
설명:
The key requirements are real-time processing, high throughput, and minimal operational overhead. Amazon Kinesis Data Streams is designed for ingesting thousands of events per second with low latency.
For anomaly detection on streaming data, Amazon Managed Service for Apache Flink provides a built-in Random Cut Forest (RCF) function. RCF is an unsupervised anomaly detection algorithm that works well on numerical streaming data and does not require labeled training data.
This fully managed combination eliminates the need to deploy or maintain SageMaker endpoints, EC2 instances, or custom ML pipelines. Options B and C introduce unnecessary infrastructure and model management overhead. Option D is batch-oriented and unsuitable for real-time anomaly detection.
Therefore, using Kinesis Data Streams with Flink's built-in Random Cut Forest is the most scalable and low- overhead solution.
질문 # 234
A company is running ML models on premises by using custom Python scripts and proprietary datasets. The company is using PyTorch. The model building requires unique domain knowledge. The company needs to move the models to AWS.
Which solution will meet these requirements with the LEAST effort?
정답:B
설명:
SageMaker script mode allows you to bring existing custom Python scripts and run them on AWS with minimal changes. SageMaker provides prebuilt containers for ML frameworks like PyTorch, simplifying the migration process. This approach enables the company to leverage their existing Python scripts and domain knowledge while benefiting from the scalability and managed environment of SageMaker. It requires the least effort compared to building custom containers or retraining models from scratch.
질문 # 235
An ML engineer needs to use Amazon SageMaker Feature Store to create and manage features to train a model.
Select and order the steps from the following list to create and use the features in Feature Store. Each step should be selected one time. (Select and order three.)
* Access the store to build datasets for training.
* Create a feature group.
* Ingest the records.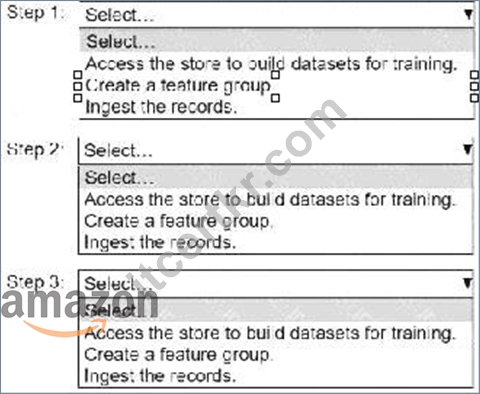
정답:
설명: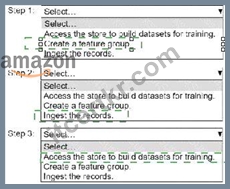
Explanation: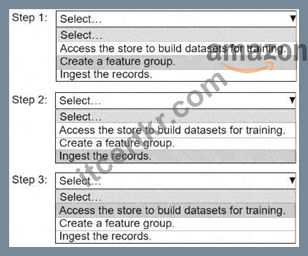
Step 1: Create a feature group.
Step 2: Ingest the records.
Step 3: Access the store to build datasets for training.
Step 1: Create a Feature Group
Why? A feature group is the foundational unit in SageMaker Feature Store, where features are defined, stored, and organized. Creating a feature group specifies the schema (name, data type) for the features and the primary keys for data identification.
How? Use the SageMaker Python SDK or AWS CLI to define the feature group by specifying its name, schema, and S3 storage location for offline access.
Step 2: Ingest the Records
Why? After creating the feature group, the raw data must be ingested into the Feature Store. This step populates the feature group with data, making it available for both real-time and offline use.
How? Use the SageMaker SDK or AWS CLI to batch-ingest historical data or stream new records into the feature group. Ensure the records conform to the feature group schema.
Step 3: Access the Store to Build Datasets for Training
Why? Once the features are stored, they can be accessed to create training datasets. These datasets combine relevant features into a single format for machine learning model training.
How? Use the SageMaker Python SDK to query the offline store or retrieve real-time features using the online store API. The offline store is typically used for batch training, while the online store is used for inference.
Order Summary:
Create a feature group.
Ingest the records.
Access the store to build datasets for training.
This process ensures the features are properly managed, ingested, and accessible for model training using Amazon SageMaker Feature Store.
질문 # 236
......
IT국제공인자격증Amazon MLA-C01시험대비덤프를 제공하는 전문적인 사이트로서 회원님의 개인정보를 철저하게 보호해드리고 페이팔을 통한 결제라 안전한 결제를 진행할수 있습니다. Amazon MLA-C01 덤프외에 다른 인증시험덤프에 관심이 있으신 분은 온라인 서비스를 클릭하여 문의해주세요.
MLA-C01퍼펙트 덤프공부문제: https://www.itcertkr.com/MLA-C01_exam.html
Itcertkr MLA-C01 최신 PDF 버전 시험 문제집을 무료로 Google Drive에서 다운로드하세요: https://drive.google.com/open?id=1fpt1T9GZI2M9OiaedmqxfNzenHxB8aEl