그리고 Itexamdump Mule-Arch-201 시험 문제집의 전체 버전을 클라우드 저장소에서 다운로드할 수 있습니다: https://drive.google.com/open?id=1PE-Ve6tTQ98fhNlo1KOtJBEIBcrs-IIn
Itexamdump는Salesforce Mule-Arch-201인증시험을 아주 쉽게 패스할 수 있도록 도와드리는 사이트입니다. Itexamdump의 엘리트한 전문가가 끈임 없는 노력으로 최고의Salesforce Mule-Arch-201자료를 만들었습니다. 이 자료로 여러분은 100%Salesforce의Mule-Arch-201인증시험을 패스할 수 있으며, Itexamdump을 선택함으로 성공을 선택한 것입니다. Itexamdump가 제공하는 시험가이드로 효과적인 학습으로 많은 분들이 모두 인증시험을 패스하였습니다. 이건 모두 Itexamdump 인증시험덤프로 공부하였기 때문입니다. 그 중Salesforce Mule-Arch-201인증시험을 패스한 분들도 모두 Itexamdump인증시험덤프를 사용하였기 때문입니다.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Managing APIs | 12% | - API Versioning - API Security (Policies, SLAs) - API Lifecycle Management |
| Topic 2: Applying Integration Patterns | 11% | - Event-Driven Architecture (EDA) - Batch Processing - Integration Scenarios & Patterns |
| Topic 3: Deploying API Implementations to CloudHub | 11% | - CloudHub 2.0 & Runtime Fabric - Deployment Strategies - CloudHub Architecture |
| Topic 4: Meeting API Quality Goals | 8% | - Resilience & Reliability Patterns - Unit & Integration Testing - API Performance Optimization |
| Topic 5: Understanding the MuleSoft Platform & Application Networks | 11% | - Application Network Fundamentals - C4E (Center for Enablement) Definition - MuleSoft Anypoint Platform Core Concepts |
| Topic 6: Monitoring and Analyzing Application Networks | 8% | - Alerting & Auditing - Anypoint Monitoring Tools - Analytics & Business Insights |
| Topic 7: Establishing Organizational and Platform Foundations | 17% | - Platform Foundation Setup - IT Delivery & C4E Operating Model - Governance and Compliance Framework |
| Topic 8: Architecting and Deploying API Implementations | 11% | - Disaster Recovery (DR) Strategies - High Availability (HA) Design - Mule Runtime Architecture |
| Topic 9: Designing and Sharing APIs | 11% | - Anypoint Exchange for Sharing Assets - API-Led Connectivity Approach - API Design Best Practices |
>> Mule-Arch-201인기자격증 시험덤프공부 <<
Itexamdump의Salesforce인증 Mule-Arch-201시험대비 덤프는 가격이 착한데 비하면 품질이 너무 좋은 시험전 공부자료입니다. 시험문제적중율이 높아 패스율이 100%에 이르고 있습니다.다른 IT자격증에 관심이 있는 분들은 온라인서비스에 문의하여 덤프유무와 적중율등을 확인할수 있습니다. Salesforce인증 Mule-Arch-201덤프로 어려운 시험을 정복하여 IT업계 정상에 오릅시다.
질문 # 43
An eCommerce company is adding a new Product Details feature to their website, A customer will launch the product catalog page, a new Product Details link will appear by product where they can click to retrieve the product detail description. Product detail data is updated with product update releases, once or twice a year, Presently the database response time has been very slow due to high volume.
What action retrieves the product details with the lowest response time, fault tolerant, and consistent data?
정답:A
설명:
Scenario Analysis:
The eCommerce company's Product Details feature requires low response time and consistent data for a feature where data rarely changes (only once or twice a year).
The database response time is slow due to high volume, so querying the database directly on each request would lead to poor performance and higher response times.
Optimal Solution Requirements:
Low Response Time: Data retrieval should be fast and not depend on database performance.
Fault Tolerance and Data Consistency: Cached or stored data should be consistent and resilient in case of database unavailability, as the product details data changes infrequently.
Evaluating the Options:
Option A: Using a Cache scope would temporarily store the product details in memory, which could improve performance but might not be suitable for infrequent updates (only twice a year), as cache expiration policies typically require shorter durations.
Option B: Storing product details in Anypoint MQ and then retrieving it through a subscriber is not suitable for this use case. Anypoint MQ is better for messaging rather than as a data storage mechanism.
Option C (Correct Answer): Using an object store to store and retrieve product details is ideal. Object stores in MuleSoft are designed for persistent storage of key-value pairs, which allows storing data retrieved from the database initially. This provides quick, consistent access without querying the database on every request, aligning with requirements for low response time, fault tolerance, and data consistency.
Option D: Selecting data directly from the database for each request would not meet the performance requirement due to known slow response times from the database.
Conclusion:
Option C is the best answer, as using an object store allows caching the infrequently updated product details. This approach reduces the dependency on the database, significantly improving response time and ensuring consistent data.
Refer to MuleSoft documentation on Object Store v2 and best practices for data caching to implement this solution effectively.
질문 # 44
An Order API triggers a sequence of other API calls to look up details of an order's items in a back-end inventory database. The Order API calls the OrderItems process API, which calls the Inventory system API. The Inventory system API performs database operations in the back-end inventory database.
The network connection between the Inventory system API and the database is known to be unreliable and hang at unpredictable times.
Where should a two-second timeout be configured in the API processing sequence so that the Order API never waits more than two seconds for a response from the Orderltems process API?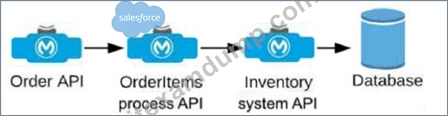
정답:D
설명:
Understanding the API Flow and Timeout Requirement:
The Order API initiates a call to the OrderItems process API, which in turn calls the Inventory system API to fetch details from the inventory database.
The requirement specifies that the Order API should not wait more than two seconds for a response from the OrderItems process API, even if there are delays further down the chain (between Inventory system API and the database).
Choosing the Appropriate Timeout Location:
Setting the timeout at the OrderItems process API level ensures that if the Inventory system API takes longer than two seconds to respond, the OrderItems process API will terminate the request and send a timeout response back to the Order API. This prevents the Order API from waiting indefinitely due to the unreliable connection to the database.
If the timeout were set in the Inventory system API or database, it would not help the Order API directly, as the OrderItems process API would still be waiting for a response.
Detailed Analysis of Each Option:
Option A (Correct Answer): Setting the timeout in the OrderItems process API allows it to control how long it waits for a response from the Inventory system API. If the Inventory system API does not respond within two seconds, the OrderItems process API can terminate the call and return a timeout response to the Order API, meeting the requirement.
Option B: Setting the timeout in the Order API would not limit the wait time at the OrderItems process API level, meaning the OrderItems process API could still wait indefinitely for the Inventory system API, leading to a longer delay.
Option C: Setting the timeout in the Inventory system API only affects the connection to the database and does not influence how long the OrderItems process API waits for the Inventory system API's response.
Option D: Setting a timeout in the database is not feasible in this context since database timeouts are typically configured for database operations and would not directly control the API response times in the overall API chain.
Conclusion:
Option A is the best choice, as it ensures that the OrderItems process API does not hold the Order API longer than the required two seconds, even if the downstream connection to the database hangs. This configuration aligns with MuleSoft best practices for setting timeouts in API orchestration to manage dependencies and prevent delays across a chain of API calls.
For additional information on timeout settings, refer to MuleSoft documentation on handling timeouts and API orchestration best practices.
질문 # 45
A company requires Mule applications deployed to CloudHub to be isolated between non-production and production environments. This is so Mule applications deployed to non-production environments can only access backend systems running in their customer-hosted non-production environment, and so Mule applications deployed to production environments can only access backend systems running in their customer-hosted production environment. How does MuleSoft recommend modifying Mule applications, configuring environments, or changing infrastructure to support this type of per-environment isolation between Mule applications and backend systems?
정답:A
설명:
Correct Answe r: Create separate Anypoint VPCs for non-production and production environments, then configure connections to the backend systems in the corresponding customer-hosted environments.
*****************************************
>> Creating different Business Groups does NOT make any difference w.r.t accessing the non-prod and prod customer-hosted environments. Still they will be accessing from both Business Groups unless process network restrictions are put in place.
>> We need to modify or couple the Mule Application Implementations with the environment. In fact, we should never implements application coupled with environments by binding them in the properties. Only basic things like endpoint URL etc should be bundled in properties but not environment level access restrictions.
>> IP addresses on CloudHub are dynamic until unless a special static addresses are assigned. So it is not possible to setup firewall rules in customer-hosted infrastrcture. More over, even if static IP addresses are assigned, there could be 100s of applications running on cloudhub and setting up rules for all of them would be a hectic task, non-maintainable and definitely got a good practice.
>> The best practice recommended by Mulesoft (In fact any cloud provider), is to have your Anypoint VPCs seperated for Prod and Non-Prod and perform the VPC peering or VPN tunneling for these Anypoint VPCs to respective Prod and Non-Prod customer-hosted environment networks.
Reference:
Bottom of Form
Top of Form
질문 # 46
To minimize operation costs, a customer wants to use a CloudHub 1.0 solution. The customer's requirements are:
* Separate resources with two Business groups
* High-availability (HA) for all APIs
* Route traffic via Dedicated load balancer (DLBs)
* Separate environments into production and non-production
Which solution meets the customer's needs?
정답:C
설명:
Understanding the Requirements:
Business Groups: The solution must support two business groups, which typically require separate VPCs for logical separation.
High Availability (HA): Requires deploying resources across multiple availability zones.
Dedicated Load Balancer (DLB): Traffic should be routed via DLBs, which operate within VPCs on CloudHub.
Separate Environments: There needs to be separation between production and non-production environments.
Evaluating the Options:
Option A: Using a single production and non-production VPC and differentiating business groups via availability zones is not ideal as it does not provide full separation for each business group, and using maximum CIDR allocation is wasteful.
Option B (Correct Answer): Creating separate production and non-production VPCs per business group with minimized CIDR blocks, multiple availability zones, and multiple workers per application for HA meets all requirements effectively.
Option C: While this option separates VPCs per business group, it does not fully address the requirement for HA across availability zones by specifying multi-zone deployment only during API deployment, which may not guarantee redundancy.
Option D: Configuring subnets to differentiate business groups within a single production and non-production VPC does not fully separate the business groups, which is a requirement.
Conclusion:
Option B is the best choice as it meets the requirements for high availability, business group separation, and cost efficiency by using minimized CIDR allocations and deploying multiple workers across availability zones.
For further reference, refer to MuleSoft's documentation on VPC configuration and high availability deployment strategies.
질문 # 47
Which component monitors APIs and endpoints at scheduled intervals, receives reports about whether tests pass or fail, and displays statistics about API and endpoint performance?
정답:D
설명:
Understanding API Functional Monitoring:
API Functional Monitoring is a feature within MuleSoft's Anypoint Platform that enables users to monitor the health and performance of APIs and endpoints by running functional tests at scheduled intervals.
It checks whether APIs are functioning as expected by running test calls and then evaluating if the response meets the desired conditions. This is particularly useful for testing endpoint availability, checking for specific data in responses, and measuring API performance over time.
Component Features:
Scheduled Intervals: Functional monitoring allows configuring tests to run at regular intervals, such as every minute, hour, or day, depending on the monitoring requirements.
Reports on Test Pass/Fail Status: After each test run, API Functional Monitoring reports whether the API passed or failed the test conditions.
Performance Statistics: It displays metrics like average response time, success rate, and error rates, giving insights into API health and performance.
Evaluating the Options:
Option A (API Analytics): API Analytics provides insights on API usage and metrics but does not involve scheduled tests for pass/fail status or endpoint health checks.
Option B (Anypoint Monitoring Dashboards): These dashboards display API metrics but do not actively test API endpoints or provide pass/fail reporting on a scheduled basis.
Option C (Correct Answer): API Functional Monitoring fits the description, as it is designed to monitor API and endpoint health with scheduled test runs and display statistics about performance.
Option D (Anypoint Runtime Manager Alerts): Runtime Manager alerts notify users of issues with application status but do not actively test endpoints at scheduled intervals.
Conclusion:
Option C (API Functional Monitoring) is the correct answer because it provides the necessary tools to test API functionality, monitor endpoint health, and display performance statistics in real-time.
Refer to MuleSoft documentation on API Functional Monitoring for further guidance on setting up and configuring these tests in Anypoint Platform.
질문 # 48
......
Itexamdump의 경험이 풍부한 IT전문가들이 연구제작해낸 Salesforce인증 Mule-Arch-201덤프는 시험패스율이 100%에 가까워 시험의 첫번째 도전에서 한방에 시험패스하도록 도와드립니다. Salesforce인증 Mule-Arch-201덤프는Salesforce인증 Mule-Arch-201최신 실제시험문제의 모든 시험문제를 커버하고 있어 덤프에 있는 내용만 공부하시면 아무런 걱정없이 시험에 도전할수 있습니다.
Mule-Arch-201최신 업데이트버전 덤프: https://www.itexamdump.com/Mule-Arch-201.html
BONUS!!! Itexamdump Mule-Arch-201 시험 문제집 전체 버전을 무료로 다운로드하세요: https://drive.google.com/open?id=1PE-Ve6tTQ98fhNlo1KOtJBEIBcrs-IIn