With DP-750 guide torrent, you may only need to spend half of your time that you will need if you didn’t use our products successfully passing a professional qualification exam. In this way, you will have more time to travel, go to parties and even prepare for another exam. The benefits of DP-750 Study Guide for you are far from being measured by money. DP-750 guide torrent has a first-rate team of experts, advanced learning concepts and a complete learning model. You give us a trust and we reward you for a better future.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Prepare and process data | 30–35% | - Optimize and manage data storage
|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
>> DP-750 Reliable Test Questions <<
Many students did not perform well before they use Implementing Data Engineering Solutions Using Azure Databricks actual test. They did not like to study, and they disliked the feeling of being watched by the teacher. They even felt a headache when they read a book. There are also some students who studied hard, but their performance was always poor. Basically, these students have problems in their learning methods. DP-750 prep torrent provides students with a new set of learning modes which free them from the rigid learning methods. You can be absolutely assured about the high quality of our products, because the content of Implementing Data Engineering Solutions Using Azure Databricks actual test has not only been recognized by hundreds of industry experts, but also provides you with high-quality after-sales service.
NEW QUESTION # 28
You need to complete the PySpark code for the Spark Structured Streaming pipelines. The solution must meet the data ingestion and processing requirements.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.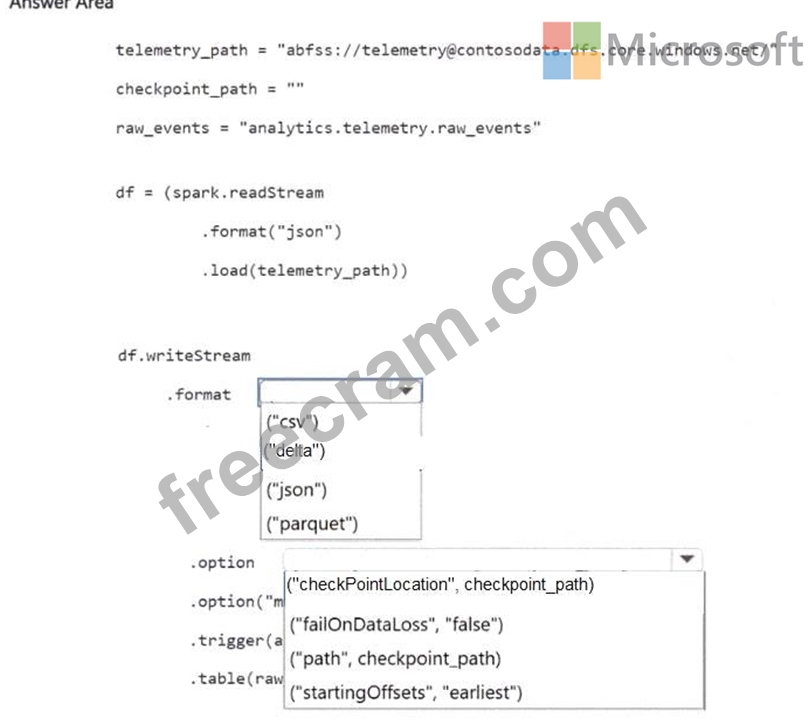
Answer:
Explanation: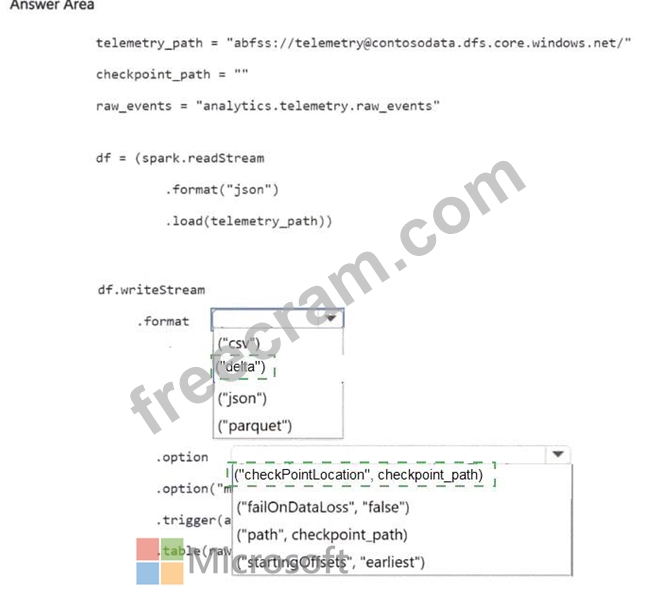
Explanation:
The solution requires spark.readStream with format('cloudFiles') for Auto Loader, paired with .writeStream using mergeSchema=true and a checkpointLocation.
Auto Loader's cloudFiles source incrementally processes new JSON files without rescanning the entire directory. The mergeSchema option handles schema drift - when sensors add new fields, the target Delta table schema expands automatically instead of throwing a parse error. This directly addresses Contoso's requirement to 'support schema drift.' The checkpointLocation is what gives the pipeline its resilience. Databricks writes the stream's committed offset and schema state to that path. If the cluster restarts, the engine reads the checkpoint and picks up exactly where it left off - no events are reprocessed, satisfying 'exactly-once semantics' and 'resume processing after failures without reprocessing the data.' Without a checkpoint, the stream would restart from the beginning on every cluster bounce, which is precisely the problem Contoso is trying to eliminate.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/auto-loader/schema
NEW QUESTION # 29
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to create an external volume named Volume1 in an existing schema. Volume1 must expose files from an Azure Storage container. The solution must meet the following requirements:
- Ensure that authentication does NOT require storing credentials in
Databricks.
- Ensure that users can access the files, but NOT modify the files.
- Follow the principle of least privilege.
Which type of authentication should you configure, and which permission should you grant to the users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.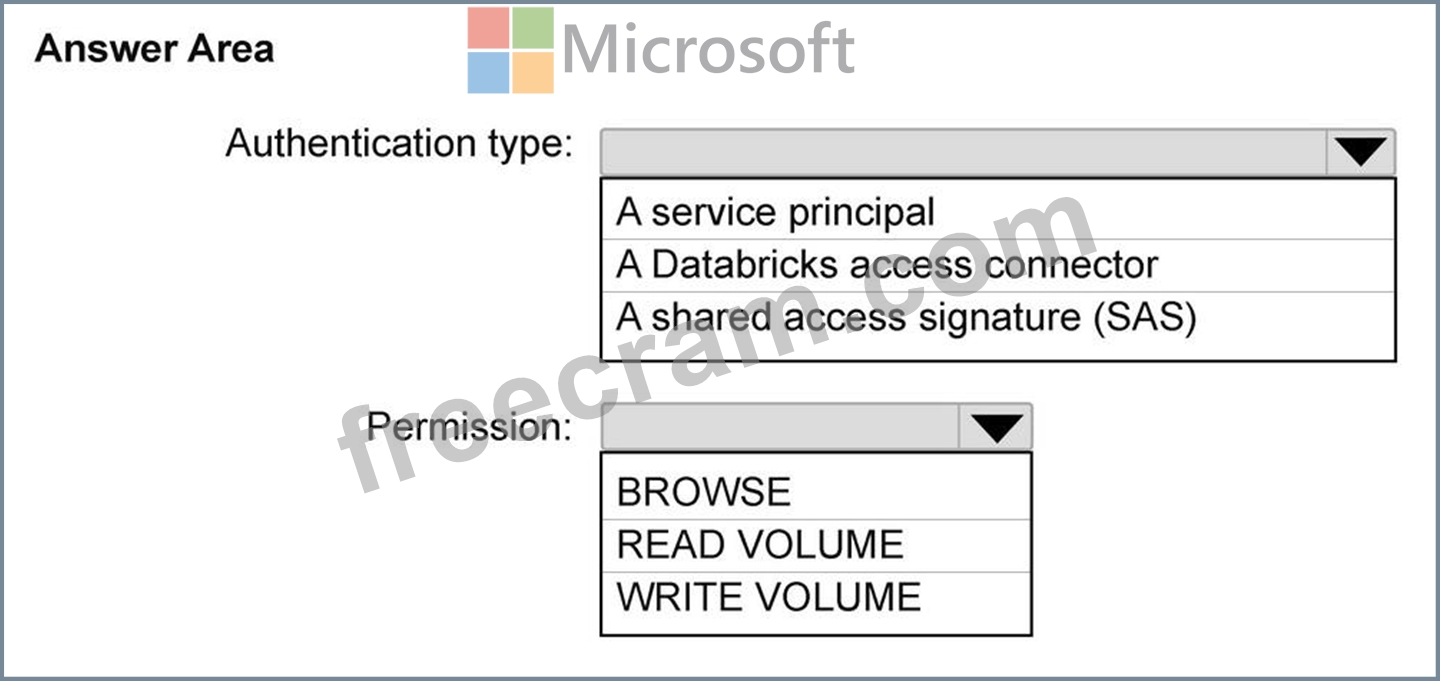
Answer:
Explanation: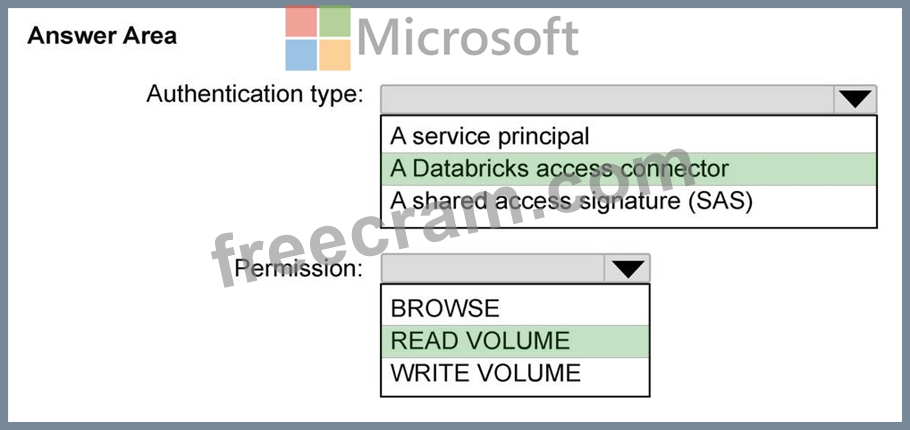
NEW QUESTION # 30
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to ensure that data lineage is captured and can be reviewed for tables accessed by Databricks notebooks and jobs. The solution must minimize administrative effort.
Which compute configuration should you use to capture the data lineage, and what should you use to review the data lineage? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.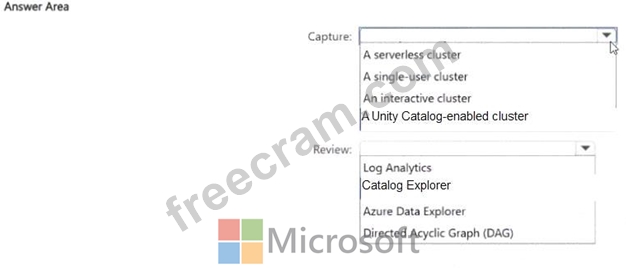
Answer:
Explanation: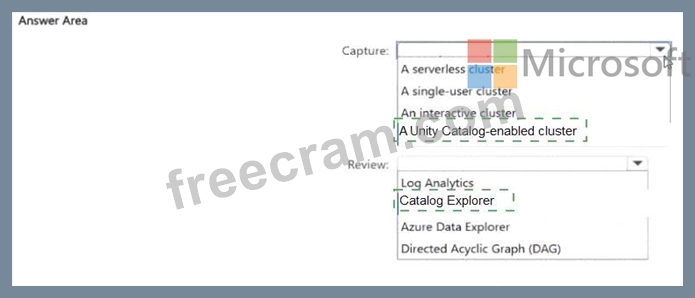
Explanation:
Data lineage in Unity Catalog is captured automatically - but only when jobs and notebooks run on clusters that are Unity Catalog-aware. Specifically, clusters must use 'Shared' or 'Single User' access mode. Clusters set to 'No Isolation Shared' or legacy 'High Concurrency' mode do not emit lineage events to the Unity Catalog lineage service.
No instrumentation, logging code, or external tools are required. The lineage service operates transparently, intercepting read and write operations at the Spark plan level and recording the table-to-table and column-to- column relationships.
To review captured lineage, open Catalog Explorer, navigate to the table, and select the Lineage tab. This shows the upstream sources that populate the table and the downstream consumers that read from it - all as an interactive graph, with no additional tooling needed. This built-in visibility is one of the core governance benefits Unity Catalog provides.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/data-lineage
NEW QUESTION # 31
Hotspot Question
You have an Azure Databricks workspace.
You have an Azure key vault named kv-secure that stores a secret named storageKey. The value of storageKey is managed and updated by the cloud security team at your company.
You need to enable a Databricks notebook named Notebook1 to retrieve the value of storageKey securely at runtime. The solution must follow the principle of least privilege and always retrieve the latest value.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.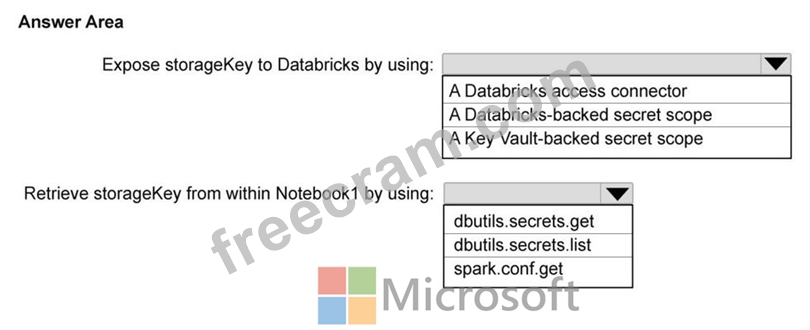
Answer:
Explanation: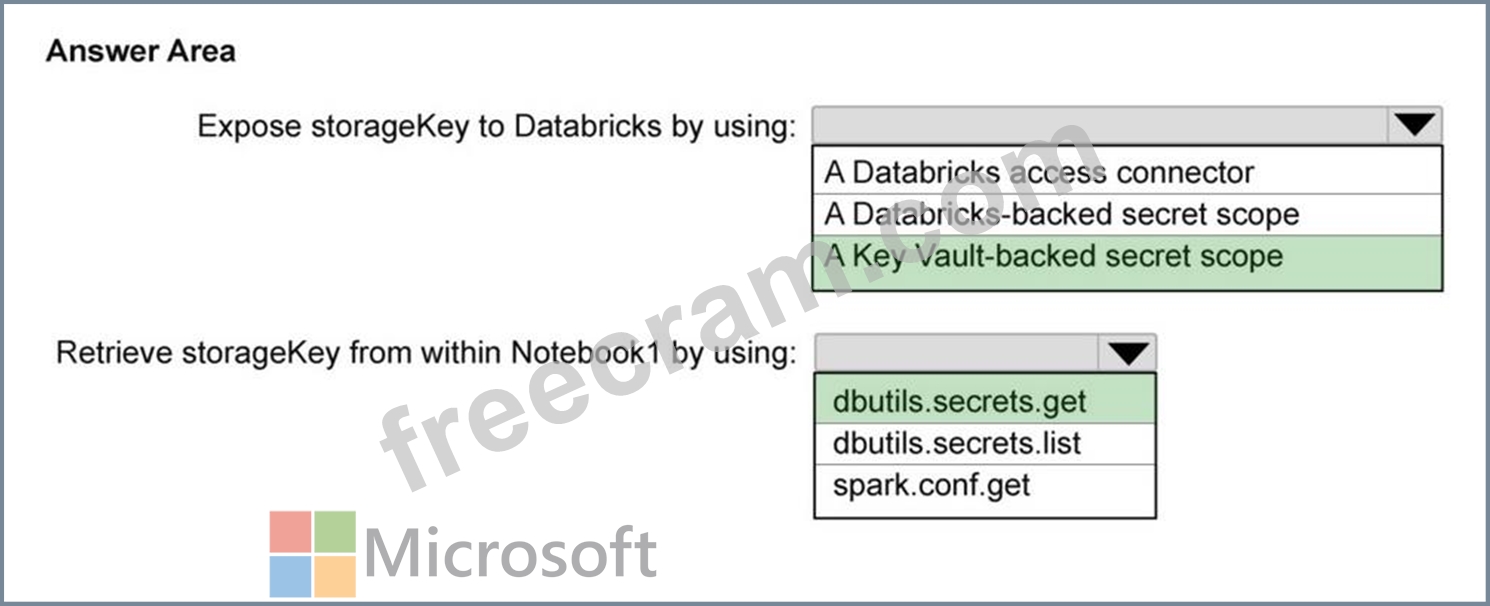
NEW QUESTION # 32
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You plan to ingest data from CSV files stored in Azure Data Lake Storage Gen2. New rows are appended frequently.
You need to implement a data ingestion solution that meets the following requirements:
* New data must be available in near-real-time (NRT).
* The data must be stored in managed Delta tables.
* The solution must minimize custom code and maintenance effort.
What should you include in the solution?
Answer: D
Explanation:
Auto Loader incrementally detects and processes new files arriving in Azure Data Lake Storage Gen2 through the cloudFiles Structured Streaming source. It supports near-real-time ingestion while automatically tracking processed files, reducing the custom state-management code required. Its output can be written to a managed Delta table, and built-in schema inference and evolution reduce ongoing maintenance. Scheduled Spark batch jobs introduce latency based on their schedule and usually require custom file-tracking logic. An external table over CSV files does not ingest the data into a managed Delta table. Azure Data Factory can orchestrate ingestion, but it introduces another service and more configuration than the native Databricks capability needed here. Auto Loader is therefore the most direct and maintainable solution for continuously arriving cloud files. Microsoft Learn
Topic 1, Contoso Case Study
Overview
Contoso has a single Azure Databricks workspace named Workspace1 in the West US Azure region.
Workspace1 is enabled for Unity Catalog.
Workspace1 contains all-purpose clusters for both development and production workloads.
The company ' s Azure environment contains:
* In the West US, Central US, and East US Azure regions, Azure event hubs that stream telemetry data and an Azure Data Lake Storage Gen2 account in each region for each hub
* A single Azure SQL database in the West US region that hosts enterprise resource planning (ERP) data
* An Azure Database for PostgreSQL server in the West US region that stores operational maintenance data Company information Contoso, Inc. is a renewable energy provider that operates solar and wind farms across North America.
Data Environment
Contoso ingests the following operational and business data:
* Telemetry data: More than 40,000 loT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
* Maintenance logs: Maintenance systems generate historical repair logs, daily incremental updates, technician notes, and unstructured attachments that are stored in the Data Lake Storage Gen2 accounts.
* Operational maintenance data: Structured operational maintenance data is stored on the Azure Database for PostgreSQL server.
* External weather data: Hourly weather forecasts are retrieved from a REST API and written to the Data Lake Storage Gen2 accounts.
* ERP data: Daily CSV extracts of 50 to 100 GB contain equipment metadata, work orders, and purchase order information.
Problem Statements
The company ' s existing analytics environment has several issues:
Ingestion
* Telemetry pipelines fall behind during peak loads.
* Telemetry ingestion fails when schema drift occurs.
* Streaming pipelines reprocess events after a pipeline restarts.
Compute
* Production and development workloads run on the same all-purpose clusters.
* Production and development workloads do NOT support autoscaling or workload isolation.
Governance
* The ERP data is duplicated across systems and development teams.
* Naming conventions are inconsistent across development teams, regions, and products.
* Ownership of the loT sensors changes over time, and analysts must track the full history of the ownership.
* Occasionally, equipment manufacturers must correct data-entry mistakes in equipment names. Historical values are NOT required.
Pipeline operations
* Pipelines lack resiliency, alerting, and centralized scheduling.
Planned Changes
Contoso plans to implement the following changes:
* Implement scalable data pipeline orchestration.
* Create a managed analytics catalog in Unity Catalog.
* Implement a consistent approach to creating curated datasets.
* Establish a centralized governance model across ingestion, cleansed, and curated layers.
* Grant data engineers access to the ERP tables by using minimal development effort.
* Adopt a compute strategy that isolates production workloads and supports autoscaling.
* Adopt a slowly changing dimension (SCD) approach to address current data modeling issues.
Technical Requirements
Contoso identifies the following environment and compute requirements:
* Ensure that production ingestion workloads run on compute clusters that can scale automatically during telemetry spikes.
* Provide fast and consistent performance for business intelligence (Bl) workloads.
* Prevent development activity from affecting production pipelines.
* Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
Contoso identifies the following data ingestion and processing requirements:
* Auto-scale ingestion pipelines to handle bursty workloads.
* Handle schema drift for the maintenance and telemetry data.
* Ingest file-based telemetry data by using minimal operational effort.
* Store all the ingested data in a format that supports incremental processing.
* Support the continuous ingestion of telemetry data from the event hubs by using exactly-once semantics.
* Support the ingestion of the structured maintenance data from the Azure Database for PostgreSQL server.
* Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
* Ensure that the Apache Spark Structured Streaming pipelines reading from the event hubs write the data into a managed Delta table named telemetry.raw_events. The pipelines must support schema drift and resume processing after failures without reprocessing the data.
Contoso identifies the following data modeling and optimization requirements:
* Build curated tables that standardize business logic.
* Overwrite equipment metadata attributes, such as name, manufacturer, model, and commissioning date, when the attributes change. Historical values are NOT required.
Contoso identifies the following pipeline deployment and operation requirements: |